
Introduction
Machine learning is one of the most exciting aspects of computer science because it allows us to experiment with problem solving skills performed by a computer without the programmer hard wiring the steps needed to come up with a solution. A while back we explored the use of genetic algorithms to solve numerical problems. In this article I would like to discuss another offshoot of the genetic algorithm called Population Based Incremental Learning (PBIL).
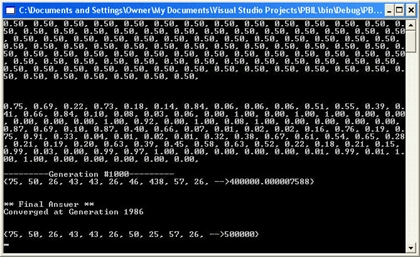
Figure 1 - The Results of a PBIL algorithm on finding the points on a Circle with radius 25 and center 50,50
Population Based Incremental Learning
PBIL allows you to represent your entire genetic population base through a probability vector rather than a myriad of chromosomes. A probability vector is simply a sequence of probabilities. Each probability value in the sequence represents the probability that we can generate a 1 or 0 at the gene position. For example the probability vector {.5, .5, 1, 1} can be represented by the following population
{0, 0, 1, 1}
{0, 1, 1, 1}
{1, 0, 1, 1}
{1, 1, 1, 1}
The probability that we will generate a 1 or 0 in the first position is 50/50, so 50% of the chromosomes in the population have 1 in the first position, and 50% of the chromosomes in the population have 0 in the first position. The probability of generating a one in the 3rd and 4th position is 1, so this number will always be one.
The algorithm for generating a solution using probability vectors is actually quite simple.
1. Initialize a probability vector with all probabilities being 1/2.
2. Generate a population of N chromosomes using the probability vector to randomly determine the gene in each chromosome position (1 or 0).
3. Evaluate the fitness of each chromosome based on a fitness function for your particular problem
4. Sort all chromosomes by fitness value
5. Update the probability value in each vector position based on the top X chromosomes using a learning rate.
Probability Vector := Probabilty Vector * (1.0 - LR) + topchromosome* (LR);
where LR = some learning rate
6. Check to see if the probability vector has converged. If not, repeat steps (2) through (5)
Listing 1 - PBIL Algorithm Steps
This algorithm is much easier to implement than the simple genetic algorithm (which involves crossovers, mutations, reproductions, and deaths), but is actually just as effective. It's a better algorithm in that it doesn't require you to remember as much information from generation to generation. You only need to maintain the probability vector which contains the probability distribution of each gene in our chromosome.
The Design
Below is the simple UML Design used by our algorithm implementation. The BinaryGene class has five methods that aid us in our PBIL implementation: CalculateFitness, CompareTo, UpdateProbabilityVector, and HasConverged. CalculateFitness is the method that we use to calculate our fitness function. The higher the value returned from this method, the higher the fitness of the chromosome. CompareTo implements the IComparable interface to allow us to sort Genomes by fitness. UpdateProbabilityVector modifies the probability vector in our algorithm according to the learning rate and the genes in our highest fit chromosomes. The HasConverged method determines if the probability vector has converged to a final solution with all 1's and 0's.
Note that the chromosome contains an array of integers called _genome. This array will either contain a value of 0 or 1. The Generate method of the BinaryGene class allows us to generate a chromosome based on the probability vector. The FormNumber method is used to break down the binary 1's and 0's inside the genome into integer values for use in the fitness function. Finally, the ToString method allows us to write our gene to the console as a readable string of integer values.
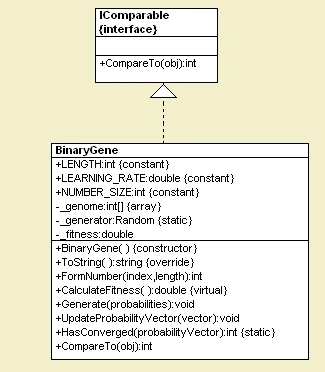
Figure 2 - Chromosome for PBIL Algorithm reverse engineered using WithClass UML Tool
Implementing PBIL through the Binary Gene Class
Once we've created our class to handle all major steps of the PBIL algorithm, we can easily implement our algorithm. Listing 2 shows the step by step implementation of PBIL through the binary gene class.
[STAThread]
{
BinaryGene[] _genomes = new BinaryGene[NUMBER_OF_SAMPLES];
double[] _probabilities = new double[BinaryGene.LENGTH];
// (1) generate initial probability vector
for (int i = 0; i < BinaryGene.LENGTH; i++)
{
_probabilities[i] = .5d; // initialize probabilities
}
// (2) generate chromosomes based on probability vector
// (3) calculate fitness of each gene
for (int i = 0; i < NUMBER_OF_SAMPLES; i++)
{
_genomes[i] = new BinaryGene();
_genomes[i].Generate(_probabilities);
_genomes[i].CalculateFitness();
}
// (4) Sort all chromosomes by fitness value
Array.Sort(_genomes);
// (5) Update the probability value in each vector position based on the top X chromosomes using a learning rate
for (int i = 0; i < NUMBER_OF_VECTORS_TO_UPDATE_FROM; i++)
{
_genomes[i].UpdateProbabilityVector(_probabilities);
}
// (6) Check to see if the probability vector has converged.
// If not, repeat steps (2) through (5)
// else we are finished
int convergenceFailureIndex = BinaryGene.HasConverged(_probabilities);
if (convergenceFailureIndex < 0)
{
Console.WriteLine("** Final Answer **");
Console.WriteLine("Converged at Generation {0}", counter);
break;
}
}
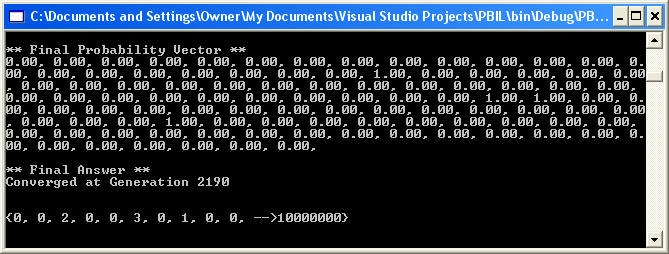
Console.WriteLine(_genomes[0].ToString()); // this is the final genome after convergence or 20,000th generation
Console.ReadLine();
}
KonradPosted Aug 31, 2009, 4:05 PM
You really just got started with Evolution Algorithms here.. and to be specific a branch of them called EDA (estimation of distribution algorithms). Later try to implement Univariate Marginal Distribution Algorithm (UMDA), then Mutual Information Maxminization for Input Clustering (MIMIC) and finally more complex ones like Mutual Information Maxminization for Input Clustering (MIMIC) or Estimation of Bayesian Networks Algorithm. I got bored by EA stuff some time ago, because I never found interesting problem to solve by them. Also, I had more fun with approximation of solution by different means. To be precise, I once created algorithm for problems which solution is permutation (this is really bad class for EA) with simulating ant colonies behavior. If you are interested don't hesitate to contact me. Good luck, and have fun:)