
This article is a continuation of Part 1 which I posted earlier. I strongly recommend you to go through part 1 before you go through this article. The demo we are going to see will use apache Spark serverless pool model where we will be loading a parquet sample data file into spark database (yes, we will create a database as well) and then analyze the same using spark from azure notebooks.
The sample parquet file used can be downloaded from the below link.
https://azuresynapsestorage.blob.core.windows.net/sampledata/NYCTaxiSmall/NYCTripSmall.parquet
To start with, make sure you have uploaded the sample file into the ADLS storage. You can refer to my previous articles if you want help or if you have any doubt on how to create a workspace, attach and data lake storage to it and upload a file. For this demo, I have uploaded the sample NYCTripSmall.parquet file under the container of my ADLS storage.
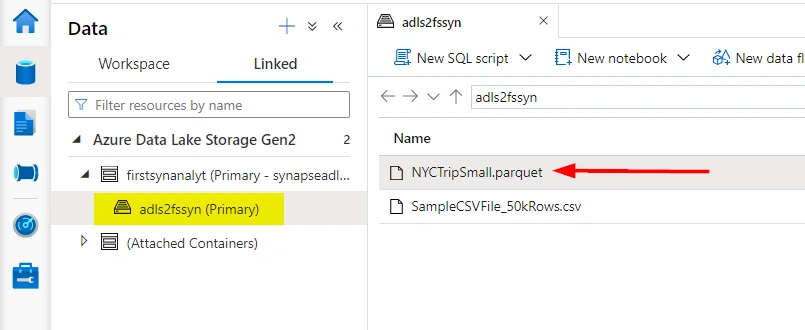
Next step is to create a Serverless Spark Pool. I would not be going through that as I have already covered it in my previous articles.
Analyze sample data with spark pool
As a first step we are going to load the sample data file from storage into spark dataframe using PySpark code. The scripts will be executed in the cells present in the notebook and it offers support for many languages like PySpark, .net(c#), scala etc., for you to run your query.
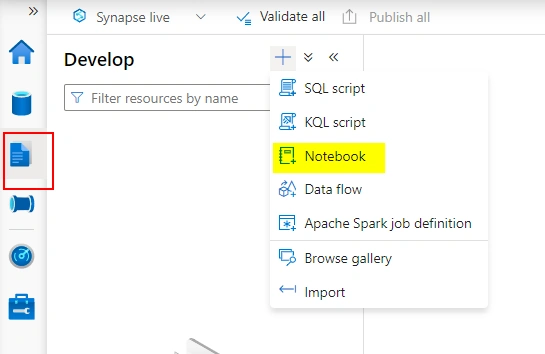
Go to development tab and select new Notebook. This is where we will see the cells as informed earlier and we have execute the codes.
You cannot run the query without selecting the spark pool resource. You can find the list of spark pools available in the dropdown to select.
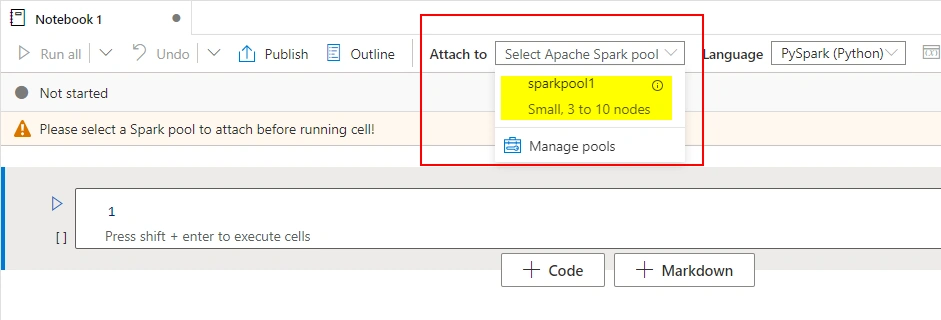
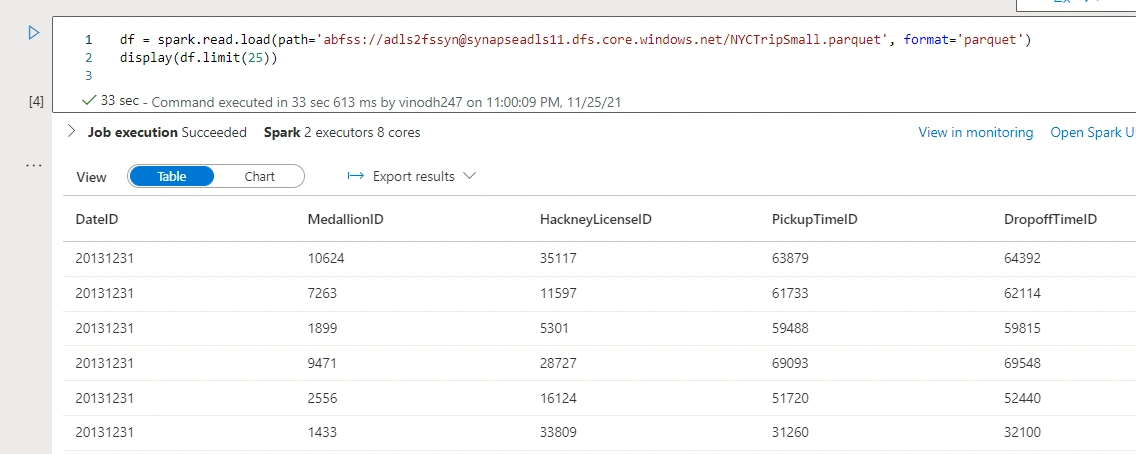
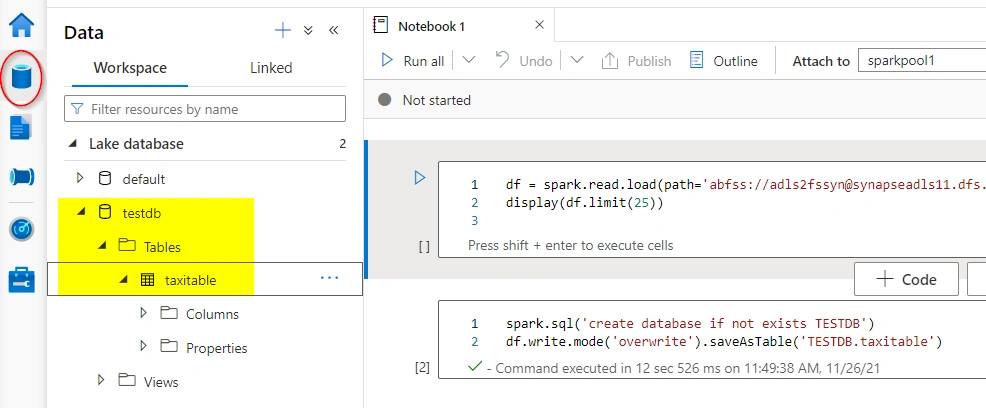
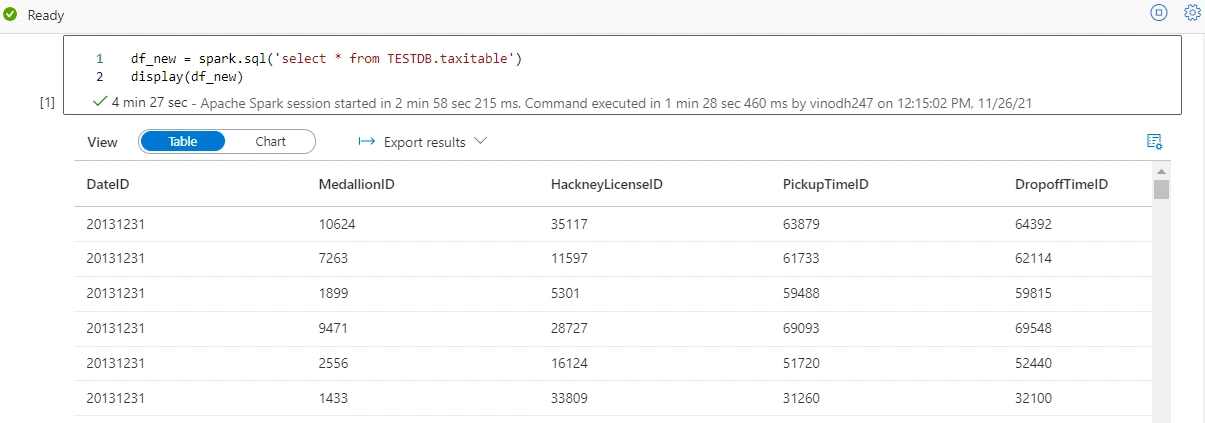
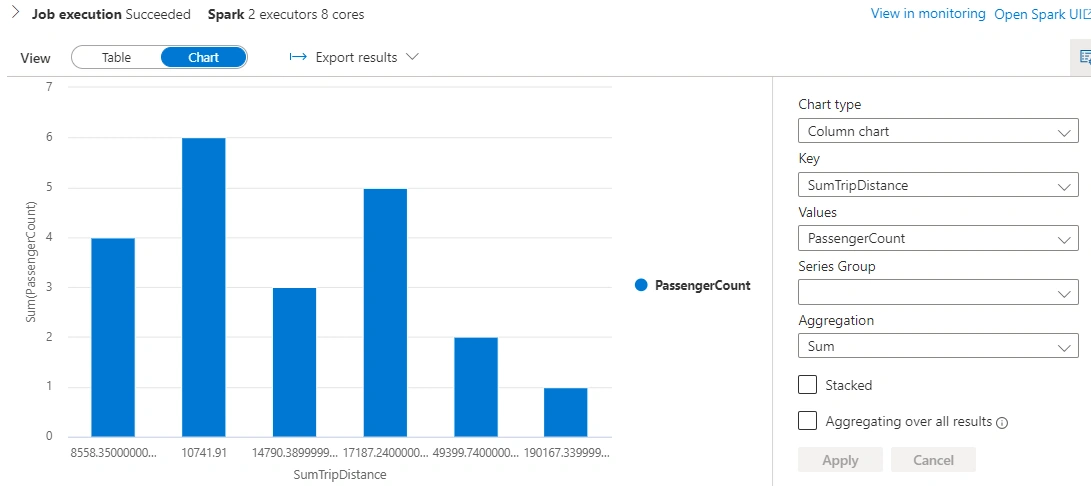
I am using the following code to load the sample file into a data frame and display the first 25 rows. The path you can get is from the sample file properties à ABFSS Path (azure blob file system path)
df = spark.read.load(path='abfss://[email protected]/NYCTripSmall.parquet', format='parquet')

display(df.limit(25))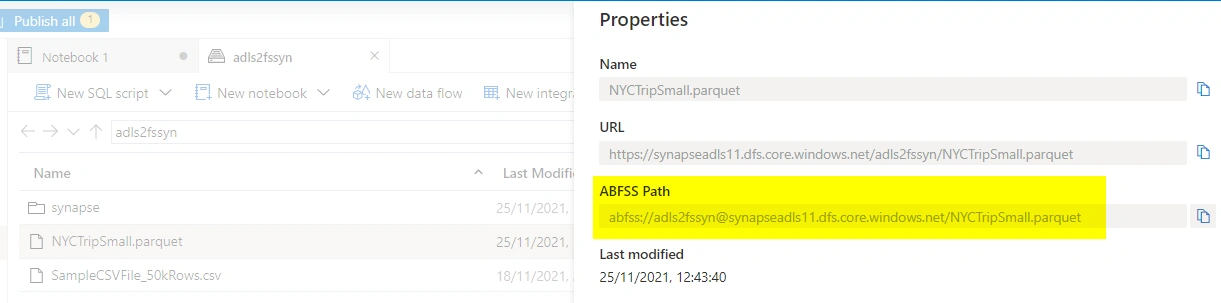
Uday DodiyaPosted Aug 28, 2022, 4:15 AM
Nice one Vinodh kumar