
Kafka is a distributed streaming platform. Distributed streaming is nothing but having a lot of applications(web or mobile) running and writing logs or embedding data. We need to store all the data in an efficient manner.
Kafka uses publish-subscribe messaging system that lets you send messages between processes, apps, and servers. It stores streams of records in fault -tolerant durable way and process streams of records as they occur. Kafka has built-in support for replication, partitioning, fault tolerance, and better throughput.
Below are the reasons why we should use Kafka.
- Scalability
Kafka supports high performance sequential writes and separates topics into partitions to facilitate highly scalable reads and writes. Kafka enable multiple producers and consumers to read and write at the same time.
- Low Latency
Kafka can provide high throughput with low latency and high availability.
- High Throughput
Kafka is capable of handling massive volumes of incoming messages at high velocity per second. 10k messages per second.
- High Performance
Kafka can deliver messages at high speeds and high volumes.
- Durability
Kafka messages are highly durable because Kafka stores the messages on the disk, and not in memory.
- Highly Reliable
Kafka can replicate data and handle many subscribers. In Apache Kafka, the messages are durable even after they have been consumed. This enables the Kafka Producer and Kafka Consumer to be available at different times and increases resilience and fault tolerance
Kafka differs from traditional messaging queues in several ways. Kafka retains message even after consumed while a Messaging Queue deletes once it is consumed. Kafka fetches message using pulling while Messaging Queue pushes the message to consumers. Kafka can be scaled horizontally while a messaging queue is scaled vertically.
Apache Kafka Architecture
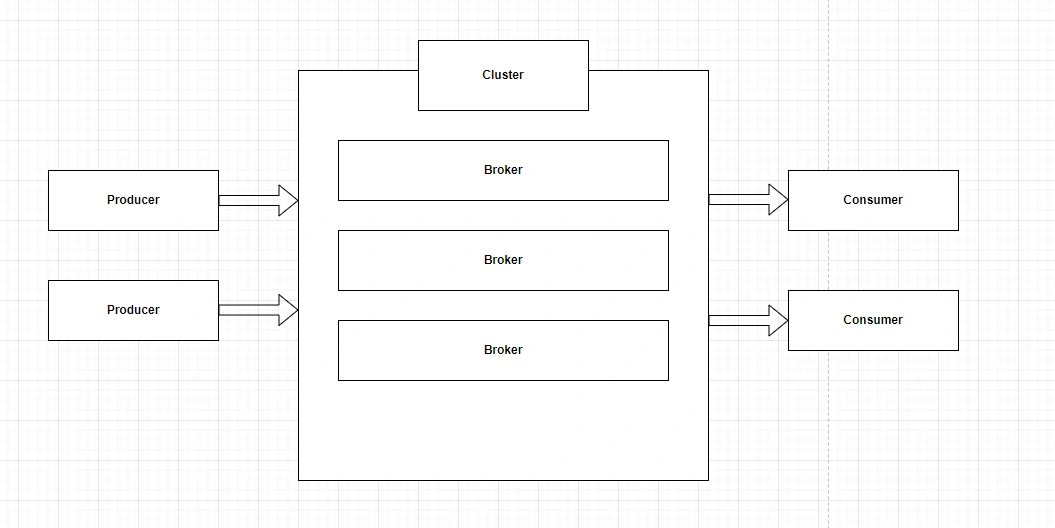
Kafka Architecture contains below components.
Topic
Topic defines a channel for the transmission of data. When producer publishes data to the topics, the consumer reads messages from them. A unique name identifies a topic pertaining to Cluster.
Producer
This serves as datasource for one or more kafka topics and is responsible for writing, optimising and publishing these messages to topics. Producer connects to cluster through zookeeper.
Consumer
Consumer consumes the data by reading messages on the topics they have subscribed to. Each Consumer belongs to a consumer group and all consumers belonging to same consumer group share a common task.
ZooKeeper
This manages and coordinates the kafka brokers in a cluster. Also notifies producers and consumers in a cluster of the existence of new brokers or failure of brokers.
Broker
Broker acts as a middleman between producers and consumers, hosting topics and enables sending & receiving messages between them. Producers and consumers don't communicate directly. Instead, they communicate using these brokers. If producers and consumers goes down, the communication pipeline continues to function.


Join the conversation! Your thoughts help the community grow.