Conclusion and Recommendation
- Microsoft Fabric is an excellent choice if your primary focus is on data integration, data quality, and governance, particularly if you require a low-code/no-code approach and seamless integration with other Microsoft Power Platform components.
- Azure Synapse is more suitable for comprehensive analytics needs, including large-scale data warehousing, big data processing, and real-time analytics. Its robust performance, scalability, and integration with Azure Data Services make it ideal for organizations with extensive data analytics requirements.
Recommendation
If your organization requires a powerful and scalable analytics platform that can handle both data warehousing and big data processing, Azure Synapse is the recommended option. However, if your primary need is for a user-friendly data integration and governance platform, Microsoft Fabric would be more appropriate.
Dedicated Vs Serverless
| Factor |
Dedicated SQL Pool |
Serverless SQL Pool |
| Performance |
Consistent performance with predefined resources; suitable for high-performance workloads |
Variable performance; ideal for ad-hoc queries and exploratory data analysis |
| Scalability |
Scalable by adjusting Data Warehousing Units (DWUs); best for predictable workloads |
Automatically scales based on workload; suitable for variable workloads |
| Cost |
Fixed cost based on DWU level; ideal for sustained, high-throughput workloads |
Pay-per-query model; cost-effective for intermittent or exploratory queries |
| Use Cases |
Data warehousing, high-performance reporting, BI applications with consistent workloads |
Ad-hoc data exploration, querying data in Azure Data Lake without ETL, variable workload patterns |
| Management |
Requires resource management and performance tuning; offers full control |
No infrastructure management: minimal maintenance required |
| Data Storage & Integration |
Structured data in relational format; integrates well with traditional ETL tools |
Queries data directly from Azure Data Lake (Parquet, CSV, JSON); easy integration with data lakes |
| Security & Compliance |
Comprehensive security features and compliance; supports fine-grained controls |
Security features like encryption and role-based access control; compliant with industry standards |
Performance
| Workload |
Serverless SQL Pool (time) |
Dedicated SQL Pool (time) |
| 1 TB SELECT query |
10 seconds |
5 seconds |
| 100 TB aggregation query |
5 minutes |
1 minute |
| 10 TB data loading |
30 minutes |
10 minutes |
| 10000 Tenant Records |
21 Seconds |
6 sec (100-DWH) |
Data isolation and security
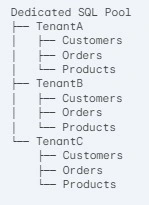
Option 1. Tenant-Specific Schemas
Each tenant receives its own schema, effectively creating a separate namespace for its tables, views, and other database objects. This prevents naming collisions and ensures that objects belonging to different tenants are clearly distinguishable.
Data Containment
All data related to a tenant is contained within its dedicated schema. This makes it easier to manage and query data for a specific tenant without the risk of accidentally accessing data belonging to other tenants.
- Granular Security
- Schema-Level Permissions: You can grant permissions (e.g., SELECT, INSERT, UPDATE, DELETE) on a schema level. This means you can easily control which users or roles have access to specific tenant data. For instance, you can grant access to Tenant A's schema only to users associated with Tenant A.
- Object-Level Permissions: Within each schema, you can further refine permissions on individual objects (tables, views, etc.). This allows for even more granular control, ensuring that users only access the specific data they are authorized to see.
- Simplified Management
- Easier Backups and Restores: By separating tenant data into different schemas, you can easily backup and restore data for individual tenants without affecting other tenants' data.
- Independent Schemas: Each tenant's schema operates independently, making it easier to manage schema changes or upgrades without impacting other tenants.
- Pros
- Data Isolation: Provides strong isolation of data per tenant, simplifying security and access control.
- Clear Ownership: Easily identify which data belongs to which tenant.
- Compliance: This can be beneficial for meeting certain compliance requirements (e.g., GDPR) that mandate data separation.
- Cons
- Potential Overhead: If you have many tenants, managing a vast number of schemas can become cumbersome.
- Query Complexity: Queries that need to access data across multiple tenants may become more complex.
- Resource Usage: Each schema consumes some metadata overhead, which could potentially impact performance in extreme cases (although unlikely to be significant with modern SQL Server versions).
- Cross-Tenant Queries: While schemas provide excellent isolation, they might make queries that need to access data from multiple tenants slightly more complex.
- Number of Schemas: If you have a large number of tenants, managing a large number of schemas can become cumbersome.
Option 2. Tool/Microservice-Wise Schemas
In this model, you create separate schemas within the dedicated SQL pool for each of your tools or microservices. Instead of grouping data by tenant, you group it by the functional area or service it belongs to.
Tenant Isolation
Since data is not naturally segregated by tenant, you must implement additional mechanisms for tenant isolation.
- Row-Level Security (RLS): Define RLS policies on tables to filter data based on a tenant identifier column.
- Views: Create tenant-specific views that filter underlying tables based on the tenant identifier.
Benefits of Tool/Microservice-Wise Schemas
- Logical Grouping: Data is organized by functionality, reflecting the application's architecture.
- Simplified Microservice Access: Easier to query data across different components of a microservice.
- Potential Performance Gains: This may improve performance for certain query patterns that access data within a single microservice.
Challenges and Considerations
- Tenant Isolation: Implementing effective tenant isolation is critical and requires careful design using RLS or views.
- Complex Security Management: Managing permissions across multiple microservices and tenants can become complex.
- Data Redundancy: Potential for data redundancy if similar data is needed by multiple microservices (e.g., user information).
Use Case
- Cross-Microservice Queries: You frequently need to query data across different components of a microservice.
- Limited Number of Tenants: The number of tenants is relatively small, making security management manageable.
- Clear Microservice Boundaries: Your application has well-defined microservice boundaries with minimal data overlap.
Recommendation
Start with the Tenant-Specific Schemas approach. It provides a strong foundation for data isolation and security, making it a more suitable choice for your multi-tenant and database-per-company scenario.
If you later find that you need to organize data by microservice functionality within a tenant, you can always create sub-schemas within the tenant-specific schemas to achieve that level of organization. This gives you flexibility while still maintaining robust data isolation at the tenant level.
Additional Considerations
- Data Sensitivity: If data privacy and compliance are top priorities, prioritize tenant-specific schemas.
- Number of Tenants: If you have many tenants, be mindful of the increased schema management overhead with tenant-specific schemas.
- Query Patterns: If your queries frequently span multiple microservices within a tenant, the microservice-wise approach might be more convenient.
- Security Complexity: Tenant-specific schemas offer a simpler security model, while microservice-wise schemas require more intricate security management.

Join the conversation! Your thoughts help the community grow.