Microsoft Power Platform provides AI Builder, a low-code AI capability that allows users to create custom models to extract specific information from documents. Once trained and published, these models can be integrated with Power Automate and Power Apps to automate document-processing tasks.
In this article, we will walk through the process of creating a custom document processing model, defining fields and tables, training the model, testing its results, publishing it, and using it in a Power Automate flow.
What is AI Builder document processing?
AI Builder document processing allows you to train a custom AI model to identify and extract information from documents.
For example, consider an application form containing the following information:
Instead of manually copying this information into another system, we can train a custom model to recognize these fields and extract their values automatically.
The extracted information can then be used in Power Automate to create SharePoint list items, update Dataverse records, send notifications, or perform other business operations.
Step 1: Create a custom document processing model
To begin, open your Power Apps environment and navigate to AI Builder.
Open Power Apps.
Select the appropriate environment.
Navigate to AI hub and open AI models.
Select the option to extract custom information from documents.
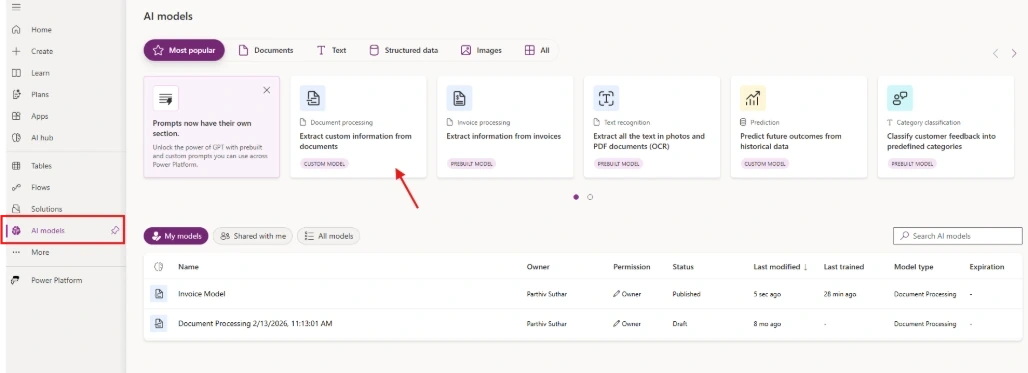
Select Create custom model.
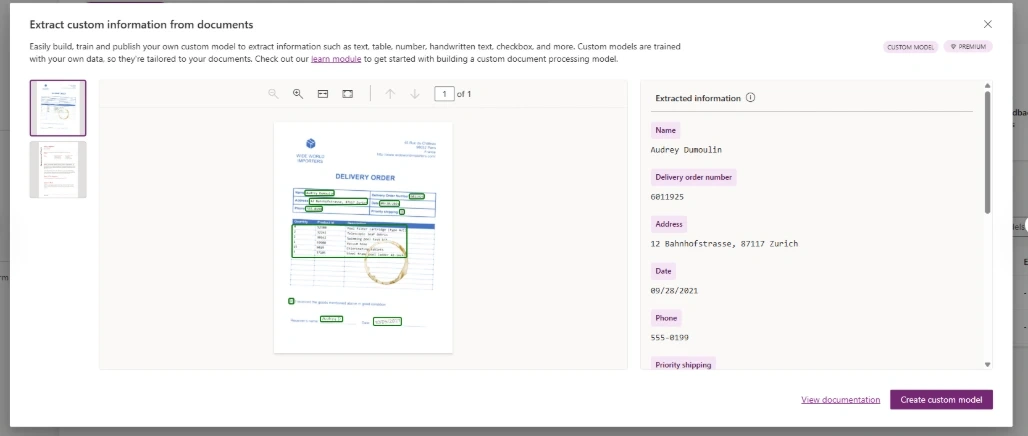
AI Builder opens a guided setup process that helps you define the document type, information to extract, and sample documents used for training.
The exact menu labels may vary slightly depending on the current interface.
Step 2: Choose the document type
The first step is to select the type of documents the model will process.
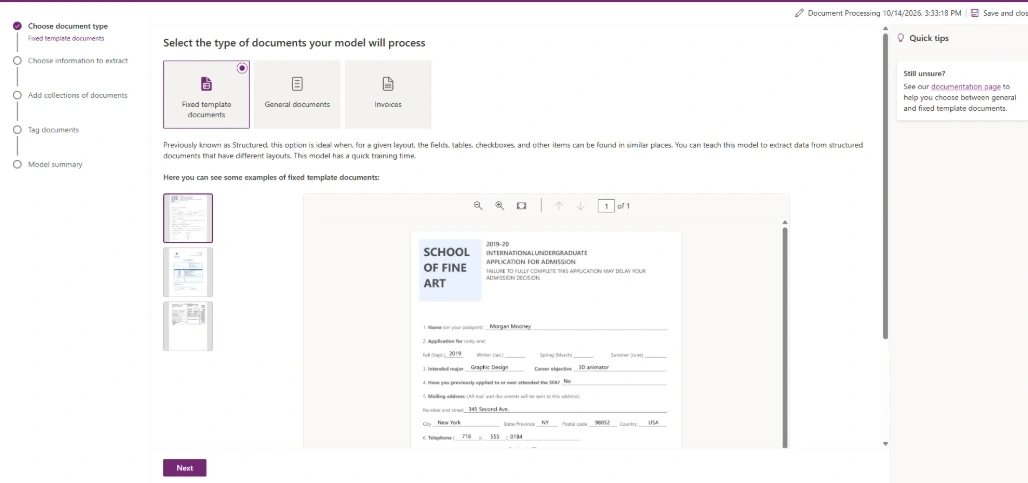
AI Builder provides three document types:
1. Fixed template documents
This option is suitable when documents have a similar structure and the required information generally appears in similar locations. Examples include standardized application forms, purchase orders, and other structured forms.
2. General documents
This option is intended for documents with more varied layouts, such as letters, contracts, and statements of work.
3. Invoices
This option is designed specifically for invoice processing.
In our example, we select Fixed template documents because the model is intended to extract defined fields and a table from similarly structured documents.
AI Builder also displays a warning when attempting to change an existing model to the invoice document type. If the dedicated invoice type is required, a new model must be created using that type.
Step 3: Choose the information to extract
After selecting the document type, define the information that the model should recognize.
For this example, we configure four fields and one table.
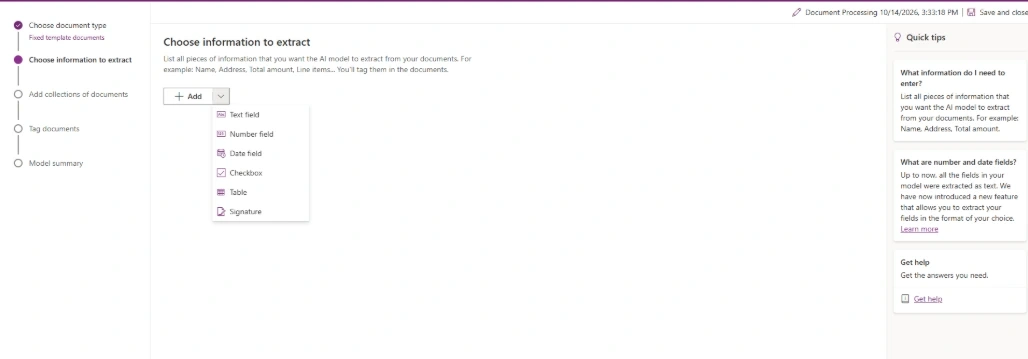
Fields
Fields represent individual pieces of information that should be extracted from the document.
For example:
Applicant name
Email address
Telephone number
Application reference
These are illustrative examples. The actual fields should match the requirements of your document.
Tables
A table represents structured information arranged in rows and columns.
For example, an application form may contain a table with course details, application choices, or other repeated information.
Configure the required table and its columns so that the model can extract the relevant values.
Defining the fields and table before training helps the model learn exactly which information is important.
Step 4: Add collections of documents
The next step is to add document collections.
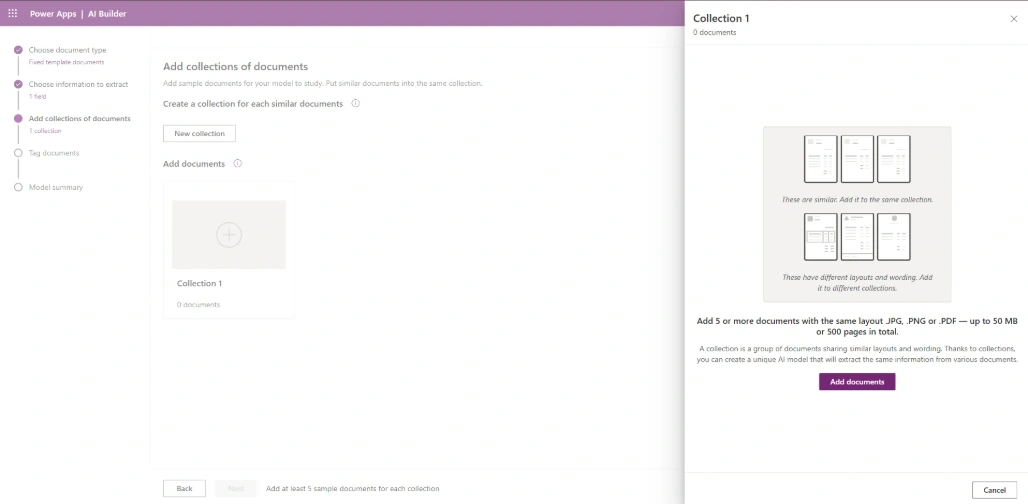
A collection groups documents that share a similar layout. This helps AI Builder learn how to identify the required fields across different examples.
In our example, two collections are configured.
When preparing collections:
Group documents according to their layouts.
Ensure that each collection contains representative examples.
Include realistic variations in the documents.
Check that the documents are clear and readable.
Microsoft recommends starting with at least five example documents that use the same layout. More representative examples may help improve extraction quality.
The number and arrangement of collections should reflect the document layouts that your model needs to support.
Step 5: Tag the documents
After adding the collections, upload or select the sample documents and label the information that the model must extract.
This process is called tagging.
For each document:
Open the document in the tagging interface.
Select the text corresponding to a defined field.
Assign that text to the appropriate field.
Identify the relevant rows and columns for the table.
Review the labels to ensure that they match the document content.
Repeat the process for the remaining sample documents.
For example, if the document contains the applicant name “Morgan Mooney,” select that text and associate it with the Applicant Name field.
Similarly, identify the appropriate values for the other configured fields and table columns.
In our example, 10 documents have been tagged.
Accurate tagging is important because the model learns from these examples. Incorrect or inconsistent labels can reduce extraction quality.
Step 6: Train the model
Once the required documents have been tagged, proceed to the model summary and review the configuration.
Check that:
The correct document type is selected.
All required fields have been configured.
The table and its columns are defined correctly.
The sample documents have been tagged accurately.
The document collections contain the intended examples.
Select Train to begin training the model.
AI Builder uses the tagged examples to learn how to identify the required information in similar documents.
When training finishes, review the training status and open the model details page.
If training fails or the results are not satisfactory, review the sample documents, tagging accuracy, and document requirements before trying again.
Step 7: Test the trained model
Before publishing the model, test it with a document that was not used for training.
On the model details page, select Quick test and upload a suitable document.
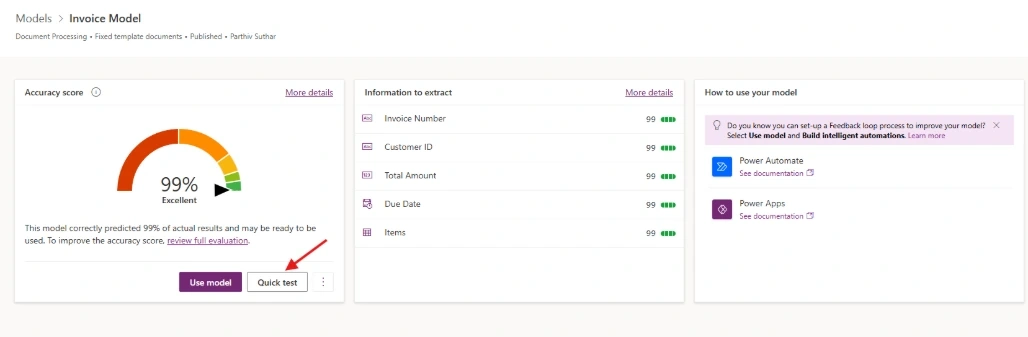
AI Builder processes the document and displays the extracted information.
Review the results carefully:
Are the individual fields extracted correctly?
Are the values assigned to the correct fields?
Is the table information extracted accurately?
Are any values missing or incorrect?
If the results are not satisfactory, correct the training data or add representative examples as appropriate, then retrain and test the model again.
Testing with different documents is important because a model that works well on one sample may not perform equally well on every document.
Step 8: Publish the model
After confirming that the model produces acceptable results, publish it.
Open the model details page.
Locate the Publish option.
Select Publish and wait for the operation to complete.
Confirm that the model status indicates that the trained version is published.
Publishing makes the model available for use in supported Power Apps and Power Automate scenarios in the current environment.
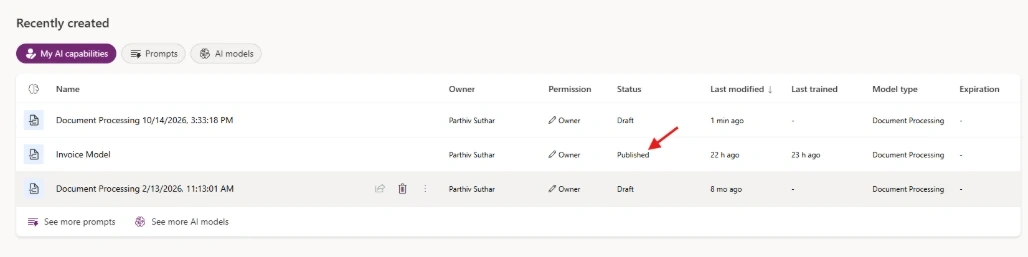
A trained model is not automatically available for operational use until it has been published.
Step 9: Use the model in Power Automate
After publishing the model, you can use it in a cloud flow to process documents automatically.
For this example, we will use a manually triggered flow that accepts a document and extracts its fields.
Create the flow
Open Power Automate.
Select Create and choose Instant cloud flow.
Give the flow a meaningful name.
Select the Manually trigger a flow trigger.
Add a File input to the trigger.
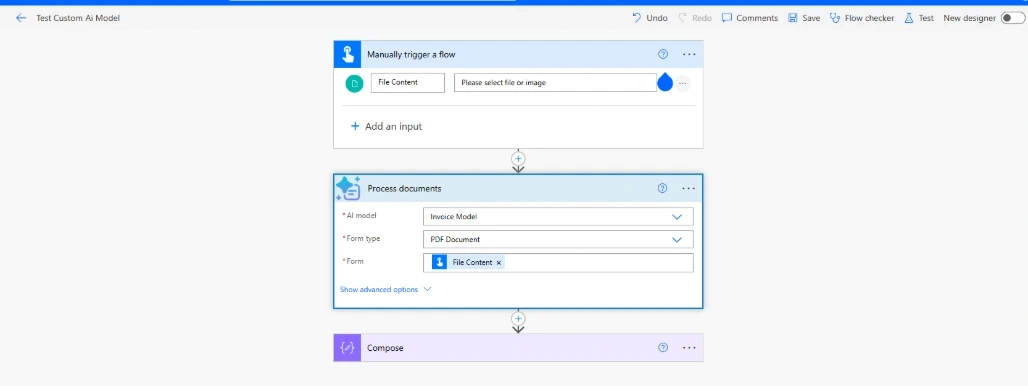
The file input allows the user to provide the document that should be processed.
Save and test the flow
After configuring the actions:
Review the run history and confirm that the extracted values are passed correctly to the next actions.
If a field is missing or incorrect, check the model's extraction results and the mapping in the flow.
Important considerations and limitations
Before using the model in a production workflow, keep the following points in mind:
Supported file formats and document-size limits apply. Microsoft documents support for PDF, JPG, and PNG inputs, with a maximum document size of 20 MB.
Documents with poor scan quality may produce inaccurate results.
Fields that span page boundaries and table rows that break across pages have documented limitations.
Extraction results should be validated when accuracy is important.
AI Builder usage, licensing, and capacity requirements should be checked for the target environment.
You should always test the model using documents representative of the actual business process before deploying it to production.
Conclusion
AI Builder makes it possible to create a custom document processing model without building a machine learning solution from scratch.
By defining the document type, selecting fields and tables, tagging sample documents, training the model, and testing the extraction results, we can create a model tailored to specific business requirements.
Power AppsAI Builderdocument processingPower Automatecustom AI modeldocument extraction

Join the conversation! Your thoughts help the community grow.