

In the enterprise landscape, recommendation engines have evolved beyond simple collaborative filtering ("users who bought X also bought Y"). Modern businesses require semantic understanding, contextual memory, and auditability. A user asking for "software that helps me manage remote team burnout" shouldn't just get HR tools; they should get a curated list based on their company’s existing tech stack, budget constraints, and previous interactions.
This article demonstrates how to build a production-grade Semantic Recommendation Agent using:
LangGraph: For stateful, cyclic multi-agent orchestration.
ChromaDB: For high-performance semantic vector storage.
Enterprise RAG: Retrieval Augmented Generation with metadata filtering and re-ranking.
Persistent Memory: To maintain user preferences across sessions.
The Real-Time Use Case: Internal Tech Stack Advisor
Scenario: An enterprise IT procurement portal where employees ask natural language questions to find approved software vendors.
The Challenge: The catalog contains 10,000+ SaaS products with dense technical documentation. Simple keyword search fails on nuanced queries like "secure alternative to Slack for healthcare compliance."
The Solution: A multi-agent system that retrieves candidates semantically, validates them against enterprise policy (RAG), remembers user department constraints, and synthesizes a ranked recommendation.
Architecture Overview
We will implement a Supervisor Multi-Agent Pattern:
State Manager: Holds the conversation history, retrieved docs, and user profile.
Retriever Agent: Queries ChromaDB with semantic similarity + metadata filters.
Policy Validator Agent: Checks retrieved items against internal compliance docs.
Recommendation Synthesizer: Generates the final response with citations.
Memory Writer: Updates long-term user preferences in ChromaDB.
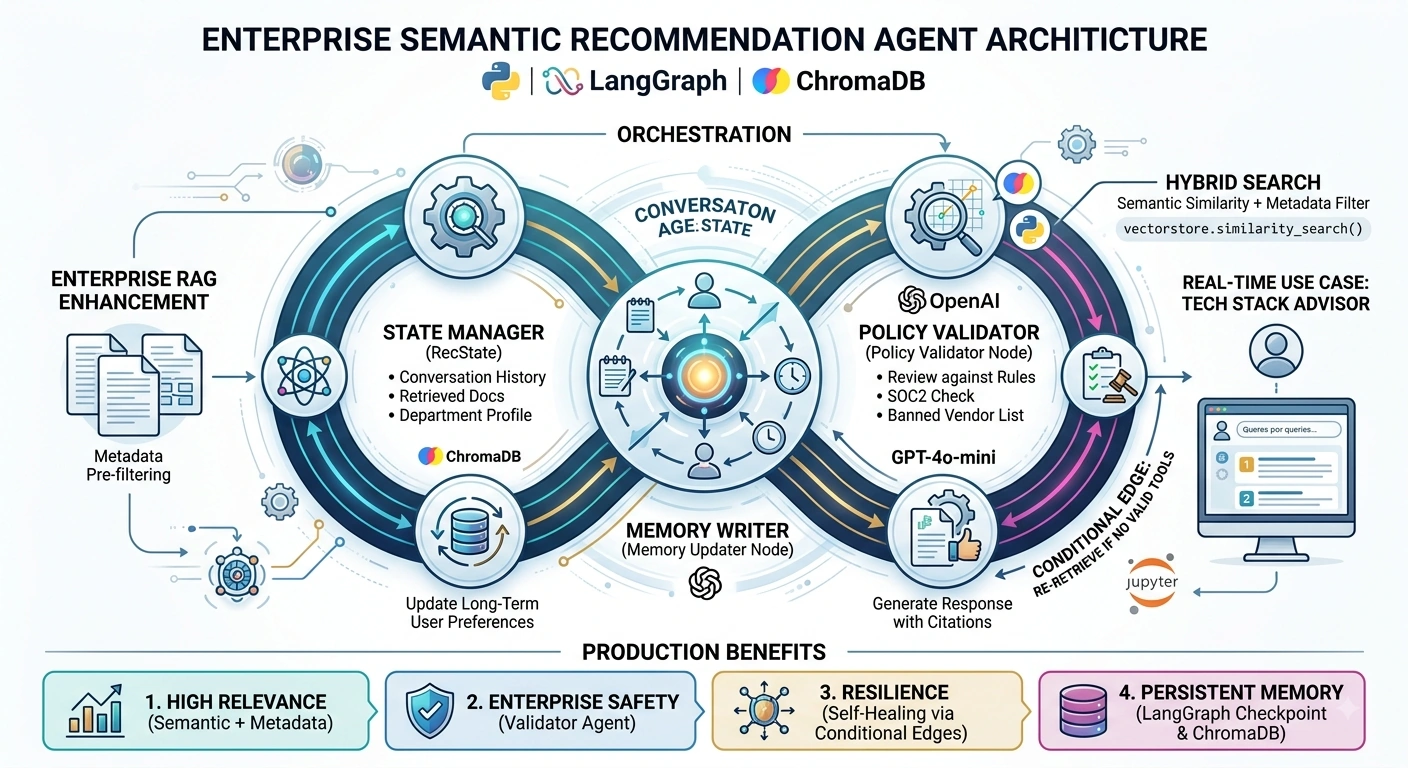
Step-by-Step Implementation
Prerequisites
pip install langgraph langchain-chroma chromadb langchain-openai pydanticStep 1: Define the Enterprise State
In LangGraph, state is the single source of truth. We define a structured schema to ensure type safety and traceability.
from typing import Annotated, List, Dict, Any
from typing_extensions import TypedDict
from langgraph.graph.message import add_messages
from langchain_core.documents import Document

class RecState(TypedDict):
    messages: Annotated[List[Any], add_messages]
    user_id: str
    department: str
    retrieved_docs: List[Document]
    validated_tools: List[Dict[str, Any]]
    final_recommendation: str
    iteration_count: int
Step 2: Initialize ChromaDB with Enterprise Metadata
Semantic similarity alone isn't enough. We use Chroma's metadata filtering to enforce enterprise boundaries before the LLM sees the data.
import chromadb
from langchain_chroma import Chroma
from langchain_openai import OpenAIEmbeddings

# In production, use PersistentClient or HTTP connection
client = chromadb.PersistentClient(path="./chroma_enterprise")

vectorstore = Chroma(
    client=client,
    collection_name="saas_catalog",
    embedding_function=OpenAIEmbeddings(model="text-embedding-3-small"),
)

# Example: Adding documents with rich enterprise metadata
# vectorstore.add_documents(
#     documents=[...],
#     metadatas=[{
#         "vendor": "AcmeCorp",
#         "compliance": ["HIPAA", "SOC2"],
#         "approved_departments": ["Engineering", "HR"],
#         "price_tier": "enterprise"
#     }]
# )
Step 3: Build the Specialized Agents
A. The Semantic Retriever Node
This node performs hybrid search: semantic similarity filtered by the user's department.
def retriever_node(state: RecState):
    """Retrieve relevant tools based on semantic similarity + dept filter."""
    query = state["messages"][-1].content

    # Enterprise-grade retrieval: Filter BEFORE semantic search
    docs = vectorstore.similarity_search(
        query,
        k=10,
        filter={"approved_departments": {"$in": [state["department"], "All"]}}
    )

    return {"retrieved_docs": docs}
B. The Policy Validator Node
An LLM-based gatekeeper that ensures recommendations don't violate security policies.
from langchain_openai import ChatOpenAI
from langchain_core.prompts import ChatPromptTemplate

llm = ChatOpenAI(model="gpt-4o-mini", temperature=0)

validation_prompt = ChatPromptTemplate.from_messages([
    ("system", """You are an IT Compliance Officer.
    Review the retrieved tools against these rules:
    1. Must have SOC2 if handling customer data.
    2. Cannot be on the banned vendor list: {banned_vendors}.
    Return ONLY valid tool names as a JSON list."""),
    ("human", "Query: {query}\nRetrieved Tools: {docs}")
])

def validator_node(state: RecState):
    chain = validation_prompt | llm
    result = chain.invoke({
        "query": state["messages"][-1].content,
        "docs": [d.metadata.get("vendor") for d in state["retrieved_docs"]],
        "banned_vendors": ["ShadowIT_Corp", "UnsecureApp"]
    })
    # Parse LLM output into structured validated_tools
    return {"validated_tools": result.content, "iteration_count": state.get("iteration_count", 0) + 1}
Join the conversation! Your thoughts help the community grow.