

In standard Retrieval-Augmented Generation (RAG), the Large Language Model (LLM) acts as a synthesizer. But in compliance-heavy industries—like finance, healthcare, and legal synthesis is not enough. Traceability is mandatory.
If an AI tells a compliance officer that a transaction violates an Anti-Money Laundering (AML) policy, the officer cannot simply "trust the AI." They need to see the exact page, paragraph, and sentence from the regulatory document that proves it. This is where Citation Grounding comes in. Standard linear RAG chains (like basic LangChain) struggle here because they cannot easily "check their own work." To build a truly grounded system, we need a framework that supports loops, state management, and self-correction. In this end-to-end guide, we will build a Citation-Grounded RAG system using LangGraph, applied to a real-world use case: Automated KYC/AML (Know Your Customer / Anti-Money Laundering) Review in Retail Banking.
The Real-World Use Case: KYC/AML Document Review
The Scenario: A global bank is onboarding a corporate client. The client submits a complex 200-page packet detailing their Ultimate Beneficial Owners (UBOs), corporate structure, and source of funds.
The Task: The compliance team must verify if the UBO structure complies with the bank’s internal AML policy and external sanctions guidelines.
The Problem: Reading 200 pages of dense legal text against a 500-page internal policy manual takes hours.
The AI Solution: A RAG system that answers: "Is the UBO structure compliant?"
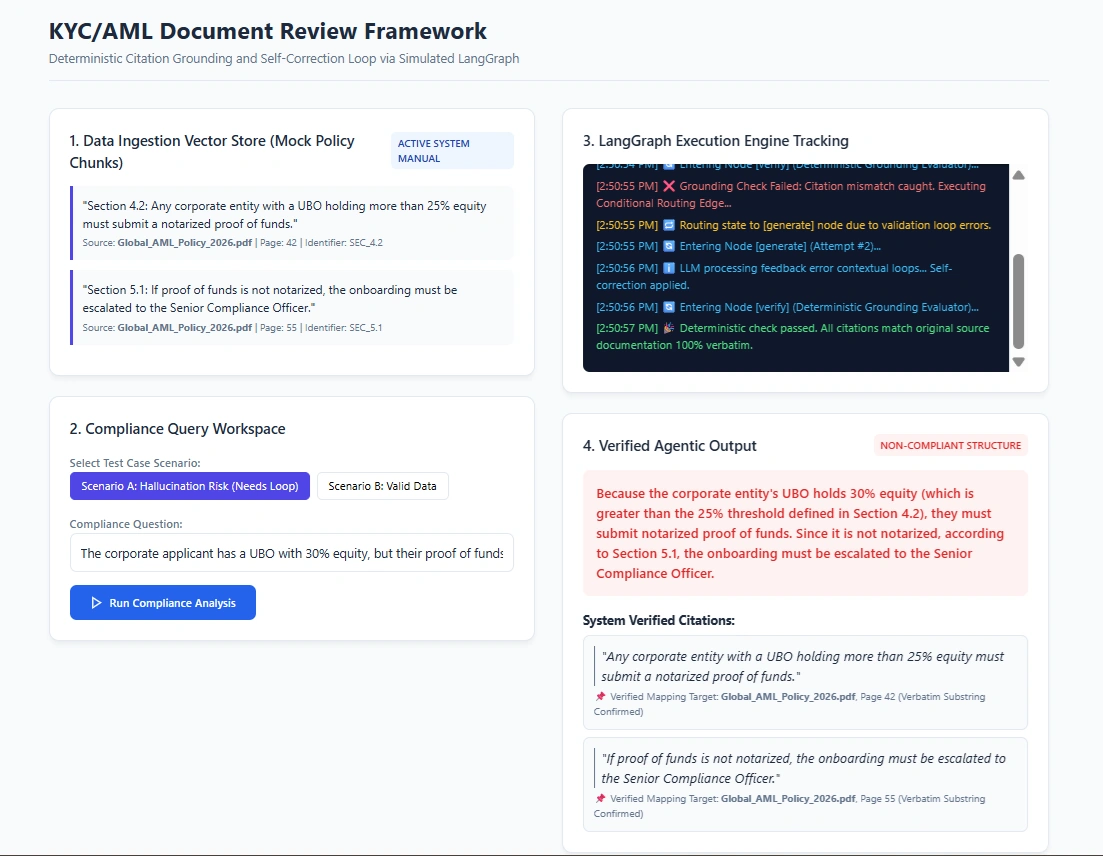
The Compliance Requirement: The AI must output the answer alongside exact, verbatim quotes from the policy manual. If it cannot find an exact quote, it must state "Insufficient information" rather than hallucinate a compliance rule.
Why LangGraph for Citation Grounding?
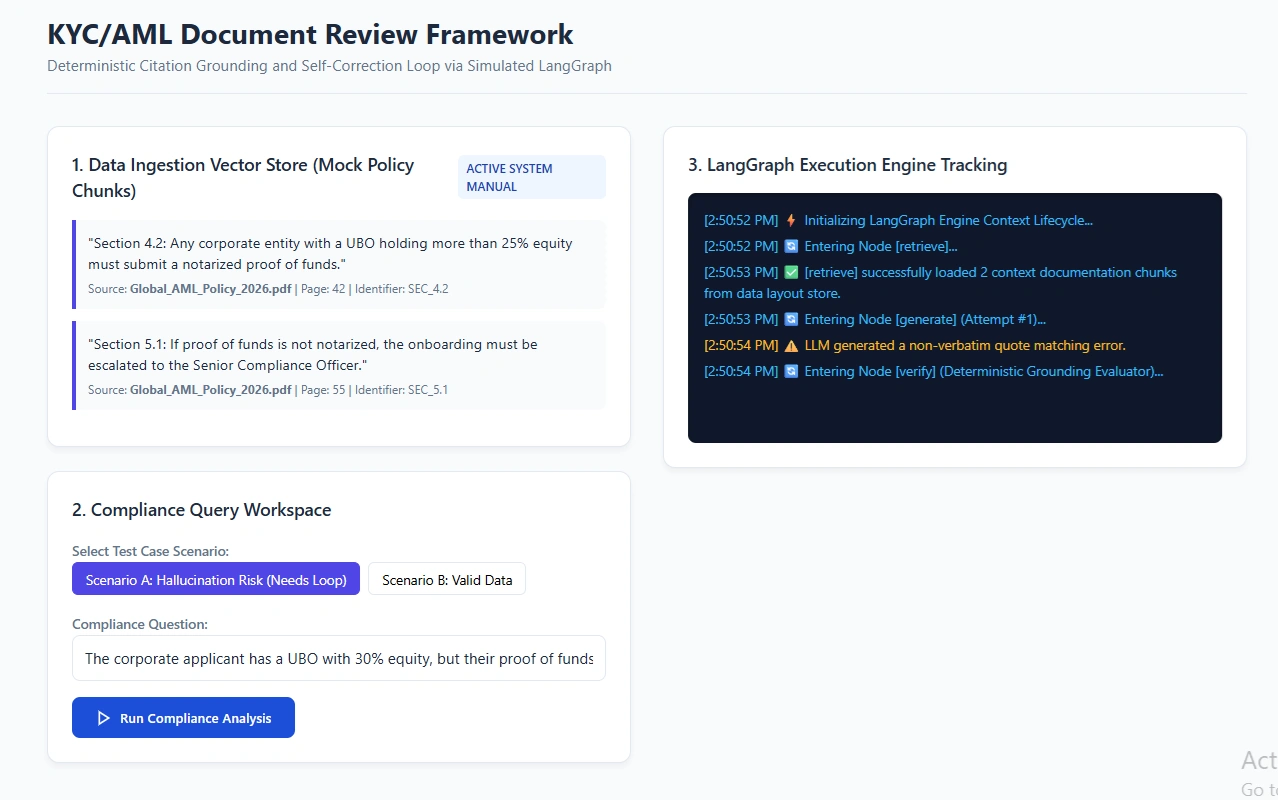
To guarantee citations, we cannot rely on a single LLM prompt. We must implement a Generate-Verify-Correct loop:
Retrieve: Fetch relevant policy chunks.
Generate: The LLM drafts an answer and extracts exact quotes as citations.
Verify (The Grounding Node): A deterministic Python script checks if the LLM's "exact quotes" actually exist in the retrieved text.
Route: If the citations are fake or missing, LangGraph routes the state back to the Generate node with an error prompt, forcing the LLM to self-correct.
Step 1: Data Ingestion & Metadata Strategy
Citation grounding fails if your chunks lack context. When chunking your compliance documents, you must preserve strict metadata.
# Example of a perfectly structured document chunk for grounding
document_chunk = {
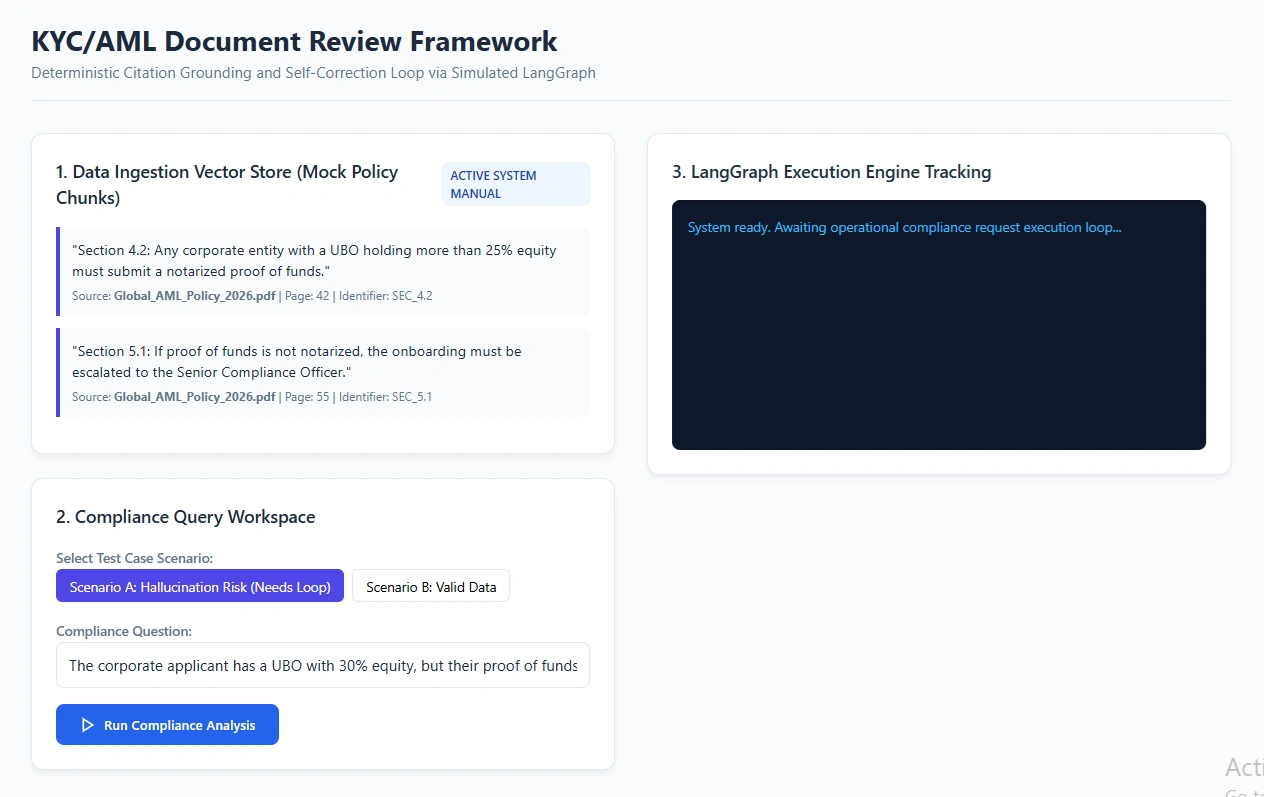
    "page_content": "Section 4.2: Any corporate entity with a UBO holding more than 25% equity must submit a notarized proof of funds.",
    "metadata": {
        "source": "Global_AML_Policy_2026.pdf",
        "page_number": 42,
        "section_id": "SEC_4.2",
        "chunk_id": "doc_123_chunk_4"
    }
}
Step 2: Defining the LangGraph State
We need a state that tracks the documents, the generated answer, the citations, and a verification flag to control the loop.
from typing import TypedDict, List, Optional
from langchain_core.documents import Document
from pydantic import BaseModel, Field

# Pydantic model to force the LLM to output structured citations
class Citation(BaseModel):
    exact_quote: str = Field(description="The exact verbatim quote from the text")
    source_doc: str = Field(description="The document name")
    page_number: int = Field(description="The page number")

class GroundedAnswer(BaseModel):
    answer: str = Field(description="The final compliance answer")
    citations: List[Citation] = Field(description="List of exact quotes supporting the answer")
    is_compliant: Optional[bool] = Field(description="True if compliant, False if not, None if unknown")

class GraphState(TypedDict):
    question: str
    documents: List[Document]
    generated_response: Optional[GroundedAnswer]
    verification_status: str # "pending", "verified", "failed"
    retry_count: int
    error_feedback: Optional[str]
Step 3: Building the LangGraph Nodes
Now we build the nodes. The magic happens in the generate_node (which uses structured output) and the verify_citations_node (which acts as the deterministic ground-truth checker).
Node 1: Retrieve
def retrieve_node(state: GraphState):
    # In production, this queries your Vector DB (e.g., Pinecone, Milvus)
    # We mock it here for the example
    question = state["question"]

    # Mock retrieval
    docs = [
        Document(page_content="Section 4.2: Any corporate entity with a UBO holding more than 25% equity must submit a notarized proof of funds.",
                 metadata={"source": "Global_AML_Policy_2026.pdf", "page_number": 42}),
        Document(page_content="Section 5.1: If proof of funds is not notarized, the onboarding must be escalated to the Senior Compliance Officer.",
                 metadata={"source": "Global_AML_Policy_2026.pdf", "page_number": 55})
    ]
    return {"documents": docs, "verification_status": "pending"}
Node 2: Generate (with Structured Output)
We use LangChain's with_structured_output to force the LLM to return our Pydantic model. This prevents the LLM from writing flowing text where citations are hard to parse.

Join the conversation! Your thoughts help the community grow.