
Introduction.
Data mining is a key member in the Business Intelligence (BI) product family in SQL Server 20051. Data mining is about analyzing data and finding hidden patterns using automatic or semiautomatic means, which can be explored for valuable information. It is about learning the characteristics of data set, which are not possible to discover by simple seeing.
There are several attempts to define the learning task applied to software systems such as: "Learning is any process that enables a system to achieve a better performance when working on the same task" or "Learning consists of constructing or modifying representations of past experience".
Large volumes of data which comes from information systems have been accumulated and stored in databases. Organizations have become data-rich and knowledge-poor. The information found in the patterns can be used for reporting, and, most importantly, for prediction.
Working with Analysis Service in SQL Server 2005 as a Data Mining tool.
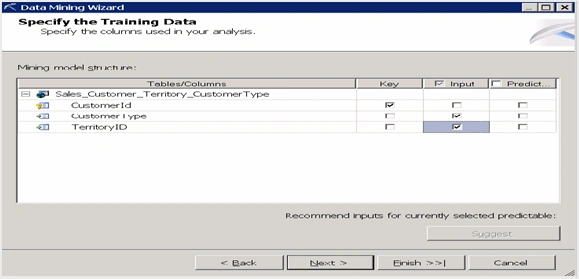
Data mining approach in Analysis Service is rather simple, all you need to do is to select the right data mining algorithm and specify the input columns and the predictable columns (which are the targets for the analysis).
Data mining can be used to solve a several problems such as:
- Classification: Classification refers to assigning cases into categories based on a predictable attribute.
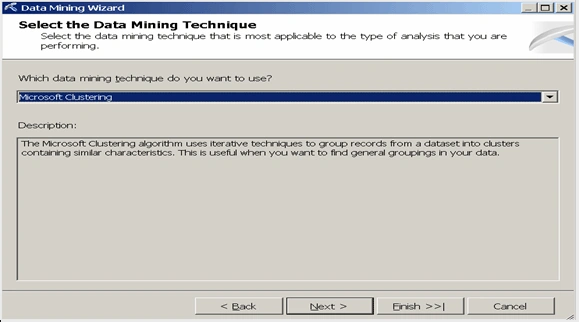
- Clustering: It is used to identify natural groupings (self-similarity groups) of cases based on a set of attributes.
- Association: The common usage of association is to identify common sets of items (frequent itemsets) and rules for the purpose of cross-selling.
- Regression: The regression task is similar to classification. The main difference is that the predictable attribute is a continuous number. Linear regression and logistic regression are the most popular regression methods. Other regression techniques include regression trees and neural networks.
- Sequence Analysis: It's used to find patterns in a discrete series. Sequence and association data are similar in the sense that each individual case contains a set of items or states. The difference between sequence and association models is that sequence models analyze the state transitions.
- Deviation Analysis: It's for finding those rare cases that behave very differently from others. It is also called outlier detection.
There are some fields where data mining application can be found such as: analysis of finance data (prediction of credit risks, discovery of fraud transactions and prediction of stock prices), analysis of genetic databases (discovery of correlations between gene sequences and protein properties, prediction of the biological effect of chemical substances), analysis of text archives (classification, retrieval of news articles, scientific publications, co-citation analysis, discovery of risk factors for diseases from medical archives), search engines (information extraction, classification of documents, disambiguation of words, relevance feedback, structuring and visualization of documents, user modeling (learning user profiles, personalized classification of documents, analysis of search behavior).
The data mining project lifecycle.
A common data mining project has lifecycle process; practitioners use CRISP DM (Cross Industry Process for Data Mining) methodology for planning, executing and controlling the whole lifecycle of former project.
CRISP DM2 comprises the following phases:
- Business understanding. (Goals: Problem goals and specification. Problem scope. Produce Project Plan. Assess the situation. Key persons). This step includes analyzing requirements, defining the scope of the problem, defining the metrics by which the model will be evaluated, create project plan and the effort distribution, and defining data mining goals from business objectives.
- Data understanding. (Goals: Collect data. Describe data. Explore data. Verify data quality.) This step is to collect initial data identifying relevant attributes, describing attributes (relevance, statistical characteristics) as well as to explore the data using techniques such as calculating the minimum and maximum values, calculating mean and standard deviations and looking for the distribution of the data and finally discovering errors and missing values in data.
- Data preparation. (Goal: Select data. Clean data. Construct data. Integrate data. Format data.) This step is to consolidate, transform and clean (correct false values, insert suitable or estimate values) the data. So, data sources which are scattered across the company and stored in several formats must be consolidated. Data representation must be standardized, for instance, if one department represents the customer information in a different schema than other, they must agree in a common vocabulary for the integration of data. It also is important to find inconsistencies (outlier entities outside the whole group) such as the age of person equal to 200 years old, and other missing information (null values). In this phase the data is generated, described and reformatted if necessary.
- Modeling. (Goal: Select modeling techniques. Generate test design. Build model. Assess model.) This is step is to build the mining model. You must separate the prepared data into two distinct dataset, training and testing dataset. You use the training dataset to build the model, and the testing dataset to test the accuracy of the former model. A model typically contains the following structure: input columns, an identifying or key column, predictable columns and the learning algorithm with its associated parameters for tuning, it depends on the experience with specific techniques and tools. Patterns are discovered by passing the original training data through the chosen algorithm. It is remarkable to say that SQL Server 2005 contains several algorithms for each type of model to build, so you must assess the best algorithm according to the business objectives and know knowledge. A good practice is to create several models and rank the former models with respect to success critical. SQL Server 2005 allows doing this task very easy.
- Evaluation. (Goal: Evaluate results. Review process. Determine next steps). This step is to evaluate the results and identify failures. Before deploying the model in the production environment, you must first test the model to measure how it performs. Also, you may have created several models and will have to decide which model performs the best according to the business success, so you may have to return to the previous step in the process, either by redefining the problem or by reinvestigating the data in the original dataset. You may test how well the model predicts unseen dataset.
- Deployment and maintenance. (Goal: Plan deployment. Plan for monitoring and maintenance. Create the final report). The last step is to deploy the developed model in the production environment and to use the model to predict and make business decisions. You may use the Integration Services provided by SQL Server 2005 to create a mining model package.
Other non-functional aspects to follow in a Data Mining project is check the data privacy and security.
Data mining basic concepts.
There are a lot of concepts in the data mining world.
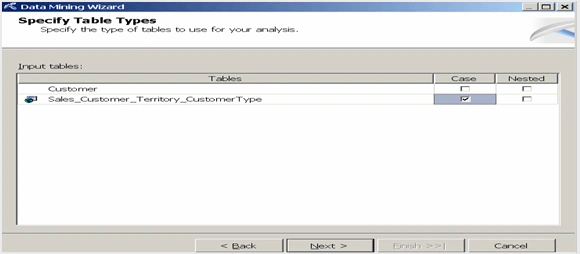
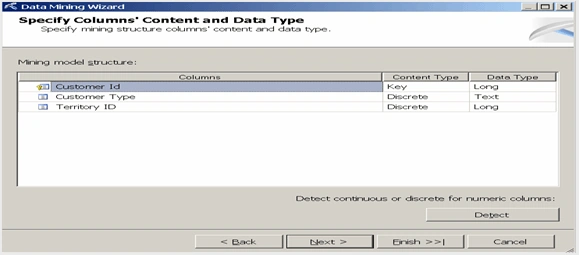
Case: a basic entity of information, that is, an information holder. It is characterized by attributes, such as Age and Fullname and its underlying state. Attributes are also called variables in statistics terms. An attribute may have values called state. Attributes may be of four different model structure types: key, input, predictable and both input and predictable and two different content types: continuous and discrete. Some may contain only input variables such as the clustering algorithm.
A case may correspond to a row in a table, but it is possible to find a case represented by at least one table row, this type of case is called nested case. Case key is the attributes which uniquely identifies the case. The primary key of the table is used often as case key. Sometimes it is composed by several primary keys, in the case of nested case.
The data mining model is characterized by key columns, input columns, and predictable columns as well as the data mining algorithm on which the model is trained. Training a data model means finding patterns in the training dataset by using the specified algorithm and the underlying parameters for tuning the algorithm. The model also stores the discovered patterns. Model training is a process for discovering knowledge about the training dataset. Model prediction is used for applying trained discovered patterns to a new dataset for predicting potential values.
The data mining algorithm3 is the mechanism that creates mining models. To create a model, an algorithm first analyzes a set of data, looking for specific patterns. The algorithm then uses the results of this analysis to define the parameters of the mining model. It is associated by the desired mining model, the mining settings; the application input specification which output a mining model result which best fits the example data.
The data mining algorithm represents the learned hypothesis using different structures such as:
- A set of rules.
- A decision tree.
- A mathematical model.
- A set of clusters.
DMX stands for Data Mining eXtensions and it is a language for defining data mining query adopting several relational concepts.
Getting started with an Data Mining project in SQL Server 2005.
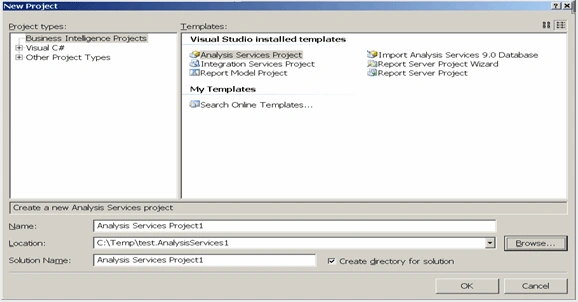
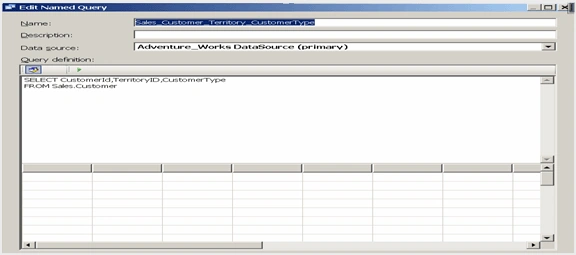
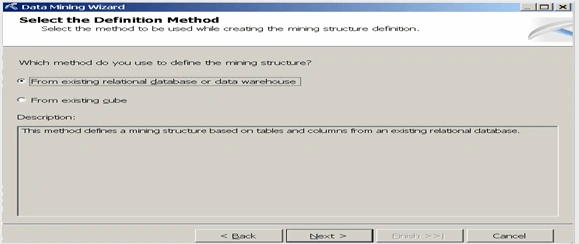
Let's create a simple illustrative data mining project. First of all, I like to say that there are two modes for working in a Data Mining Project.
Immediate mode.
Working in Immediate mode is generally a more natural experience for data mining users. When you work in Immediate mode, you are connected directly and continually to an Analysis Services server. When you open an object, such as a mining structure, you are opening the real object from the server as you would expect. When you change the object and save it, the object is immediately changed on the server.
Elavarasan RPosted Apr 20, 2018, 7:32 AM
nice article, keep Up the good work..
Reshwanth SPosted Oct 28, 2017, 10:11 AM
Thanks for sharing your knowledge
Rajni KaushalPosted Mar 3, 2017, 4:22 AM
Hi, I have created one Data mining model. Now i want to use it on my web application like we are using report viewer to show SSRS reports in dotnet. I want to show Data mining prediction report in web application created in dot net. Please suggest which tool i can use for the same. I already tried https://code.msdn.microsoft.com/Web-Enabled-SQL-Server-413ee966 code but its only working on IE 5 and 7. Not on other browsers. Please suggest on this
spark mohideenPosted Oct 9, 2009, 11:04 AM
hi guys, I read out the exact article on Data mining of sql server along the following website, i hope you can get good feel as myself. http://sql2008.info/sql2008/post/SQL-Server2008-Data-Mining.aspx
Kelly DirksPosted Sep 17, 2009, 5:07 PM
Do you have any examples / resouces for developing a multivariable regression solution? Thanks, Kelly
alireza hatamiPosted Dec 12, 2007, 4:04 PM
web are looking for a web report builder which support sql server 2005 and oracle and web chart , print reports and can use it in c# application solution. would you please to help me.