

Databricks continues to enhance workflow orchestration capabilities with the introduction of Disable Tasks in Lakeflow Jobs. Although this may appear to be a small enhancement, it provides significant operational flexibility for data engineers, platform engineers, and DevOps teams managing complex ETL and data pipelines.
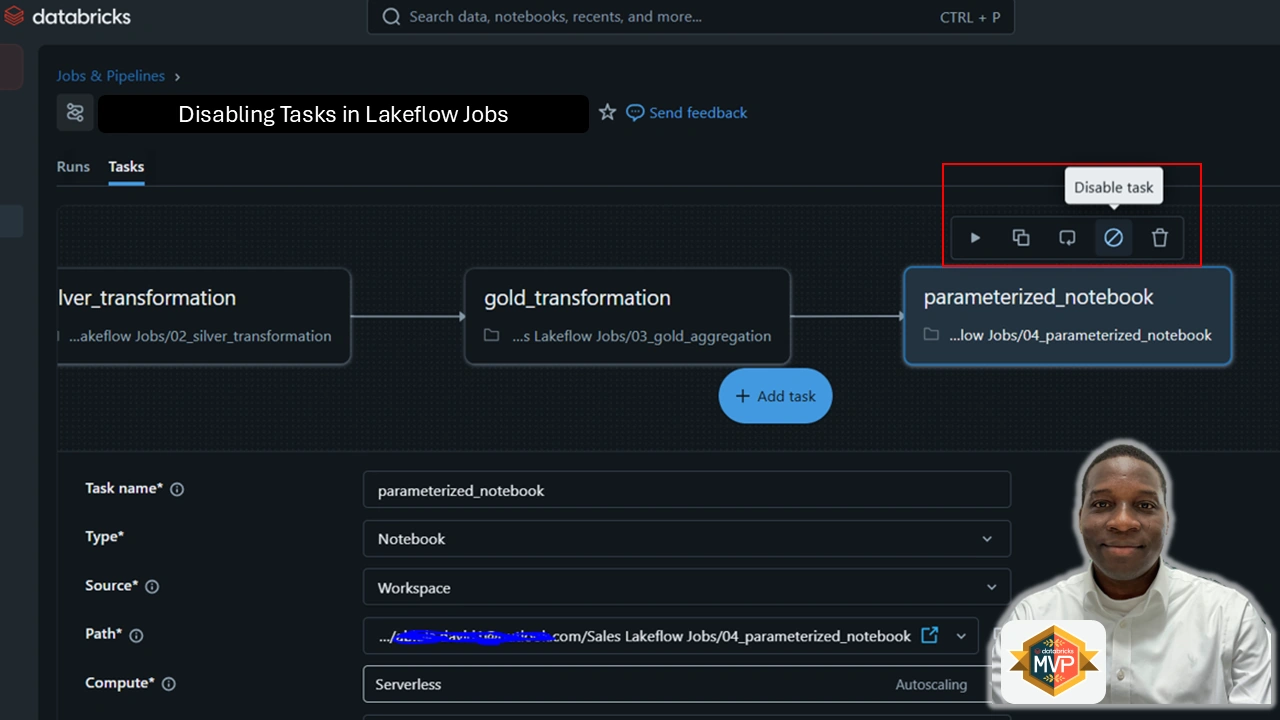
In modern data engineering environments, workflows often contain multiple dependent tasks responsible for ingestion, transformation, validation, machine learning, reporting, and notifications. During development, testing, debugging, or phased deployments, engineers frequently need to temporarily bypass specific tasks without deleting or redesigning the workflow. Previously, this required manual changes, custom conditional logic, or maintaining separate job versions. With disabled tasks, Databricks simplifies this process dramatically.
What Are Disabled Tasks in Lakeflow Jobs?
Disabled tasks allow you to temporarily deactivate specific tasks within a Lakeflow Job while preserving:
Task configuration
Dependencies
Cluster settings
Parameters
Run history
Workflow structure
Instead of deleting a task or modifying orchestration logic, you can simply disable it directly within the workflow.
This provides a cleaner and more maintainable orchestration experience.
Why This Feature Matters
In production-grade data platforms, workflows evolve continuously. Teams commonly face situations such as:
Temporarily skipping data quality checks
Disabling expensive ML scoring tasks
Pausing downstream reporting
Testing ingestion independently
Running partial workflows during debugging
Gradually deploying new pipeline stages
Handling maintenance windows
Without disabled tasks, engineers previously relied on:
Commenting out code
Creating duplicate jobs
Adding conditional notebook logic
Maintaining separate dev/test/prod workflows
Manually rewiring task dependencies
All these approaches increase complexity and operational overhead.
Disabled tasks solve this elegantly.
How Disabled Tasks Work
When a task is disabled:
The task does not execute
The workflow still retains the task definition
Databricks marks the task with a Disabled termination status
Downstream tasks behave according to their configured Run if conditions
This means workflow execution remains predictable and controlled.
For example:
Bronze Ingestion
      ↓
Silver Transformation
      ↓
Gold Aggregation
      ↓
Email Notification
If the Email Notification task is disabled:
Bronze, Silver, and Gold continue executing normally
Notification step is skipped
Workflow history remains intact
Practical Real-World Scenarios
1. Testing Individual Pipeline Layers
Suppose you are developing a Medallion Architecture pipeline:
Bronze → Silver → GoldYou may want to repeatedly test only the Bronze ingestion layer while skipping downstream transformations.
Instead of modifying notebook code, simply disable Silver and Gold tasks temporarily.
2. Phased Production Rollouts
During a new feature deployment:
Bronze ingestion may already be production-ready
Gold reporting logic may still be under testing
Disabled tasks allow partial production deployments without maintaining separate workflow versions.
3. Reducing Compute Costs
Some tasks may be resource-intensive:
ML inference
Large aggregations
External API integrations
You can temporarily disable these tasks during low-priority runs or testing windows to reduce compute consumption.
Join the conversation! Your thoughts help the community grow.