

Fraud detection is one of those domains where full automation is a liability. Auto-declining a legitimate transaction angers a customer. Auto-approving a clever fraud costs real money. The sweet spot is a system that handles the obvious cases instantly and escalates the ambiguous ones to a human analyst — without losing state, context, or momentum.
LangGraph is purpose-built for this. Its interrupt primitives + checkpointed persistence let you pause a graph mid-flight, hand control to a human (or external system), and resume exactly where you left off — even hours later, from a different process.
This article walks through building a production-grade credit card fraud detection workflow with HITL approval gates, using a real transaction review queue as the running example.
1. Why HITL Matters in Fraud Detection
A typical fraud pipeline produces a risk score between 0 and 1. Most teams bucket decisions into three zones:
| Risk Score | Zone | Action |
|---|---|---|
| 0.0 – 0.3 | Safe | Auto-approve |
| 0.3 – 0.7 | Grey zone | Human review |
| 0.7 – 1.0 | Dangerous | Auto-decline |
The grey zone is where HITL lives. It contains:
Unusual but legitimate purchases (travel, big-ticket items)
Sophisticated fraud that barely crosses thresholds
Edge cases that break your ML model
Without HITL, you either over-decline (hurting revenue and UX) or over-approve (eating fraud losses). With HITL, you get calibrated decisions with an audit trail.
2. The Use Case: Credit Card Transaction Review
Our workflow:
Transaction → Rule Check → ML Scoring → Risk Routing
                                           ├── Auto-Approve
                                           ├── Human Review (HITL) ← pause here
                                           └── Auto-Decline
                                                    ↓
                                            Final Decision → Emit Event
The human reviewer sees:
The transaction details
Rule violations triggered
ML model score + top contributing features
Customer history (last 5 transactions)
Recommended action (from a "recommend" node)
They respond with: approve, decline, or request_more_info.
3. HITL Primitives in LangGraph
Three mechanisms, pick the right one:
| Primitive | Use When |
|---|---|
interrupt_before=[node] | You know statically which node needs approval |
interrupt_after=[node] | You want to review a node's output before continuing |
raise NodeInterrupt(...) | The decision to interrupt is dynamic (e.g., based on state) |
Resuming is always done with:
graph.invoke(Command(resume=human_decision), config)Critical: HITL requires a checkpointer (persistence). Without it, the paused state is lost.
4. Setting Up the Stack
pip install langgraph langchain-openai langchain-core pydanticFor persistence, we'll use SqliteSaver locally. In production, swap for PostgresSaver.
5. Defining the State
# state.py
from typing import TypedDict, Literal, Optional
from pydantic import BaseModel

class Transaction(BaseModel):
    tx_id: str
    user_id: str
    amount: float
    currency: str
    merchant: str
    country: str
    timestamp: str

class FraudState(TypedDict):
    transaction: dict
    rule_violations: list[str]
    ml_score: float
    ml_features: dict
    customer_history: list[dict]
    recommendation: str
    human_decision: Optional[str]       # approve | decline | request_more_info
    human_notes: Optional[str]
    final_action: Optional[str]
    audit_trail: list[dict]
6. Building the Nodes
# nodes.py
from state import FraudState
from langgraph.errors import NodeInterrupt

# ---------- Rule Check ----------
def rule_check(state: FraudState) -> dict:
    tx = state["transaction"]
    violations = []
    if tx["amount"] > 5000:
        violations.append("high_amount")
    if tx["country"] not in ["US", "CA", "GB"]:
        violations.append("unusual_country")
    # In reality: velocity checks, BIN checks, etc.
    return {"rule_violations": violations}

# ---------- ML Scoring ----------
def ml_score_node(state: FraudState) -> dict:
    # Replace with your actual model call
    tx = state["transaction"]
    base = 0.1
    if "high_amount" in state["rule_violations"]:
        base += 0.3
    if "unusual_country" in state["rule_violations"]:
        base += 0.25
    # Add some noise to simulate model
    score = min(base + (hash(tx["tx_id"]) % 20) / 100, 1.0)
    return {
        "ml_score": score,
        "ml_features": {
            "amount_z_score": 2.1,
            "country_risk": 0.7,
            "merchant_risk": 0.3,
        }
    }

# ---------- Risk Routing ----------
def route_by_risk(state: FraudState) -> str:
    score = state["ml_score"]
    if score < 0.3:
        return "auto_approve"
    elif score > 0.7:
        return "auto_decline"
    else:
        return "human_review"

# ---------- Recommendation (runs before HITL) ----------
def recommend_action(state: FraudState) -> dict:
    score = state["ml_score"]
    if score < 0.45:
        rec = "approve"
    elif score < 0.55:
        rec = "request_more_info"
    else:
        rec = "decline"
    return {"recommendation": rec}

# ---------- The HITL Node ----------
def human_review(state: FraudState) -> dict:
    """This node is where the graph pauses.

    We use NodeInterrupt to dynamically pause and surface
    a review payload to the human queue."""
    tx = state["transaction"]

    # If we're resuming, human_decision is already in state
    if state.get("human_decision"):
        return {
            "audit_trail": state.get("audit_trail", []) + [{
                "step": "human_review",
                "decision": state["human_decision"],
                "notes": state.get("human_notes"),
            }]
        }

    # Otherwise, pause and surface the review payload
    review_payload = {
        "tx_id": tx["tx_id"],
        "amount": tx["amount"],
        "merchant": tx["merchant"],
        "country": tx["country"],
        "ml_score": state["ml_score"],
        "ml_features": state["ml_features"],
        "rule_violations": state["rule_violations"],
        "recommendation": state["recommendation"],
        "customer_history": state["customer_history"],
    }
    raise NodeInterrupt(review_payload)

# ---------- Final Decision ----------
def final_decision(state: FraudState) -> dict:
    if state.get("human_decision") in ("approve", "decline"):
        action = state["human_decision"]
    elif state["ml_score"] < 0.3:
        action = "approve"
    else:
        action = "decline"

    return {
        "final_action": action,
        "audit_trail": state.get("audit_trail", []) + [{
            "step": "final_decision",
            "action": action,
        }]
    }

# ---------- Auto nodes (for completeness) ----------
def auto_approve(state: FraudState) -> dict:
    return {"final_action": "approve"}

def auto_decline(state: FraudState) -> dict:
    return {"final_action": "decline"}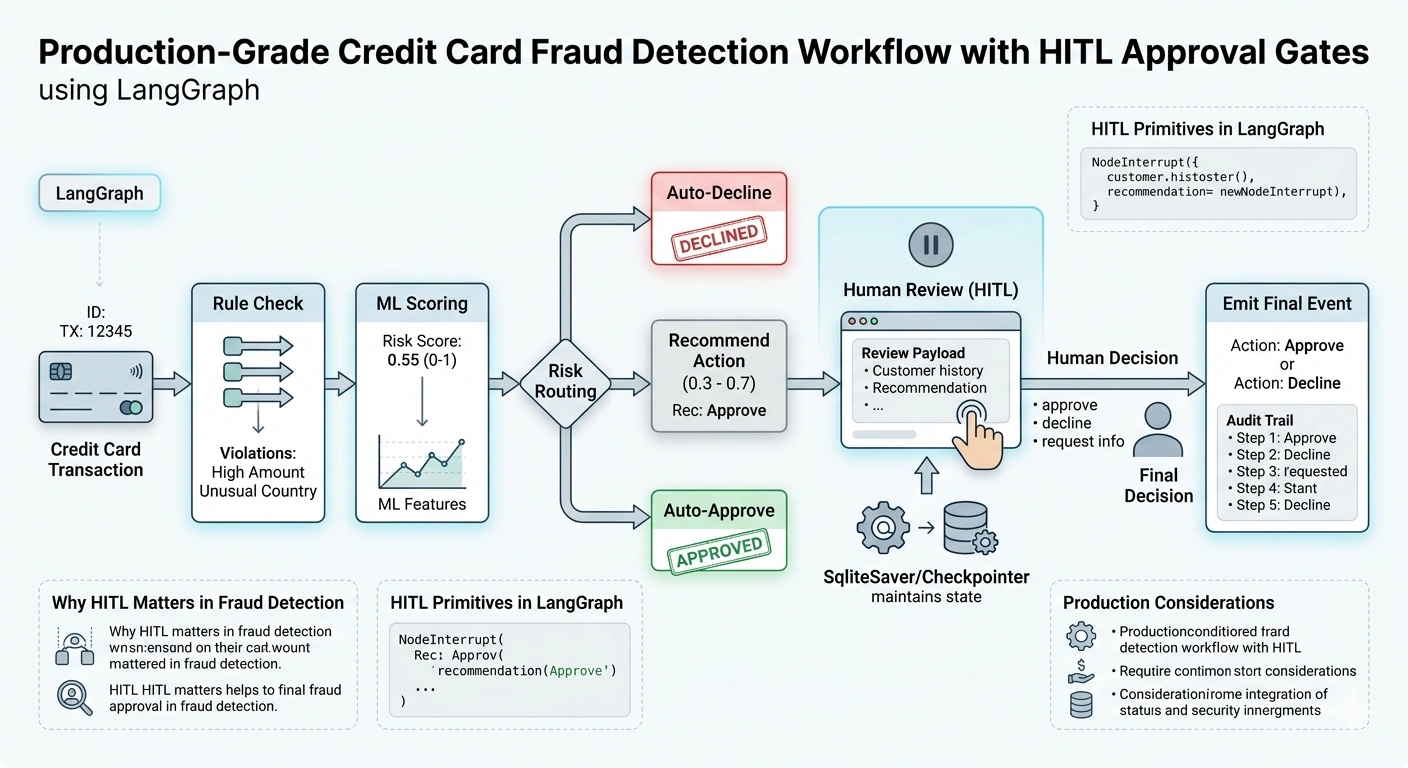
Join the conversation! Your thoughts help the community grow.