
Introduction
We have already learned about Kafka's essential architecture that consists of Producer, Consumer, Cluster, Broker, Topic, Partition, and their configurations.
In production, we configure Apache Kafka to have multiple brokers in the Cluster. It is actually possible to have one broker in Cluster, but there is no value, and we mostly use such type of configuration for testing and learning purposes.
Depending on multiple factors, we may have 3 or 30 brokers in our Cluster. Here are the reasons why we should consider multiple brokers.
1. High Availability and Fault Tolerance
With a single broker, if it goes down, our entire Kafka cluster becomes unavailable. This can be a huge risk for critical applications.
By having multiple brokers, we can replicate data across them. This ensures that if one broker fails, the data is still available on other brokers, and your applications can continue to operate with minimal disruption.
2. Scalability and Performance
As our data volume and processing needs grow, a single broker can become overwhelmed.
Adding more brokers distributes the load across multiple machines, which can significantly improve throughput and reduce latency.
This allows us to handle larger data volumes and higher message rates without impacting performance.
3. Redundancy and Disaster Recovery
Having multiple brokers in different geographic locations can help protect your data from disasters.
If one data center goes down, the data is still available to brokers in other locations.
This can be essential for mission-critical applications that require high uptime and data durability.
4. Flexibility and Manageability
With multiple brokers, we can easily add new brokers or remove old ones as needed.
This allows us to adapt your Kafka cluster to changing requirements without downtime.
Additionally, you can distribute different topics or partitions across different brokers based on their needs, which further improves performance and manageability.
5. Increased Concurrency
With multiple brokers, we can have more producers and consumers concurrently accessing your data.
This can be beneficial for applications that require high levels of parallelism.
The optimal number of brokers for your Kafka cluster will depend on our specific needs and requirements.
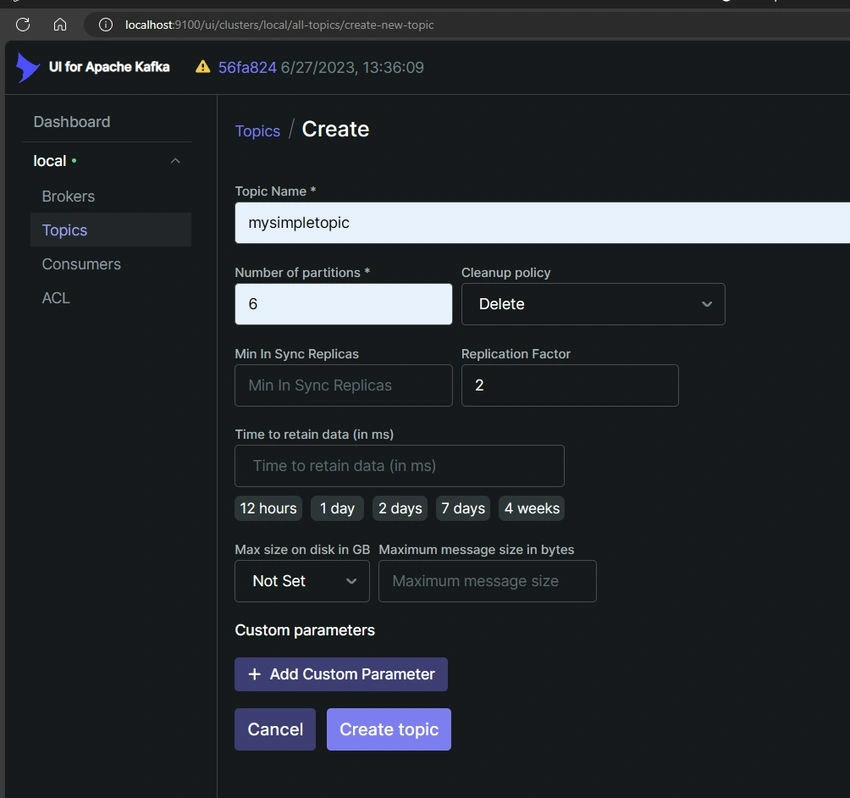
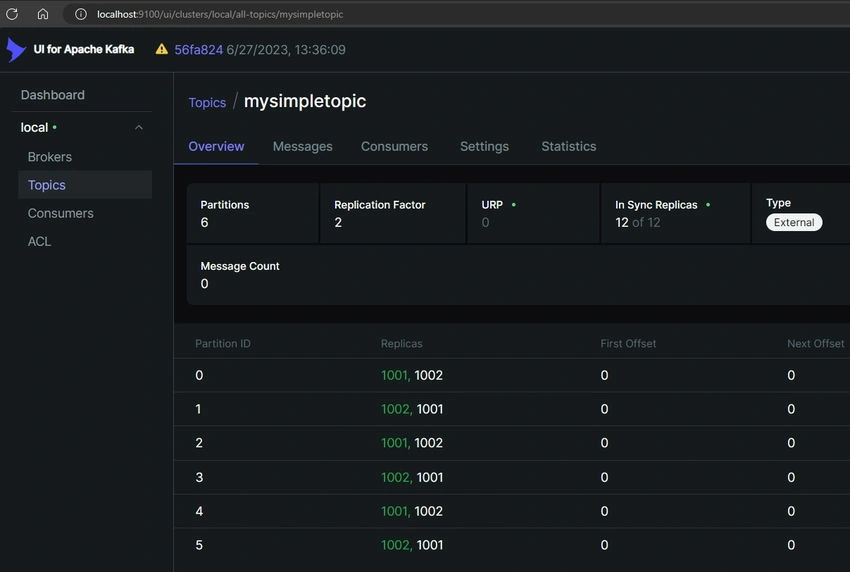
We need to carefully consider the replication factor when setting up your cluster. The replication factor determines how many copies of each message are stored on different brokers.
Adding too many brokers can also have negative impacts, such as increased complexity and management overhead.
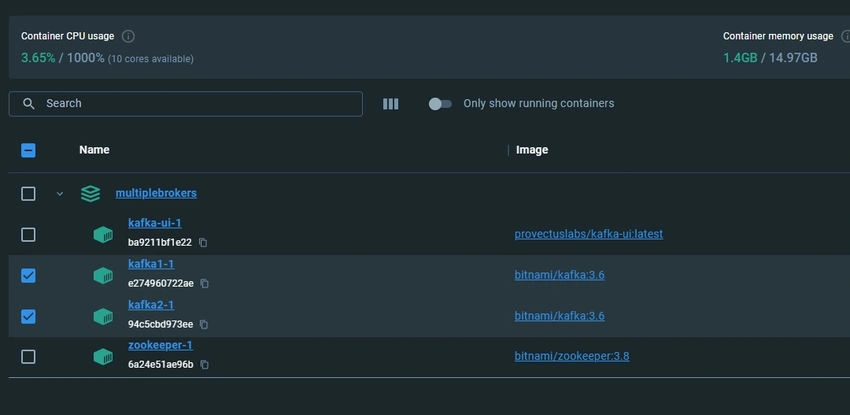
The above sayings sound interesting, but actually, how do we have a cluster with multiple (at least with more than one) brokers?
We have several ways of configuring it but the easiest one I think is the docker-compose file. What do you need?
- Running the docker desktop application
- The proper docker-compose.yml file to run

Join the conversation! Your thoughts help the community grow.