

Linear Regression using Python
In the previous article, we studied Data Science. One thing that I believe is that if we can correlate anything with us or our life, there are greater chances of understanding the concept. So I will try to explain everything by relating it to humans.
What is Regression and Why is it called so?
Regression is an ML algorithm that can be trained to predict real numbered outputs; like temperature, stock price, etc. Regression is based on a hypothesis that can be linear, quadratic, polynomial, non-linear, etc. The hypothesis is a function based on some hidden parameters and input values. In the training phase, the hidden parameters are optimized w.r.t. the input values presented in the training. The process that does the optimization is the gradient descent algorithm. You also need a Back-propagation algorithm that can be used to compute the gradient at each layer, If you are using neural networks. Once the hypothesis parameters got trained (when they gave the least error during the training), then the same hypothesis with the trained parameters is used with new input values to predict outcomes that will be again real values.
Advantages/Features of Linear Regression
- Linear regression is an extremely simple method.
- It is very easy and intuitive to use and understand.
- A person with only the knowledge of high school mathematics can understand and use it.
- In addition, it works in most cases. Even when it doesn’t fit the data exactly, we can use it to find the nature of the relationship between the two variables.
Disadvantages/Shortcomings of Linear Regression
- By its definition, linear regression only models relationships between dependent and independent variables that are linear. It assumes there is a straight-line relationship between them which is incorrect sometimes. Linear regression is very sensitive to the anomalies in the data (or outliers).
- Take for example most of your data lies in the range 0-10. If due to any reason only one of the data items comes out of the range, say for example 15, this significantly influences the regression coefficients.
- Another disadvantage is that if we have a number of parameters than the number of samples available then the model starts to model the noise rather than the relationship between the variables.
Types of Regression
1. Linear regression is used for predictive analysis. Linear regression is a linear approach for modeling the relationship between the criterion or the scalar response and the multiple predictors or explanatory variables. Linear regression focuses on the conditional probability distribution of the response given the values of the predictors. For linear regression, there is a danger of overfitting. The formula for linear regression is Y’ = bX + A.
2. Logistic regression is used when the dependent variable is dichotomous. Logistic regression estimates the parameters of a logistic model and is a form of binomial regression. Logistic regression is used to deal with data that has two possible criteria and the relationship between the criteria and the predictors. The equation for logistic regression is l =  .
.3. Polynomial regression is used for curvilinear data. Polynomial regression is fit with the method of least squares. The goal of regression analysis to model the expected value of a dependent variable y in regards to the independent variable x. The equation for polynomial regression is l = 
4. Stepwise regression is used for fitting regression models with predictive models. It is carried out automatically. With each step, the variable is added or subtracted from the set of explanatory variables. The approaches for stepwise regression are forward selection, backward elimination, and bidirectional elimination. The formula for stepwise regression is 
5. Ridge regression is a technique for analyzing multiple regression data. When multicollinearity occurs, least squares estimates are unbiased. A degree of bias is added to the regression estimates, and a result, ridge regression reduces the standard errors. The formula for ridge regression is 
6. Lasso regression is a regression analysis method that performs both variable selection and regularization. Lasso regression uses soft thresholding. Lasso regression selects only a subset of the provided covariates for use in the final model. Lasso regression is:  .
.7. ElasticNet regression is a regularized regression method that linearly combines the penalties of the lasso and ridge methods. ElasticNet regression is used to support vector machines, metric learning, and portfolio optimization. The penalty function is given by: 
9. Decision Tree regression is a regression where the ID3 algorithm can be used to identify the splitting node by reducing the standard deviation (in classification information gain is used).
A decision tree is built by partitioning the data into subsets containing instances with similar values (homogenous). Standard deviation is used to calculate the homogeneity of a numerical sample. If the numerical sample is completely homogeneous, its standard deviation is zero.
10. Random Forest regression is an ensemble approach where we take into account the predictions of several decision regression trees.
- Select K random points
- Identify n where n is the number of decision tree regressors to be created. Repeat steps 1 and 2 to create several regression trees.
- The average of each branch is assigned to the leaf node in each decision tree.
- To predict output for a variable, the average of all the predictions of all decision trees are taken into consideration.
Key Terms
1. Estimator
A formula or algorithm for generating estimates of parameters, given relevant data.
2. Bias
An estimate is unbiased if its expectation equals the value of the parameter being estimated; otherwise, it is biased.
3.Efficiency
An estimator A is more efficient than an estimator B if A has a smaller sampling variance — that is, if the particular values generated by A are more tightly clustered around their expectation.
4. Consistency
An estimator is consistent if the estimates it produces converge on the true parameter value as the sample size increases without limit. Consider an estimator that produces estimates θ^ of some parameter θ, and let ^ denote a small number. If the estimator is consistent, we can make the probability as close to 1.0 as we like or as small as we like by drawing a sufficiently large sample. Note that a biased estimator may nonetheless be consistent if the bias tends to zero in the limit. Conversely, an unbiased estimator may be inconsistent if its sampling variance fails to shrink appropriately as the sample size increases.
5. Standard error of the Regression (SER)
An estimate of the standard deviation of the error term in a regression model.
6. R-squared
A standardized measure of the goodness of fit for a regression model.
7. Standard error of regression coefficient
An estimate of the standard deviation of the sampling distribution for the coefficient in question.
8. P-value
The probability, supposing the null hypothesis to be true, of drawing sample data that are as adverse to the null as the data are actually drawn, or more so. When a small p-value is found, the two possibilities are that we happened to draw a low-probability unrepresentative sample or that the null hypothesis is in fact false.
9. Significance level
For a hypothesis test, this is the smallest p-value for which we will not reject the null hypothesis. If we choose a significance level of 1%, we're saying that we'll reject the null if and only if the p-value for the test is less than 0.01. The significance level is also the probability of making a type 1 error (that is, rejecting a true null hypothesis).
10. T-test
The t-test (or z-test, which is the same thing asymptotically) is a common test for the null hypothesis that a particular regression parameter, βi, has some specific value (commonly zero, but generically βH0).
11. F-test
A common procedure for jointly testing a set of linear restrictions on a regression model.
12. Multicollinearity
A situation where there is a high degree of correlation among the independent variables in a regression model — or, more generally, where some of the Xs are close to being linear combinations of other Xs. Symptoms include large standard errors and the inability to produce precise parameter estimates. This is not a serious problem if one is primarily interested in forecasting; it is a problem is one is trying to estimate causal influences.
13. Omitted variable bias
Bias in the estimation of regression parameters that arises when a relevant independent variable is omitted from a model and the omitted variable is correlated with one or more of the included variables.
14. Log variables
A common transformation permits the estimation of a nonlinear model using OLS to substitute the natural log of a variable for the level of that variable. This can be done for the dependent variable and/or one or more independent variables. A key point to remember about logs is that for small changes, the change in the log of a variable is a good approximation to the proportional change in the variable itself. For example, if log(y) changes by 0.04, y changes by about 4%.
15. Quadratic terms
Another common transformation. When both xi and x^2_i are included as regressors, it is important to remember that the estimated effect of xi on y is given by the derivative of the regression equation with respect to xi. If the coefficient on xi is β and the coefficient on x 2 i is γ, the derivative is β + 2γ xi.
16. Interaction terms
Pairwise products of the "original" independent variables. The inclusion of interaction terms in a regression allows for the possibility that the degree to which xi affects y depends on the value of some other variable x j. In other words, x j modulates the effect of xi on y. For example, the effect of experience on wages (xi) might depend on the gender (x j) of the worker.
17. Independent Variable
An independent variable is a variable that is changed or controlled in a scientific experiment to test the effects on the dependent variable.
18. Dependent Variable
A dependent variable is a variable being tested and measured in a scientific experiment. The dependent variable is 'dependent' on the independent variable. As the experimenter changes the independent variable, the effect on the dependent variable is observed and recorded.
19. Regularization
There are extensions of the training of the linear model called regularization methods. These seek to both minimize the sum of the squared error of the model on the training data (using ordinary least squares) but also to reduce the complexity of the model (like the number or absolute size of the sum of all coefficients in the model).
Gradient Descent
Gradient descent is an optimization algorithm used to minimize some function by iteratively moving in the direction of steepest descent as defined by the negative of the gradient. In machine learning, we use gradient descent to update the parameters of our model. Parameters refer to coefficients in Linear Regression and weights in neural networks.
1. Learning Rate
The size of these steps is called the learning rate. With a high learning rate, we can cover more ground each step, but we risk overshooting the lowest point since the slope of the hill is constantly changing. With a very low learning rate, we can confidently move in the direction of the negative gradient since we are recalculating it so frequently. A low learning rate is more precise, but calculating the gradient is time-consuming, so it will take us a very long time to get to the bottom.
2. Cost Function
A Loss Function or Cost Function tells us “how good” our model is at making predictions for a given set of parameters. The cost function has its own curve and its own gradients. The slope of this curve tells us how to update our parameters to make the model more accurate.
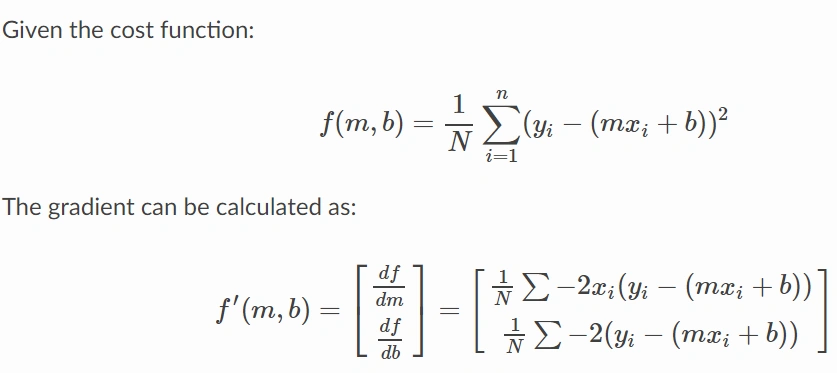
Python Implementation of Gradient Descent
- def update_weights(m, b, X, Y, learning_rate):
- m_deriv = 0
- b_deriv = 0
- N = len(X)
- for i in range(N):
- # Calculate partial derivatives
- # -2x(y - (mx + b))
- m_deriv += -2*X[i] * (Y[i] - (m*X[i] + b))
- # -2(y - (mx + b))
- b_deriv += -2*(Y[i] - (m*X[i] + b))
- # We subtract because the derivatives point in direction of steepest ascent
- m -= (m_deriv / float(N)) * learning_rate
- b -= (b_deriv / float(N)) * learning_rate
- return m, b
Remembering Variables With DRYMIX
When results are plotted in graphs, the convention is to use the independent variable as the x-axis and the dependent variable as the y-axis. The DRY MIX acronym can help keep the variables straight:
- D is the dependent variable
- R is the responding variable
- Y is the axis on which the dependent or responding variable is graphed (the vertical axis)
- M is the manipulated variable or the one that is changed in an experiment
- I is the independent variable
- X is the axis on which the independent or manipulated variable is graphed (the horizontal axis)
Simple Linear Regression Model
The simple linear regression model is represented like this: y = (β0 +β1 + Ε)
By mathematical convention, the two factors that are involved in simple linear regression analysis are designated x and y. The equation that describes how y is related to x is known as the regression model. The linear regression model also contains an error term that is represented by Ε, or the Greek letter epsilon. The error term is used to account for the variability in y that cannot be explained by the linear relationship between x and y. There also parameters that represent the population being studied. These parameters of the model are represented by (β0+β1x).
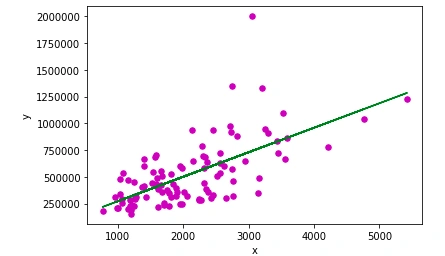
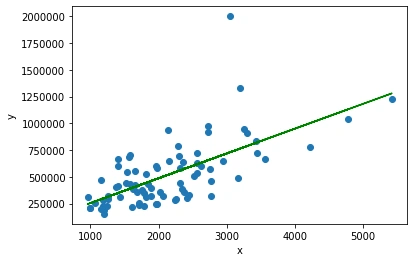
The simple linear regression equation is graphed as a straight line.
The simple linear regression equation is represented like this: Ε(y) = (β0 +β1*x)
- β0 is the y-intercept of the regression line.
- β1 is the slope.
- Ε(y) is the mean or expected value of y for a given value of x.
A regression line can show a positive linear relationship, a negative linear relationship, or no relationship.
- If the graphed line in a simple linear regression is flat (not sloped), there is no relationship between the two variables.
- If the regression line slopes upward with the lower end of the line at the y-intercept (axis) of the graph, and the upper end of the line extending upward into the graph field, away from the x-intercept (axis) a positive linear relationship exists.
- If the regression line slopes downward with the upper end of the line at the y-intercept (axis) of the graph, and the lower end of the line extending downward into the graph field, toward the x-intercept (axis) a negative linear relationship exists.
ŷ = β0 +β1*x
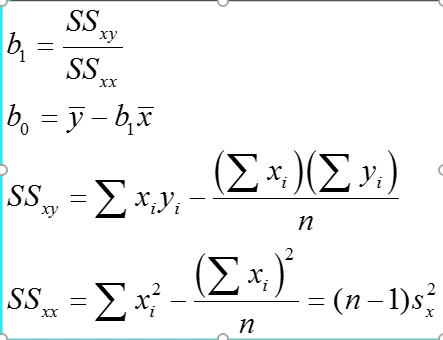
Important Note
1. Regression analysis is not used to interpret cause-and-effect relationships( a mechanism where one event makes another event happen, i.e each event is dependent on one-another) between variables. Regression analysis can, however, indicate how variables are related or to what extent variables are associated with each other.
2. It is also known as bivariate regression or regression analysis
Sum of Square Errors
This is the sum of differences between the points and the regression line. It can serve as a measure of how well the line fits the data.

Standard Estimate of Errors
The mean error is equal to zero. If se(sigma_epsilon) is small the errors tend to be close to zero (close to the mean error). Then, the model fits the data well. Therefore, we can use se as a measure of the suitability of using a linear model. An estimator of se is given by se(sigma_epsilon)
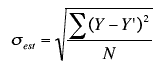
Coefficient of Determination
To measure the strength of the linear relationship we use the coefficient of determination. R^2 takes on any value between zero and one.
- R^2 = 1: Perfect match between the line and the data points.
- R^2 = 0: There is no linear relationship between x and y.

Simple Linear Regression Example
Let's take the example of Housing Price Prediction, the data that I am using is KC House Prices, you can download it from the article. Feel free to use any dataset, there some very good datasets available on kaggle and with Google Colab.
Before we start with this, it is highly recommended you read the following tutorials
- import pandas as pd
- df = pd.read_csv("kc_house_data.csv")
- df.describe()
Output
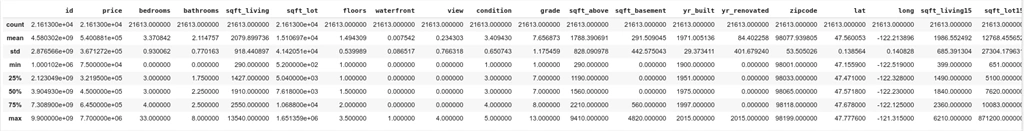
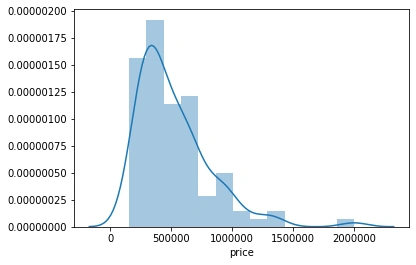
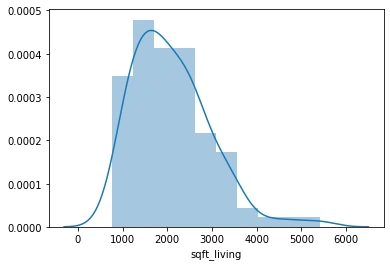
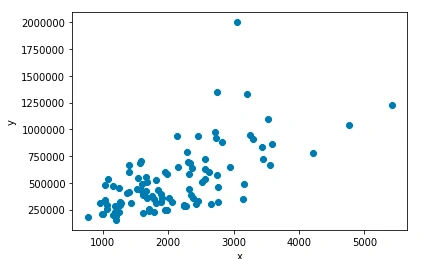
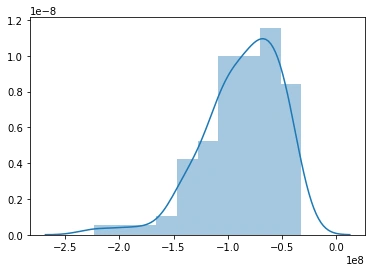
From the above data, we can see that we have a lot of tables, but simple linear regression can only process two columns, so we select the "price" and "sqrt_living". Here we will take the first 100 rows for our demonstration.
Before fitting the data let's analyze the data:
- import seaborn as sns
- df = pd.read_csv("kc_house_data.csv")
- sns.distplot(df['price'][1:100])
Output
- import seaborn as sns
- df = pd.read_csv("kc_house_data.csv")
- sns.distplot(df['sqrt_living'][1:100])
Rikam PalkarPosted Sep 8, 2020, 11:11 PM
Woh, Now that's something to read. Much appreciate it Rohit Gupta
Elavarasan RPosted Nov 7, 2019, 4:06 AM
Nice article, very useful to me..
Pankajkumar PatelPosted Oct 30, 2019, 11:54 PM
Nice article
Sourav Kumar DasPosted Oct 28, 2019, 11:55 PM
Nice Article Sir..
Onkar SharmaPosted Oct 28, 2019, 7:13 AM
Superb Article...
Sundaram SubramanianPosted Oct 28, 2019, 7:08 AM
I have read many articles on the same topic, where it was difficult to understand even it has examples. But today after reading your article, it gave me an immediate understanding. The way you wrote is clear.