
Introduction
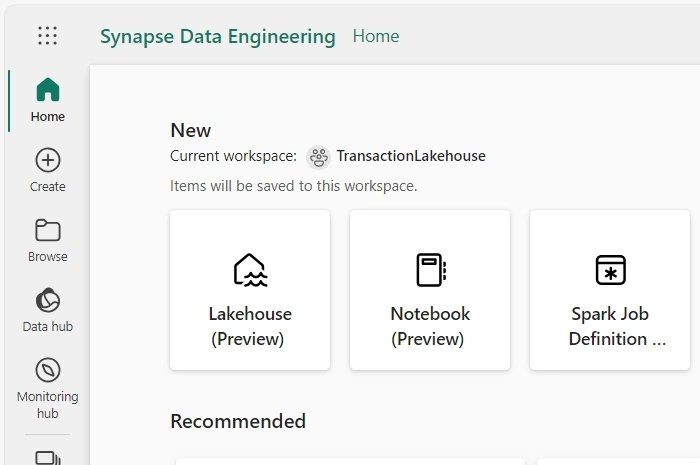
In this article, we will learn about the Microsoft Fabric Lakehouse object located in the Synapse Data Engineering platform. The Microsoft Fabric Lakehouse is a versatile data architecture platform designed to centralize the storage, administration, and examination of both structured and unstructured data in one unified repository. This adaptable and expandable solution empowers enterprises to effectively manage extensive data sets, utilizing a variety of tools and frameworks for data processing and analysis. It seamlessly incorporates other data management and analytics tools, delivering a comprehensive solution for data engineering and analytics needs.
Interacting with Lakehouse Components
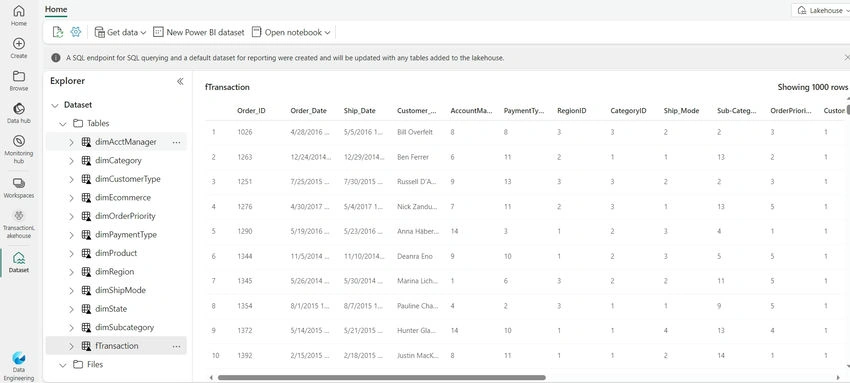
- The Lakehouse Explorer: Serving as the primary interface for the Lakehouse, the explorer enables users to load data into their Lakehouse, explore data within it using the object explorer, and manage tasks such as setting MIP labels and more. To delve deeper into the explorer experience, navigate through the Fabric Lakehouse Explorer.
- Notebooks: Users can utilize notebooks to write code for tasks like reading, transforming, and writing data directly into the Lakehouse as tables or folders. Gain a better understanding of using notebooks for your Lakehouse by exploring these resources: "Exploring Data in Your Lakehouse with a Notebook" and "How to Utilize a Notebook to Load Data into Your Lakehouse."
- Pipelines: Data engineers have the option to employ data integration tools, such as the pipeline copy tool, to extract data from various sources and deposit it into the Lakehouse. To discover more about the copy activity, refer to "How to Copy Data Using Copy Activity."
- Apache Spark Job Definitions: Data engineers can craft robust applications and oversee the execution of compiled Spark jobs in languages like Java, Scala, and Python. Explore further insights into Spark jobs by reading "What Is an Apache Spark Job Definition?"
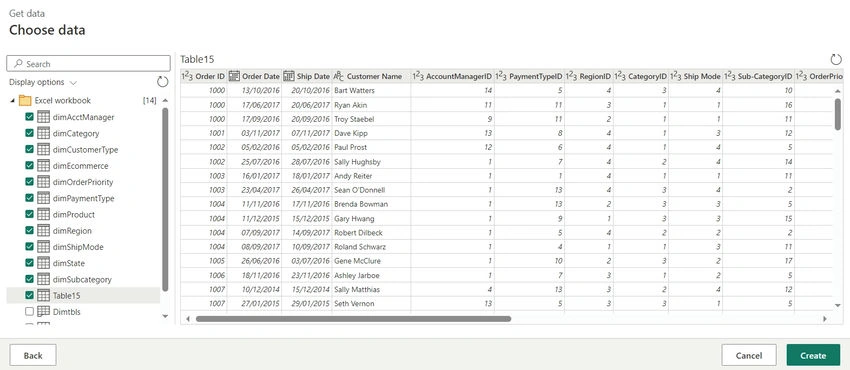
- Dataflows Gen 2: Data engineers can leverage Dataflows Gen 2 to ingest and prepare their data. For comprehensive instructions on loading data using dataflows, consult "Create Your First Dataflow to Obtain and Transform Data."
Creating a Workspace
To use the Synapse Data Engineering platform of the Fabric in creating a Lakehouse, it is required to create a Workspace. To create the workspace.
- Click on the PowerBI icon at the bottom left of the Microsoft Fabric welcome page and select Workspaces.
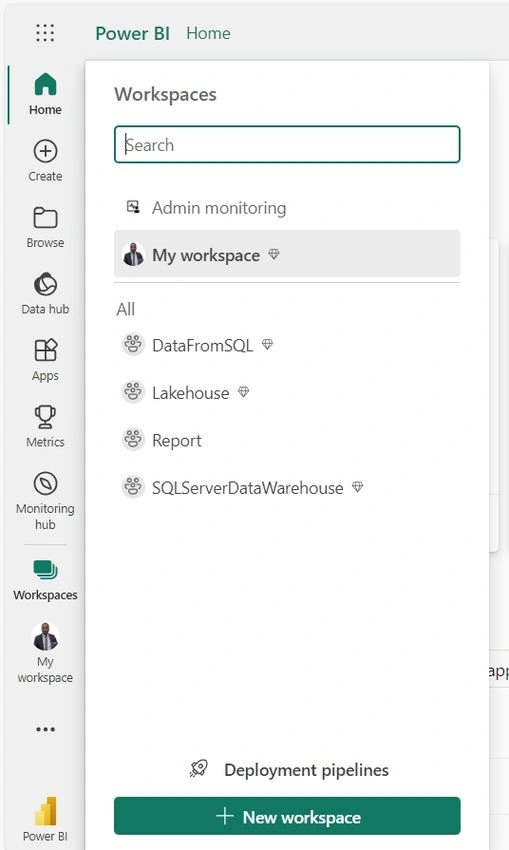
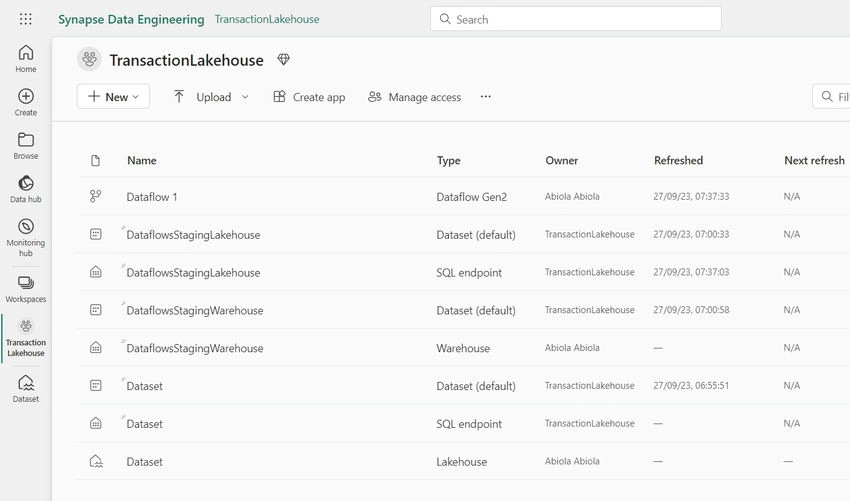
In the workspaces pane, click on New Workspace. - Next, provide a suitable name for the workspace. For this article, TransactionLakehouse is provided as the name.
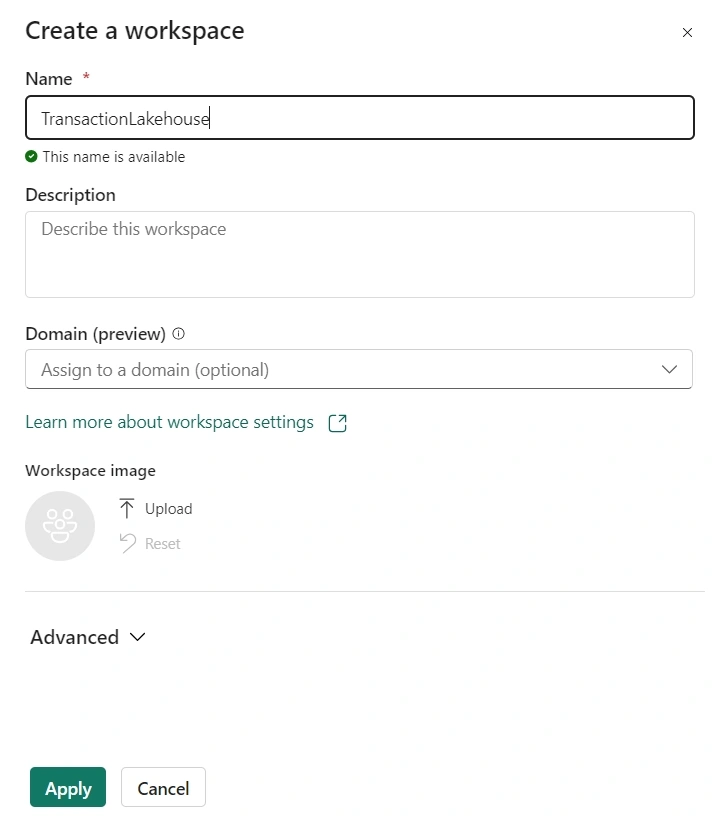
- Click on Apply.
Join the conversation! Your thoughts help the community grow.