
Introduction
Large Language Models (LLMs) have revolutionized AI-driven applications, from chatbots to code generation. However, their computational demands pose significant challenges, particularly in real-time inference. Azure AI Supercomputing Clusters provide the necessary infrastructure to optimize LLM inference, ensuring faster, cost-effective, and scalable AI deployments. This article explores how to leverage Azure’s AI supercomputing capabilities for efficient LLM inference.
The Challenge of LLM Inference
LLMs, such as GPT-based models, require extensive computing resources due to,
- High computational overhead: Processing complex queries necessitates vast parallel processing.
- Memory bottlenecks: Handling large parameter models demands efficient memory distribution.
- Latency constraints: Applications such as chatbots and automated assistants need real-time responses.
- Scalability limitations: Scaling inference across multiple nodes introduces synchronization challenges.
To address these challenges, Azure AI Supercomputing Clusters offer specialized infrastructure designed to optimize LLM inference.
Leveraging Azure AI Supercomputing Clusters
Azure AI Supercomputing Clusters provide a robust ecosystem for deploying and optimizing LLM inference through a combination of cutting-edge hardware and software solutions.
1. GPU-Accelerated Inference
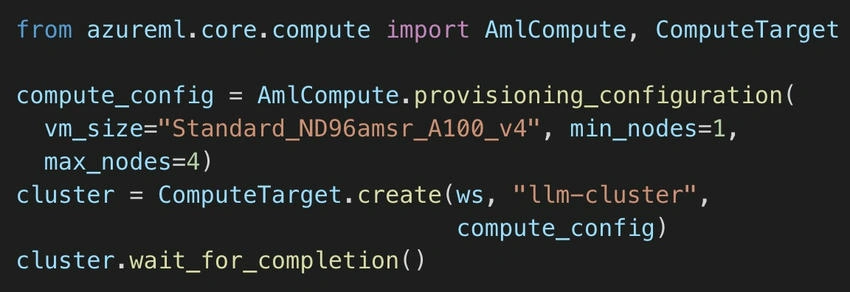
Azure integrates powerful GPUs, including NVIDIA A100 and H100 Tensor Core GPUs, to accelerate deep learning workloads. Using GPU parallelism, model inference time is drastically reduced. Key features include.
- Tensor cores for optimized matrix operations
- Multi-GPU scaling for distributed inference
- High-bandwidth memory (HBM) for efficient data access
2. Model Parallelism and Optimization Techniques
Azure AI offers model parallelism strategies, enabling efficient inference on massive models.
- Tensor Parallelism: Splits model layers across multiple GPUs, reducing memory overhead.
- Pipeline Parallelism: Distributes computation across sequential layers for improved utilization.
- Mixture of Experts (MoE): Activates only relevant portions of the model during inference, optimizing compute usage.
Join the conversation! Your thoughts help the community grow.