
Introduction
Once trained, Neural Networks are fairly good at recognizing voices, images, and objects in every frame of a video – even when you are playing the video. Let’s say you are not able to buy an expensive painting from a famous painter; can you create/generate an artificial painter who can paint like any famous artist by learning from his/her past collections? The answer is Yes – using Generative adversarial networks (GAN) you can. Generative Adversarial Networks (GANs) are a class of algorithms used in unsupervised learning -- you don’t need labels for your dataset in order to train a GAN.
So what is a GAN?
Let’s take the example of a painter to understand GAN. The intuitive idea for a GAN is that there is an expert deep neural network and a learner deep neural network. Then we make them fight against each other, endlessly attempting to out-do one another. In the process, they both become stronger.
The expert has information about the original painting. The learner learns in multiple passes where it generates the neural network and gives its output to the expert to check correctness. The job of the expert is to find the real vs fake. As the process continues, the expert and learner are trained in an alternating fashion. So the expert and learner - they are dependent on each other for efficient training. If one of them fails, the whole system fails.
Architecture
Generative adversarial networks consist of two models: a generative model and a discriminative model. The discriminative model is our expert here and the generative model is the learner.
The whole foundation of GANs is the equilibrium between the two networks. They help each other adapt and become stronger. They are both addressing different problems, i.e, the discriminator is a classifier network and generator is a regressor network. They have different architectures and are trained with different loss functions. Hence they cannot use each other's weights.
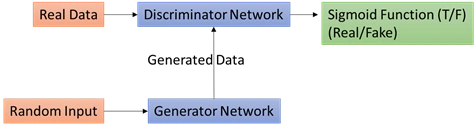
The discriminator model is a classifier that determines whether a given image looks like a real image from the dataset or like an artificially created image. This is basically a binary classifier that will take the form of a normal convolutional neural network (CNN).
The generator model takes random input values and transforms them into images through a deconvolution neural network. After many training iterations, the weights and biases in the discriminator and the generator are trained through backpropagation.
- Do a forward pass through the Generator network. This outputs the “fake” image since it is created from the Generator.
- Use the fake image as the input to do a forward and backward pass through the Discriminator network. We set the labels for logistic regression to 0 to represent that this is a fake image. This trains the Discriminator to learn what a fake image looks like. We save the gradient produced in backpropagation for the next step.
- Do a forward and backward pass through the Discriminator using a real image. The label for logistic regression will now be 1 to represent the real images, so the Discriminator can learn to recognize a real image.
- Update the Discriminator by adding the result of the gradient generated during backpropagation on the fake image with the gradient from backpropagation on the real image.
- Now that the Discriminator has been updated for this data batch, we still need to update the Generator. First, do a forward and backward pass with the same data batch on the updated Discriminator, to produce a new gradient. Use the new gradient to do a backward pass.

Elavarasan RPosted Aug 14, 2018, 11:50 PM
Nice explanation...
Mahesh ChandPosted Feb 24, 2018, 8:16 AM
Nice Veena. Hope all is well. Are you planning to attend the conference this year?
Gajendra JangidPosted Feb 24, 2018, 12:18 AM
Vary imprassive......