
Introduction
In continuation of our previous article, we will look at how could we use parameterization in datasets and pipelines. We will also implement a pipeline with simple copy activity to see how and where we can implement parameters in the Azure data factory.
Consider a scenario where you want to run numerous pipelines with many datasets for your project. At times this becomes very hard to manage multiple linked services one for server name, database with different credentials and it becomes a tedious process. What if there is a way to use a single linked service or pipeline for all requirements, sounds good right? This is what exactly parameterization does. It helps us to enter the server name, database name, credentials, etc., dynamically when we are running the pipeline thereby helping us to reuse instead of creating one for each request.
Parameterization in Datasets
Let’s look at a demo on how to get used to the parameterization in datasets. In my previous article, I have discussed how to use parameterization in linked services. On that, I have created a parameter for database name which obviously means that I can give different DB names dynamically over the run time instead of creating a linked service for each requirement.
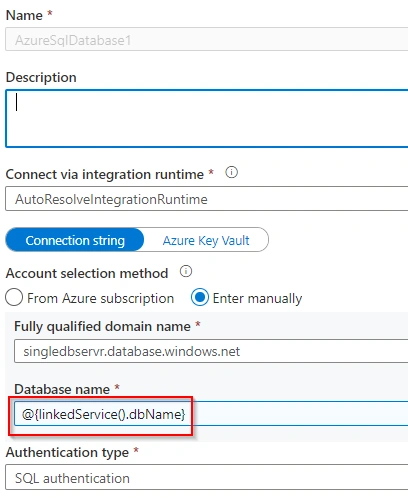
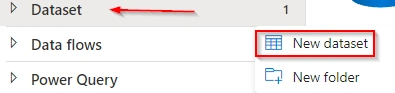
Now go to azure data factory studio and create a new dataset like given below.
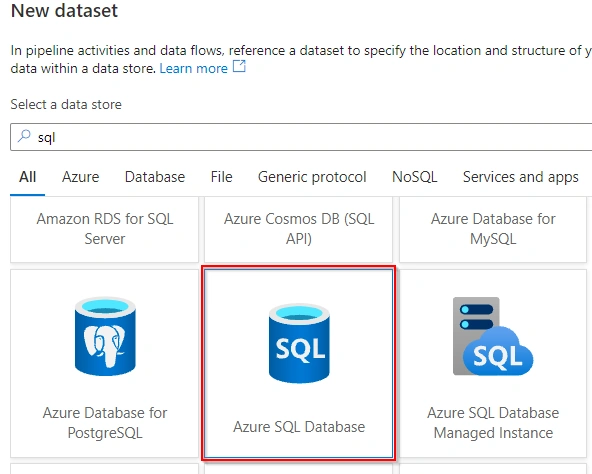
I have a SQL database in my azure subscription which I will use for this demo. The database can be selected as per your choice within the given list.
After creating the dataset, I have selected the linked services which I have created earlier and then I am creating two parameters through the parameters tab, one for dbName and tableName. Remember the dbName parameter is which we created when creating Linked services earlier hence I have referred here to add to the table name as well. The default values can be left blank as we should be able to pass the values dynamically when running the pipeline.
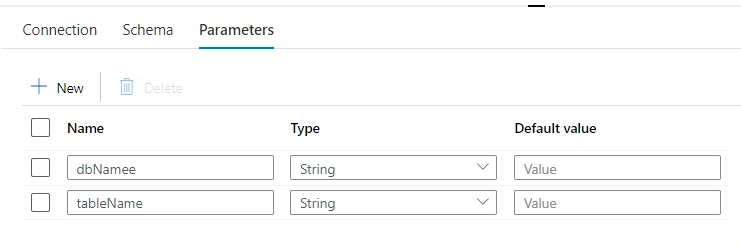
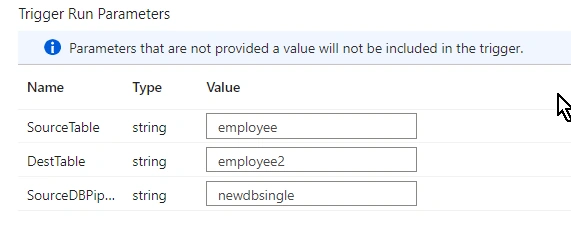
Once this is done you can call your dataset anywhere in the pipeline and pass on values at run-time.
Parameterization in Pipelines
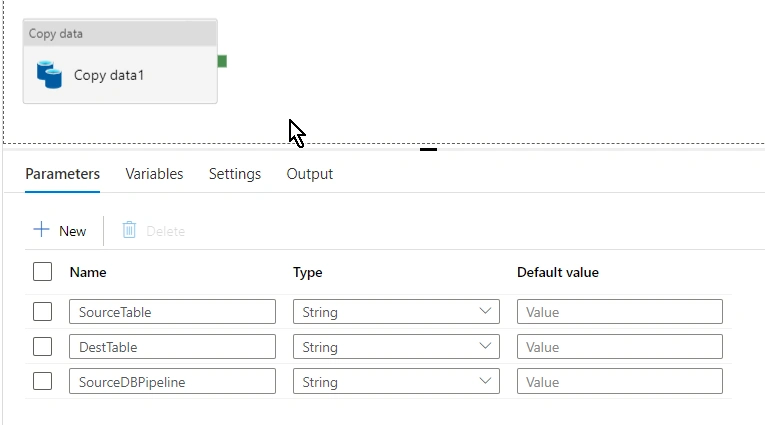
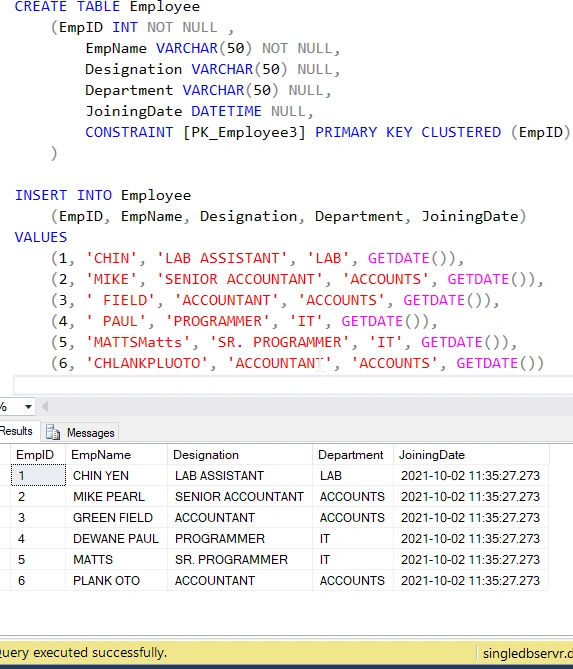
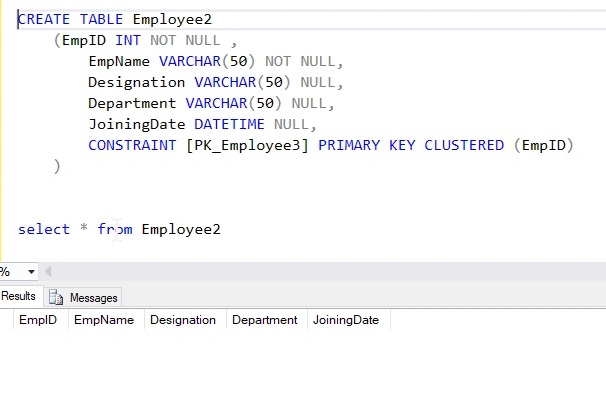
The demo task we are looking at today is to copy records from one table to another in a SQL database. We will create a new pipeline and then click and drag the ‘Copy data’ task from ‘Move & transform’. There will be options with multiple tables for configuring source and sink(destination), settings, etc. once when you click the copy data task.
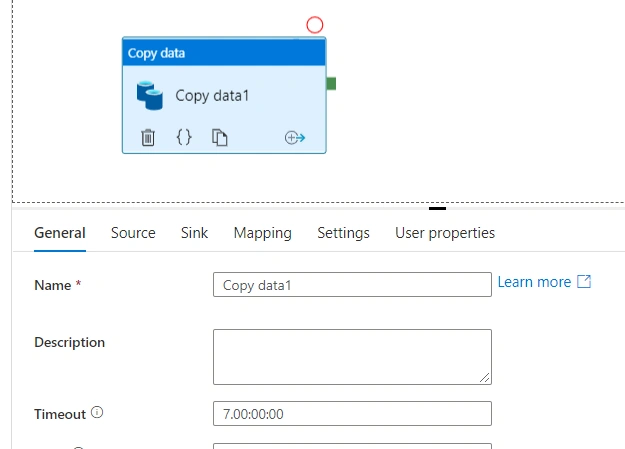
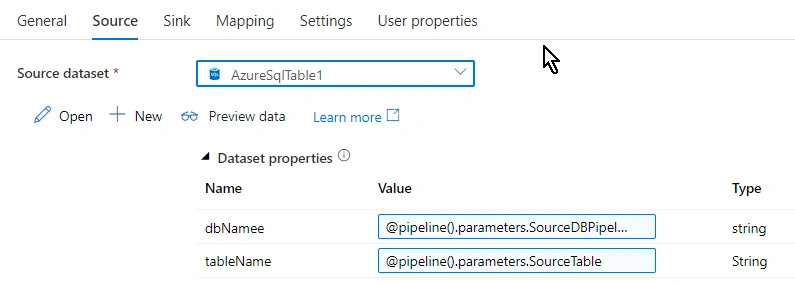
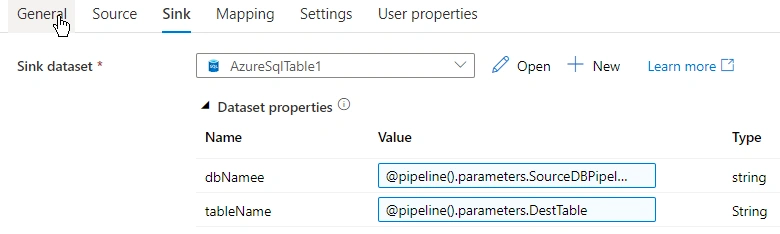
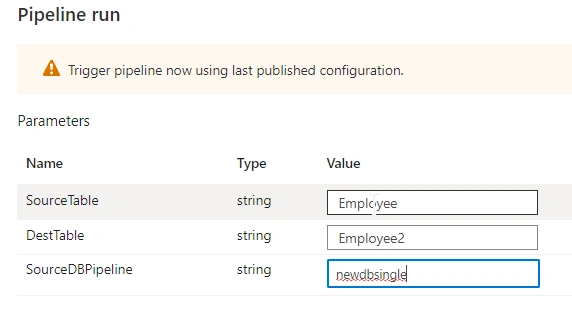
Other than all the tabs provided here, the tabs we will work on are source and sink. Obviously, we have to call the dataset that we have created in the previous section into the ‘Source’ tab. We can see the parameters that we used when creating the dataset will be listed out as soon as we select the source dataset -dbName and tableName in this case.
Join the conversation! Your thoughts help the community grow.