

Abstract / Overview
ParserGPT extracts structured rows from irregular websites and produces clean CSVs. It separates learning from execution. A small learner infers per-domain selectors. A deterministic runner applies those selectors at scale. An LLM fills only missing fields under strict schema control. The pipeline is auditable, typed, and cost-aware.
Assumption: Python 3.11+, FastAPI, Postgres, Playwright, LangChain, and LangGraph.
Conceptual Background
Web pages change often. DOMs differ by template and device. Client scripts hydrate content late. Naive LLM parsing of whole pages is slow and expensive. Full-rule scrapers drift and break.
ParserGPT uses two roles:
Learner generates a compact adapter for a domain. The adapter stores URL patterns, selectors, and tests. The learner iterates on representative pages until coverage is high.
Runner executes adapters deterministically. It crawls within scope, normalizes types, and writes rows. It calls an LLM only when a field is empty or malformed. All generations must pass schema validation before merging.
This split balances speed and resilience. Deterministic selectors are fast and repeatable. LLM usage becomes targeted and bounded.
Step-by-Step Walkthrough
Define the target schema with field names and dtypes. Keep dtypes simple:
string,number,date,string[].Sample representative pages with HTTP fetch. Escalate to a headless browser only when the server blocks or content requires script execution.
Run the learner on samples. Produce a minimal adapter containing URL patterns, CSS/XPath/regex selectors, and a small test suite.
Validate the adapter against samples. Repair selectors until coverage meets a threshold.
Launch the runner. Constrain crawl by domain, depth, and allowed paths. Store raw HTML, normalized rows, and crawl metadata.
Apply LLM fallback only to missing or invalid fields. Use a strict JSON schema so merges never corrupt good values.
Export a typed CSV. Keep per-domain adapters versioned and reproducible.
Code / JSON Snippets
Minimal code. Replace placeholders before use.
FastAPI surface: job creation and CSV download
# app/main.py
import os, asyncio, csv, json
from fastapi import FastAPI, HTTPException
from fastapi.responses import FileResponse
from pydantic import BaseModel
from typing import List, Literal

app = FastAPI()

class Field(BaseModel):
    name: str
    dtype: Literal["string", "number", "date", "string[]"]

class JobIn(BaseModel):
    start_url: str
    allowed_domains: List[str] = []
    max_depth: int = 1
    max_pages: int = 25
    field_spec: List[Field]

@app.post("/jobs")
async def create_job(job: JobIn):
    job_id = 1  # replace with DB insert and autoincrement id
    asyncio.create_task(run_job(job_id, job))
    return {"job_id": job_id, "status": "started"}

@app.get("/jobs/{job_id}/csv")
def download_csv(job_id: int):
    path = f"job_{job_id}.csv"
    if not os.path.exists(path):
        raise HTTPException(404, "CSV not ready")
    return FileResponse(path, media_type="text/csv", filename=os.path.basename(path))

async def run_job(job_id: int, job: JobIn):
    # 1) sample pages
    samples = await sample_pages(job.start_url, job.allowed_domains, max_pages=min(5, job.max_pages))
    # 2) learn adapter
    adapter = await learn_adapter(job.field_spec, samples)
    # 3) crawl and extract
    rows = await crawl_and_extract(job, adapter)
    # 4) write CSV
    write_csv(f"job_{job_id}.csv", [f.model_dump() if hasattr(f, "model_dump") else f for f in job.field_spec], rows)

def write_csv(path: str, field_spec, rows: List[dict]):
    names = [f["name"] for f in field_spec]
    with open(path, "w", newline="", encoding="utf-8") as f:
        w = csv.DictWriter(f, fieldnames=names)
        w.writeheader()
        for r in rows:
            w.writerow({k: (", ".join(v) if isinstance(v, list) else v) for k, v in r.items() if k in names})
HTTP first, browser if blocked
# sampling.py
import httpx, asyncio, urllib.parse
from typing import List, Tuple, Set
from playwright.async_api import async_playwright

async def fetch_http(url: str) -> str:
    async with httpx.AsyncClient(follow_redirects=True, timeout=30.0, http2=True) as c:
        r = await c.get(url, headers={"User-Agent": "Mozilla/5.0"})
        if r.status_code == 200 and "text/html" in r.headers.get("content-type", ""):
            return r.text
    return ""

async def fetch_browser(url: str) -> str:
    async with async_playwright() as p:
        ctx = await p.chromium.launch_persistent_context(
            user_data_dir="./pw-profile",
            headless=True,
            args=["--disable-blink-features=AutomationControlled"]
        )
        page = await ctx.new_page()
        await page.add_init_script("Object.defineProperty(navigator,'webdriver',{get:()=>undefined});")
        await page.goto(url, wait_until="load", timeout=60000)
        await page.wait_for_timeout(1200)
        html = await page.content()
        await ctx.close()
        return html

def same_domain(url: str, allowed_domains: List[str]) -> bool:
    host = urllib.parse.urlparse(url).netloc
    return any(host.endswith(d) for d in allowed_domains) if allowed_domains else True

async def sample_pages(start_url: str, allowed_domains: List[str], max_pages: int = 5) -> List[Tuple[str, str]]:
    seen: Set[str] = set()
    out: List[Tuple[str, str]] = []
    queue = [start_url]
    while queue and len(out) < max_pages:
        url = queue.pop(0)
        if url in seen or not same_domain(url, allowed_domains):
            continue
        seen.add(url)
        html = await fetch_http(url)
        if not html:
            html = await fetch_browser(url)
        if html:
            out.append((url, html))
        # intentionally skip link expansion to stay minimal
    return out
Learner: propose a compact adapter under strict JSON
# learner.py
from typing import Dict, List, Tuple
from pydantic import BaseModel, Field
from langchain.output_parsers import PydanticOutputParser
from langchain_core.prompts import ChatPromptTemplate
from langchain_openai import ChatOpenAI

class Adapter(BaseModel):
    url_patterns: Dict[str, List[str]] = Field(default_factory=dict)
    selectors: Dict[str, Dict[str, str]] = Field(default_factory=dict)
    tests: List[Dict[str, Dict[str, str]]] = Field(default_factory=list)

parser = PydanticOutputParser(pydantic_object=Adapter)
PROMPT = ChatPromptTemplate.from_messages([
    ("system", "Infer minimal, robust CSS/XPath/regex selectors for the fields. Return ONLY valid JSON."),
    ("human", "FIELDS: {fields}\nEXAMPLES:\n{examples}\n{format_instructions}")
])
llm = ChatOpenAI(model="gpt-4o-mini", temperature=0)

async def learn_adapter(field_spec: List[Dict], samples: List[Tuple[str, str]]) -> Dict:
    examples = "\n\n".join(f"URL: {u}\nHTML:\n{h[:6000]}" for u, h in samples)
    msg = {
        "fields": ", ".join(f"{f['name']}:{f['dtype']}" for f in field_spec),
        "examples": examples,
        "format_instructions": parser.get_format_instructions()
    }
    draft = await (PROMPT | llm | parser).ainvoke(msg)
    return draft.model_dump()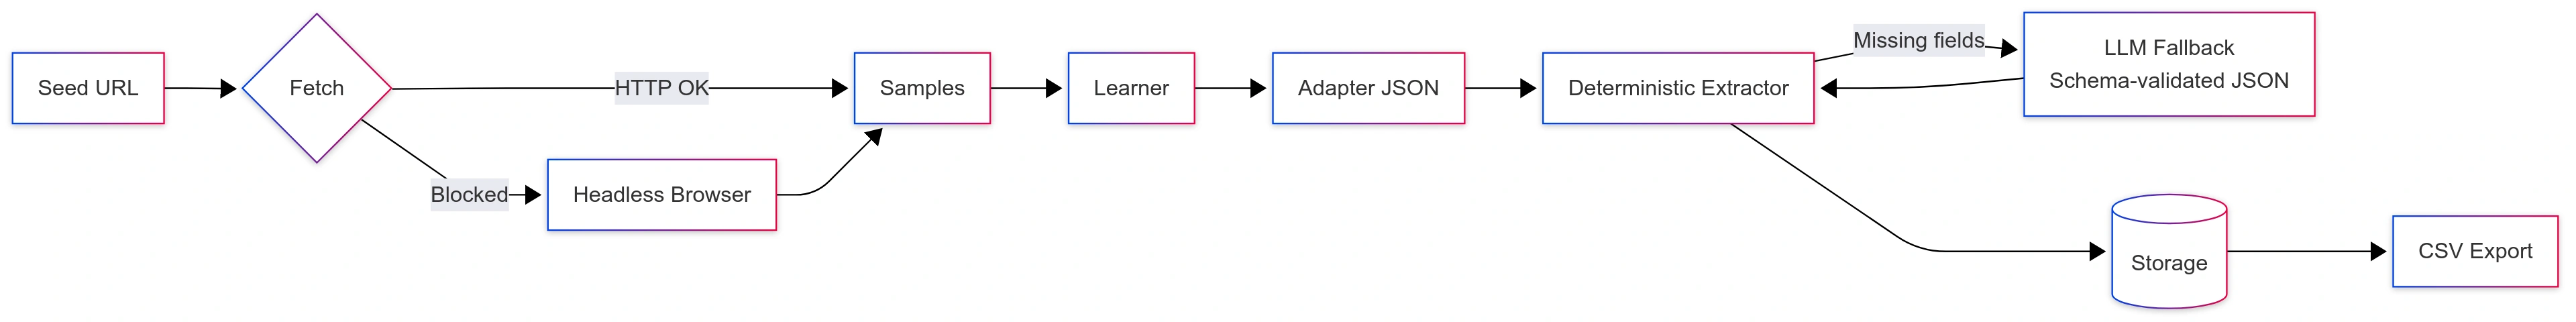
Join the conversation! Your thoughts help the community grow.