
Abstract / Overview
Qwen3-Omni is Alibaba Cloud’s flagship omni-modal AI foundation model, created by the Qwen team. Unlike text-only large language models (LLMs), Qwen3-Omni natively processes text, image, audio, and video inputs, and generates streaming outputs in both text and natural speech.
It delivers SOTA performance in 22 of 36 multimodal benchmarks and performs on par with top commercial systems such as Google Gemini 2.5 Pro in ASR and conversational audio tasks. This makes Qwen3-Omni a leading real-time multimodal model suitable for global-scale applications.
Conceptual Background
LLMs historically focused on text. Extensions into vision or audio were often modular, creating imbalances across modalities. Qwen3-Omni overcomes this by:
Unified multimodal pretraining (not just adapters).
Streaming architecture for both text and natural speech.
Balanced optimization across text, vision, and audio.
Multilingual support for cross-border communication and translation.
This shift represents the industry’s movement toward true omni-modal AI where models act as interactive, real-time assistants instead of static query engines.
Step-by-Step Walkthrough
Model Architecture
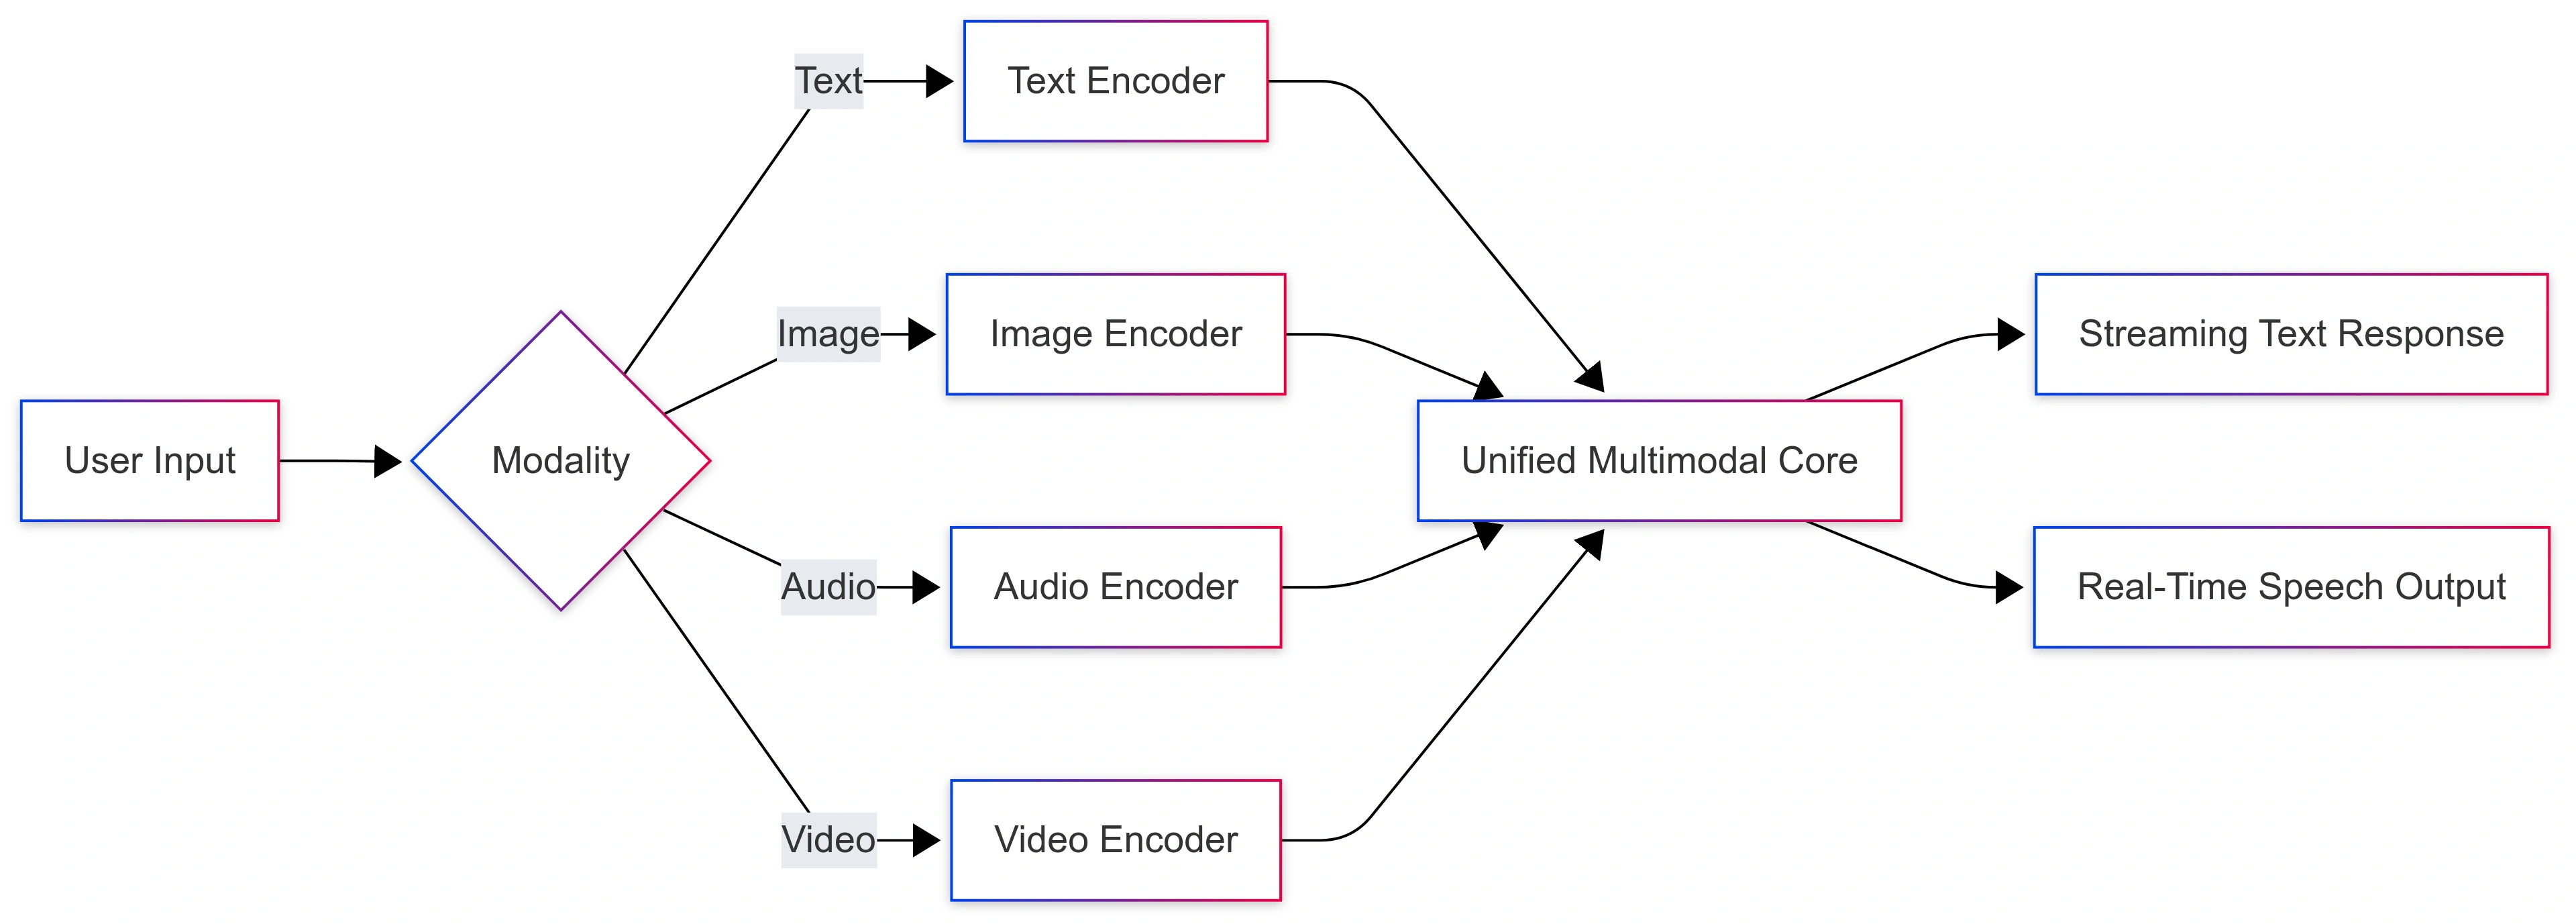
Unified multimodal encoders for text, images, audio, and video.
Streaming inference producing token-by-token text and real-time voice.
Efficient optimization reducing latency and compute load.
Multilingual training corpus for global-scale deployment.
Performance Benchmarks
Audio/Video: SOTA in 22/36 public tasks.
Speech Recognition: Matches Gemini 2.5 Pro.
Conversational Speech: Exceeds prior open-source multimodal baselines.
Image + Text tasks: Matches leading vision-language models.
Deployment Options
Transformers (Hugging Face) for research and fine-tuning.
vLLM integration for enterprise-scale inference.
DashScope API for real-time cloud deployment.
Dockerized demos for easy local setup.
Mermaid Diagram: Qwen3-Omni Workflow
Use Cases / Scenarios
Conversational AI Assistants – Real-time, multilingual, voice-enabled dialogue.
Accessibility Tools – Speech-to-speech translation and transcription.
Education – Interactive tutoring with text, visuals, and audio responses.
Media Applications – Captioning, dubbing, and video-based Q&A.
Enterprise Monitoring – Audio and video compliance checks with summarization.
Limitations / Considerations
Compute-heavy training demands large GPU clusters.
Latency in speech streaming compared to text-only models.
Bias risks from multimodal datasets.
Ecosystem competition with GPT-4o and Gemini.
Feature Comparison: Qwen Model Family
| Model | Primary Focus | Modalities Supported | Key Features | Typical Use Cases |
|---|---|---|---|---|
| Qwen1.5 | Early LLM | Text | Multilingual reasoning, basic tasks | Chatbots, text analysis |
| Qwen2 | Advanced LLM | Text | Stronger logic and reasoning | Knowledge bases, enterprise AI |
| Qwen-VL | Vision-Language | Text + Images | Image captioning, visual Q&A | Media, accessibility |
| Qwen-Audio | Speech/Audio | Text + Audio | Speech recognition, audio understanding | Voice assistants, transcription |
| Qwen-Agent | Agentic AI | Multi-step reasoning | Task automation, planning, tool use | Workflows, digital assistants |
| Qwen3-Omni | Omni-Modal AI | Text + Image + Audio + Video | Real-time multimodal conversation with speech streaming | AI assistants, accessibility, media |
FAQs
Q1. How does Qwen3-Omni compare to GPT-4o and Gemini?
It is multimodal by design, unlike modular competitors, ensuring consistent performance across all modalities.
Q2. Can it generate speech in real time?
Yes, Qwen3-Omni delivers low-latency, natural speech streaming.
Q3. Is it open-source?
Yes, released under the Apache 2.0 license on GitHub.
Q4. How can I deploy it?
Options include Hugging Face, vLLM, DashScope API, and Docker demos.
Q5. Does it support multilingual AI?
Yes. It supports cross-lingual interaction and translation.
Conclusion
Qwen3-Omni is Alibaba Cloud’s most ambitious step toward true omni-modal AI. It unifies text, vision, audio, and video processing within a single system capable of streaming real-time text and natural speech. Its open-source release and enterprise deployment options make it an attractive choice for developers and organizations seeking scalable multimodal intelligence.
By extending beyond text into speech and video understanding, Qwen3-Omni sets a new benchmark for the future of foundation models.
Join the conversation! Your thoughts help the community grow.