
Introduction
In This tutorial we are going to learn about how to work with PDF Files in .NET Core. I believe this is a very important topic. When working with PDF files there are a lot of libraries available out there in the market and nuget repository. I will use the open source library. The tutorial is divided into 3 Cases and 1 Scenario. First, let us understand about iText7.
iText7
iText7, formerly known as iTextSharp, is the enterprise grade PDF library that takes care of all the PDF standards and related technologies. It solves all the problems related to PDF and lets the developers focus purely on business logic. It offers an abstract document model. It gives us the ability to structure, read, delete, insert PDF documents. It meets all the global PDF standards. It comes with comprehensive documentation. It offers high performance. It is extensible. We can do add-ons in it using iText7 Suite. It is available in Java and .NET. It is supported by the community. The iText7 source code is also open source and available on Github.
Free Licenses
We can use it for free iText7 Community under Open Source AGPL license. The license has some restrictions. For commercial purposes please read its official documentation for licenses.
What will be covered in the tutorial?
In this tutorial i will create 3 functions where we will perform read operation using itext7, compare two files' content using diff_match_patch offered by Google as a free source on github, and creating a pdf file using itext7 that will store the result. So, overall we are going to perform comparison of 2 pdf files by taking one real life scenario. So, let’s start!!
Case 1
Reading A Pdf File To Text, using iText7
- /*
- ..
- using iText.Kernel.Pdf;
- using iText.Kernel.Pdf.Canvas.Parser;
- using iText.Kernel.Pdf.Canvas.Parser.Listener;
- */
- public string ReadFile(string pdfPath) {
- var pageText = new StringBuilder();
- using(PdfDocument pdfDocument = new PdfDocument(new PdfReader(pdfPath))) {
- var pageNumbers = pdfDocument.GetNumberOfPages();
- for (int i = 1; i <= pageNumbers; i++) {
- LocationTextExtractionStrategy strategy = new LocationTextExtractionStrategy();
- PdfCanvasProcessor parser = new PdfCanvasProcessor(strategy);
- parser.ProcessPageContent(pdfDocument.GetFirstPage());
- pageText.Append(strategy.GetResultantText());
- }
- }
- return pageText.ToString();
- }
Case 2
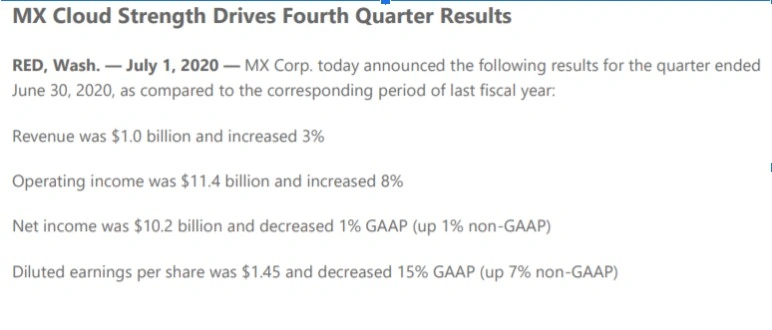
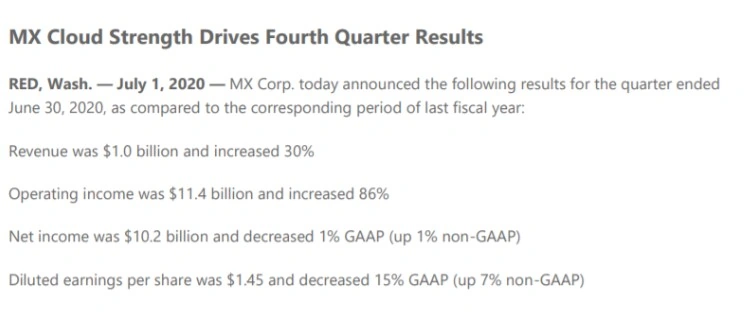
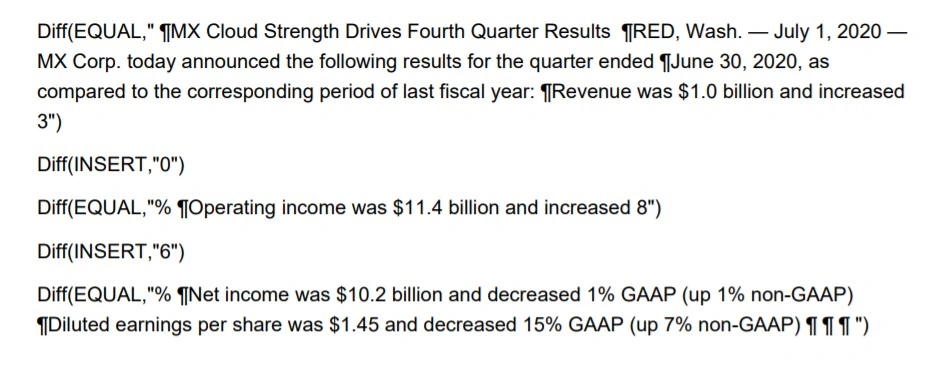
Reading and Comparing Two Pdf Files, using Above Function and Google diff_match_patch which is now open source and available at here. We will simply download that file and write the code below.
This diff match patch is a powerful library to compare/manipulate the plain texts.
Japanese DudePosted Jun 29, 2021, 9:02 AM
Hi thanks for the tutorial! what would you recommend i look into to format the text in the comparison result file?