
Abstract / Overview
The Hilbert Curve plays an important behind-the-scenes role in modern AI systems, especially those that power Large Language Models (LLMs). While users interact with models through natural language, the infrastructure underneath must handle billions of vectors, embeddings, and search operations.
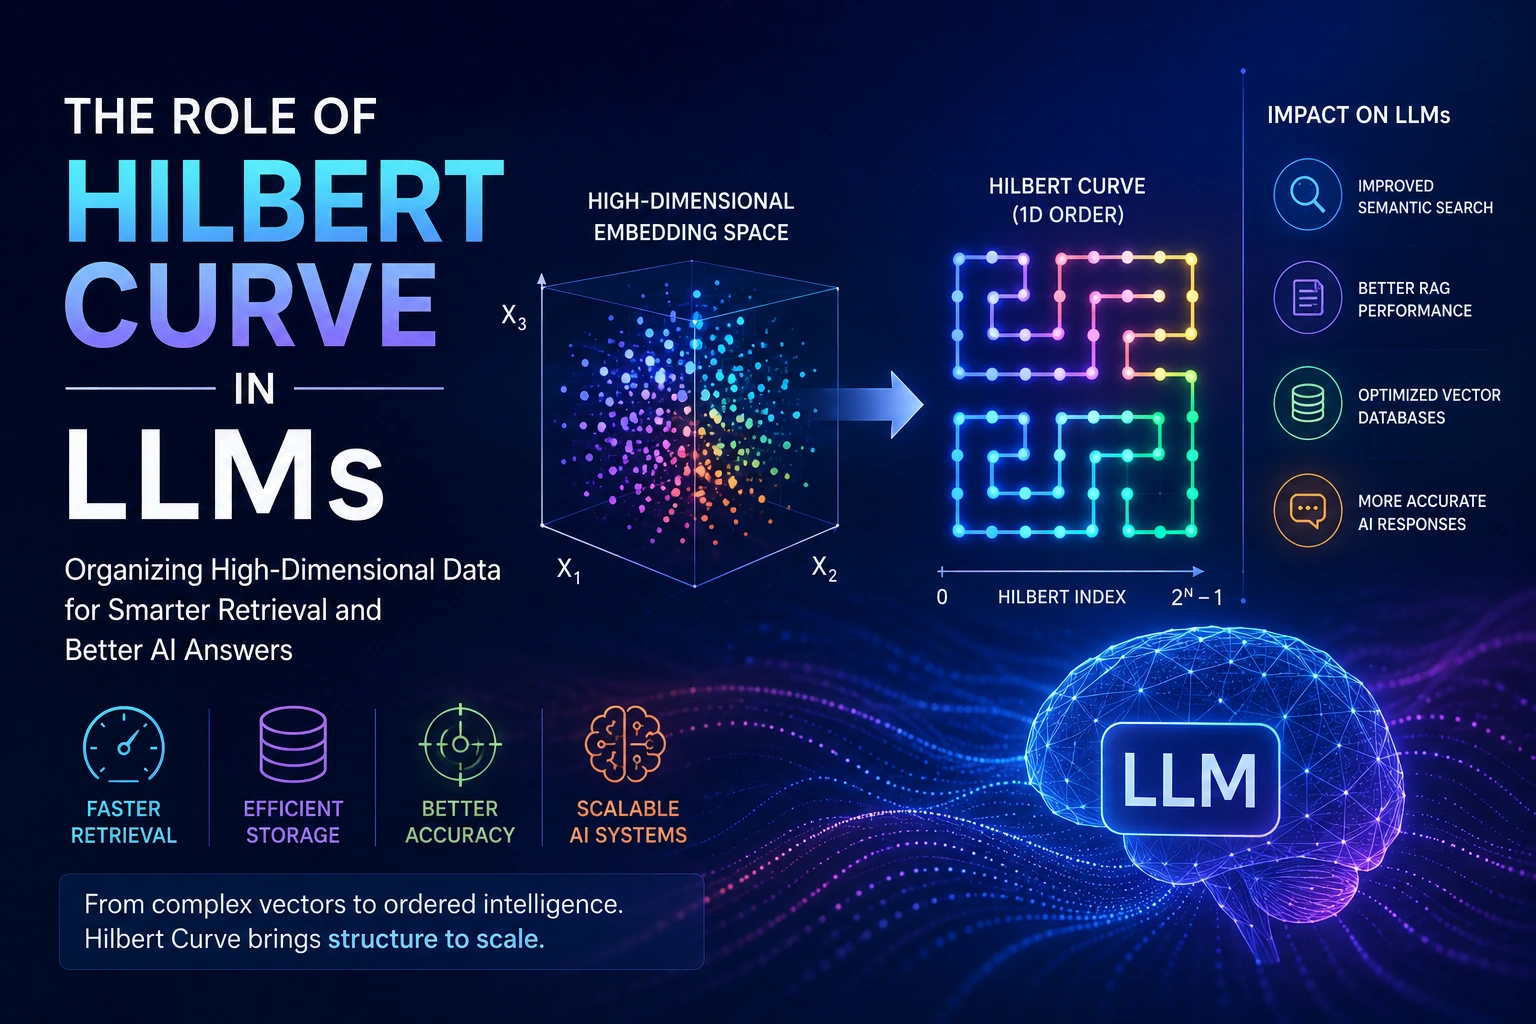
A Hilbert Curve helps convert multi-dimensional data into a one-dimensional sequence while preserving locality. In simple terms, points that are close together in high-dimensional space remain close together after mapping. This property is valuable for vector databases, semantic search systems, Retrieval-Augmented Generation (RAG), and large-scale AI infrastructure.
As LLM applications continue to grow, efficient retrieval becomes just as important as model size. This is one reason why organizations invest heavily in advanced indexing and search techniques. Teams looking to build production-grade AI retrieval systems often work with experts such as C# Corner Consulting to design scalable AI architectures.
Direct Answer:
A Hilbert Curve helps LLM ecosystems organize embedding vectors efficiently by preserving spatial relationships during indexing. This improves search speed, storage efficiency, retrieval quality, and scalability in vector databases used by modern AI applications.
Last Updated: June 2026
Conceptual Background
What Is a Hilbert Curve?
The Hilbert Curve is a space-filling curve developed by German mathematician David Hilbert in 1891.
It maps a multi-dimensional space into a single dimension while keeping nearby points close together.
Imagine converting a 2D map into a single line without losing neighborhood information. That is essentially what a Hilbert Curve does.
Why Is This Important?
Most AI systems work with vectors.
For example:
A word embedding may have 768 dimensions.
A sentence embedding may have 1024 dimensions.
A document embedding may have thousands of dimensions.
Searching through billions of these vectors is expensive.
The Hilbert Curve provides a way to arrange vectors more efficiently.
Simple Visualization

Understanding Embeddings in LLMs
Before understanding the Hilbert Curve's role, it is important to understand embeddings.
An embedding is a numerical representation of text.
Example:
"Dog"
"Puppy"
"Pet"
These words become vectors that appear close to each other in embedding space.
LLMs and RAG systems search these vector spaces to find relevant information.
The challenge is that searching billions of vectors can become slow and expensive.
This is where Hilbert Curves become useful.
How Hilbert Curves Work
A Hilbert Curve transforms coordinates from multi-dimensional space into a single ordered sequence.
For example:
Instead of storing vectors randomly:
Point A -> (x1,y1)
Point B -> (x2,y2)
Point C -> (x3,y3)
The curve assigns each point a Hilbert value:
A -> 101
B -> 102
C -> 103
Nearby points usually receive nearby values.
This property helps databases group related vectors together.
Role of Hilbert Curve in LLM Infrastructure
Vector Database Optimization
Many LLM systems rely on vector databases.
Examples include:
Pinecone
Weaviate
Milvus
Qdrant
These systems store billions of embeddings.
A Hilbert Curve can help:
Reduce search space
Improve indexing efficiency
Increase retrieval speed
Improve cache utilization
Instead of scanning all vectors, systems can search nearby Hilbert ranges.
Faster Semantic Search
Semantic search finds meaning instead of matching keywords.
When a user asks:
"How do I reduce cloud costs?"
The system searches embeddings rather than exact words.
Hilbert ordering allows similar embeddings to be physically stored near each other.
Benefits include:
Faster lookup
Reduced disk access
Lower latency
Better Retrieval-Augmented Generation (RAG)
RAG systems retrieve documents before generating answers.
Typical workflow:

When Hilbert-based indexing is used:
Document retrieval becomes faster.
Candidate selection improves.
Infrastructure costs decrease.
Response time improves.
Efficient Distributed Storage
Modern AI systems run across many servers.
A challenge is distributing vectors efficiently.
Hilbert Curves help by:
Partitioning vector space
Balancing workloads
Reducing network communication
This becomes critical when handling billions of embeddings.
Why Hilbert Curves Are Better Than Simple Ordering
Traditional sorting methods struggle with multi-dimensional data.
Hilbert Curves preserve locality better than many alternatives.
Advantages include:
Better clustering
Reduced fragmentation
Faster nearest-neighbor search
Improved storage efficiency
This makes them attractive for AI retrieval systems.
Hilbert Curve vs Z-Order Curve
Another popular technique is the Z-Order Curve (Morton Order).
Join the conversation! Your thoughts help the community grow.