

Why Evaluation Must Be Stateful
Most RAG systems treat evaluation as an afterthought—a single pass that returns a score and hopes for the best. In enterprise compliance research, this is unacceptable. A regulatory answer citing outdated guidance or missing a jurisdictional nuance isn’t just wrong; it’s a liability. The system must evaluate its own output, identify specific deficiencies, retrieve targeted corrections, and re-evaluate until quality thresholds are met or safely degraded. This is a stateful evaluation loop: not a simple retry, but a cycle where each iteration accumulates evidence about what went wrong and uses that accumulated state to guide the next correction attempt. The state distinguishes a self-correcting system from one that blindly repeats the same mistakes. This article implements a complete stateful evaluation loop in an enterprise Compliance Research Assistant using LangGraph, with persistent memory, typed state, and production-grade termination guarantees.
The Real-Time Use Case: Multi-Jurisdictional Regulatory Research
An analyst asks:
"Compare customer due diligence requirements for money service businesses under EU AMLR 2024 and FinCEN’s CDD Rule, focusing on beneficial ownership thresholds."
A naive RAG retrieval returns plausible-sounding but incomplete content: it covers EU thresholds correctly but cites FinCEN’s 2016 rule instead of the 2024 update, and omits the MSB-specific exemption clause. A single-pass evaluator might give this 0.7 confidence—passable but dangerous.
A stateful evaluation loop must:
Detect the outdated FinCEN citation
Retrieve the 2024 update specifically
Re-evaluate whether the correction resolved the gap
Detect the missing MSB exemption
Retrieve that specific clause
Re-evaluate again
Converge when all gaps are closed—or degrade honestly when they can’t be
Each iteration’s state informs the next. This is fundamentally different from “retry up to N times.”
Architecture: The Evaluation Loop as First-Class Graph Structure
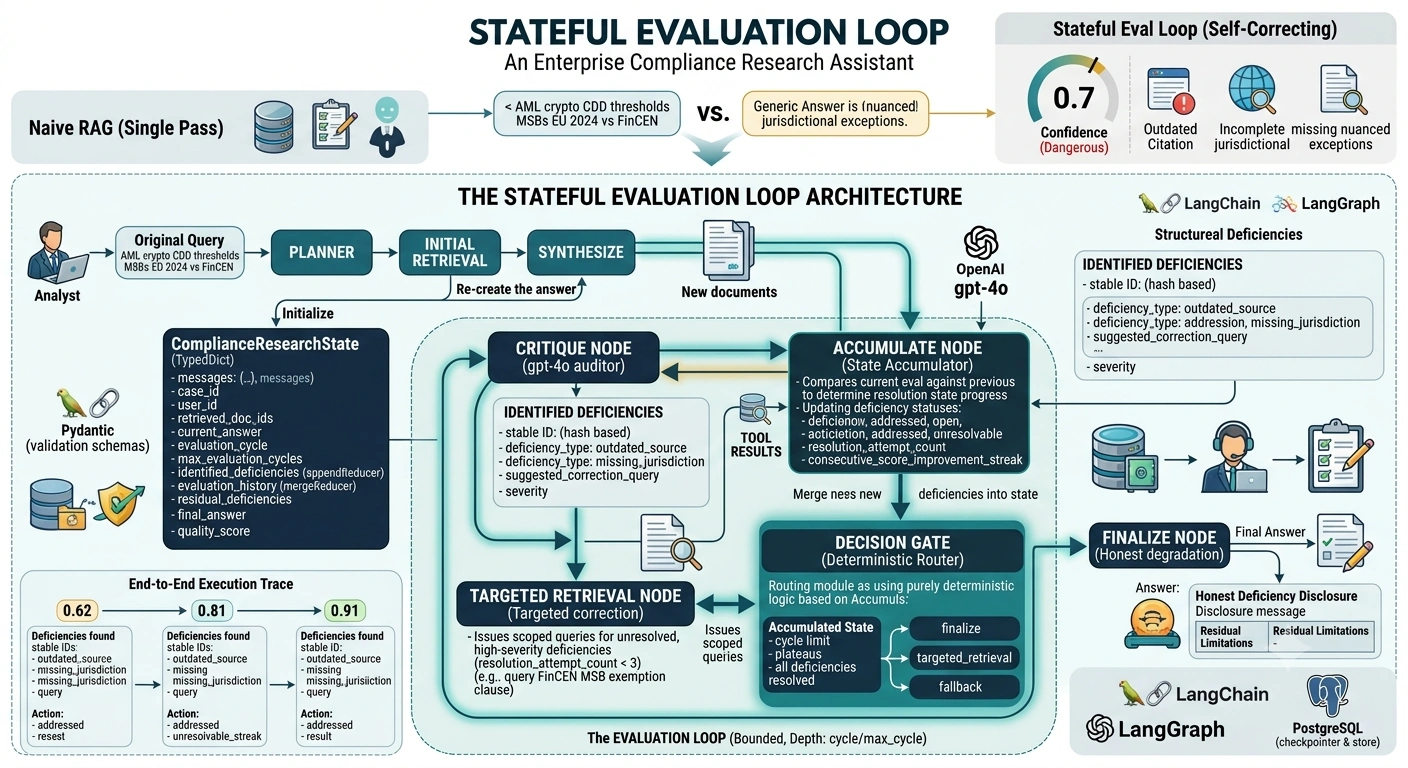
The evaluation loop is not a wrapper around the graph. It is the graph’s central structure. Every node inside it reads and writes evaluation state.
Step 1: Typed State with Evaluation-Specific Fields
State must capture not just what was retrieved, but what was evaluated, what failed, and what was attempted to fix it. Without this, the loop repeats the same corrections endlessly.
from typing import Annotated, TypedDict, Literal, Optional
from langgraph.graph.message import add_messages
from langchain_core.messages import BaseMessage
from pydantic import BaseModel, Field
from enum import Enum
import time


class DeficiencyType(str, Enum):
    OUTDATED_SOURCE = "outdated_source"
    MISSING_JURISDICTION = "missing_jurisdiction"
    INCORRECT_THRESHOLD = "incorrect_threshold"
    MISSING_EXEMPTION = "missing_exemption"
    CONTRADICTORY_SOURCES = "contradictory_sources"
    INSUFFICIENT_SPECIFICITY = "insufficient_specificity"


class IdentifiedDeficiency(BaseModel):
    """A specific, actionable deficiency found during evaluation."""
    id: str                          # Unique ID for deduplication
    deficiency_type: DeficiencyType
    description: str                 # Human-readable explanation
    affected_section: str            # Which part of the answer has the problem
    suggested_correction_query: str  # Targeted retrieval query to fix this
    severity: float = Field(ge=0.0, le=1.0)
    identified_at_cycle: int         # When this was first found
    resolution_status: Literal["open", "addressed", "unresolvable"] = "open"
    resolution_attempt_count: int = 0


class EvaluationCycleRecord(BaseModel):
    """Immutable record of each evaluation iteration for audit."""
    cycle_number: int
    deficiencies_found: list[str]       # IDs of deficiencies identified this cycle
    deficiencies_resolved: list[str]    # IDs resolved this cycle
    overall_score: float
    retrieval_queries_issued: list[str]
    timestamp: float = Field(default_factory=time.time)


def _append_deficiencies(existing: list[IdentifiedDeficiency], new: list[IdentifiedDeficiency]) -> list[IdentifiedDeficiency]:
    """Merge deficiencies: update existing by ID, append new ones."""
    existing_map = {d.id: d for d in existing}
    for d in new:
        if d.id in existing_map:
            # Update resolution status and attempt count
            existing_map[d.id] = d
        else:
            existing_map[d.id] = d
    return list(existing_map.values())


def _append_cycle_records(existing: list[EvaluationCycleRecord], new: list[EvaluationCycleRecord]) -> list[EvaluationCycleRecord]:
    """Append-only cycle history."""
    return existing + new


class ComplianceResearchState(TypedDict):
    # Core message history
    messages: Annotated[list[BaseMessage], add_messages]

    # Session identity
    session_id: str
    user_id: str
    original_query: str

    # Research artifacts
    retrieved_doc_ids: list[str]
    current_answer: Optional[str]
    citations: list[dict]

    # ═══ EVALUATION LOOP STATE ═══════════════════════════════════
    evaluation_cycle: int                           # Current iteration (0-indexed)
    max_evaluation_cycles: int                      # Hard upper bound
    identified_deficiencies: Annotated[list[IdentifiedDeficiency], _append_deficiencies]
    evaluation_history: Annotated[list[EvaluationCycleRecord], _append_cycle_records]
    consecutive_score_improvement_streak: int        # Soft convergence signal
    last_evaluation_score: float                     # Previous cycle's score
    evaluation_termination_reason: Optional[str]     # Why the loop stopped

    # Output
    final_answer: Optional[str]
    quality_score: Optional[float]
    residual_deficiencies: list[str]  # Unresolved issues disclosed to user
Why Each Evaluation Field Matters
| Field | Purpose | Failure Without It |
|---|---|---|
identified_deficiencies (with merge reducer) | Tracks what’s wrong AND what’s been tried | Loop re-identifies same deficiency every cycle |
resolution_status per deficiency | Distinguishes open/addressed/unresolvable | Can’t tell if a fix worked |
resolution_attempt_count | Counts fix attempts per deficiency | Can’t detect unfixable problems |
evaluation_history | Full audit trail of scoring progression | No way to prove improvement to auditors |
consecutive_score_improvement_streak | Soft convergence when scores plateau | Loops forever on marginal improvements |
last_evaluation_score | Delta calculation for convergence | Can’t measure progress |
evaluation_termination_reason | Explicit reason for stopping | Silent failures; no debugging signal |
Step 2: The Critique Agent — Structured Deficiency Identification
The critique agent doesn’t return a score. It returns structured, actionable deficiencies that drive targeted correction.
CRITIQUE_SYSTEM_PROMPT = """You are a compliance research quality auditor. Given a draft answer
and the original query, identify SPECIFIC deficiencies. Do NOT give general feedback.

For each deficiency, provide:
- deficiency_type: one of [{DEFICIENCY_TYPES}]
- description: precise explanation of what is wrong
- affected_section: quote the problematic text
- suggested_correction_query: exact retrieval query that would find the correct information
- severity: 0.0-1.0 impact on answer correctness

If the answer is fully correct and complete, return an empty deficiencies list.

Respond ONLY in JSON: {deficiencies: [...], overall_score: 0.0-1.0}"""

DEFICIENCY_TYPES = ", ".join(e.value for e in DeficiencyType)


async def critique_node(state: ComplianceResearchState) -> dict:
    """Identify specific deficiencies in the current answer."""
    response = await critique_llm.ainvoke([
        SystemMessage(content=CRITIQUE_SYSTEM_PROMPT.format(DEFICIENCY_TYPES=DEFICIENCY_TYPES)),
        HumanMessage(content=(
            f"ORIGINAL QUERY: {state['original_query']}\n\n"
            f"DRAFT ANSWER:\n{state['current_answer']}\n\n"
            f"CITATIONS: {json.dumps(state['citations'])}\n\n"
            f"PREVIOUSLY IDENTIFIED DEFICIENCIES: "
            f"{json.dumps([d.model_dump() for d in state['identified_deficiencies'] if d.resolution_status == 'open'])}"
        ))
    ])

    result = json.loads(response.content)

    # Convert to typed deficiency objects with stable IDs
    new_deficiencies = []
    for i, raw in enumerate(result.get("deficiencies", [])):
        # Stable ID based on type + affected section hash
        import hashlib
        def_id = hashlib.sha256(
            f"{raw['deficiency_type']}:{raw['affected_section']}".encode()
        ).hexdigest()[:12]

        new_deficiencies.append(IdentifiedDeficiency(
            id=def_id,
            deficiency_type=DeficiencyType(raw["deficiency_type"]),
            description=raw["description"],
            affected_section=raw["affected_section"],
            suggested_correction_query=raw["suggested_correction_query"],
            severity=raw["severity"],
            identified_at_cycle=state["evaluation_cycle"],
            resolution_status="open",
            resolution_attempt_count=0
        ))

    return {
        "identified_deficiencies": new_deficiencies,  # Merged via custom reducer
        "last_evaluation_score": result["overall_score"],
        "messages": [AIMessage(content=(
            f"Evaluation cycle {state['evaluation_cycle']}: "
            f"Score={result['overall_score']:.2f}, "
            f"Deficiencies={len(new_deficiencies)}"
        ))],
    }
Key Design Choice: Stable Deficiency IDs
Deficiency IDs are derived from content hashes, not random UUIDs. This means if the same underlying problem persists across cycles, it maps to the same ID, enabling the merge reducer to update rather than duplicate. Without this, the loop treats recurring problems as new problems and never recognizes unfixable deficiencies.
Join the conversation! Your thoughts help the community grow.