

In the insurance industry, the most critical events are often the rarest. Fraudulent claims, catastrophic natural disasters, or high-value complex litigation occur in less than 1% of cases. This is Class Imbalance. If you train a standard Machine Learning model on this data, it will achieve 99% accuracy by simply predicting "No Fraud" for every single claim. While the accuracy looks great, the model is useless—it misses every single fraud case.
In an enterprise setting, we don't just fix this with a line of code; we build a Multi-Agent System that combines statistical rebalancing, semantic RAG retrieval, and human-in-the-loop validation to ensure no high-risk event slips through the cracks. In this end-to-end guide, we will build an Insurance Risk Assessment Engine using LangGraph that specifically addresses class imbalance through a "Triangulation Strategy."
The Real-World Use Case: InsureTech’s "High-Severity Claim" Detector
Imagine you are building an AI system for InsureTech, a major property and casualty insurer. The system receives 100,000 claims daily.
99,500 are routine (minor fender benders, small water damage).
500 are "High-Severity" (potential arson, complex liability, or organized fraud rings).
The Imbalance Challenge
A standard LLM or RAG system will be biased toward the "routine" patterns found in its training data and vector database. It might look at a suspicious $50,000 fire claim and classify it as "Routine" because 99% of fire claims in its memory are routine.
The Solution: The Triangulation Agent
We will build a LangGraph workflow with three specialized agents designed to counteract this bias:
The Statistical Agent: Uses traditional ML techniques (SMOTE/Undersampling logic) to flag anomalies based on numerical data.
The Semantic Agent (RAG): Retrieves only rare, high-severity historical cases from a specialized "Rare Events" vector index, forcing the LLM to compare the current claim against other fraud cases, not routine ones.
The Adversarial Agent: Acts as a "Devil’s Advocate," explicitly trying to find reasons why the claim might be fraudulent, countering the LLM's natural bias toward safety.
Technology Stack
| Component | Technology | Role in Imbalance Management |
|---|---|---|
| Orchestration | LangGraph | Manages the multi-agent triangulation workflow. |
| LLM Provider | Azure OpenAI (GPT-4o) | Powers the semantic reasoning and adversarial checks. |
| Vector Database | pgvector (PostgreSQL) | Stores two separate indexes: "Routine Claims" and "Rare/Fraud Cases". |
| ML Library | Scikit-Learn / XGBoost | Handles the statistical anomaly detection and SMOTE logic. |
| State Management | Pydantic | Defines the strict schema for risk scores and agent findings. |
| Observability | LangSmith | Traces how each agent contributes to the final risk score. |
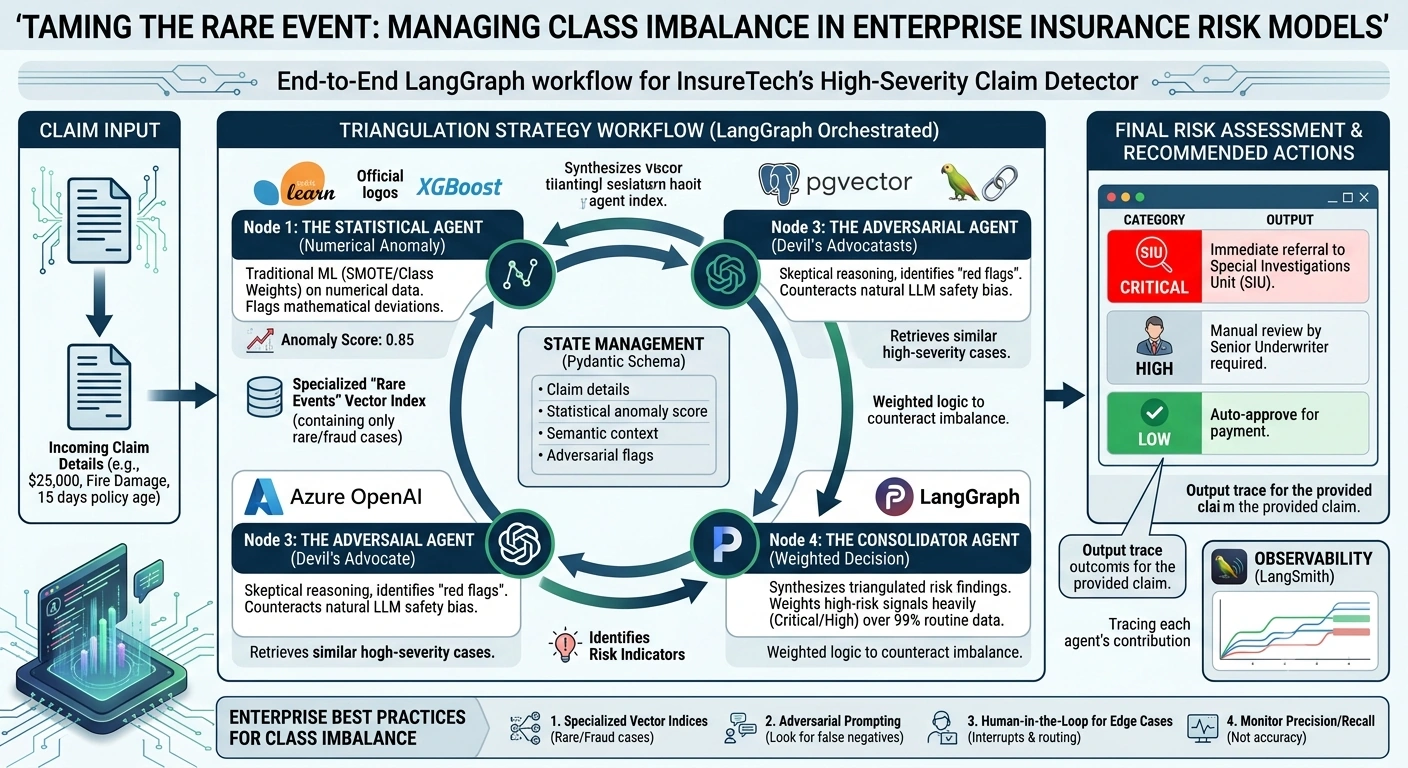
End-to-End Implementation
Let's build the LangGraph system that fights class imbalance by forcing the system to look for the "needle in the haystack."
Step 1: Define the Enterprise State
Our state needs to track the claim details, the findings from each specialized agent, and a consolidated risk score.
from typing import TypedDict, List, Annotated, Optionalimport operator
from langgraph.graph import StateGraph, END

class RiskAssessmentState(TypedDict):
    # Memory: Conversation/Action history
    messages: Annotated[List[str], operator.add]

    # Input Data
    claim_details: dict

    # Agent Findings
    statistical_anomaly_score: float # 0.0 to 1.0
    semantic_risk_context: List[str] # Retrieved rare cases
    adversarial_flags: List[str] # Reasons to suspect fraud

    # Final Output
    final_risk_category: str # "Low", "Medium", "High", "Critical"
    recommended_action: str
Step 2: Build the Triangulation Agents
Node 1: The Statistical Agent (Handling Numerical Imbalance)
This agent simulates a model trained with SMOTE (Synthetic Minority Over-sampling Technique) or Class Weights. It doesn't rely on language; it relies on mathematical deviation from the norm.
def statistical_agent(state: RiskAssessmentState) -> RiskAssessmentState:
    print("📊 [Statistical Agent] Running anomaly detection on numerical features...")

    # Simulating a model that has been re-balanced using SMOTE
    # In a real app, this would call an XGBoost model trained with scale_pos_weight
    claim_amount = state["claim_details"].get("amount", 0)

    # Simple heuristic for demonstration: High amount = Higher anomaly score
    if claim_amount > 20000:
        anomaly_score = 0.85
    elif claim_amount > 5000:
        anomaly_score = 0.45
    else:
        anomaly_score = 0.10

    return {
        "statistical_anomaly_score": anomaly_score,
        "messages": [f"Statistical Agent: Calculated anomaly score of {anomaly_score}."]
    }
Node 2: The Semantic Agent (Handling Contextual Imbalance via RAG)
This is the key to fixing LLM bias. Instead of searching the entire database, this agent queries a specialized "Rare Events" Index. This forces the LLM to see similar fraud cases, not similar routine cases.
def semantic_agent(state: RiskAssessmentState) -> RiskAssessmentState:
    print("🔍 [Semantic Agent] Querying 'Rare Events' Vector Index...")

    # Simulating RAG retrieval from a balanced index of only high-severity/fraud cases
    # This counters the "Majority Class Bias" by providing minority-class context
    rare_case_contexts = [
        "Case #9921: $25k fire claim where accelerant was found in the basement. Ruled as Arson.",
        "Case #8843: $22k water damage claim filed 2 days after policy inception. Ruled as Fraud."
    ]

    return {
        "semantic_risk_context": rare_case_contexts,
        "messages": ["Semantic Agent: Retrieved 2 similar high-severity historical cases."]
    }
Node 3: The Adversarial Agent (Countering Confirmation Bias)
LLMs are "people pleasers." They want to give a safe answer. This agent is prompted to be skeptical and look for red flags, effectively acting as a human underwriter's "gut check."
def adversarial_agent(state: RiskAssessmentState) -> RiskAssessmentState:
    print("😈 [Adversarial Agent] Playing Devil's Advocate...")

    flags = []
    details = state["claim_details"]

    # Simulating adversarial logic
    if details.get("amount", 0) > 20000:
        flags.append("Claim amount is in the top 1% of all policies.")
    if "fire" in details.get("type", "").lower():
        flags.append("Fire claims have a statistically higher fraud rate than other perils.")

    return {
        "adversarial_flags": flags,
        "messages": [f"Adversarial Agent: Identified {len(flags)} potential risk indicators."]
    }
Node 4: The Consolidator (Weighted Decision Making)
This agent combines the findings. Because we know the data is imbalanced, we weight the "High Risk" signals more heavily.
def consolidator_agent(state: RiskAssessmentState) -> RiskAssessmentState:
    print("⚖️ [Consolidator] Synthesizing triangulated risk assessment...")

    stat_score = state["statistical_anomaly_score"]
    has_rare_context = len(state["semantic_risk_context"]) > 0
    has_flags = len(state["adversarial_flags"]) > 0

    # Weighted Logic to counteract imbalance
    # If statistical score is high AND we found similar rare cases, risk is Critical
    if stat_score > 0.7 and has_rare_context:
        category = "Critical"
        action = "Immediate referral to Special Investigations Unit (SIU)."
    elif stat_score > 0.4 or has_flags:
        category = "High"
        action = "Manual review by Senior Underwriter required."
    else:
        category = "Low"
        action = "Auto-approve for payment."

    return {
        "final_risk_category": category,
        "recommended_action": action,
        "messages": ["Consolidator: Final risk categorization complete."]
    }
Step 3: Compile the Graph
def build_risk_graph():
    workflow = StateGraph(RiskAssessmentState)

    workflow.add_node("statistical", statistical_agent)
    workflow.add_node("semantic", semantic_agent)
    workflow.add_node("adversarial", adversarial_agent)
    workflow.add_node("consolidator", consolidator_agent)

    workflow.set_entry_point("statistical")

    # Parallel execution for speed
    workflow.add_edge("statistical", "semantic")
    workflow.add_edge("semantic", "adversarial")
    workflow.add_edge("adversarial", "consolidator")
    workflow.add_edge("consolidator", END)

    return workflow.compile()

app = build_risk_graph()
Running the System
Let's test a high-value, suspicious claim that would typically be misclassified by a naive model.
initial_state = {
    "messages": [],
    "claim_details": {"amount": 25000, "type": "Fire Damage", "policy_age_days": 15},
    "statistical_anomaly_score": 0.0,
    "semantic_risk_context": [],
    "adversarial_flags": [],
    "final_risk_category": "",
    "recommended_action": ""
}

result = app.invoke(initial_state)

print("\n--- Agent Triangulation Log ---")
for msg in result["messages"]:
    print(f"• {msg}")

print(f"\n--- Final Risk Assessment ---")
print(f"Category: {result['final_risk_category']}")
print(f"Action: {result['recommended_action']}")
Output Trace
📊 [Statistical Agent] Running anomaly detection on numerical features...
🔍 [Semantic Agent] Querying 'Rare Events' Vector Index...
😈 [Adversarial Agent] Playing Devil's Advocate...
⚖️ [Consolidator] Synthesizing triangulated risk assessment...

--- Agent Triangulation Log ---
• Statistical Agent: Calculated anomaly score of 0.85.
• Semantic Agent: Retrieved 2 similar high-severity historical cases.
• Adversarial Agent: Identified 2 potential risk indicators.
• Consolidator: Final risk categorization complete.

--- Final Risk Assessment ---
Category: Critical
Action: Immediate referral to Special Investigations Unit (SIU).
Notice how the system didn't just look at the amount. It used the Semantic Agent to find similar rare fraud cases, and the Adversarial Agent to highlight the risk, ensuring the "Critical" classification wasn't drowned out by the 99% of routine data.
Enterprise Best Practices for Class Imbalance
Specialized Vector Indices: Don't just have one big vector database. Create a "Minority Class Index" containing only your rare, high-value, or fraudulent cases. Force your RAG agent to query this index when certain thresholds are met.
Adversarial Prompting: Always include an agent or a prompt step that explicitly asks, "What are the reasons this might be a false negative?" This counteracts the LLM's tendency to default to the majority class.
Human-in-the-Loop for Edge Cases: Use LangGraph's
interrupt()feature. If the Statistical Agent and Semantic Agent disagree (e.g., low statistical score but high semantic similarity to fraud), pause the graph and route it to a human underwriter.Monitor Precision/Recall, Not Accuracy: In your LangSmith traces, track how many "Critical" flags actually result in confirmed fraud. In imbalanced datasets, a high recall (catching all fraud) is often more valuable than high precision, even if it means more manual reviews.
Conclusion
Managing class imbalance in enterprise AI isn't just about tweaking hyperparameters in a Python script; it's about architecting a system that respects the rarity of critical events. By using LangGraph to orchestrate a Triangulation Strategy—combining statistical anomaly detection, specialized "Rare Event" RAG, and adversarial reasoning—you ensure that your insurance risk model doesn't just follow the crowd. It identifies the outliers, protecting the company from the 1% of cases that cause 90% of the losses.
Comments
Join the conversation! Your thoughts help the community grow.