
If you build .NET applications that process scanned documents, invoices, IDs, forms, or screenshots, you have probably hit the moment where PdfReader.GetText() returns nothing because the page is an image file. Optical Character Recognition (OCR) is how you turn those pixels into searchable PDF files and searchable text that provides structured data. The C# OCR library ecosystem has a generous set of options in 2026, but the field is noisier than it was five years ago. Commercial .NET SDK options, cloud APIs, ML-based open-source projects, and Tesseract OCR wrappers all claim to be the best OCR library for your specific OCR solution.
This article compares ten OCR libraries that .NET developers actually shortlist. We ran each one against the same categories of real-world inputs our team handles in production: scanned PDFs, phone photos of paperwork, multi-language receipts, and form documents. I will tell you where each library earns its place, where it does not, and which two I would pick over IronOCR for specific jobs.
Why C# OCR Library Selection Matters
OCR is not a monolithic feature. Developers reach for .NET OCR SDK's or OCR libraries to do three categorically different things: extract plain text from images and scanned PDFs for search indexing, scan and convert existing PDF documents into searchable archival files, utilizing text recognition capabilities to pull structured data out of structured forms, invoices, and receipts. A library that is excellent at one of these can be mediocre at the other two, which is why "the best C# OCR library" is always conditional on the job.
Deployment is the other axis. Cloud OCR options are often the accuracy leaders on casual inputs, but they ship your PDF documents off-premise, which is a non-starter for government agencies, healthcare, and finance work. On-premise .NET libraries like IronOCR, ABBYY FineReader Engine, LEADTOOLS, and Tesseract OCR keep the data inside your process but ask you to think about OCR process preprocessing, language packs, and .NET environments. In our testing, the right choice depended less on raw accuracy and more on where documents were allowed to travel.
1. Tesseract (.NET Wrapper)
Tesseract is the baseline. Google has maintained it since 2006, it sits under more commercial OCR products than most vendors admit, and any serious conversation about C# OCR starts here. The canonical .NET wrapper is charlesw/tesseract on GitHub (Apache License 2.0), which tracks the Tesseract 5.x core and ships as the Tesseract NuGet package. There is also an actively maintained fork, TesseractOCR by Sicos1977, which tracks Tesseract 5.5.0.
Basic recognition: You initialize a TesseractEngine pointing at a tessdata directory, load an image as a Pix object, and call Process() to recognize a page.
using System;
using Tesseract;
using var engine = new TesseractEngine(@"./tessdata", "eng", EngineMode.Default);
using var img = Pix.LoadFromFile(@"./samples/receipt.png");
using var page = engine.Process(img);

var text = page.GetText();

Console.WriteLine("Mean confidence: {0:P2}", page.GetMeanConfidence());
Console.WriteLine(text);
Tesseract Basic OCR Output
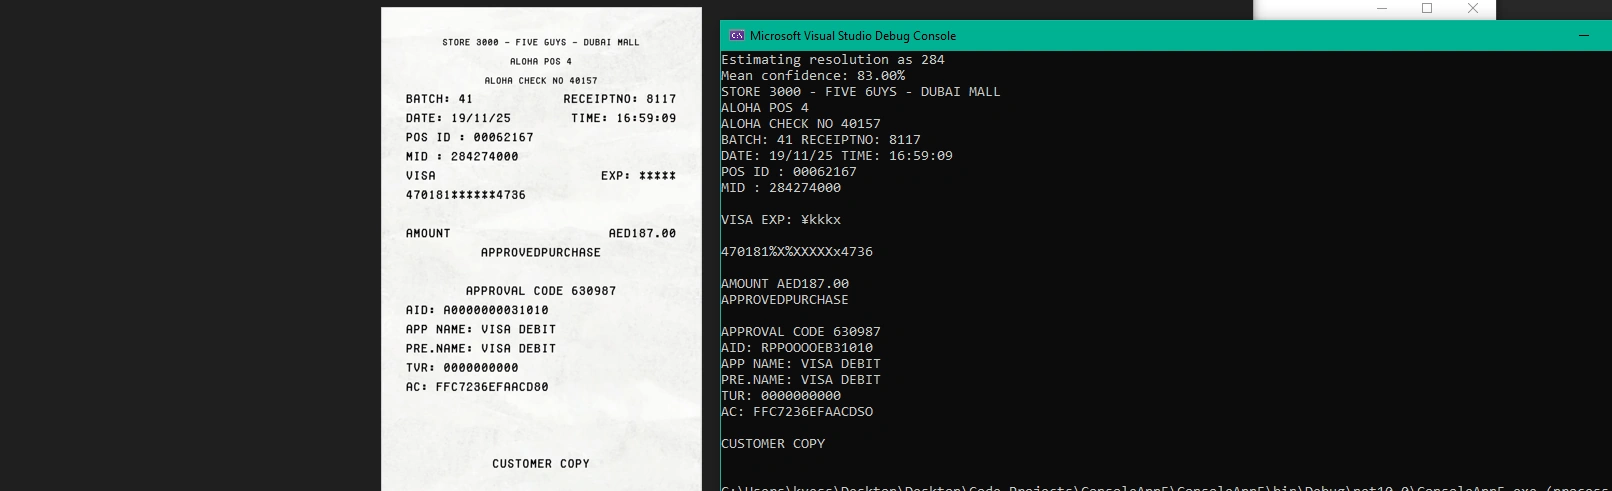
For clean, high-resolution inputs Tesseract is free, fast enough, and genuinely good. On real-world photographs, low-DPI scans, and skewed phone pictures it falls apart without manual preprocessing (deskew, binarization, denoising), and that preprocessing work is the reason every commercial OCR library in this article exists. The other honest caveat is deployment: I have spent more afternoons than I care to admit getting tessdata paths right across Windows and Linux targets.
2. IronOCR
IronOCR is Iron Software's commercial .NET OCR library. Under the hood the IronTesseract engine wraps Tesseract 3, 4, and 5, but what you pay for is the preprocessing pipeline, automatic tessdata and native binary management, and first-class PDF input - not to mention the accurate text extraction, and powerful OCR capabilities with great OCR accuracy. It targets .NET 9, 8, 7, 6, 5, .NET Core and Standard, and Framework 4.6.2 and later, running on Windows, macOS, Linux, Android, iOS, Docker, Azure, and AWS.
Basic image and PDF recognition with just a few lines of code: The entry point is IronTesseract, which accepts an OcrInput built from images, PDFs, streams, or byte arrays. Reading a mixed image-and-PDF batch takes a handful of lines.
using System;
using IronOcr;

var ocr = new IronTesseract();
ocr.Language = OcrLanguage.English;
using var input = new OcrInput();
input.LoadImage(@"./samples/scan.png");
input.LoadPdf(@"./samples/report.pdf");
OcrResult result = ocr.Read(input);
Console.WriteLine(result.Text);
IronOCR Output for Extracting Text
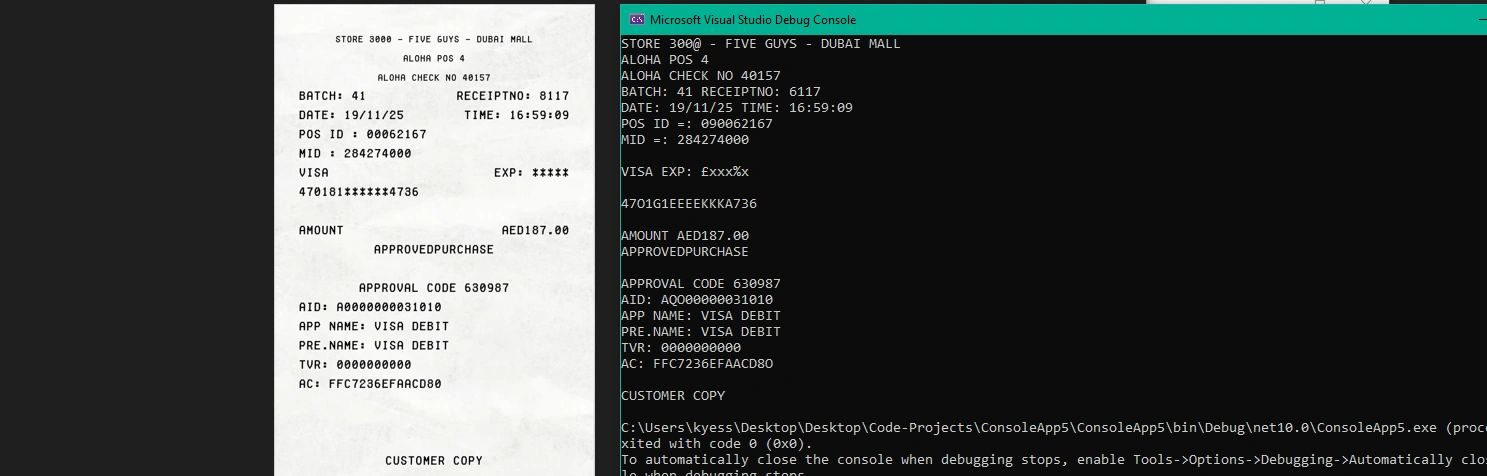
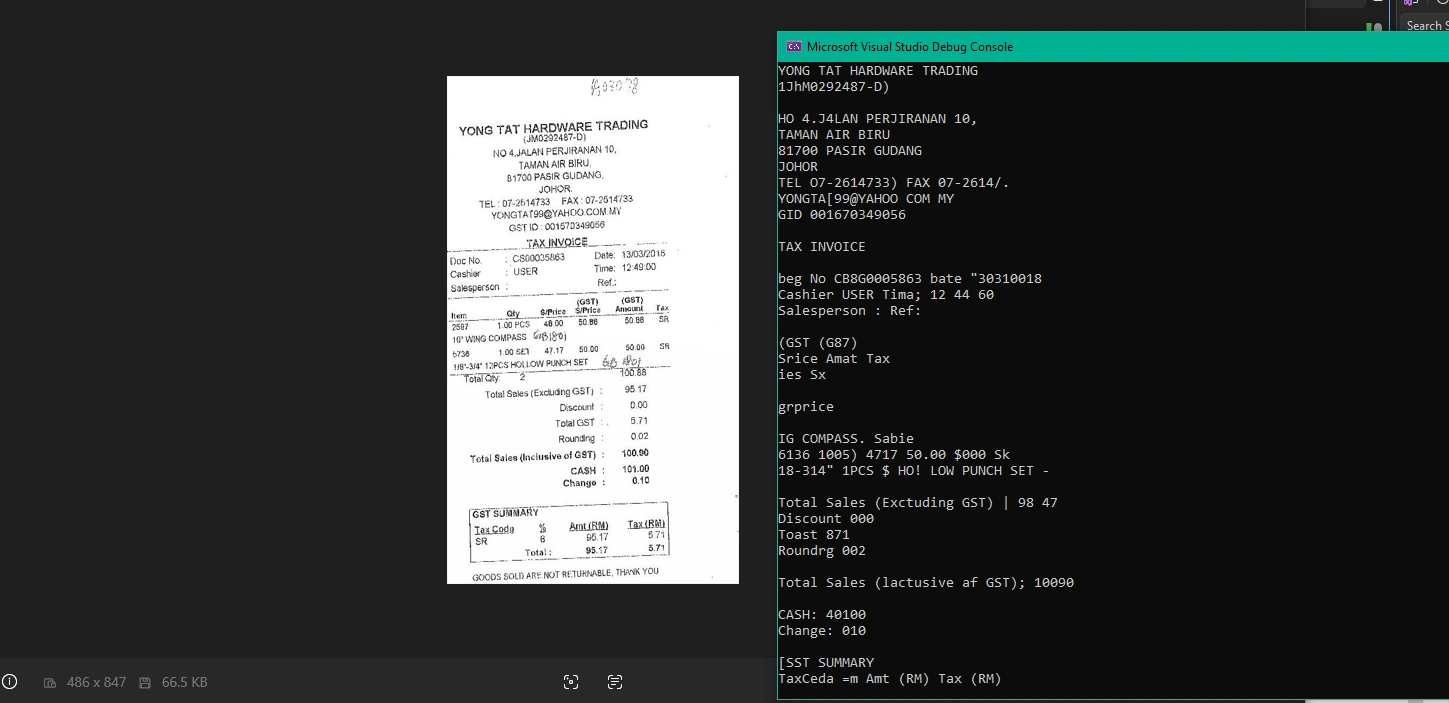
Preprocessing for real-world scans: The preprocessing surface is where IronOCR separates itself from a raw Tesseract wrapper. When we fed IronOCR the same skewed, noisy invoice scans that produced garbage from vanilla Tesseract, the chained filters on OcrInput recovered readable output in a single pass.
using IronOcr;

var ocr = new IronTesseract();
using var input = new OcrInput();
input.LoadImage(@"./samples/skewed-noisy-scan.jpg");

// Repair the input before recognition
input.Deskew();
input.DeNoise();
input.EnhanceResolution(300);
input.ToGrayScale();

OcrResult result = ocr.Read(input);
Console.WriteLine(result.Text);
IronOCR Output with Messy Input Image
Beyond basic recognition, IronOCR supports multiple languages simultaneously through AddSecondaryLanguage(), reads tables when you set Configuration.ReadDataTables = true, and exports directly to searchable PDF and PDF/A (archival PDF format required for long-term storage). It also reads barcodes and QR codes from the same input, which is convenient for invoice and ID-processing pipelines. Pricing is per-developer with runtime-royalty-free production deployment.
3. ABBYY FineReader Engine 12
If your organization has ever paid for enterprise OCR, you have probably paid ABBYY. FineReader Engine 12 is the SDK under ABBYY's FineReader desktop products, and it holds the bar for recognition accuracy on complex layouts, CJK (Chinese, Japanese, Korean) scripts, and handwriting. Release 7 shipped in September 2025 with over 200 recognition languages. The C# API lives in the FREngine namespace and follows a COM-style Engine to FRDocument pattern.
Recognition and export: You load the engine through OutprocLoader, create an FRDocument from an image file, process it, and export the result in a chosen format.
using System;
using FREngine;

var engineLoader = new OutprocLoader();
IEngine engine = engineLoader.InitializeEngine();
FRDocument document = engine.CreateFRDocument();
document.AddImageFile(@"./samples/invoice.pdf", null, null);
document.Process(null);
document.Export(
    @"./out/invoice-searchable.pdf",
    FileExportFormatEnum.FEF_PDF,
    null);
document.Close();
engineLoader.ExplicitlyUnload();
ABBYY Output
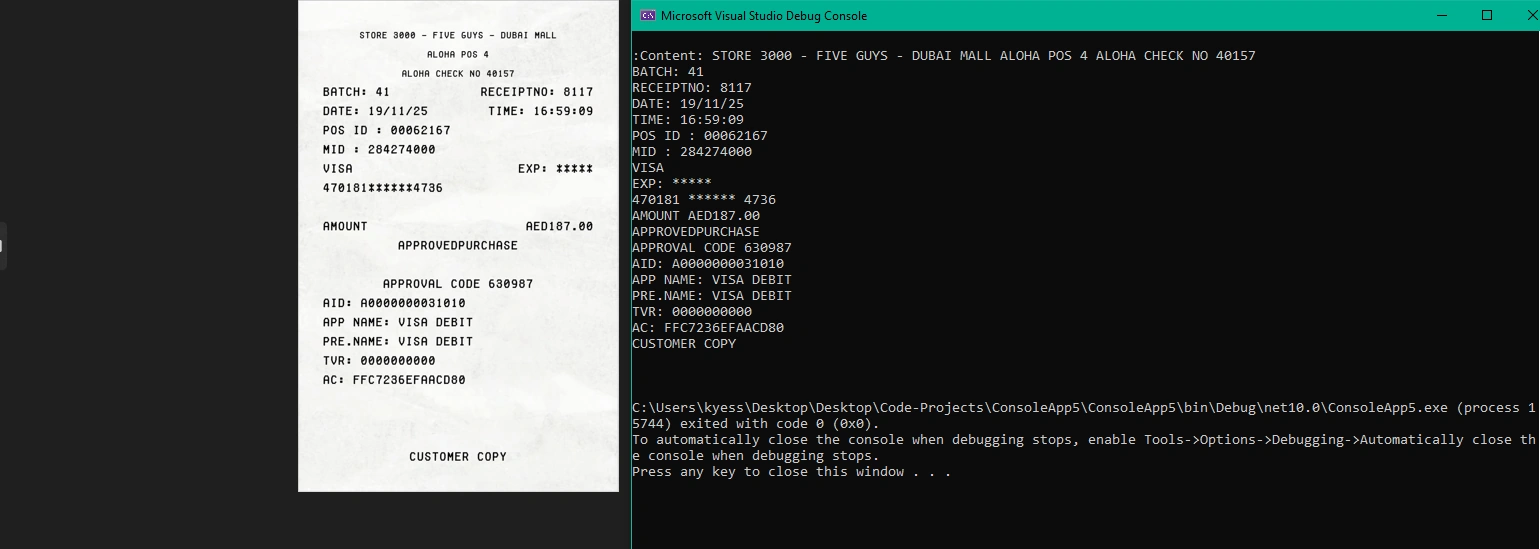
The reason ABBYY keeps its place despite the price tag is layout-reconstruction quality. On documents where the downstream consumer needs structural fidelity (financial reports, multi-column academic papers, forms with nested tables), ABBYY produced output that held together where cheaper engines gave us runs of unordered text. Licensing is quote-based, typically per-developer plus annual page volume, and the SDK requires a direct sales conversation to access.
4. LEADTOOLS OCR
LEADTOOLS is a multi-purpose imaging and document-processing SDK that has been on the market since the early 1990s. It is now published by Apryse Software Corp following the acquisition. The OCR module sits alongside barcode, forms recognition, DICOM, and viewer components, which is either its biggest strength or its biggest overhead depending on what you need.
Strengths: Production-grade ICR (handwriting recognition), MICR (bank-check codeline), OMR (checkboxes and bubble forms), and MRZ (passport machine-readable zones) out of the box. Broad .NET coverage: .NET 6 and later, .NET Framework, MAUI, UWP, WinForms, WPF. The IOcrEngine, AutoRecognizeManager, and OcrZone abstractions map cleanly onto enterprise document pipelines.
Limitations: Heavy to install and harder than it should be to get running cross-platform. If you only need text OCR, you are buying far more SDK than you will use. The Leadtools.Ocr APIs have a steeper learning curve than newer libraries.
Licensing: Commercial enterprise. Per-developer seats with runtime royalties, quote-based.
5. Aspose.OCR for .NET
Aspose.OCR is part of Aspose's broader document-processing suite (Words, Cells, PDF, Slides). The Aspose.OCR.AsposeOcr class wraps a proprietary engine with AI-assisted postprocessing; the current NuGet release is 26.4.0.
Strengths: Over 140 languages including extended Latin, Cyrillic, CJK, Arabic, Persian, Tamil, and Hindi. Multilingual documents with three-plus scripts on the same page recognize cleanly. Converts directly to searchable PDF, Word, or JSON, and the API is one of the cleanest in this list: Recognize(source) returns an OcrOutput that indexes like a collection.
Limitations: License-key management is strict, with a demo watermark applied when the license is unset. If you already run Aspose.Words and Aspose.PDF, Aspose.OCR is a natural fit; if you do not, you are buying into an ecosystem rather than picking a standalone OCR library.
Licensing: Commercial, per-developer. Entry-level developer small-business licensing starts around $99 per Aspose's published pricing.
6. Syncfusion OCR Processor
Syncfusion's OCR support is bundled into the Syncfusion.Pdf.OCR NuGet packages (separate builds for WinForms, WPF, .NET Core, ASP.NET MVC, and Blazor). The OCRProcessor class wraps Tesseract 4.0 and later under the Syncfusion assembly namespace, which gives you Tesseract-grade recognition with zero native-binary fuss.
Strengths: From version 21.1.x onward, the package auto-includes Tesseract binaries and tessdata paths, which removes the most common class of Tesseract integration headaches. Runs on Azure App Services, Azure Functions, Docker, and AWS Lambda. Integrates with the rest of the Syncfusion PDF framework so converting a scanned PDF into a searchable one is a two-call operation.
Limitations: It is Tesseract under the hood, so the recognition ceiling is Tesseract's ceiling. If you need ABBYY-class layout fidelity on complex documents, you will not find it here.
Licensing: Commercial. Syncfusion also publishes a free Community License for individuals and organizations with less than $1 million USD annual gross revenue, five or fewer developers, ten or fewer total employees, and no more than $3 million USD in outside capital from venture capital or private equity. For indie developers and small teams who already fit inside those thresholds, this is a legitimate free path.
7. Google Cloud Vision
Google Cloud Vision's Google.Cloud.Vision.V1 client library exposes the ImageAnnotatorClient, which handles OCR through two methods: DetectText() for general text and DetectDocumentText() for dense, structured documents. The recognition backend is one of the strongest in the industry on rare languages and stylized fonts.
Strengths: Accuracy on hard inputs (street signs, mixed-font posters, handwritten notes) routinely outperforms on-premise engines. The C# client library is mature and idiomatic. Returns structured TextAnnotation with bounding polygons down to the symbol level.
Limitations: Your documents leave the building. For regulated data, Google Cloud Vision is disqualified before you evaluate accuracy. Costs can surprise on high-volume workflows.
Licensing: Pay-as-you-go per 1,000 units; the first 1,000 units per month are free on most features.
8. Azure AI Vision (Image Analysis)
Microsoft's cloud OCR lives in the Azure.AI.Vision.ImageAnalysis SDK. The ImageAnalysisClient exposes an Analyze() method that accepts VisualFeatures.Read and returns DetectedTextBlock, DetectedTextLine, and DetectedTextWord structures. If you are already shipping on Azure, the managed-identity and key-credential authentication alone saves a week of integration work.
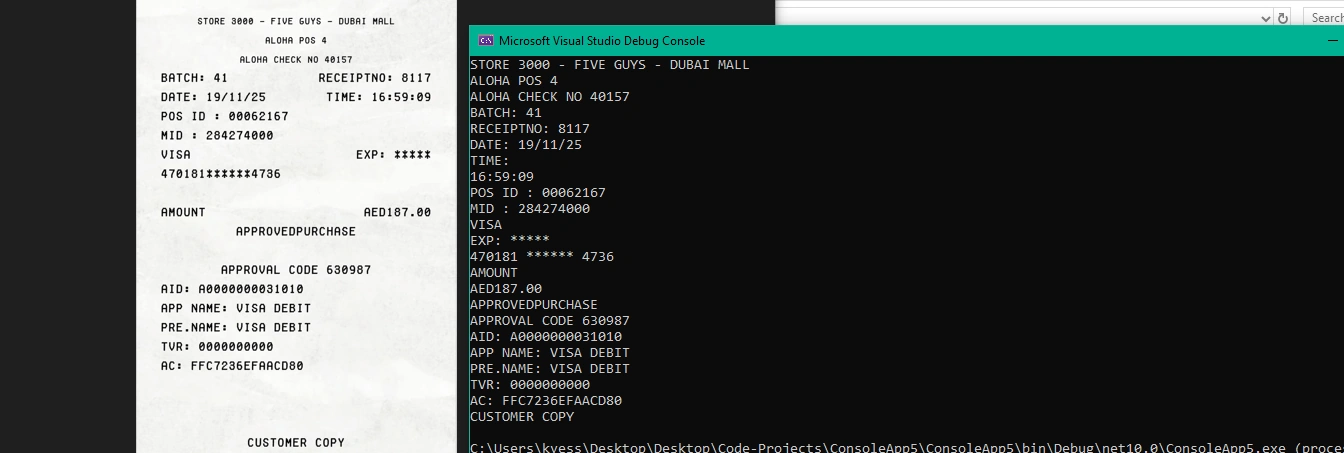
Read-based recognition: The typical pattern reads an image from disk, pipes it through the client, and walks the block-line-word tree.
using System;
using System.IO;
using Azure;
using Azure.AI.Vision.ImageAnalysis;

string endpoint = Environment.GetEnvironmentVariable("VISION_ENDPOINT");
string key = Environment.GetEnvironmentVariable("VISION_KEY");
var client = new ImageAnalysisClient(new Uri(endpoint), new AzureKeyCredential(key));

BinaryData imageData = BinaryData.FromStream(File.OpenRead(@"./samples/receipt.jpg"));
ImageAnalysisResult result = client.Analyze(imageData, VisualFeatures.Read);
foreach (DetectedTextBlock block in result.Read.Blocks)
{
    foreach (DetectedTextLine line in block.Lines)
    {
        Console.WriteLine(line.Text);
    }
}
Join the conversation! Your thoughts help the community grow.