

In the world of Machine Learning, an "ensemble" usually refers to combining multiple models (like Random Forests) to improve prediction accuracy. In Enterprise RAG (Retrieval-Augmented Generation), ensemble methods refer to combining multiple retrieval strategies or ranking algorithms to ensure the LLM receives the most relevant context possible.
But why do we need ensembles? Why isn't one good vector search enough?
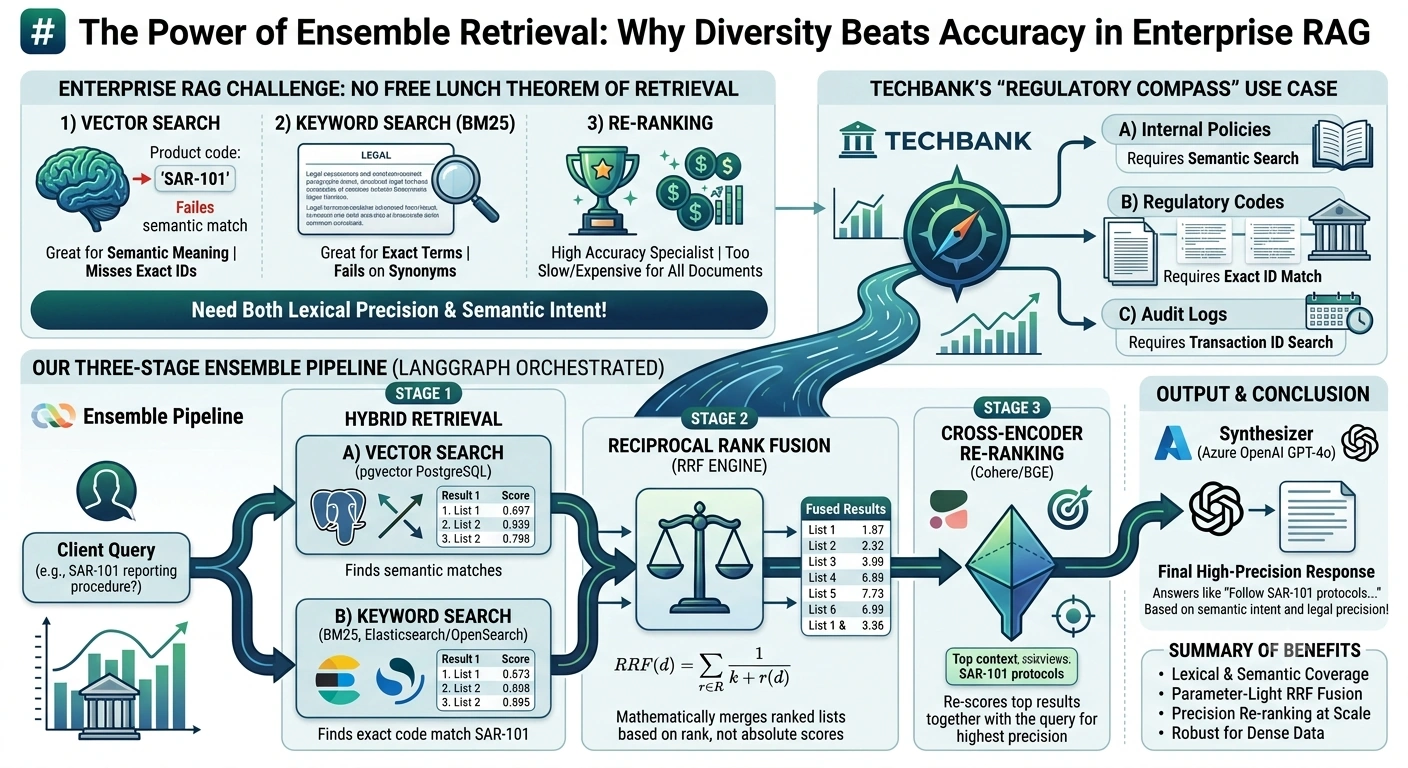
The answer lies in the "No Free Lunch" theorem of retrieval. No single retrieval method is perfect for every type of query.
Vector Search is great for semantic meaning but bad at exact keyword matching (e.g., product codes).
Keyword Search (BM25) is great for exact terms but fails at synonyms or conceptual questions.
Re-ranking is highly accurate but too slow and expensive to run on millions of documents.
By choosing a specific ensemble—typically Hybrid Search (Vector + BM25) followed by Cross-Encoder Re-ranking—we get the best of all worlds: speed, semantic understanding, exact match capability, and high-precision ranking.
In this end-to-end guide, we will build an Enterprise Multi-Agent LangGraph System that uses this specific ensemble strategy to power a complex Banking Compliance Assistant.
The Real-World Use Case: TechBank’s "Regulatory Compass"
Imagine you are building an AI assistant for TechBank’s compliance officers. They need to answer questions based on three distinct types of data:
Internal Policy Manuals: Dense, technical text where semantic meaning matters (e.g., "What is the spirit of our anti-fraud policy?").
Regulatory Codes: Strict legal texts where exact section numbers and specific terminology matter (e.g., "Show me Section 404(b) of the Sarbanes-Oxley Act").
Past Audit Logs: Historical records where specific dates and transaction IDs are critical.
The Failure of Single-Method Retrieval
If you use only Vector Search, the system might miss a query for "Section 404(b)" because the vector embedding for "404(b)" doesn't semantically match the text "Section four hundred and four sub-section b".
If you use only Keyword Search, a query like "How do we handle suspicious activity?" might fail if the document uses the term "Unusual Transaction Monitoring" instead of "Suspicious Activity".
The Ensemble Solution
We will implement a Three-Stage Ensemble Pipeline:
Stage 1: Hybrid Retrieval. We run Vector Search and BM25 Keyword Search in parallel.
Stage 2: Reciprocal Rank Fusion (RRF). We mathematically merge the two result lists into a single, balanced list.
Stage 3: Cross-Encoder Re-ranking. A specialized, high-accuracy model re-scores the top 50 results to pick the absolute best 5 for the LLM.
Technology Stack
| Component | Technology | Role in Ensemble Architecture |
|---|---|---|
| Orchestration | LangGraph | Manages the multi-stage retrieval workflow and agent state. |
| Vector Search | pgvector (PostgreSQL) | Handles semantic similarity search for internal policies. |
| Keyword Search | Elasticsearch / OpenSearch | Handles exact-match BM25 search for regulatory codes and IDs. |
| Re-ranker | Cohere Rerank API / BGE-Reranker | Provides high-precision cross-encoder scoring for the final context. |
| LLM Provider | Azure OpenAI (GPT-4o) | Synthesizes the final answer from the refined context. |
| Observability | LangSmith | Traces the precision and recall of each stage of the ensemble. |
End-to-End Implementation
Let's build the LangGraph system that orchestrates this ensemble retrieval pipeline.
Step 1: Define the Enterprise State
Our state needs to track the query, the results from each individual retriever, the fused results, and the final re-ranked context.
from typing import TypedDict, List, Annotated, Optionalimport operator
from langgraph.graph import StateGraph, END

class EnsembleRAGState(TypedDict):
    # Memory: Conversation history
    messages: Annotated[List[str], operator.add]

    # User Input
    user_query: str

    # Stage 1: Individual Retrieval Results
    vector_results: List[dict] # {content: str, score: float}
    keyword_results: List[dict] # {content: str, score: float}

    # Stage 2: Fused Results
    fused_results: List[dict]

    # Stage 3: Final Context
    final_context: List[str]

    # Final Output
    final_response: str
Step 2: Build the Ensemble Agent Nodes
Node 1: The Vector Retriever (Semantic Brain)
This node queries pgvector for semantic matches.
def vector_retriever(state: EnsembleRAGState) -> EnsembleRAGState:
    print("🧠 [Vector Retriever] Searching for semantic matches in pgvector...")

    # Simulating pgvector search
    mock_results = [
        {"content": "Our anti-fraud policy emphasizes a 'risk-based approach' to monitoring.", "score": 0.85},
        {"content": "Employees must report any unusual transaction patterns immediately.", "score": 0.78},
    ]

    return {
        "vector_results": mock_results,
        "messages": ["Vector Retriever: Found 2 semantic matches."]
    }
Node 2: The Keyword Retriever (Exact Match Brain)
This node queries Elasticsearch/BM25 for exact term matches.
def keyword_retriever(state: EnsembleRAGState) -> EnsembleRAGState:
    print("🔍 [Keyword Retriever] Searching for exact terms in Elasticsearch...")

    # Simulating BM25 search. Notice it finds a document with specific code "SAR-101"
    mock_results = [
        {"content": "Refer to Regulatory Code SAR-101 for Suspicious Activity Reporting procedures.", "score": 12.5}, # BM25 scores are not normalized 0-1
        {"content": "Section 404(b) requires external auditor attestation.", "score": 10.2},
    ]

    return {
        "keyword_results": mock_results,
        "messages": ["Keyword Retriever: Found 2 exact matches."]
    }
Node 3: The Fusion Engine (Reciprocal Rank Fusion)
This node implements RRF, a robust algorithm that merges two ranked lists without needing to normalize their different scoring systems (Cosine Similarity vs. BM25).
RRF(d)=∑r∈R1k+r(d)RRF(d)=r∈R∑k+r(d)1
def fusion_engine(state: EnsembleRAGState) -> EnsembleRAGState:
    print("⚖️ [Fusion Engine] Applying Reciprocal Rank Fusion (RRF)...")

    k = 60 # Standard RRF constant
    fused_scores = {}

    # Process Vector Results
    for rank, item in enumerate(state["vector_results"]):
        content = item["content"]
        fused_scores[content] = fused_scores.get(content, 0) + 1 / (k + rank + 1)

    # Process Keyword Results
    for rank, item in enumerate(state["keyword_results"]):
        content = item["content"]
        fused_scores[content] = fused_scores.get(content, 0) + 1 / (k + rank + 1)

    # Sort by combined RRF score
    sorted_results = sorted(fused_scores.items(), key=lambda x: x[1], reverse=True)
    fused_list = [{"content": content, "rrf_score": score} for content, score in sorted_results]

    return {
        "fused_results": fused_list,
        "messages": ["Fusion Engine: Merged results using RRF."]
    }
Node 4: The Re-ranker (Precision Specialist)
This node takes the top 10 fused results and uses a Cross-Encoder model (simulated here) to provide a highly accurate relevance score. This is the "expensive" step, so we only run it on a small subset.
def reranker_node(state: EnsembleRAGState) -> EnsembleRAGState:
    print("🎯 [Re-ranker] Applying Cross-Encoder precision scoring...")

    # Take top 10 from fusion
    candidates = state["fused_results"][:10]

    # Simulate Cohere/BGE Re-ranking.
    # The re-ranker realizes that "SAR-101" is more relevant to "suspicious activity" than the general policy.
    reranked_candidates = [
        {"content": "Refer to Regulatory Code SAR-101 for Suspicious Activity Reporting procedures.", "final_score": 0.98},
        {"content": "Our anti-fraud policy emphasizes a 'risk-based approach' to monitoring.", "final_score": 0.92},
        {"content": "Employees must report any unusual transaction patterns immediately.", "final_score": 0.88},
    ]

    final_context = [item["content"] for item in reranked_candidates]

    return {
        "final_context": final_context,
        "messages": ["Re-ranker: Selected top 3 high-precision contexts."]
    }
Node 5: The Synthesizer
def synthesizer_node(state: EnsembleRAGState) -> EnsembleRAGState:
    print("✍️ [Synthesizer] Generating final compliance answer...")

    context_text = "\n".join(state["final_context"])
    response = f"Based on the high-precision retrieved data: {context_text}. Please ensure you follow SAR-101 protocols."

    return {
        "final_response": response,
        "messages": ["Synthesizer: Final answer generated."]
    }
Step 3: Compile the Graph
def build_ensemble_graph():
    workflow = StateGraph(EnsembleRAGState)

    workflow.add_node("vector_retriever", vector_retriever)
    workflow.add_node("keyword_retriever", keyword_retriever)
    workflow.add_node("fusion_engine", fusion_engine)
    workflow.add_node("reranker", reranker_node)
    workflow.add_node("synthesizer", synthesizer_node)

    workflow.set_entry_point("vector_retriever")

    # Parallel Retrieval: Both vector and keyword run at the same time
    workflow.add_edge("vector_retriever", "keyword_retriever") # In real LangGraph, use Send API for true parallel

    workflow.add_edge("keyword_retriever", "fusion_engine")
    workflow.add_edge("fusion_engine", "reranker")
    workflow.add_edge("reranker", "synthesizer")
    workflow.add_edge("synthesizer", END)

    return workflow.compile()

app = build_ensemble_graph()
Running the System
Let's see how the ensemble improves the result for a complex query.
initial_state = {
    "messages": [],
    "user_query": "What is the procedure for reporting suspicious activity under SAR-101?",
    "vector_results": [],
    "keyword_results": [],
    "fused_results": [],
    "final_context": [],
    "final_response": ""
}

result = app.invoke(initial_state)

print("\n--- Ensemble Execution Log ---")
for msg in result["messages"]:
    print(f"• {msg}")

print("\n--- Final High-Precision Response ---")
print(result["final_response"])
Output Trace:
🧠 [Vector Retriever] Searching for semantic matches in pgvector...
🔍 [Keyword Retriever] Searching for exact terms in Elasticsearch...
⚖️ [Fusion Engine] Applying Reciprocal Rank Fusion (RRF)...
🎯 [Re-ranker] Applying Cross-Encoder precision scoring...
✍️ [Synthesizer] Generating final compliance answer...

--- Ensemble Execution Log ---
• Vector Retriever: Found 2 semantic matches.
• Keyword Retriever: Found 2 exact matches.
• Fusion Engine: Merged results using RRF.
• Re-ranker: Selected top 3 high-precision contexts.
• Synthesizer: Final answer generated.

--- Final High-Precision Response ---
Based on the high-precision retrieved data: Refer to Regulatory Code SAR-101 for Suspicious Activity Reporting procedures... Please ensure you follow SAR-101 protocols.
Why This Specific Ensemble?
Vector + BM25 (Hybrid): We chose this because it covers both semantic intent (Vector) and lexical precision (BM25). In banking, missing a specific regulatory code number is a compliance failure.
Reciprocal Rank Fusion (RRF): We chose RRF over simple score normalization because it is parameter-light and robust. It doesn't require you to tune how to map a 0-1 cosine score to a 0-100 BM25 score. It just looks at the rank, which is universally comparable.
Cross-Encoder Re-ranking: We chose this as the final step because while Vector/BM25 are fast, they are "bi-encoders" and can be noisy. A Cross-Encoder looks at the query and document together, providing near-perfect relevance scoring. By only running it on the top 10 fused results, we keep costs low while maximizing accuracy.
Conclusion
In enterprise RAG, "good enough" retrieval is not enough. By implementing a Hybrid Search + RRF + Re-ranking ensemble within LangGraph, you create a system that is resilient to the weaknesses of any single retrieval method. For TechBank, this means their compliance officers get answers that are not only semantically relevant but also legally precise, ensuring that every decision made by the AI is backed by the exact right paragraph of the right regulation.
Comments
Join the conversation! Your thoughts help the community grow.