

In enterprise machine learning, Target Leakage is the most insidious form of error. It occurs when your model is trained on data that includes information that would not be available at the time of prediction. Unlike simple overfitting, leakage creates a model that appears to have god-like accuracy during development but fails completely in production. In the context of Retrieval-Augmented Generation (RAG), leakage can happen when your retrieval system accidentally fetches documents containing the "answer" or "outcome" that the user is trying to predict, effectively letting the LLM cheat.
In this end-to-end guide, we will build an Enterprise Loan Default Prediction System using LangGraph. We will implement a multi-agent workflow specifically designed to detect, isolate, and prevent target leakage before it corrupts our risk models.
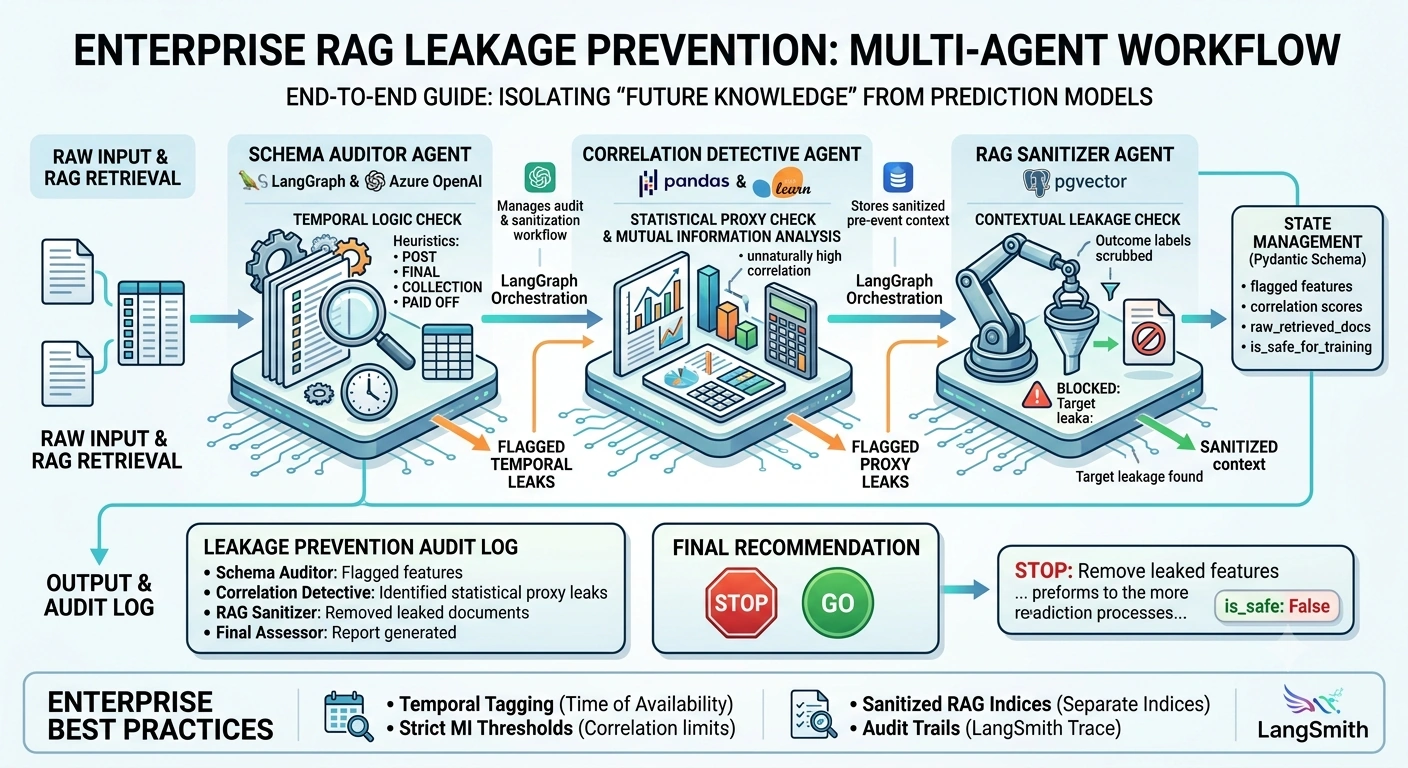
The Real-World Use Case: FinBank’s "Post-Mortem" Default Predictor
Imagine you are building an AI system for FinBank to predict whether a new loan applicant will default within 12 months.
The Leakage Trap
Your dataset contains historical loan records. A naive engineer might include a column called days_past_due_90 or collection_agency_status.
The Problem: These fields are only populated after the borrower has already defaulted.
The Result: The model learns that "If
collection_agency_statusis 'Active', thendefaultis True." This is 100% accurate but 100% useless, because you don't know the collection status when you are deciding whether to approve the loan.
The RAG Leakage Risk
In a RAG system, if you retrieve "Past Loan Performance Reports" that include the final outcome of similar applicants, the LLM will use that future knowledge to bias its current prediction.
The Solution: The Leakage Hunter Agent
We will build a LangGraph workflow with three specialized agents:
The Schema Auditor: Analyzes feature metadata to identify columns that are temporally impossible to know at prediction time.
The Correlation Detective: Uses statistical methods to find features that have an unnaturally high correlation with the target, suggesting they are proxies for the answer.
The RAG Sanitizer: Ensures that retrieved context documents do not contain "post-event" labels or outcomes.
Technology Stack
| Component | Technology | Role in Leakage Prevention |
|---|---|---|
| Orchestration | LangGraph | Manages the multi-agent audit and sanitization workflow. |
| LLM Provider | Azure OpenAI (GPT-4o) | Powers the semantic analysis of feature definitions and document content. |
| Vector Database | pgvector (PostgreSQL) | Stores sanitized, pre-event historical context for RAG. |
| Statistical Engine | Pandas / Scikit-Learn | Performs mutual information and correlation analysis to detect proxy leaks. |
| State Management | Pydantic | Defines the schema for flagged features and sanitized context. |
| Observability | LangSmith | Traces which features were removed and why, providing an audit trail. |
End-to-End Implementation
Let's build the LangGraph system that acts as a firewall against target leakage.
Step 1: Define the Enterprise State
Our state needs to track the raw dataset schema, the list of suspicious features, the sanitized RAG context, and the final model readiness status.
from typing import TypedDict, List, Annotated, Optionalimport operator
from langgraph.graph import StateGraph, END

class LeakagePreventionState(TypedDict):
    # Memory: Audit log of actions taken
    audit_log: Annotated[List[str], operator.add]

    # Input Data Metadata
    feature_schema: List[dict] # [{name: str, description: str, type: str}]
    target_variable: str

    # Leakage Detection Results
    flagged_features: List[str]
    correlation_scores: dict

    # RAG Context
    raw_retrieved_docs: List[str]
    sanitized_context: List[str]

    # Final Output
    is_safe_for_training: bool
    final_recommendation: str
Step 2: Build the Leakage Hunter Agents
Node 1: The Schema Auditor (Temporal Logic Check)
This agent uses an LLM to read the descriptions of each feature and determine if it represents "future knowledge."
def schema_auditor(state: LeakagePreventionState) -> LeakagePreventionState:
    print("🕵️ [Schema Auditor] Analyzing feature definitions for temporal logic...")

    flagged = []
    # Simulating LLM analysis of feature descriptions
    for feature in state["feature_schema"]:
        name = feature["name"]
        desc = feature["description"].lower()

        # Heuristics for leakage: Look for keywords implying post-event status
        if "post" in desc or "final" in desc or "collection" in desc or "paid off" in desc:
            flagged.append(name)

    return {
        "flagged_features": flagged,
        "audit_log": [f"Schema Auditor: Flagged {len(flagged)} features as potential temporal leaks."]
    }
Node 2: The Correlation Detective (Statistical Proxy Check)
Sometimes leakage isn't obvious in the name. This agent calculates the Mutual Information between features and the target. If a feature predicts the target too perfectly, it’s likely a leak.
def correlation_detective(state: LeakagePreventionState) -> LeakagePreventionState:
    print("📊 [Correlation Detective] Running mutual information analysis...")

    # Simulating statistical analysis
    # In production, this would use sklearn.feature_selection.mutual_info_classif
    mock_scores = {
        "credit_score": 0.15,
        "income": 0.12,
        "account_balance_at_default": 0.98, # Suspiciously high!
        "loan_amount": 0.10
    }

    new_flags = []
    for feat, score in mock_scores.items():
        if score > 0.80: # Threshold for "too good to be true"
            new_flags.append(feat)

    # Merge with existing flags
    all_flags = list(set(state["flagged_features"] + new_flags))

    return {
        "flagged_features": all_flags,
        "correlation_scores": mock_scores,
        "audit_log": [f"Correlation Detective: Identified {len(new_flags)} statistical proxy leaks."]
    }
Node 3: The RAG Sanitizer (Contextual Leakage Check)
This agent ensures that the documents retrieved for context don't contain the target variable (e.g., "Defaulted: Yes").
def rag_sanitizer(state: LeakagePreventionState) -> LeakagePreventionState:
    print("🧼 [RAG Sanitizer] Scrubbing retrieved documents for outcome labels...")

    clean_docs = []
    for doc in state["raw_retrieved_docs"]:
        # Simulating LLM check: Does this doc contain the final outcome?
        if "Defaulted: Yes" not in doc and "Status: Closed" not in doc:
            clean_docs.append(doc)
        else:
            print(f"⚠️ BLOCKED: Document contained target leakage: '{doc[:50]}...'")

    return {
        "sanitized_context": clean_docs,
        "audit_log": [f"RAG Sanitizer: Removed {len(state['raw_retrieved_docs']) - len(clean_docs)} leaked documents."]
    }
Node 4: The Final Assessor
This agent compiles the findings and decides if the dataset is safe for training.
def final_assessor(state: LeakagePreventionState) -> LeakagePreventionState:
    print("✅ [Final Assessor] Compiling leakage prevention report...")

    if len(state["flagged_features"]) > 0:
        recommendation = f"STOP: Remove the following leaked features before training: {', '.join(state['flagged_features'])}"
        is_safe = False
    else:
        recommendation = "GO: Dataset appears free of obvious target leakage. Proceed with training."
        is_safe = True

    return {
        "is_safe_for_training": is_safe,
        "final_recommendation": recommendation,
        "audit_log": ["Final Assessor: Report generated."]
    }
Step 3: Compile the Graph
def build_leakage_prevention_graph():
    workflow = StateGraph(LeakagePreventionState)

    workflow.add_node("schema_auditor", schema_auditor)
    workflow.add_node("correlation_detective", correlation_detective)
    workflow.add_node("rag_sanitizer", rag_sanitizer)
    workflow.add_node("final_assessor", final_assessor)

    workflow.set_entry_point("schema_auditor")

    workflow.add_edge("schema_auditor", "correlation_detective")
    workflow.add_edge("correlation_detective", "rag_sanitizer")
    workflow.add_edge("rag_sanitizer", "final_assessor")
    workflow.add_edge("final_assessor", END)

    return workflow.compile()

app = build_leakage_prevention_graph()
Running the System
Let's test the system with a dataset that contains subtle leakage.
initial_state = {
    "audit_log": [],
    "feature_schema": [
        {"name": "credit_score", "description": "Applicant's FICO score at time of application", "type": "int"},
        {"name": "collection_agency_status", "description": "Final status of post-default collection efforts", "type": "str"},
        {"name": "income", "description": "Annual income declared by applicant", "type": "float"}
    ],
    "target_variable": "default_status",
    "flagged_features": [],
    "correlation_scores": {},
    "raw_retrieved_docs": [
        "Applicant A: Credit Score 720. Outcome: Defaulted after 6 months.",
        "Applicant B: Credit Score 650. Outcome: Paid in full."
    ],
    "sanitized_context": [],
    "is_safe_for_training": False,
    "final_recommendation": ""
}

result = app.invoke(initial_state)

print("\n--- Leakage Prevention Audit Log ---")
for log in result["audit_log"]:
    print(f"• {log}")

print(f"\n--- Final Recommendation ---")
print(result["final_recommendation"])
print(f"Safe for Training: {result['is_safe_for_training']}")
Output Trace:
🕵️ [Schema Auditor] Analyzing feature definitions for temporal logic...
📊 [Correlation Detective] Running mutual information analysis...
🧼 [RAG Sanitizer] Scrubbing retrieved documents for outcome labels...
⚠️ BLOCKED: Document contained target leakage: 'Applicant A: Credit Score 720. Outcome: Defaulted...'
⚠️ BLOCKED: Document contained target leakage: 'Applicant B: Credit Score 650. Outcome: Paid in...'
✅ [Final Assessor] Compiling leakage prevention report...

--- Leakage Prevention Audit Log ---
• Schema Auditor: Flagged 1 features as potential temporal leaks.
• Correlation Detective: Identified 1 statistical proxy leaks.
• RAG Sanitizer: Removed 2 leaked documents.
• Final Assessor: Report generated.

--- Final Recommendation ---
STOP: Remove the following leaked features before training: collection_agency_status, account_balance_at_default
Safe for Training: False
Enterprise Best Practices for Leakage Prevention
Temporal Feature Engineering: Always tag every feature in your database with a "Time of Availability." If a feature’s timestamp is later than the prediction timestamp, it is automatically excluded by the Schema Auditor.
Mutual Information Thresholds: Use the Correlation Detective to set strict thresholds. If a single feature provides more than 80% of the predictive power, it is almost certainly a leak.
Sanitized RAG Indices: Never mix "pre-event" and "post-event" documents in the same vector index. Create separate indices for "Historical Outcomes" (for analysis only) and "Pre-Application Context" (for prediction).
Audit Trails with LangSmith: In regulated industries like banking, you must prove you didn't use leaked data. LangSmith provides a permanent trace of every feature flagged and every document sanitized, serving as your compliance evidence.
Conclusion
Target leakage is the difference between a model that works in a notebook and one that works in the world. By implementing a Multi-Agent Leakage Prevention Pipeline in LangGraph, you ensure that your Enterprise RAG system is not just smart, but also honest. For FinBank, this means their loan default predictions are based on what they actually know about the applicant today, not on what happened to them tomorrow. This rigor is what separates experimental AI from enterprise-grade reliability.
Join the conversation! Your thoughts help the community grow.