
In this article, I will cover the capabilities of Snowflake Cortex’s Large Language Model (LLM) function, which can be utilized for a variety of tasks, such as sentiment analysis, text completion, and language translation.
Introduction
Snowflake has introduced a powerful suite of LLM functions under its Cortex platform that offers access to advanced LLMs from companies like Google, Meta, Mistral, and Anthropic. These models are hosted and managed by Snowflake, ensuring seamless integration and high performance without the need for extensive setup. With Snowflake, your data remains securely within the platform, ensuring you benefit from the expected performance, scalability, and governance.
Snowflake Cortex features are provided as SQL functions and are also available in Python.
Snowflake Cortex LLM functions can be grouped into the categories below.
1. COMPLETE Function
The COMPLETE function is capable of performing a wide range of tasks, such as aspect-based sentiment classification, synthetic data generation, and customized summaries.
2. Task-Specific Function
These functions are tailored for specific tasks, making them highly efficient for routine operations:
- CLASSIFY_TEXT: Categorizes text into predefined categories.
- EXTRACT_ANSWER: Finds answers to questions within unstructured data.
- PARSE_DOCUMENT: Extracts text and layout elements from documents.
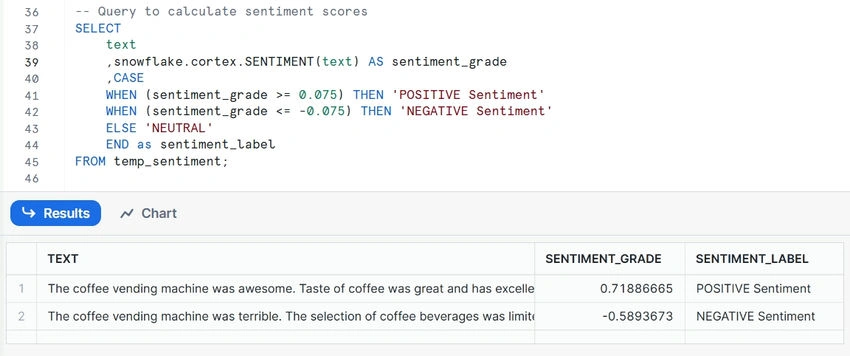
- SENTIMENT: Analyzes the sentiment of a given text and returns a score from -1 to 1, representing sentiment as negative or positive.
- SUMMARIZE: Return a summary of a given text.
- TRANSLATE: Translates text between supported languages
3. Helper Function
Helper functions enhance the reliability of other LLM functions by managing token counts and handling execution errors:
- COUNT_TOKENS: Returns the token count for a given text.
- TRY_COMPLETE: It is similar to the COMPLETE function but returns NULL instead of an error when execution fails
Lab Setup
Let’s set the environment before using the LLM function -
Set up your current context for the role, database, schema, and warehouse.
Set the Role
USE ROLE accountadmin;
Set the Warehouse
USE WAREHOUSE compute_wh;
Create a database
CREATE DATABASE IF NOT EXISTS llmtest_db;
Create a schema in a database
CREATE SCHEMA IF NOT EXISTS llmtest_db.data;
Create a stage to hold data for sentiment analysis
CREATE STAGE IF NOT EXISTS llmtest_db.data.reviews

DIRECTORY = (ENABLE = TRUE, REFRESH_ON_CREATE = TRUE);
Switch to the schema that was created on previous steps -
USE SCHEMA llmtest_db.data;
Run LLM functions
1. Analyze Sentiment
This LLM function aims to detect the mood or tone of the given English-language text. The function returns a sentiment score from -1 to 1, representing the text’s detected negative or positive sentiment. This function takes a single parameter, the English-language input text you want analyzed. It returns a floating-point number from -1 to 1 (inclusive), indicating the text’s negative or positive sentiment level. Values around 0 indicate neutral sentiment
Setting variables for sentiments
SET VAR_SENTIMENT_POSITIVE = 'The coffee vending machine was awesome. Taste of coffee was great and has excellent selection of coffee beverages.';

SET VAR_SENTIMENT_NEGATIVE = 'The coffee vending machine was terrible. The selection of coffee beverages was limited and taste poor.';
Create Temporary table
CREATE OR REPLACE TEMPORARY TABLE temp_sentiment (text VARCHAR);
Inserting the example texts into the temporary table
INSERT INTO temp_sentiment (text) VALUES ($VAR_SENTIMENT_POSITIVE);

INSERT INTO temp_sentiment (text) VALUES ($VAR_SENTIMENT_NEGATIVE);
Display the stored texts to verify the correct insertion
SELECT * FROM temp_sentiment;
Let's run the below query to calculate sentiment scores
Join the conversation! Your thoughts help the community grow.