
Abstract / Overview
Cosmos Reason 2 is an open, customizable reasoning vision-language model (VLM) from NVIDIA designed for “physical AI”: systems that must interpret images or video, reason about space, time, and physics, and then produce action-relevant outputs (plans, constraints, detections, and decisions). It sits inside the NVIDIA Cosmos family of world foundation models, pairing naturally with synthetic data generation and simulation workflows so robotics, autonomous vehicles, and industrial vision agents can be trained and evaluated more reliably. (NVIDIA Docs)
Assumption: This article targets developers building embodied agents (robots, AV stacks, vision agents) who want an actionable understanding of Cosmos Reason 2 and how to integrate it into real pipelines as of January 8, 2026.
Conceptual Background
What “reasoning VLM” means in physical AI
A conventional vision model answers “what is in the scene.” A physical-AI-grade reasoning VLM must also answer:
What is happening over time (spatiotemporal understanding)
What physical constraints apply (stability, collisions, occlusions, motion)
What the agent should do next (action selection, safe plans, verification steps)
What evidence supports the decision (structured explanations suitable for logging and audits)
NVIDIA positions Cosmos Reason 2 as a model that uses prior knowledge, physics understanding, and common sense to comprehend the real world and interact with it. (NVIDIA)
Where Cosmos Reason 2 fits in NVIDIA Cosmos
NVIDIA Cosmos is presented as a platform of “world foundation models” that covers:
Cosmos Transfer (turn simulation outputs into high-fidelity data)
Cosmos Predict (world prediction and policy evaluation in simulation)
Cosmos Reason 2 (reasoning VLM for understanding and action-centric outputs)
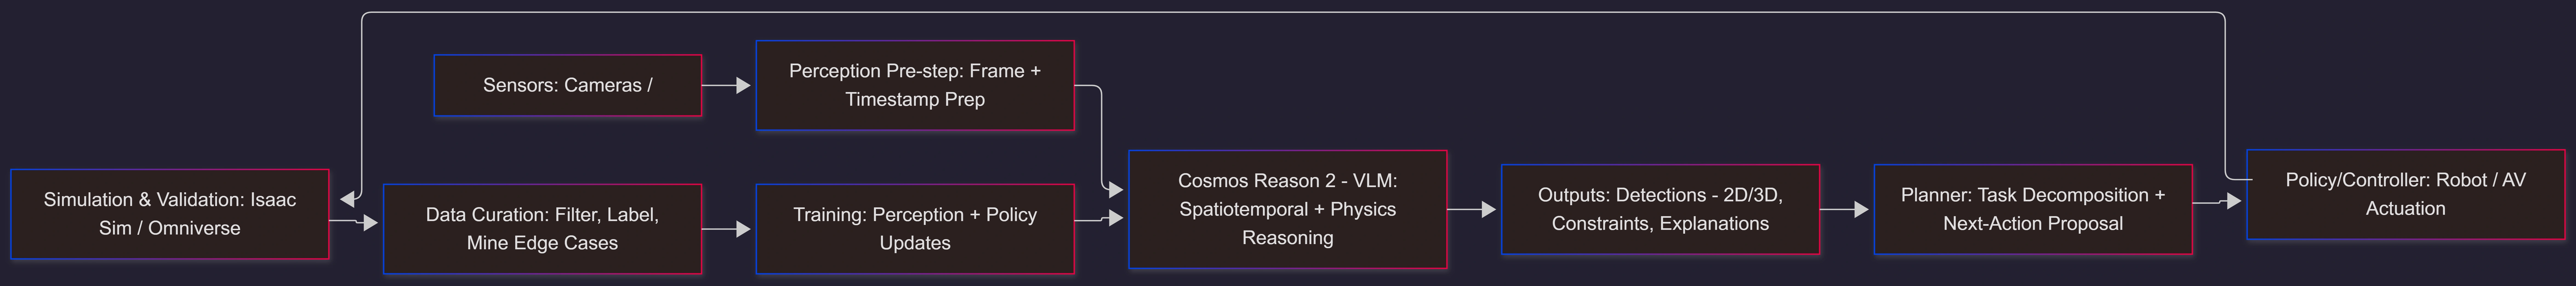
In practice, this encourages a closed loop:
Simulate or capture sensor data
Generate or enhance scenarios with world models
Use Reason 2 to label, filter, plan, and validate
Train downstream perception and policy models
Re-evaluate in simulation and iterate
NVIDIA explicitly highlights “reason, filter synthetic data using Cosmos Reason” as part of robot learning workflows. (NVIDIA)
Why this matters now
Three shifts make physical AI workflows unusually data-hungry and evaluation-heavy:
Synthetic data is moving from “nice to have” to “default.” Gartner predicted that by 2024, 60% of data for AI would be synthetic (up from 1% in 2021). (Gartner)
Data readiness is becoming a major failure mode. Gartner predicts that through 2026, organizations will abandon 60% of AI projects unsupported by AI-ready data. (Gartner)
Autonomous systems are operating at real scale, raising the bar for robustness. Stanford’s AI Index reports that Waymo provides over 150,000 autonomous rides each week. (Stanford HAI)
Cosmos Reason 2 is aimed at this environment: more edge cases, less tolerance for brittle perception, and a stronger need to explain what the system “thought” before acting.
What Cosmos Reason 2 Is
Cosmos-Reason2 is described in NVIDIA documentation as:
Open and customizable
A reasoning VLM for physical AI and robotics
A model that understands space, time, and fundamental physics
A planning model that can reason about steps an embodied agent might take next (NVIDIA Docs)
Key capabilities called out by NVIDIA include:
Enhanced spatiotemporal reasoning with improved timestamp precision
Object detection with 2D/3D point localization and bounding-box coordinates, plus labels and reasoning explanations
Improved long-context understanding up to 256K input tokens (NVIDIA Docs)
Model family and access
NVIDIA’s Cosmos-Reason2 repository states the release (December 19, 2025) and identifies two model sizes:
Cosmos-Reason2-2B
Cosmos-Reason2-8B (GitHub)
NVIDIA’s model listing highlights cosmos-reason2-8b for “structured reasoning on videos or images,” and notes that reasoning can be enabled via a prompt format. (NVIDIA NIM APIs)
“Open” in practice
NVIDIA’s newsroom announcement frames Cosmos Reason 2 as part of a set of new open models available on Hugging Face. (NVIDIA Newsroom)
The GitHub repository shows an Apache-2.0 license for the repo itself (documentation and utilities), so you should still verify the model weights’ specific license terms where you download them. (GitHub)
Diagram: How Reason 2 powers “see → reason → act” loops
Step-by-Step Walkthrough
Step 1: Define the agent’s job in “physical” terms
Write requirements as observable constraints, not just natural-language goals:
Scene understanding requirements: objects, poses, distances, trajectories
Temporal requirements: when an event starts/ends, ordering, duration
Safety requirements: minimum distance, no-go zones, speed limits
Action requirements: allowed actions, prohibited actions, fallback behaviors
Logging requirements: what explanations must be stored for audits
This directly maps to Cosmos Reason 2 features like timestamp precision, 2D/3D localization, and explanation-friendly outputs. (NVIDIA Docs)
Step 2: Choose input modality and context budget
Cosmos Reason 2 is positioned for both images and video, and NVIDIA documentation highlights long-context support up to 256K tokens. (NVIDIA Docs)
Practical implications:
Use short clips for fast control loops
Use longer clips for incident analysis, safety review, and training data mining
Use the long context budget to pack: timestamps, calibration, map hints, task rules, and prior observations
Step 3: Standardize outputs as machine-consumable “action artifacts”
Treat model outputs as structured artifacts that downstream components can verify:
Detections: bounding boxes, 2D points, 3D points
State: object velocities, “moving/stationary,” predicted interactions
Constraints: “do not proceed,” “yield,” “keep distance”
Plan: next steps in a bounded action space
Rationale: short explanation designed for logs and debugging
This aligns with NVIDIA’s emphasis on object detection with 2D/3D localization and reasoning explanations. (NVIDIA Docs)
Step 4: Add a simulation gate before real actuation
For physical systems, “acting” should usually be mediated by a verification step:
Run the candidate plan in simulation (fast approximate or high-fidelity)
Reject if it violates constraints or produces unstable outcomes
Record counterexamples as training and evaluation data
NVIDIA’s ecosystem explicitly references Isaac Sim and Omniverse-based workflows for robotics development and validation. (NVIDIA)
Step 5: Close the loop with data curation
Use Reason 2 to improve the dataset itself:
Filter out ambiguous labels
Identify near-miss scenarios (edge cases)
Auto-generate human review queues with explanations and evidence
This matches Cosmos’ stated role in robot learning pipelines, where Reason is used to reason and filter synthetic data. (NVIDIA)
Code / JSON Snippets
Minimal prompt pattern for “physical reasoning outputs”
Keep outputs short, structured, and verifiable.
Task: You are a physical-world reasoning assistant.
Input: video frames with timestamps and camera calibration metadata.
Output format:
- detections: list of {label, bbox_xyxy, point2d_xy, point3d_xyz_m, confidence}
- scene_state: key physical facts (motion, distances, occlusions)
- constraints: safety and feasibility constraints
- plan: next actions in the allowed action set
- rationale: brief explanation tied to evid
This mirrors NVIDIA’s published feature set around spatiotemporal reasoning, localization, and explanations. (NVIDIA Docs)
Sample workflow JSON for an embodied agent loop
This example shows how teams typically operationalize “see → reason → verify → act” with explicit guardrails.
{
  "workflow_name": "physical_ai_reason2_loop",
  "version": "2026-01-08",
  "inputs": {
    "video_clip_uri": "s3://YOUR_BUCKET/robot/run-00042.mp4",
    "camera_calibration_uri": "s3://YOUR_BUCKET/robot/calib/front_cam.json",
    "task": "Navigate to docking station and stop within 0.2m without collisions",
    "allowed_actions": ["STOP", "MOVE_FORWARD", "TURN_LEFT", "TURN_RIGHT", "YIELD"],
    "safety_rules": {
      "min_distance_m": 0.5,
      "max_speed_mps": 0.6,
      "no_go_zones": ["restricted_area_a"]
    }
  },
  "steps": [
    {
      "name": "preprocess",
      "type": "video_to_frames",
      "params": { "fps": 5, "max_frames": 64, "attach_timestamps": true }
    },
    {
      "name": "reasoning",
      "type": "vlm_inference",
      "model": "nvidia/cosmos-reason2-8b",
      "params": {
        "output_schema": "detections+constraints+plan+rationale",
        "max_output_tokens": 800
      }
    },
    {
      "name": "verification",
      "type": "simulation_check",
      "engine": "isaac_sim",
      "params": {
        "simulate_seconds": 3,
        "reject_on_constraint_violation": true
      }
    },
    {
      "name": "actuation",
      "type": "robot_controller",
      "params": {
        "send_action_if_verified": true,
        "fallback_action": "STOP"
      }
    },
    {
      "name": "logging",
      "type": "audit_log",
      "params": {
        "store_frames": true,
        "store_rationale": true,
        "store_constraints": true
      }
    }
  ],
  "outputs": {
    "action": "robot_controller.last_action",
    "evidence_log_uri": "s3://YOUR_BUCKET/robot/logs/run-00042.json"
  }
}
Practical integration note: “reasoning mode” prompts
NVIDIA’s hosted model page indicates that some interfaces enable reasoning behavior through a specific prompt format. If you deploy via a service layer, standardize this behavior at the gateway so application teams do not depend on brittle prompt strings. (NVIDIA NIM APIs)
Use Cases / Scenarios
Robotics: task decomposition and safer autonomy
Pick-and-place with clutter and partial occlusions
Warehouse navigation with humans and dynamic obstacles
Inspection robots that must explain anomalies with visual evidence
Cosmos Reason 2 is positioned as a planning-capable model for embodied decisions, not just captioning. (NVIDIA Docs)
Autonomous vehicles and robotaxis: long-tail edge cases
The value is strongest when:
The scene is unusual (construction, novel signage, unexpected behavior)
Temporal reasoning matters (who moved first, what changed)
You need auditability (why the car yielded, stopped, or re-routed)
NVIDIA’s CES messaging repeatedly emphasizes “physical AI” and reasoning for real-world autonomy; Jensen Huang framed this as a “ChatGPT moment for physical AI.” (Axios)
Video analytics agents: understand, search, and resolve incidents
NVIDIA cites enterprise partners using Cosmos Reason for video analysis workflows, including incident resolution improvements in robotics contexts. (NVIDIA Newsroom)
This is a natural fit for long-context video understanding and explanation-first outputs. (NVIDIA Docs)
Synthetic data pipelines: curate, label, and validate at scale
If synthetic data becomes the dominant source in many pipelines, the bottleneck shifts to:
Scenario coverage
Label correctness
Filtering unrealistic samples
Building evaluation suites that match reality
Cosmos Reason’s “reason and filter synthetic data” positioning directly targets this. (NVIDIA)
For a Cosmos synthetic data overview on C# Corner (useful as a companion read), see the Cosmos Transfer 2.5 explainer. (C# Corner)
Limitations / Considerations
Physical grounding is not physical control. Reason 2 can propose plans, but safe actuation still requires controllers, constraint checkers, and hardware-aware safety layers.
Dataset mismatch persists. A reasoning VLM can reduce labeling and planning friction, but it cannot fully eliminate sim-to-real gaps; you still need real-world validation loops.
Long context increases operational complexity. Large context windows can raise inference cost and latency; adopt tiered inference (fast loop vs. deep review) rather than always-on long context. (NVIDIA Docs)
Licensing and compliance must be explicit. “Open” does not automatically mean “unrestricted.” Verify the model weight license at download time and document allowed uses and redistribution terms. (NVIDIA Docs)
Explanations are not guarantees. Rationales help debugging and audits, but they are not proof. Build verification gates that check geometry, constraints, and safety rules independently.
Fixes
Output is fluent but not actionable
Fix by enforcing a strict output schema and rejecting responses that omit coordinates, timestamps, or allowed-action constraints.
Fix by adding a post-processor that validates bounding boxes, 3D points, and action names against your interface contract. (NVIDIA Docs)
Model misses the “why now” temporal detail
Fix by explicitly requesting event boundaries: “start time, end time, evidence frame indices.”
Fix by limiting clips to the minimum window around the decision, then running a second pass for broader context only if needed. (NVIDIA Docs)
Hallucinated physics constraints
Fix by adding a simulation or rule-based constraint checker as the final arbiter before actuation.
Fix by training a lightweight verifier on your environment’s constraints and using it as a veto layer. (NVIDIA Newsroom)
Data pipeline grows but project stalls
Fix by treating AI-ready data as a first-class product requirement. Gartner’s warning about AI projects failing without AI-ready data should be operationalized into dashboards and exit criteria. (Gartner)
FAQs
1. Is Cosmos Reason 2 the same as a vision-language-action model?
No. Cosmos Reason 2 is a reasoning VLM. NVIDIA separately describes Isaac GR00T as a reasoning vision-language-action (VLA) model for humanoid robots that uses Cosmos Reason for better reasoning and contextual understanding. (NVIDIA Newsroom)
2. What’s new in Reason 2 compared to earlier Cosmos Reason releases?
NVIDIA documentation highlights improved spatiotemporal understanding and timestamp precision, 2D/3D localization with bounding boxes and labels, and long-context understanding up to 256K input tokens. (NVIDIA Docs)
3. What model sizes are available?
NVIDIA’s repository lists 2B and 8B models released on December 19, 2025. (GitHub)
4. How do teams use Reason 2 in production without risking unsafe actions?
Common patterns:
Use Reason 2 for perception-plus-planning proposals
Run simulation or rule-based verification gates
Use a conservative fallback action (often STOP)
Log evidence and rationale for audits and continuous improvement (NVIDIA Newsroom)
5. Why does NVIDIA emphasize synthetic data alongside Reason 2?
Because physical AI needs enormous scenario diversity, and synthetic generation scales coverage. Gartner’s synthetic-data prediction explains why many teams are shifting strategy, while Cosmos provides world models plus a reasoning model to curate and validate that data. (Gartner)
6. How do I measure whether Cosmos Reason 2 is improving my system?
Adopt metrics that capture physical-world robustness:
Constraint-violation rate in simulation and real runs
Edge-case recall (how often the system catches rare hazards)
Intervention rate and near-miss rate
Explanation quality for audits (completeness and evidence alignment)
For broader “answer engine” visibility and authority measurement ideas (useful if you publish technical docs for retrieval and citation), the GEO measurement concepts are a complementary framework.
References
NVIDIA Newsroom: announcement listing Cosmos Reason 2 as an open reasoning VLM available on Hugging Face. (NVIDIA Newsroom)
NVIDIA Cosmos documentation: Cosmos-Reason2 description and feature list (timestamps, 2D/3D localization, 256K context). (NVIDIA Docs)
NVIDIA Cosmos platform page: positioning of Cosmos Reason within the Cosmos world foundation model stack. (NVIDIA)
NVIDIA Cosmos Reason2 GitHub repository: model family (2B/8B) and release date. (GitHub)
NVIDIA Build model page: cosmos-reason2-8b description and reasoning prompt format note. (NVIDIA NIM APIs)
Gartner press release (Aug 1, 2023): prediction that by 2024, 60% of data for AI will be synthetic (up from 1% in 2021). (Gartner)
Gartner newsroom (Feb 26, 2025): prediction that through 2026, organizations will abandon 60% of AI projects unsupported by AI-ready data. (Gartner)
Stanford HAI AI Index 2025: real-world autonomy scale indicator (Waymo rides per week). (Stanford HAI)
C# Corner (companion Cosmos overview): Cosmos Transfer 2.5 explainer referencing Cosmos Reason as part of Cosmos WFMs. (C# Corner)
Conclusion
Cosmos Reason 2 is NVIDIA’s practical answer to a core physical AI requirement: moving from “seeing” to “understanding and deciding” with explicit spatiotemporal grounding, localization outputs, long-context reasoning, and explanation-friendly artifacts. Its most reliable value emerges when integrated as one component in a verified loop: structured outputs, simulation gates, conservative actuation policies, and continuous data curation. In 2026-era physical AI—where synthetic data scales scenario coverage and real-world deployments demand auditable decisions—Reason 2 is best treated as a reasoning layer that upgrades robustness only when paired with rigorous verification and data discipline.
Join the conversation! Your thoughts help the community grow.