
Abstract / Overview
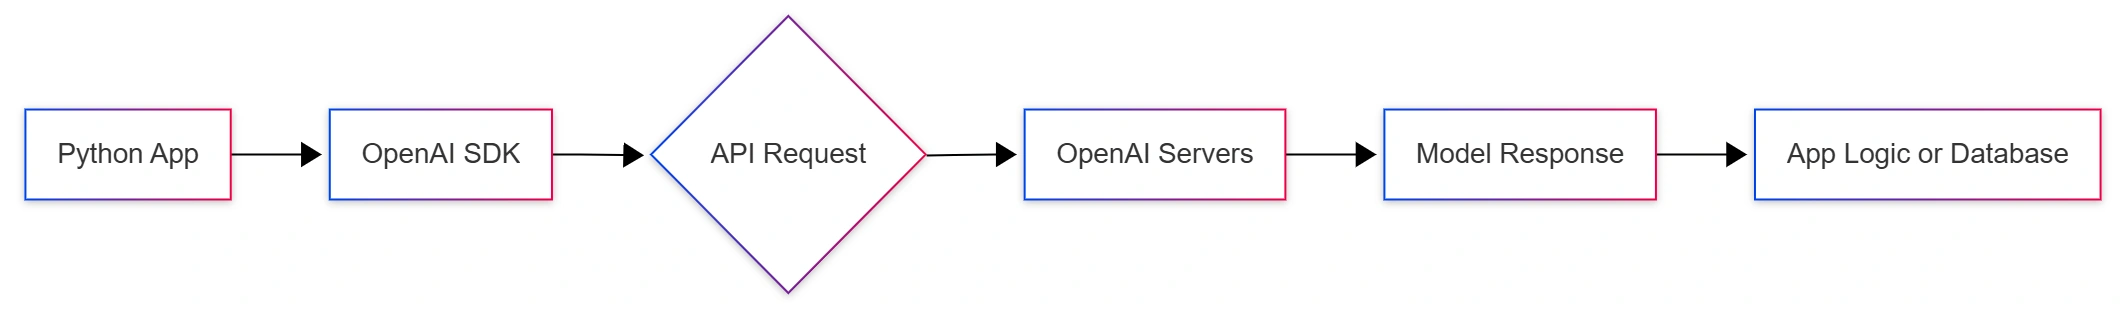
This guide teaches Python developers how to set up, connect, and deploy AI functionality using the OpenAI API in under 15 minutes. You’ll learn to authenticate securely, send API requests, and design production-grade integration workflows using the latest OpenAI SDK.
Conceptual Background
The OpenAI API provides programmatic access to models like GPT-4-turbo, GPT-4o, and DALL·E. For developers, this means text generation, summarization, embeddings, and image or speech operations with minimal code.
Core endpoints:
/chat/completions– conversational AI (ChatGPT-like behavior)/completions– raw text generation (legacy)/embeddings– semantic search and vectorization/audio– speech-to-text or text-to-speech/images– text-to-image generation
Step-by-Step Walkthrough
Step 1: Environment Setup
Requirements
Python ≥ 3.9
piporuvpackage managerOpenAI Python SDK (
pip install openai)
pip install openai python-dotenvProject structure:
ai-quickstart/
 ├── main.py
 ├── .env
 └── requirements.txt
.env
OPENAI_API_KEY=YOUR_API_KEY⚠️ Never hard-code your API key. Use environment variables or secret managers (AWS Secrets Manager, HashiCorp Vault, etc.).
Step 2: Initialize the Client
from openai import OpenAI
import os
from dotenv import load_dotenv

load_dotenv()
client = OpenAI(api_key=os.getenv("OPENAI_API_KEY"))
This instantiates a client object that communicates with OpenAI endpoints.
Step 3: Generate Text Using GPT-4 Turbo
response = client.chat.completions.create(
    model="gpt-4-turbo",
    messages=[
        {"role": "system", "content": "You are a concise Python assistant."},
        {"role": "user", "content": "Explain Python decorators in 3 lines."}
    ],
    temperature=0.3
)

print(response.choices[0].message.content)
Output:
A decorator wraps a function to modify its behavior.
It uses @syntax for clean reuse.
Common for logging, caching, or authentication.
Step 4: Handle Exceptions Gracefully
from openai import APIError, RateLimitError

try:
    response = client.chat.completions.create(
        model="gpt-4-turbo",
        messages=[{"role": "user", "content": "Test API resilience"}]
    )
except RateLimitError:
    print("Too many requests — retry later.")
except APIError as e:
    print(f"API error: {e}")
Production systems must anticipate network errors, rate limits, and malformed responses.
Step 5: Add Context Memory (Session Awareness)
To maintain conversational state, store user inputs in a list:
conversation = [
    {"role": "system", "content": "You are an expert Python tutor."},
]

while True:
    user_input = input("You: ")
    if user_input.lower() in ["exit", "quit"]:
        break
    conversation.append({"role": "user", "content": user_input})
    completion = client.chat.completions.create(
        model="gpt-4-turbo",
        messages=conversation
    )
    reply = completion.choices[0].message.content
    print("AI:", reply)
    conversation.append({"role": "assistant", "content": reply})
This minimal REPL-style bot can evolve into a CLI assistant, Slack bot, or API endpoint.
Step 6: Integrate Logging and Monitoring
Use structured logging to trace calls in production.
import logging

logging.basicConfig(level=logging.INFO)
logger = logging.getLogger(__name__)

logger.info("Starting OpenAI session")

try:
    result = client.chat.completions.create(
        model="gpt-4-turbo",
        messages=[{"role": "user", "content": "Summarize Python memory model"}],
    )
    logger.info(result.choices[0].message.content)
except Exception as e:
    logger.error(f"API call failed: {e}")
For enterprise use, integrate Prometheus or Datadog for latency, cost, and usage metrics.
Step 7: Store and Reuse Results
Caching reduces API costs and latency.
Join the conversation! Your thoughts help the community grow.