
1. What a Transformer Actually Computes
A decoder-only transformer (the backbone of most LLMs) is a stack of identical blocks. Each block does:
1. LayerNorm/RMSNorm → Multi-Head Self-Attention (MHSA)
For tokens \(x \in \mathbb{R}^{T \times d_{model}}\), project to queries/keys/values:
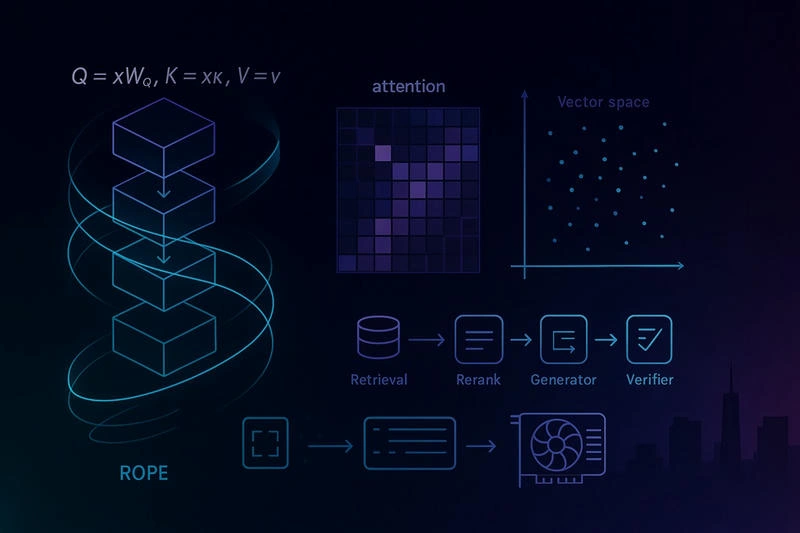
Q = xW_Q, K = xW_K, V = xW_V
Attn(Q,K,V) = softmax( (Q Kᵀ) / √d_h + mask ) V
For each head h (head dim \(d_h = d_{model}/H\)). Heads are concatenated and projected by \(W_O\).
2. Residual connection (pre/post-norm depending on variant).
3. MLP (a gated feed-forward network)
Classic: \( \text{GELU}(xW_1 + b_1)W_2 + b_2 \).
Modern LLMs often use SwiGLU: \(\text{SwiGLU}(x) = ((xW_{up}) \odot \sigma(xW_{gate})) W_{down}\).
4. Positional encoding (where RoPE/ALiBi live; see §5).
Key scaling features
GQA/MQA reduce K/V heads relative to Q heads to shrink memory bandwidth during attention.
FlashAttention computes attention with IO-aware tiling: same math, far less HBM traffic.
KV cache stores \(K, V\) from prior tokens, so generation is \(O(1)\) per new token per layer (vs recomputing history).
2. Weights: What They Encode and How They’re Organized
Weights are the learned parameters of projections (Q/K/V/O), MLP matrices, embed tables, and norm scales. They encode:
Token semantics: via input/output embedding matrices.
Relational structure: via attention projections and the statistics baked into them.
Compositional patterns: via MLPs that model nonlinear feature interactions.
Common choices
Norms: RMSNorm (no learned bias) vs LayerNorm (learned \(\gamma,\beta\)). RMSNorm is simpler and stable at scale.
Weight tying: Share input and output embedding matrices (saves params, improves sample efficiency).
Initialization: Scaled variants (e.g., µP, DeepNet) stabilize very deep stacks.
MoE (Mixture-of-Experts): Sparse activation routes tokens to a small subset of experts → more parameters without proportional compute.
Practical memory math (float16)
Model weights ≈ \( \text{params} \times 2\) bytes (fp16) or 1 byte (int8) after quantization.
KV cache per token ≈ \(2 \times L \times H \times d_h \times \text{bytes}\). Example: \(L=48, H=32, d_h=128\), bf16 (2 bytes) → about 786 kB per token; at 8k context that’s ~6.3 GB just for KV per batch element.
3. Embeddings: From Tokens to Geometry
Token embeddings map discrete IDs to vectors \(e_t \in \mathbb{R}^{d}\). Positional embeddings inject order (see §5). Output embeddings (tied) convert hidden states back to vocabulary logits.
Semantic embeddings (for search/RAG) map arbitrary text to vectors where cosine/dot distance correlates with semantic similarity. They are trained with contrastive/ranking losses (positive pairs close, negatives far).
Vector geometry & similarity
Cosine (angles) is scale-invariant; normalize vectors to unit length when using cosine.
Dot product benefits from learned norms but is sensitive to scale.
L2 is less common for language but fine for certain setups.
Dimensionality trade-offs:
Low-dim (e.g., 256–512): cheaper, faster ANN; risk of lost nuance.
Mid (768–1024): good general default.
High (1536–3072): better headroom for multilingual or long passages but heavier memory/index cost.
4. Vectors in Systems: Indexing, Search, and Reranking
Chunking: 256–800 tokens typical. Aim for semantic boundaries (paragraphs/sections). Maintain overlap (e.g., 20–30%) to handle query drift across chunk edges.
Indexing algorithms (ANN)
HNSW (graph-based): strong recall/latency; tune M and efSearch (higher = better recall, slower).
IVF-PQ/OPQ (inverted file + product quantization): smaller memory; add recheck on a small candidate set to reduce PQ error.
DiskANN/SCaNN: optimized for SSD or fast recall on large corpora.
Hybrid search: BM25 (lexical) + dense cosine often beats either alone; use late fusion (reciprocal rank fusion) or learned fusion.
Reranking: Use a cross-encoder (bi-directional attention over [query, candidate]) on top-k ANN results for precision@k. It’s the single highest-ROI step in many RAG stacks.
Evaluation: report Recall@k, MRR, nDCG, and Answer faithfulness when generation is involved. Track coverage (how often gold can be retrieved) to separate retriever from generator errors.
5. Positional Representations and Long Context
Absolute learned: simple, but hard to extrapolate beyond train window.
ALiBi: head-specific linear biases encourage monotonic decay over distance.
RoPE (rotary): rotates Q/K in complex space by position-dependent angles; enables efficient relative encoding: \(\text{RoPE}(q_i) = R(\theta_i)q_i,\ \text{RoPE}(k_j) = R(\theta_j)k_j\). Dot products then depend on relative positions \(i-j\).
Extending context
NTK-aware RoPE scaling / YaRN / PI stretch frequencies to larger windows with minimal retrain.
Segmented attention and ring-attention reduce quadratic cost but require careful engineering.
Memory tokens and state compression attempt to carry long-range info without full attention.
6. Training: Objectives and Signals
Pretraining (causal LM): maximize \( \sum \log p(x_t|x_{<t}) \). Tokenization often BPE/Unigram with special tokens (system, tool, citation).
SFT (Supervised Finetune): align on task format, tool protocols, and refusal behavior.
Preference learning (RLHF/DPO/KTO): optimize for human preferences, safety, calibration.
Tool-augmented training: include function-calling traces; reward tool correctness and citation quality.
Spec-aware training: add process rewards (schema adherence, unit tests pass, contract checks) so the model learns how to produce verifiable outputs, not just fluent text.
Compute budgeting: FLOPs for decoder-only roughly \(6 \times \text{tokens} \times \text{params}\). Data quality dominates once you scale; synthetic data helps if diverse, verified, and de-duplicated.
7. Inference: Latency, Throughput, and Memory
KV cache turns per-token cost into attention over just the new token and stored history. Optimize with paged KV, int8/FP8 KV quant, and grouped-query attention to cut memory BW.
Speculative decoding: Draft model proposes tokens; verifier model confirms—often 1.5–3× speedup when acceptance rate is high.
Batching and continuous batching keep GPUs busy; tune max concurrency vs. tail latency.
Pipeline parallel + tensor parallel for very large models; balance with activation checkpointing if memory-bound.
8. Quantization & Distillation (What Works Today)
· Weight-only quantization:
- INT8 (LLM.int8): safe default with minimal quality loss.
- NF4/INT4 (QLoRA/AWQ/GPTQ): 4-bit weights; add per-channel scales for stability.
KV cache quantization: often INT8 safe; INT4 is model- and task-dependent.
Activation quantization: harder; needs calibration (SmoothQuant/AWQ).
Distillation: smaller student trained on teacher traces; pair with task-specific data for best transfer.
9. Retrieval-Augmented Generation (RAG) That Holds Up
A robust RAG loop is a contract between retriever and generator:
5. Query planning (optionally multi-hop).
6. Retriever (hybrid dense+lexical), filters, and reranker.
7. Grounding: pass citations/snippets; require attribution.
8. Generator constrained to cite; verifier checks claims against sources.
9. Feedback: failure cases become hard negatives for retriever and counter-examples for the generator.
Common pitfalls: over-chunking, no reranker, mixing vector spaces (don’t index cosine-normalized vectors and then use dot without renorm), ignoring temporal freshness in embeddings.
10. Security, Safety, and Governance
Prompt injection & tool abuse: validate/escape untrusted text; whitelist functions; inspect tool arguments.
Data leakage: embeddings can leak if vectors are reversible; protect with encryption at rest, tenant isolation, and careful logging redaction.
PII & compliance: schema-level redaction + policy checks at both retrieval and generation time.
Calibration & uncertainty gates: block low-confidence autonomous actions; escalate with reasons.
11. Practical Tuning Playbook
Start with RMSNorm + RoPE + SwiGLU + GQA + FlashAttention.
Tie embeddings; use bfloat16 for stability.
Profile HBM bandwidth; if bound, prioritize KV quant, GQA, and FlashAttention before chasing more FLOPs.
For RAG, always add a cross-encoder reranker; it’s cheap leverage.
Track per-request cost, P90 latency, and pass@k together; optimize the bottleneck, not just one metric.
12. Mental Models for Builders
Transformers are feature routers. Attention routes which features interact; MLPs synthesize them.
Weights store priors; vectors navigate them. Pretraining builds a cognitive map; embeddings are your coordinates.
Throughput is a memory problem. Most production slowness is bandwidth/KV cache, not FLOPs.
Verification beats clever prompting. Schema checks, tests, and reranking move accuracy more than “better wording.”
Scale smartly. A smaller model with RAG, reranking, and verification often outperforms a larger, unguided one for enterprise tasks.
Conclusion
Transformers give us a programmable bias for compositional reasoning; weights encode the priors; embeddings turn knowledge into geometry; vector indexes make it searchable at scale. Shipping systems means balancing all four: efficient attention and KV memory, disciplined vector pipelines (indexing + reranking), quantization that preserves quality, and verification that converts plausible text into contract-satisfying outcomes. Build with those constraints in mind and you’ll get models that are not just impressive—but reliable, fast, and cost-effective in the real world.
Join the conversation! Your thoughts help the community grow.