
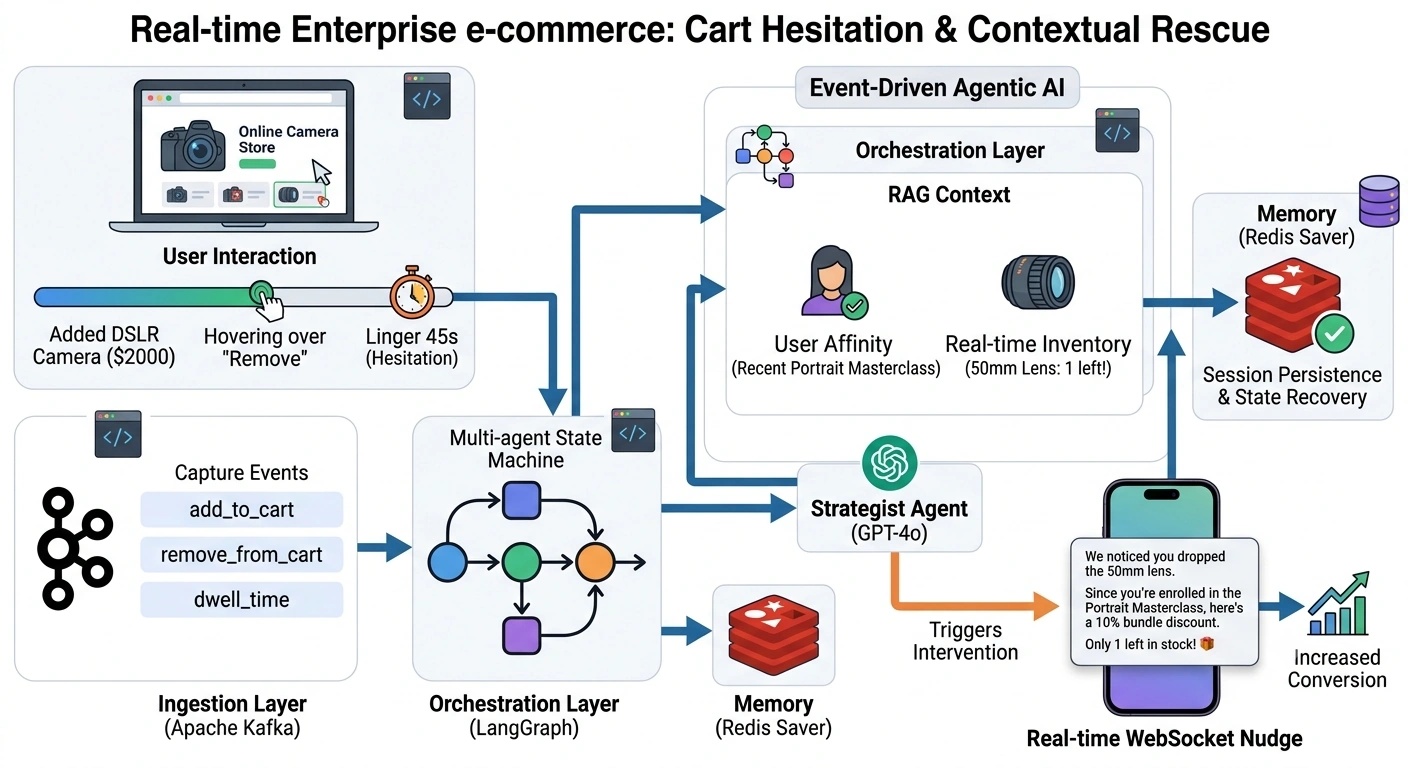
In modern enterprise e-commerce, batch processing is a relic. When a user adds a $2,000 camera to their cart, hovers over the "remove" button, and abandons the session, waiting 24 hours for a batch email is a lost sale. Real-time intervention requires sub-second latency, deep contextual awareness, and hyper-personalization.
This article provides an end-to-end architectural guide and code implementation for building a High-Throughput, Event-Driven Multi-Agent System using Apache Kafka, LangGraph, RAG (Retrieval-Augmented Generation), and Redis-backed State Memory.
The Architecture: Event-Driven Agentic AI
To handle millions of events per second while invoking LLMs and Vector DBs, we must decouple ingestion from processing.
Ingestion Layer (Kafka): Captures raw user behavior (clicks, cart adds, dwell time) via high-throughput partitioned topics.
Orchestration Layer (LangGraph): An asynchronous, multi-agent state machine. We use a Sequential Pipeline Architecture rather than a looping ReAct agent to guarantee deterministic latency bounds required for real-time streams.
Context Layer (RAG): A Vector Database (e.g., Pinecone/Milvus) holding user embeddings, past purchase affinities, and real-time inventory contexts.
Memory Layer (Redis): LangGraph checkpointing via Redis ensures that if a stream processor crashes, the exact state of the user's cart and agent reasoning is recovered without data loss.
The Use Case: "Cart Hesitation & Contextual Rescue"
The Scenario
A user adds a high-end DSLR camera to their cart. They linger on the checkout page for 45 seconds (hesitation), then remove a complementary lens they previously added.
The Agentic Response
Ingestion: Kafka captures the
remove_from_cartand dwell events.RAG: Retrieves the user's history (they recently bought a photography masterclass) and current inventory (the lens is the last one in stock).
Strategist Agent: Recognizes the hesitation and the FOMO (Fear Of Missing Out) trigger.
Action: Pushes a real-time WebSocket nudge:
"We noticed you dropped the 50mm lens. Since you're enrolled in the Portrait Masterclass, here's a 10% bundle discount. Only 1 left in stock!"
End-to-End Implementation (Python)
Prerequisites
pip install aiokafka langgraph langchain-openai langchain-core langgraph-checkpoint-redis pydantic
Step 1: Define the Enterprise State & Memory
We define a strict Pydantic-backed state for LangGraph. This state is passed between agents and persisted in Redis.
import os
import json
import asyncio
from typing import TypedDict, List, Dict, Any, Optional
from pydantic import BaseModel, Field
from langchain_core.messages import BaseMessage, SystemMessage, HumanMessage
from langgraph.graph import StateGraph, END
from langgraph.checkpoint.redis import RedisSaver

# 1. Define the State
class CartEvent(BaseModel):
    event_type: str # e.g., 'add_to_cart', 'remove_from_cart', 'dwell'
    item_id: str
    timestamp: float
    metadata: Dict[str, Any] = {}

class AgentState(TypedDict):
    session_id: str
    user_id: str
    cart_contents: List[str]
    recent_events: List[Dict]
    rag_context: str
    intervention_needed: bool
    final_action_payload: Optional[Dict]
    messages: List[BaseMessage]

# 2. Initialize Redis Checkpointer for Enterprise Fault Tolerance
# In production, use a Redis Cluster connection string
redis_checkpointer = RedisSaver(
    connection_string="redis://localhost:6379/0",
    ttl={"config": 3600} # Expire session state after 1 hour of inactivity
)
Step 2: The RAG Context Retriever
In a real enterprise, this connects to Pinecone/Weaviate. Here, we simulate the async RAG retrieval that fetches user affinity and product urgency.
from langchain_core.prompts import ChatPromptTemplate
from langchain_openai import ChatOpenAI

llm = ChatOpenAI(model="gpt-4o", temperature=0.1)

async def retrieve_rag_context(state: AgentState) -> Dict[str, Any]:
    """Node 1: Fetches contextual embeddings based on cart and user ID."""
    user_id = state["user_id"]
    cart_items = state["cart_contents"]

    # Simulated Vector DB Query (e.g., Pinecone aquery)
    # In reality: vector_store.asimilarity_search(f"User {user_id} cart {cart_items}")
    simulated_rag_data = f"""
    User Profile: Enrolled in 'Portrait Photography Masterclass' 2 weeks ago.
    Price Sensitivity: Medium. Responds well to scarcity and educational bundles.
    Inventory Alert: Item '50mm-f1.8-lens' has only 2 units left in regional warehouse.
    """

    return {"rag_context": simulated_rag_data}
Step 3: The Multi-Agent Nodes
We split the reasoning into specialized nodes. This prevents the "jack-of-all-trades" LLM hallucination problem and allows us to use smaller, faster models for routing and larger models for strategy.
async def analyze_cart_dynamics(state: AgentState) -> Dict[str, Any]:
    """Node 2: Analyzes the sequence of events to detect patterns like hesitation."""
    events = state["recent_events"]

    # Heuristic + LLM hybrid analysis
    dwell_events = [e for e in events if e['event_type'] == 'dwell']
    removals = [e for e in events if e['event_type'] == 'remove_from_cart']

    # If dwell > 30s and recent removal, flag for intervention
    hesitation_detected = len(dwell_events) > 0 and len(removals) > 0

    return {
        "intervention_needed": hesitation_detected,
        "messages": [SystemMessage(content="Cart dynamics analyzed. Hesitation detected." if hesitation_detected else "Normal browsing.")]
    }

async def strategist_agent(state: AgentState) -> Dict[str, Any]:
    """Node 3: The Core LLM Agent that formulates the intervention using RAG."""
    if not state["intervention_needed"]:
        return {"final_action_payload": None}

    prompt = ChatPromptTemplate.from_messages([
        ("system", """You are an elite e-commerce conversion strategist.
        Formulate a real-time JSON intervention payload based on the user's cart dynamics and RAG context.
        Output strictly JSON with keys: 'message' (string, max 15 words), 'discount_code' (string or null), 'urgency_trigger' (string)."""),
        ("human", "User ID: {user_id}\nCart: {cart}\nRecent Events: {events}\nRAG Context: {context}")
    ])

    chain = prompt | llm
    response = await chain.ainvoke({
        "user_id": state["user_id"],
        "cart": state["cart_contents"],
        "events": state["recent_events"],
        "context": state["rag_context"]
    })

    # Parse LLM JSON response (using LangChain output parsers in production)
    import json
    try:
        payload = json.loads(response.content)
    except:
        payload = {"message": "Complete your setup today!", "discount_code": None, "urgency_trigger": None}

    return {"final_action_payload": payload}
Join the conversation! Your thoughts help the community grow.