
Introduction
Tracking changes in data over time is a common problem, and deciding on your approach relies on answering the questions, such as “Do I want to track every field or just some fields?”, “Does it need to be ‘live’ or is it okay to detect changes within a period of time?”, and “What audit fields are available to me and what degree of tracking is needed (e.g. deletions vs. just updates)?”
In this article, I’ll examine four different approaches, diving into some implementation details with an emphasis on contrasting the differences - including performance benchmarking. I’ve made my test harness available on GitHub. Executing this T-SQL script will not only create all necessary objects to demonstrate all four solutions but output the performance numbers I will quote later, so you can check my work!
Motivation and Goals
The type of tracking I’m going to discuss is a general framework that’s largely transparent to applications – in some cases supported by the SQL engine itself. For example, you might have a requirement of: “I’m interested in knowing when any user changes some important data, including who did it, when, and what was the exact change.” The challenge is coming up with a way to apply this to one or more tables, without having your application know or care about the implementation of your auditing.
This is achievable, but some basic requirements apply to all solutions:
- You’ll need to track who last changed records.
- You’ll need to track when records were changed.
This is useful information even if you never keep a history of changes, and it’s common to see the “who” handled through a text field (e.g. LastUpdatedBy), and “when” through a DateTime (or datetime2) field (e.g. LastUpdatedDate). The names of the fields are less important than their function. LastUpdatedBy might be sourced from SUSER_SNAME() – but if you’re using forms authentication, you might prefer to use the application-maintained user ID. LastUpdatedDate might be sourced from GETDATE() or GETUTCDATE(), for example.
Several solutions expose history tables that sit behind an application’s audited tables (which I’ll refer to as base tables). The structure of the history tables might be similar to the base tables - with perhaps a few extra attributes to support auditing. Or we could construct a history tracking system that captures changes in a single log table where we record the table name, field name, old value, new value, etc. The single table approach is something I’ve generally steered away from for a few reasons:
- A “mimic” of the base table means when the business decides they want to track a field that was previously untracked, you may already have it. If you’re only writing out records at a field level, you have no way to “go back in time” to determine what the values were prior to the request to add the field. This may not be a big deal, but it’s a consideration.
- A “mimic” of the base table supports easy point-in-time queries. In this case, you could use such a point-in-time query to restore individual records, if you need to. Constructing a point-in-time picture of the base record using a single change table isn’t impossible (if you have all the necessary data) – but this can be difficult.
- The act of pivoting data, in this case, would make the penalty for logging potentially significantly higher if, for example, we had 10 of 20 fields we wanted to audit on a single table. We might presumably do this in a trigger which needs to perform 10 possible INSERT’s, instead of one that matches the shape of the row. In general, I favor solutions that minimize write penalty to base tables since the reading of history tends to be a rarer need. We can also optimize our history tables by only recording a subset of columns, where that makes sense.
If we accept that use of history tables with one row per version of all base records is a goal, then all four approaches I’ll look at either do that or a close variation.
It’s worth noting that I’ve also created a “pivoting” job that does turn one row per version into one row per field change of interest, based on a configuration table, making some application screens faster where the format matched exactly what users wanted to see. This job didn’t have to maintain real-time changes and didn’t suffer from problem #1 listed above since all fields were available in history tables - it was effectively populating a materialized view.
Another goal here is to educate through a common example that runs through the various implementation options. The sample base table that I’ll be using has the following attributes,
[PersonID] [int] IDENTITY(1,1) NOT NULL PRIMARY KEY,
[FullName] [nvarchar](100) NOT NULL,
[Username] [varchar](100) NOT NULL,
[IsActive] [bit] NOT NULL,
[Birthday] [date] NULL,
[Age]  AS (DATEDIFF(year,[Birthday],GETDATE())),
[LastUpdatedDate] [datetime2](7) NOT NULL,
[LastUpdatedBy] [varchar](50) NOT NULL
Alternative #1 – Roll-your-own Snapshots
You might be interested in change tracking, but what if it’s tracking tables in a third-party system? You may not have the freedom to add triggers or change the schema, so are you stuck? No! One option if you’re willing to accept tracking over an interval is to use a set of T-SQL statements that can most easily be packaged in a stored procedure (per table). Such a procedure can be scheduled to run every few minutes (or hours), depending on your requirements. You’ll only pick up the last change in that interval, determined by comparing the current state in your base table versus the most recent state in your history table, based on a chosen natural key. (In our example, PersonID is our natural key.)
The history table we’ll use looks like the base table but with two additional fields,
[RowExpiryDate] [datetime2](7) NOT NULL,
[IsDeleted] [bit] NOT NULL
In the T-SQL script that I offer here, the stored procedure [History].[up_Track_Proc_Load] is what populates the history table, [History].[Track_Proc]. There’re three basic steps:
- Expire old records (as would happen on updates).
- Insert new/changed records (supporting inserts and updates).
- Flag deleted records.
Starting from an empty base and history table, if we were to run this script,
INSERT dbo.Track_Proc (FullName, Username, IsActive, Birthday, LastUpdatedBy, LastUpdatedDate)
    VALUES ('Bobby Tables', 'bob', 1, '1/1/2000', 'inserter_guy', GETDATE());

EXEC History.up_Track_Proc_Load;

WAITFOR DELAY '00:00:02';

UPDATE dbo.Track_Proc
SET FullName = 'Robert Tables', UserName = 'rob', LastUpdatedBy = 'updater_guy', LastUpdatedDate = GETDATE()
WHERE PersonID = 1;

EXEC History.up_Track_Proc_Load;

WAITFOR DELAY '00:00:02';

UPDATE dbo.Track_Proc
SET UserName = 'robby', LastUpdatedBy = 'updater_guy', LastUpdatedDate = GETDATE()
WHERE PersonID = 1;

EXEC History.up_Track_Proc_Load;

WAITFOR DELAY '00:00:02';

DELETE dbo.Track_Proc
WHERE PersonID = 1;

EXEC History.up_Track_Proc_Load;

SELECT * FROM History.Track_Proc
ORDER BY LastUpdatedDate ASC;
We’d see the following contents in the History.Track_Proc history table,
| PersonID | FullName | Username | IsActive | Birthday | LastUpdatedBy | LastUpdatedDate | RowExpiryDate | IsDeleted |
| 1 | Bobby Tables | bob | True | 1/1/2000 12:00:00 AM | inserter_guy | 8/24/2018 12:44:49 PM | 8/24/2018 12:44:51 PM | False |
| 1 | Robert Tables | rob | True | 1/1/2000 12:00:00 AM | updater_guy | 8/24/2018 12:44:51 PM | 8/24/2018 12:44:53 PM | False |
| 1 | Robert Tables | robby | True | 1/1/2000 12:00:00 AM | updater_guy | 8/24/2018 12:44:53 PM | 8/24/2018 12:44:55 PM | False |
| 1 | Robert Tables | robby | True | 1/1/2000 12:00:00 AM | updater_guy | 8/24/2018 12:44:55 PM | 1/1/3000 12:00:00 AM | True |
Of note, we can use LastUpdatedDate and RowExpiryDate to box off time windows for when a given state was valid in the base table. The GitHub script includes examples of creating views that can present back individual field-level changes – search for “_Changes” in the script to see how this can be done.
What if our base table is missing LastUpdatedDate and By fields? We can still track changes - but with more limitations. In my example script, search for “NoAudit” to find an implementation where I remove LastUpdatedBy and Date, so limitations necessarily include:
- We can’t tell who made changes at all, just what the changes were. As you can tell from the above result set, we can’t determine who the “delete user” is, regardless of having a LastUpdatedBy field or not.
- We can’t tell exactly when the last change was made for a given natural key value – just that some net change happened as of the run date of the procedure.
Scheduling running our load procedure is easy with SQL Agent (or the scheduler of your choice), and the load process itself is rather efficient, although we could do more such as using partitioning based on say “year” of our LastUpdatedDate. (This would offer a way to more easily archive “old” history.)
Alternative #2 – Triggers
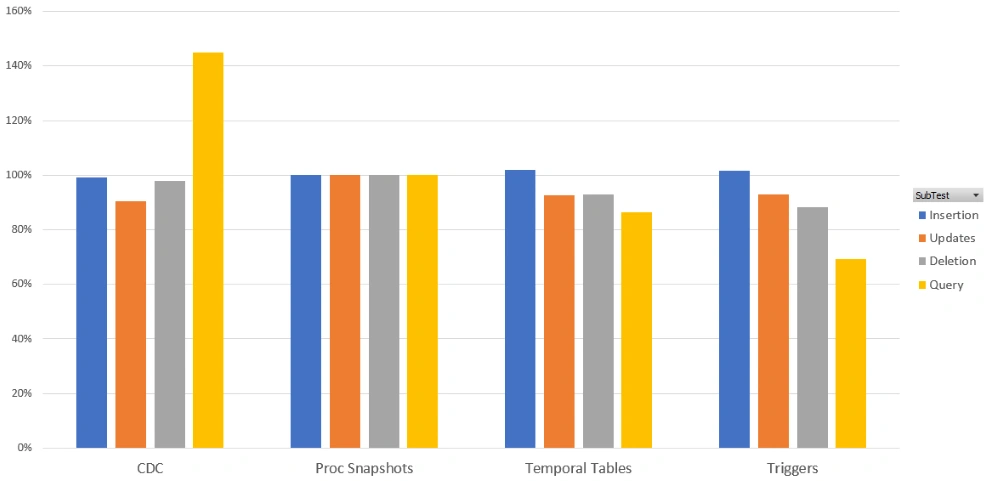
If we’re willing to use triggers on base tables, we can get the benefit of tracking all changes, not just net changes over a time interval. I’ve used this approach before, back in the “old days” with a version of triggers that populated a history table almost identical to what I show above for snapshot-based tracking. However, I decided over time I could improve performance by eliminating the persisted RowExpiryDate and instead generate a view that presents historical data in the same format. This allowed me to eliminate a trigger - down to only an AFTER UPDATE and FOR DELETE trigger. With this new format, the current record is not maintained in the history table – it’s only moved there on UPDATE or DELETE. What it does is make the query of historical data more complex – but in testing, as I’ll show later, it’s still the absolute winner among all approaches for query performance in a specific test case (and likely in general).
Ankur MistryPosted Sep 1, 2018, 3:58 AM
Good one thanks for sharing
Sarathlal SaseendranPosted Aug 29, 2018, 9:56 AM
Good Information. Thanks for the article.