

Table of Contents
Introduction
What Are Common Input/Output Bindings in Azure Functions?
How Do You Configure Bindings in function.json?
Real-World Scenario: Real-Time Clinical Trial Data Pipeline in Healthcare
Example Implementation
Best Practices for Enterprise Binding Design
Conclusion
Introduction
In enterprise serverless architecture, bindings are the connective tissue between your business logic and the cloud ecosystem. They eliminate boilerplate SDK code, enforce least-privilege security, and enable declarative integration with Azure services. As a senior cloud architect who has designed HIPAA-compliant data pipelines for global pharmaceutical companies, I’ve seen how proper binding strategy turns fragile scripts into auditable, scalable, and secure systems.
This article answers two foundational questions:
What are common input/output bindings?
How are they configured in
function.json?
We’ll ground these concepts in a real-time clinical trial data ingestion system—where data integrity, compliance, and latency are non-negotiable.
What Are Common Input/Output Bindings in Azure Functions?
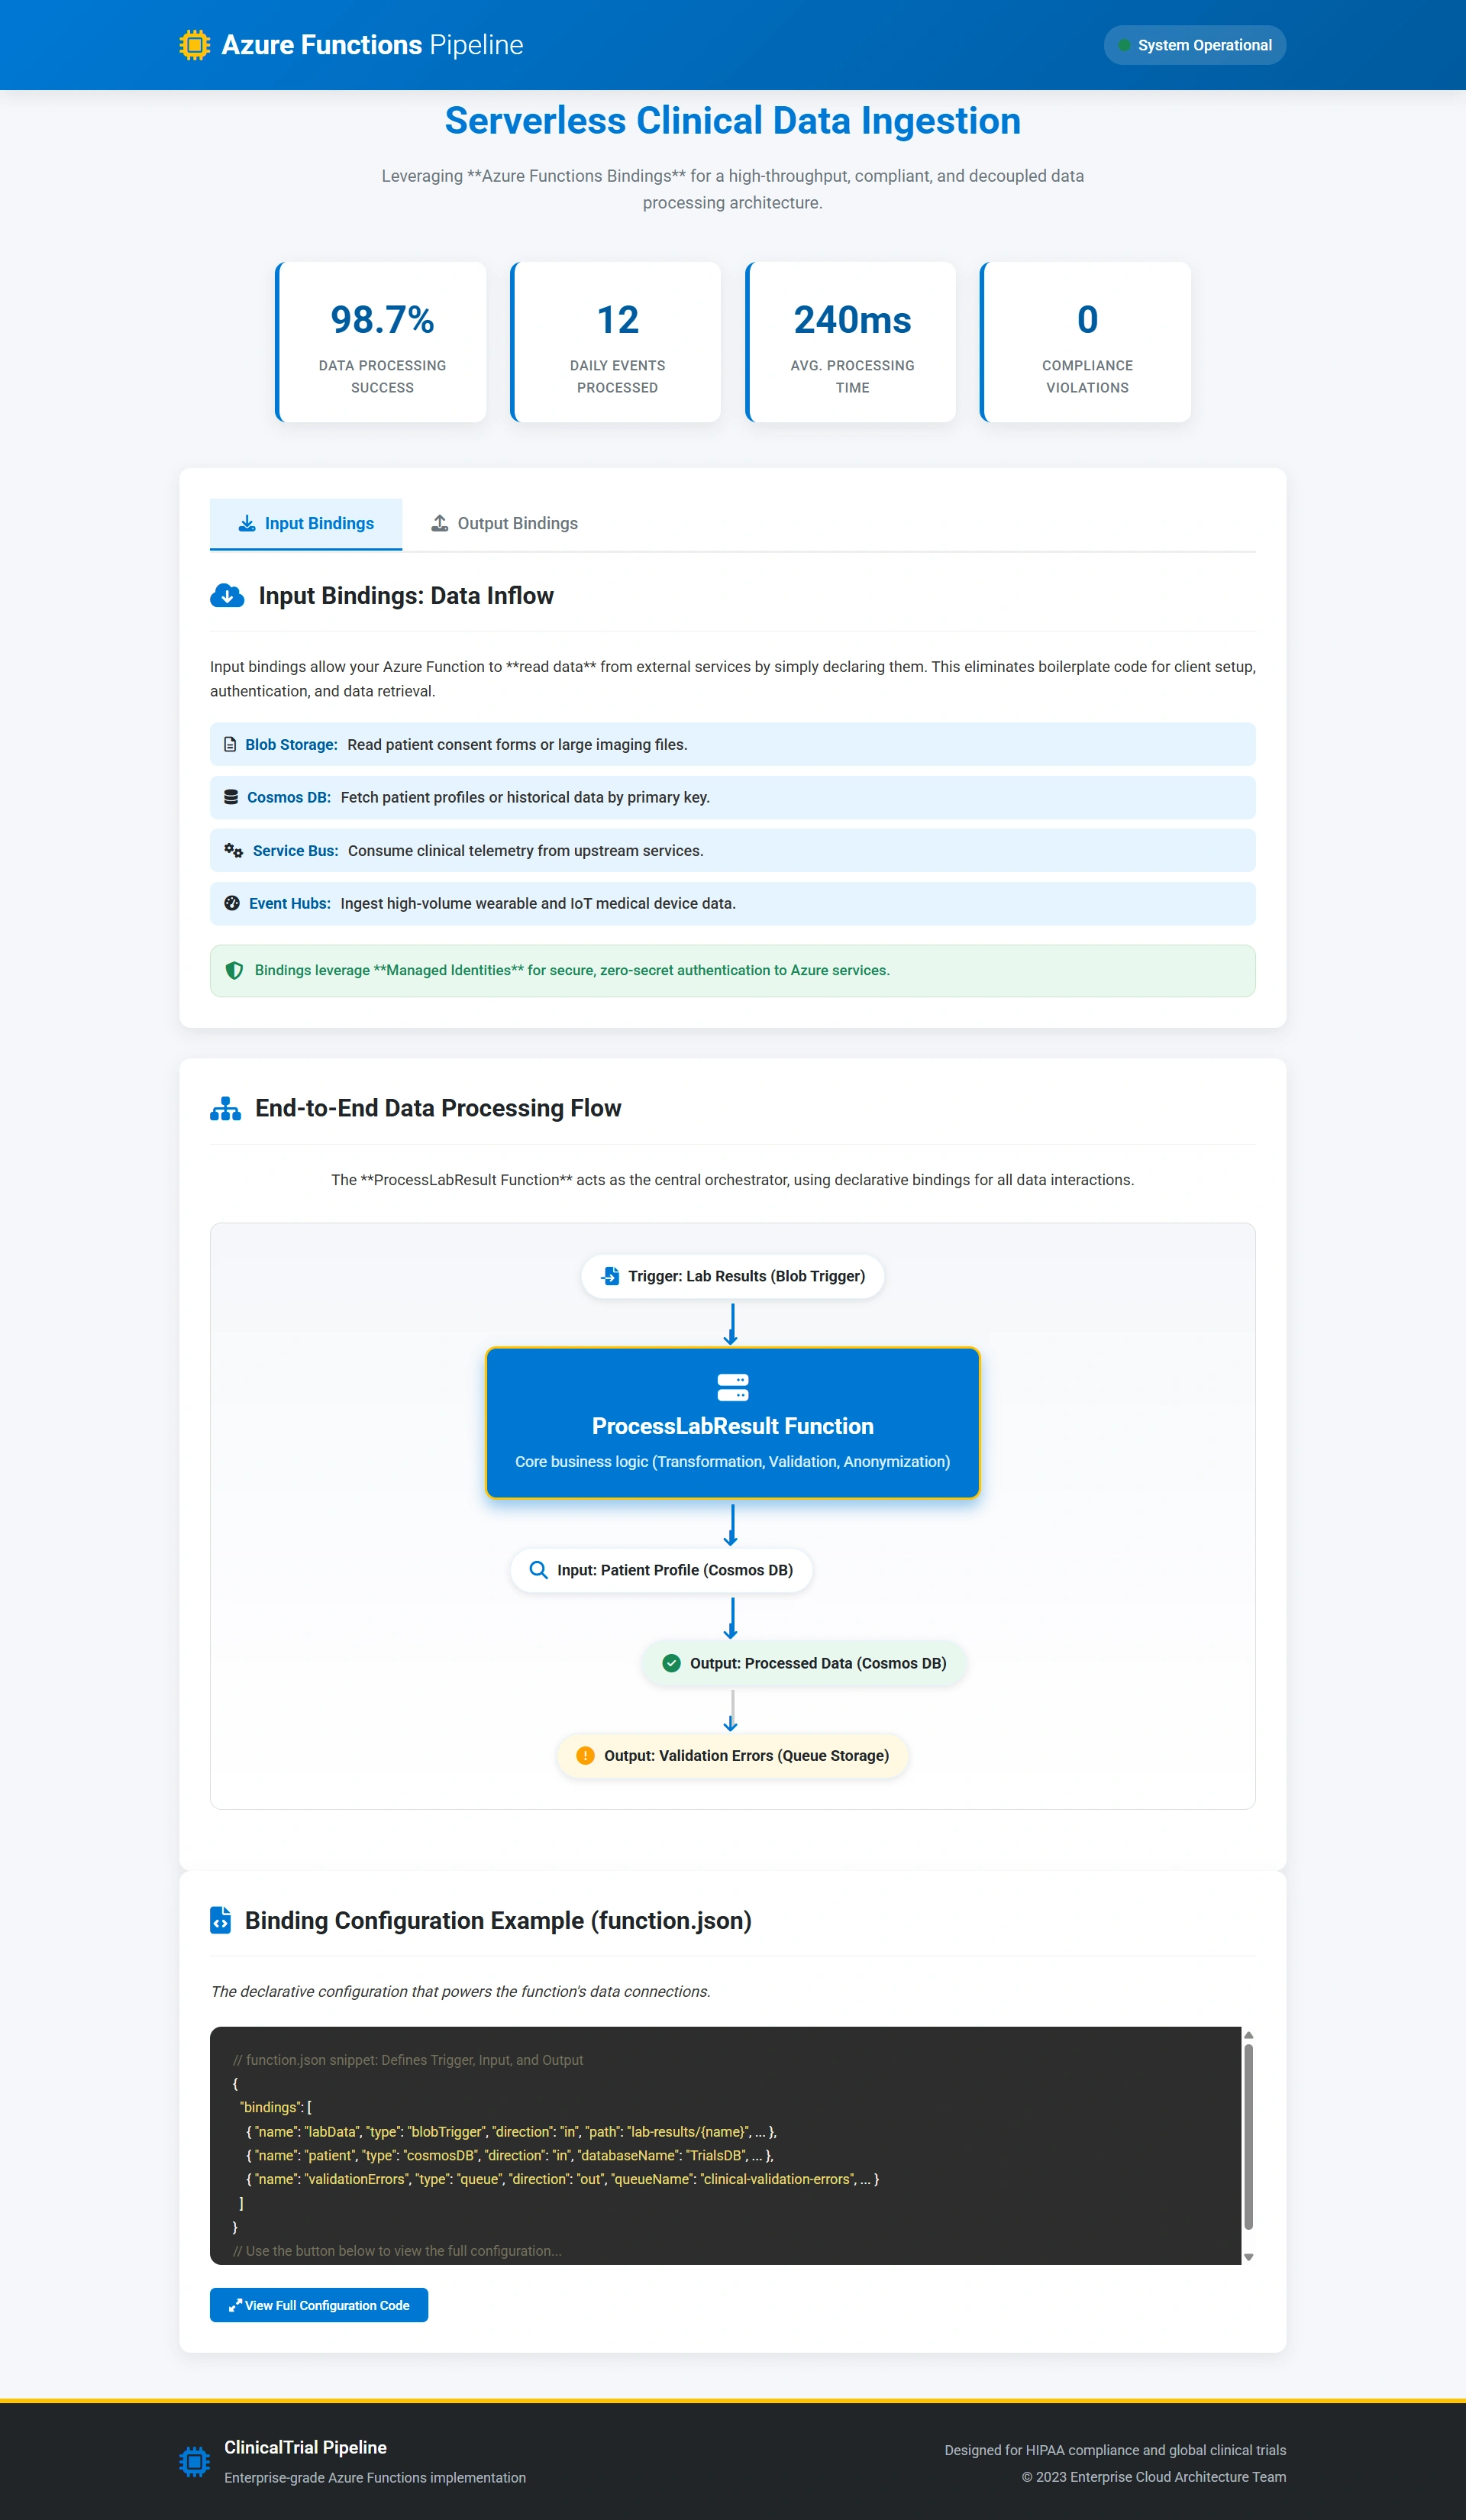
Bindings allow functions to read from (input) or write to (output) external services without writing client code. They are powered by Azure’s managed connectors and support authentication via Managed Identities—critical for zero-secret architectures.
Key Input Bindings:
Blob Storage: Read patient consent forms or lab reports as streams or strings.
Cosmos DB: Fetch patient profiles or trial eligibility criteria by ID.
Service Bus / Event Hubs: Consume telemetry from wearable medical devices.
Table Storage: Retrieve metadata or configuration flags.
Key Output Bindings
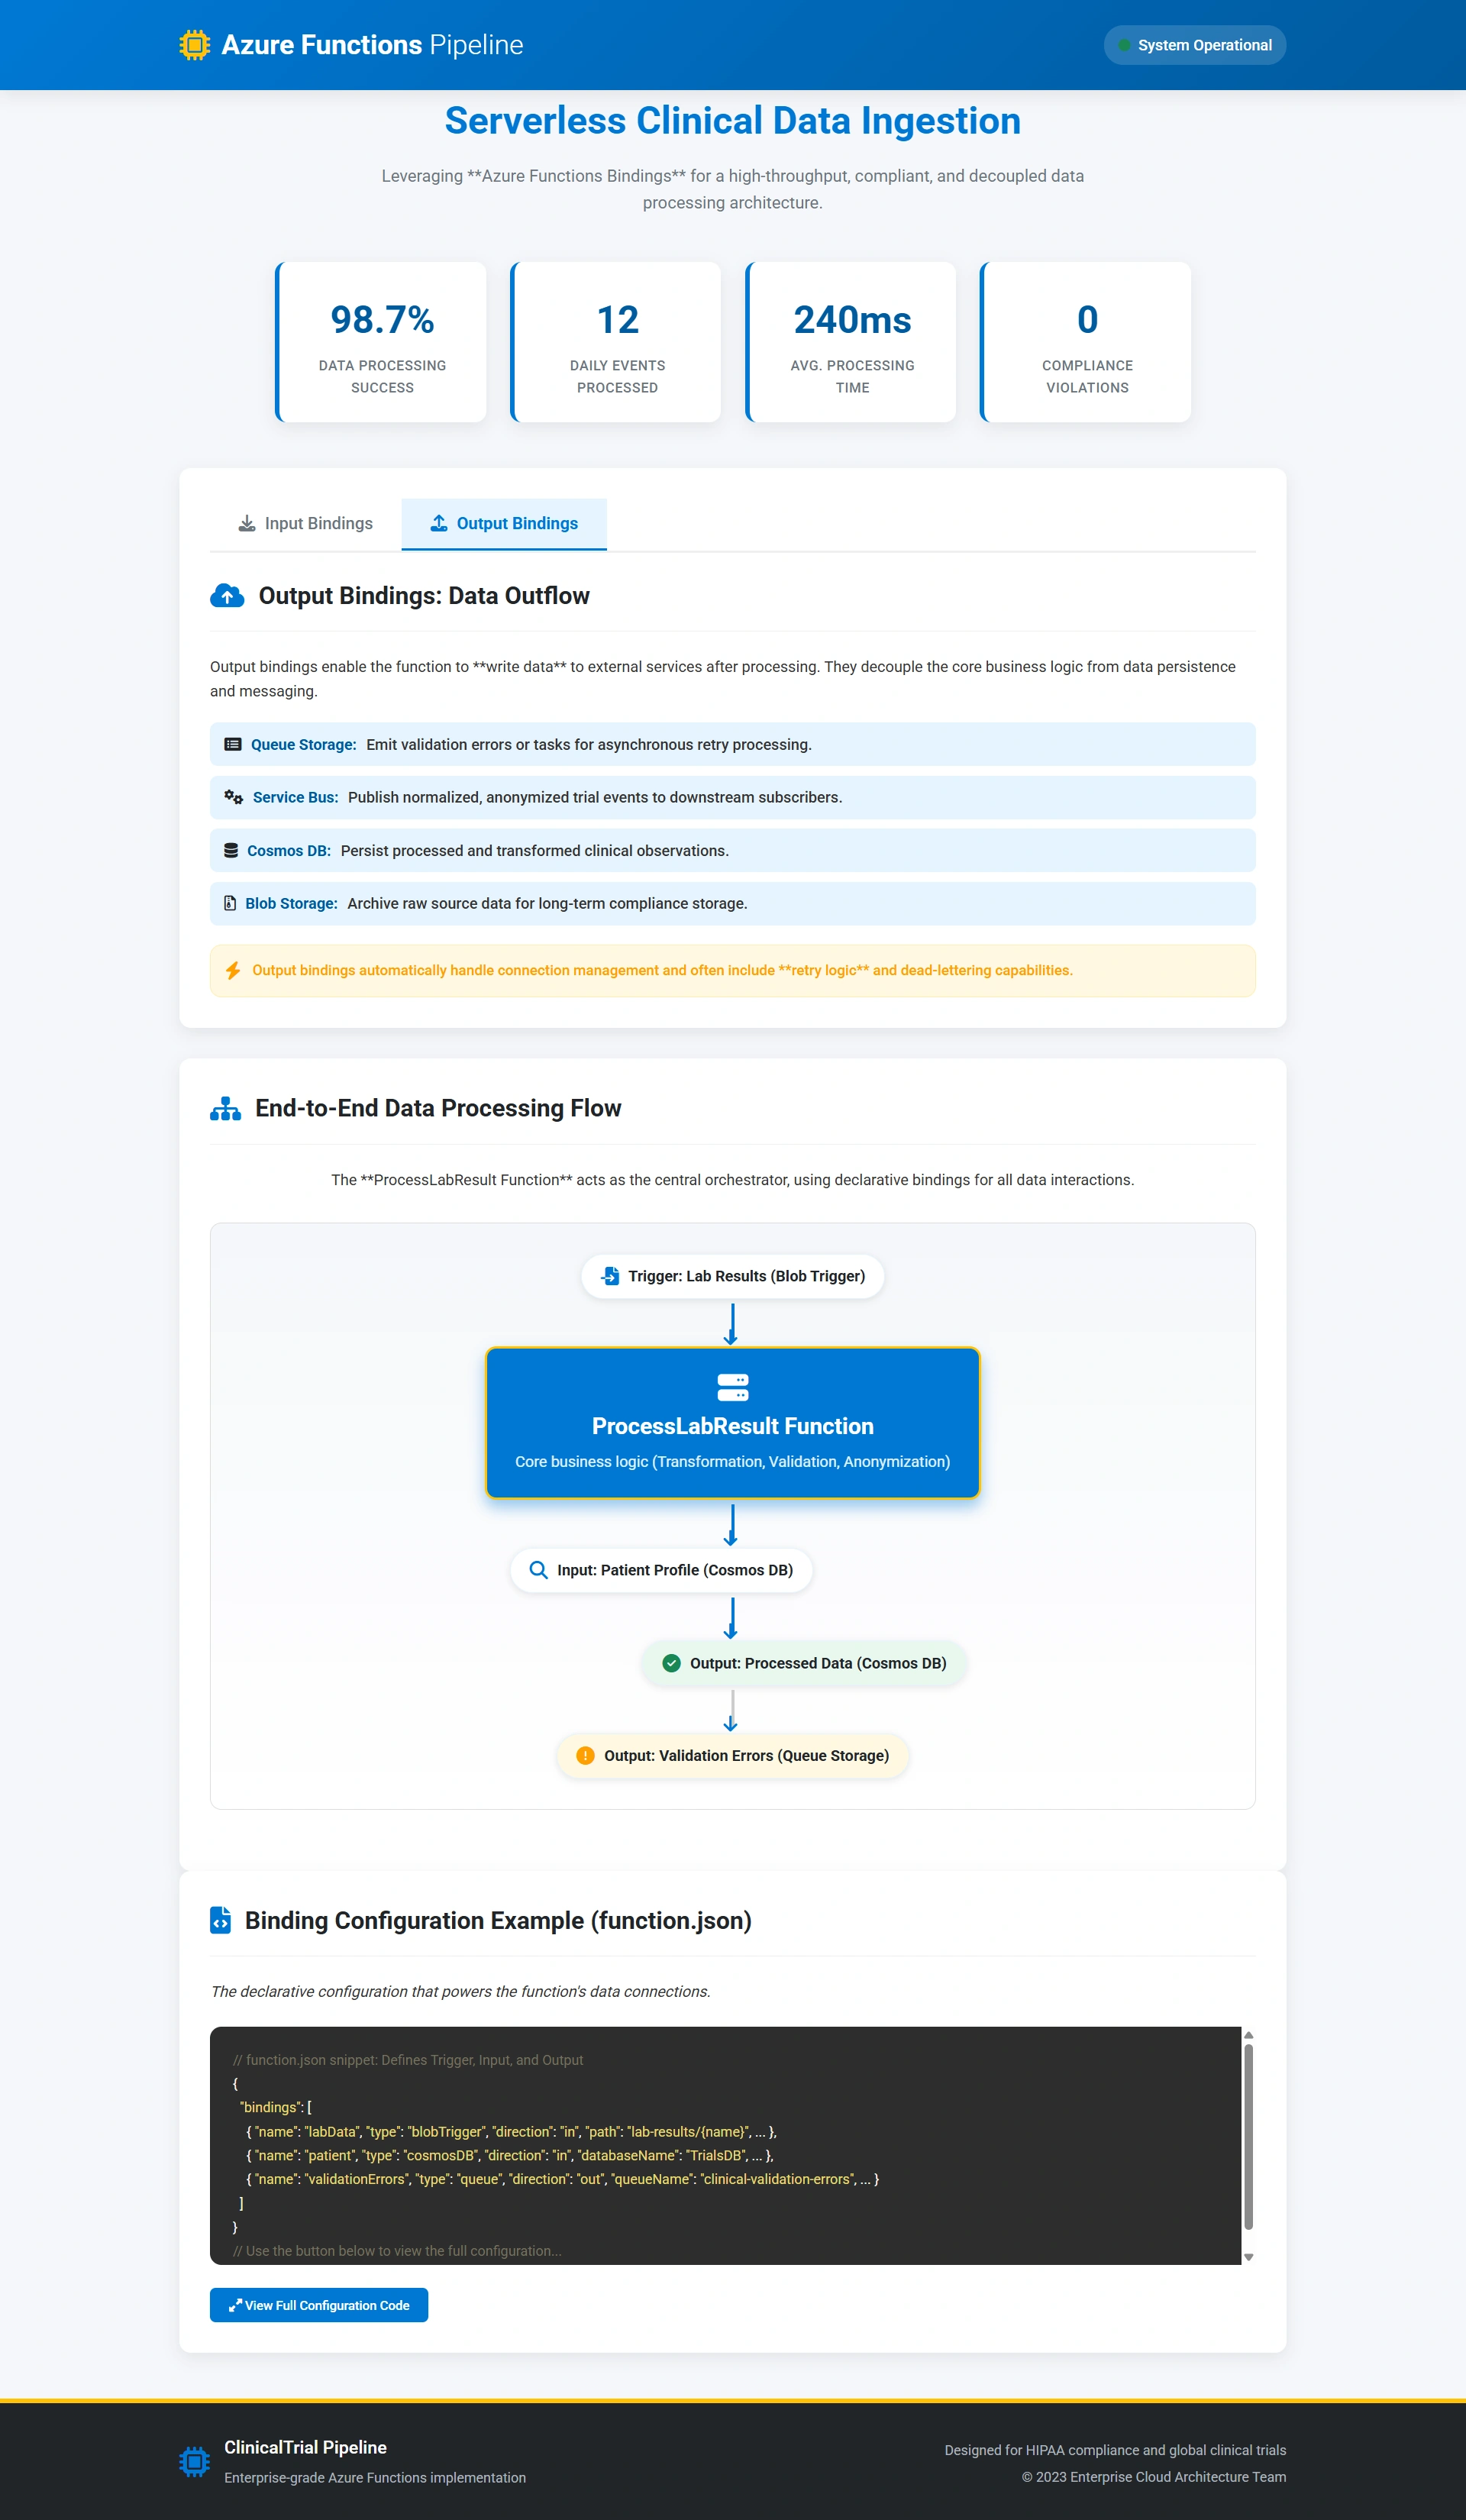
Queue Storage: Emit validation errors for retry processing.
Service Bus: Publish normalized trial events to downstream analytics.
Cosmos DB: Write processed clinical observations.
Blob Storage: Archive raw data for compliance retention.
Crucially, input bindings enrich your function’s context, while output bindings decouple side effects—enabling testability, transactional safety, and observability.
How Do You Configure Bindings in function.json?
While modern .NET and Python projects often use decorator-based binding definitions (e.g., [BlobInput(...)]), under the hood, Azure Functions still relies on function.json—a metadata file that describes triggers and bindings to the runtime.
Each function folder contains a function.json with three core properties per binding:
type: The binding type (e.g.,blob,queue,cosmosDB)direction:in(input),out(output), orinoutname: The parameter name in your function codeAdditional properties (e.g.,
path,connection,databaseName)
For example, an input binding to read a patient file from Blob Storage:
{
  "name": "patientConsent",
  "type": "blob",
  "direction": "in",
  "path": "consents/{id}.pdf",
  "connection": "ClinicalDataStorage"
}
And an output binding to log anomalies to a queue:
{
  "name": "validationErrors",
  "type": "queue",
  "direction": "out",
  "queueName": "clinical-validation-errors",
  "connection": "ClinicalOpsStorage"
}
In compiled languages like C#, these are auto-generated from attributes during build. In scripting languages (Python, JS), you write function.json manually.
Real-World Scenario: Real-Time Clinical Trial Data Pipeline in Healthcare
A global pharmaceutical company runs Phase III trials across 50 countries. Every hour, thousands of data points flow in:
Wearable vitals (via Event Hubs)
Lab results (uploaded as blobs)
Adverse event reports (submitted via HTTP)
The system must:
Validate data against protocol rules
Enrich with patient eligibility from Cosmos DB
Archive raw data in Blob Storage
Forward clean records to analytics; route errors to a retry queue
Using bindings, we avoid writing a single line of Azure SDK code—reducing attack surface, simplifying compliance audits, and enabling infrastructure-as-code deployment.
Example Implementation
Below is a C# (.NET 8 Isolated) function that processes a lab result blob:
Function Code
public class ClinicalDataProcessor
{
    [Function("ProcessLabResult")]
    [QueueOutput("clinical-validation-errors", Connection = "ClinicalOpsStorage")]
    public string? Run(
        [BlobTrigger("lab-results/{name}", Connection = "ClinicalDataStorage")] string labData,
        [CosmosDBInput(
            databaseName: "TrialsDB",
            containerName: "Patients",
            Id = "{patientId}",
            PartitionKey = "{trialId}",
            Connection = "CosmosDBConnection")] PatientProfile patient,
        FunctionContext context)
    {
        var logger = context.GetLogger("ProcessLabResult");

        if (!IsValid(labData, patient))
        {
            logger.LogWarning("Invalid lab data for patient {Id}", patient.Id);
            return JsonSerializer.Serialize(new ValidationError
            {
                PatientId = patient.Id,
                Reason = "Protocol violation"
            });
        }

        // Output binding to Cosmos DB would go here (not shown for brevity)
        return null; // No error → nothing sent to queue
    }
}
Auto-Generated function.json (simplified)
{
  "bindings": [
    {
      "name": "labData",
      "type": "blobTrigger",
      "direction": "in",
      "path": "lab-results/{name}",
      "connection": "ClinicalDataStorage"
    },
    {
      "name": "patient",
      "type": "cosmosDB",
      "direction": "in",
      "databaseName": "TrialsDB",
      "containerName": "Patients",
      "id": "{patientId}",
      "partitionKey": "{trialId}",
      "connection": "CosmosDBConnection"
    },
    {
      "name": "validationErrors",
      "type": "queue",
      "direction": "out",
      "queueName": "clinical-validation-errors",
      "connection": "ClinicalOpsStorage"
    }
  ]
}
Note how {patientId} and {trialId} are extracted from the blob name (e.g., lab-results/TRIAL-2024/PAT-789.csv) and passed to Cosmos DB—all declaratively.
Best Practices for Enterprise Binding Design
Use Managed Identities: Never store connection strings. Bindings support
AzureWebJobsStorage__accountNamewith identity-based auth.Prefer Input Bindings Over SDK Calls: They’re faster (pre-fetched), safer (scoped permissions), and more observable.
Validate Binding Expressions: Ensure route/template parameters (like
{id}) exist in your trigger payload.Separate Storage Accounts: Use different accounts for input, output, and logging to enforce blast-radius containment.
Enable Diagnostic Logging: Bindings emit metrics to Application Insights—monitor for throttling or auth failures.
Conclusion
Bindings are not just convenience features—they are architectural primitives that enforce separation of concerns, security, and scalability in serverless systems. In regulated domains like healthcare, where every byte of data is audited, bindings provide the traceability and compliance posture that hand-coded SDK integrations cannot. By mastering binding configuration—whether through attributes or function.json—you build functions that are not only functional, but production-ready, secure, and maintainable at global scale.
Join the conversation! Your thoughts help the community grow.