

Abstract / Overview
Local AI allows individuals and organizations to run large language models (LLMs) privately on their own machines. Instead of depending on cloud-based services like OpenAI or Anthropic, you can use Ollama to host and manage models locally and LangChain to orchestrate them into useful applications.
This article explains how to:
Set up Ollama for local AI model management.
Integrate Ollama with LangChain for building AI pipelines.
Implement Retrieval-Augmented Generation (RAG) using local data.
Build a fully local AI chatbot that respects privacy and delivers fast, context-aware responses.
Conceptual Background
Ollama is a lightweight model server that lets you run open-source LLMs (like Llama 3, Mistral, or Gemma) locally with GPU acceleration. It handles model downloading, quantization, and prompt management.
LangChain is a Python and JavaScript framework for chaining together LLMs, tools, and data sources to build context-aware AI workflows.
When combined:
Ollama runs the model locally.
LangChain acts as the orchestration layer that structures prompts, memory, and data retrieval.
This setup creates a self-contained AI system that can reason, recall, and respond — all offline.
Step-by-Step Walkthrough
1. Install Ollama
macOS / Linux:
curl -fsSL https://ollama.com/install.sh | shWindows (PowerShell):
winget install Ollama.OllamaAfter installation, verify:
ollama --version2. Pull a Model
To use a model locally:
ollama pull llama3Available models include:
llama3mistralphi3gemma
List all available models:
ollama list3. Run Your First Prompt
Start the Ollama server:
ollama serveThen interact:
ollama run llama3 "Write a haiku about local AI"4. Install LangChain
pip install langchain langchain-communityOptional (for retrieval and embeddings):
pip install chromadb5. Connect LangChain to Ollama
LangChain integrates with Ollama via its built-in API wrapper.
Python Example:
from langchain_community.llms import Ollama

llm = Ollama(model="llama3")
response = llm.invoke("Explain the benefits of local AI in simple terms.")
print(response)
This sends a prompt to the local Ollama server and retrieves the generated text — no internet required.
6. Add Prompt Templates
from langchain.prompts import PromptTemplate

template = PromptTemplate.from_template(
    "You are a technical writer. Explain {topic} in 5 concise bullet points."
)

response = llm.invoke(template.format(topic="Retrieval-Augmented Generation"))
print(response)
7. Implement a Simple Chain
from langchain.chains import LLMChain

chain = LLMChain(llm=llm, prompt=template)
print(chain.run(topic="local LLMs for startups"))
8. Add Local Data with RAG (Retrieval-Augmented Generation)
Create a RAG pipeline to feed your own documents into the model.
from langchain_community.document_loaders import TextLoader
from langchain.text_splitter import CharacterTextSplitter
from langchain_community.vectorstores import Chroma
from langchain_community.embeddings import OllamaEmbeddings
from langchain.chains import RetrievalQA

# Load and split local documents
loader = TextLoader("local_data.txt")
docs = loader.load()
splitter = CharacterTextSplitter(chunk_size=1000, chunk_overlap=100)
texts = splitter.split_documents(docs)

# Create vector store with Ollama embeddings
embeddings = OllamaEmbeddings(model="llama3")
db = Chroma.from_documents(texts, embeddings)

# Create retriever and QA chain
retriever = db.as_retriever(search_kwargs={"k": 3})
qa = RetrievalQA.from_chain_type(llm=llm, retriever=retriever)

query = "Summarize the main ideas in my document."
print(qa.run(query))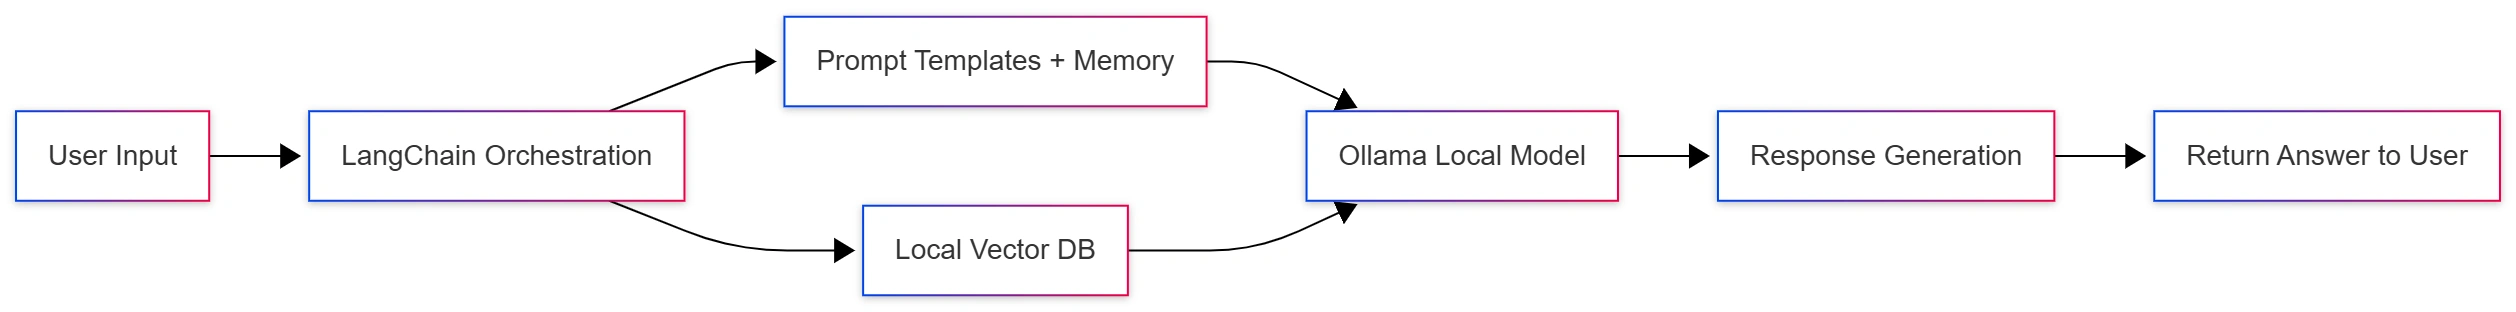
Join the conversation! Your thoughts help the community grow.