
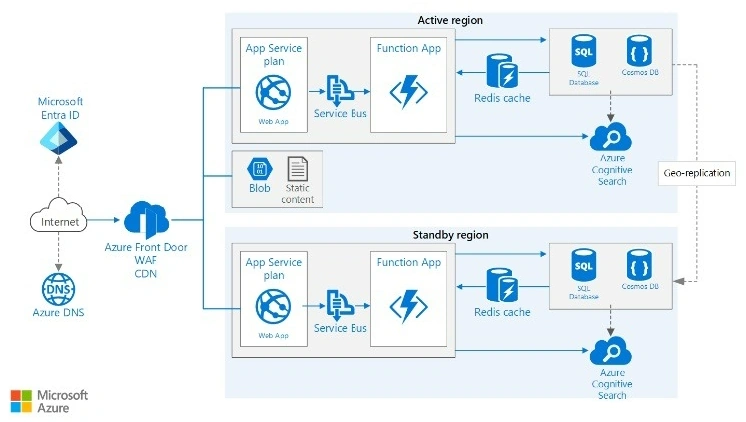
This article aims to create a high-availability application using Microsoft Azure PaaS services, incorporating Cloud Native services whenever feasible. The application relies on caching, authentication, and document databases, with a strong emphasis on scalability and performance.
The Approach
The following high-level approach is recommended for designing a high-availability application using Azure App Service. This platform allows you to develop and host web applications, mobile backends, and RESTful APIs in your preferred programming language without the need to manage the underlying infrastructure. Azure App Service provides features like autoscaling and high availability and supports automated deployments from GitHub, Azure DevOps, or any other Git repository.
Define Availability Requirements
To effectively design and manage high-availability cloud workloads, it is essential to identify their usage patterns and establish relevant availability metrics. Here are the key metrics to consider.
- Percentage of Uptime: This metric measures the amount of time a system or service is operational and available, usually expressed as a percentage of total time. For example, an uptime of 99.9% means the system is down for no more than 8.76 hours per year.
- Mean Time to Recovery (MTTR): This is the average time required to restore a system to normal operation after a failure. It includes the time taken to detect the issue, diagnose the problem, and implement the fix.
- Mean Time Between Failures (MTBF): This metric measures the average time between failures of a system or component. A higher MTBF indicates better reliability and fewer failures over time.
- Recovery Time Objective (RTO): RTO is the maximum acceptable amount of time that a system, application, or function can be down after a failure or disaster occurs. It defines the target time to restore normal operations.
- Recovery Point Objective (RPO): RPO is the maximum acceptable amount of data loss measured in time. It indicates the point in time to which data must be recovered to resume normal operations after a disruption.
Plan your High Availability Architecture
- Identify potential types of failures, their implications, and recovery strategies.
- Ensure systems can fail gracefully and resume operations without service disruption. Isolate critical resources for enhanced reliability.
- Replicate application data across two regions. During normal operations, route network traffic to the primary region. If the primary region becomes unavailable, reroute traffic to the secondary region.
- Ensure data replication supports the redundancy strategy and aligns with the application’s RTO and RPO. The following table details the RPO for all consistency levels of an Azure Cosmos DB account deployed in at least two regions.
Consistency level RPO in case of region outage Session, Consistent Prefix, Eventual < 15 minutes Bounded Staleness K & T Strong 0 - K = The number of "K" versions (i.e., updates) of an item.
- T = The time interval "T" since the last update.
Join the conversation! Your thoughts help the community grow.