
TL;DR:
Resume Microsoft 365 Agents Playground sessions without losing routed context.
Capture router spans with session identifiers, checkpoint usage, and fallback metadata.
Preserve Azure AI Foundry model router policies while meeting Part 5 evaluation gates.
Align session storage improvements with Microsoft Agent Framework checkpoint guidance.
Introduction
Keeping conversational memory inside a single session is what makes GraphRAG answers actionable, because every turn depends on the classifier understanding the history it already routed. The earlier installments supplied those building blocks—routing patterns that coordinate sequential, concurrent, and handoff workflows; evaluation gates that locked in TaskAdherence 80% and IntentResolution 100%; and the Azure AI Foundry model router that selects Balanced, Cost, or Quality modes per request Use model router with Foundry agents. This part (7th) finishes the arc by layering checkpoint-aware session storage on top, letting Microsoft 365 Agents Playground resume the same conversation while the router contract stays intact.
Development
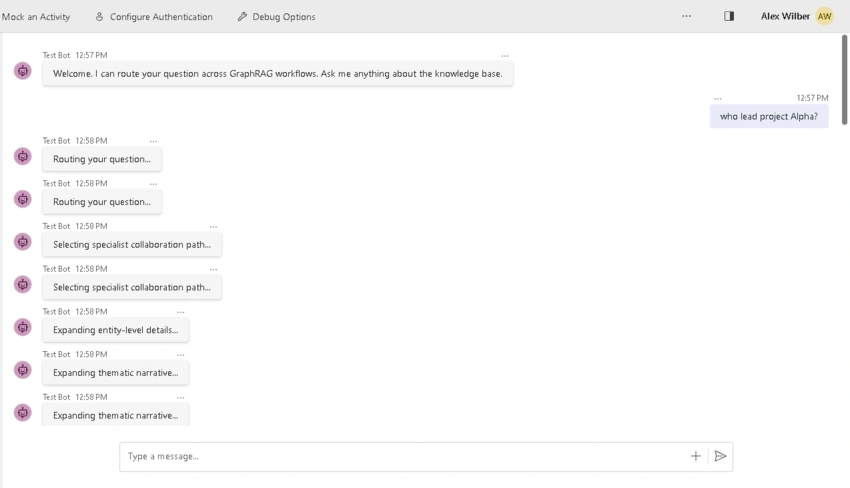
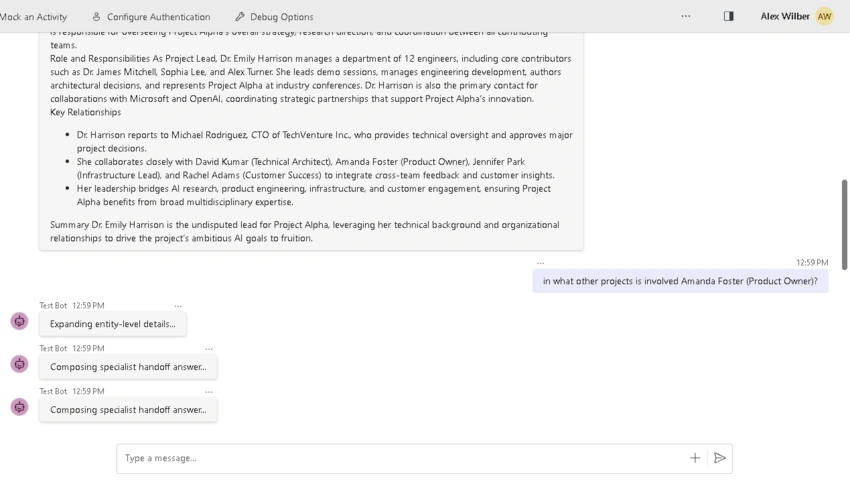
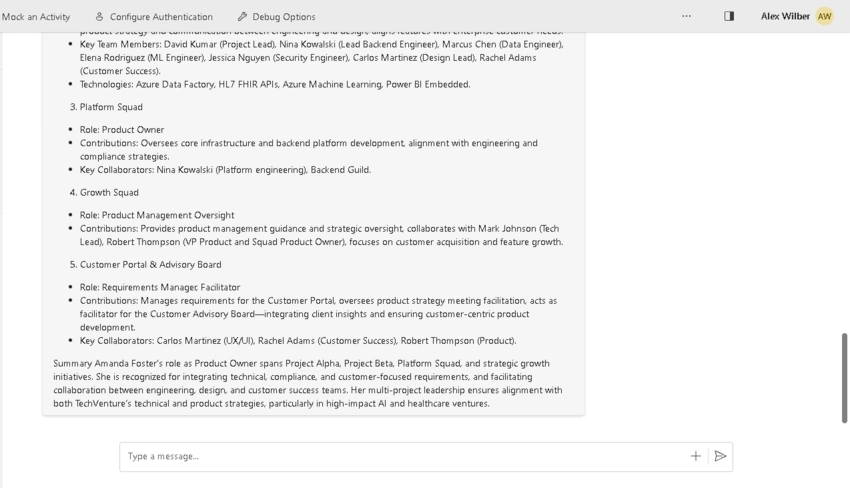
RouterWorkflow in src/workflows/router.py still anchors the routing contract with _MIN_ROUTING_CONFIDENCE_SCORE = 80, _CLASSIFIER_MAX_ATTEMPTS = 3, and deterministic fallback to sequential when the classifier exhausts retries. Unknown labels and explicit out_of_context results continue to degrade into sequential, preventing retrieval fan-out when context is missing. The same module now emits richer telemetry: every call records the classified label, the routed workflow, the fallback reason, and the session context that triggered the decision. On the storage side, src/agents/session_store.py keeps TTL, LRU eviction, and compaction rules while exposing ActiveWorkflowRun metadata so a resumed session can map directly to the checkpoint ID returned by Microsoft Agent Framework. Playground traffic exercises the same /api/messages surface provided by run_router_chatbot.py, meaning multi-turn validation happened on the production entry point instead of a bespoke harness. Quality gates remain unchanged: run_batch_evaluation.py and run_redteam.py still publish the Part 5 metrics and safety evidence.
Azure Monitor setup now lives in src/core/observability.py, and both the router chatbot (run_router_chatbot.py) and evaluation helper (src/evaluation/monitoring/otel_setup.py) call configure_azure_monitor_exporters() so spans, metrics, and logs share the same resource metadata without copy/pasted instrumentation code.
Router spans keep policy observable
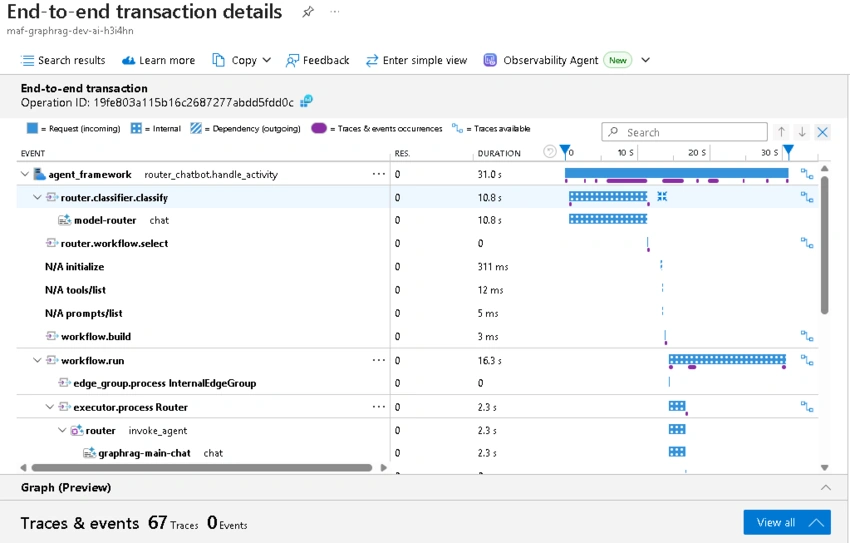
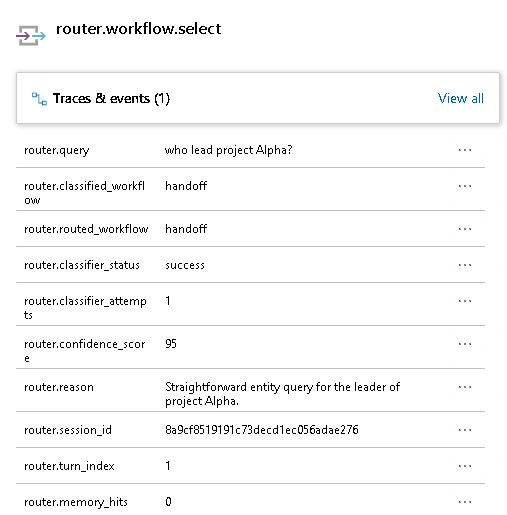
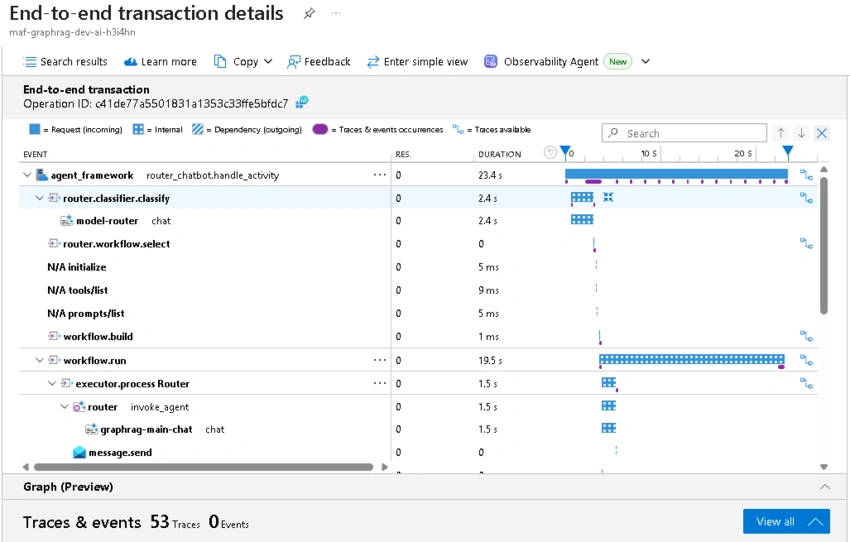
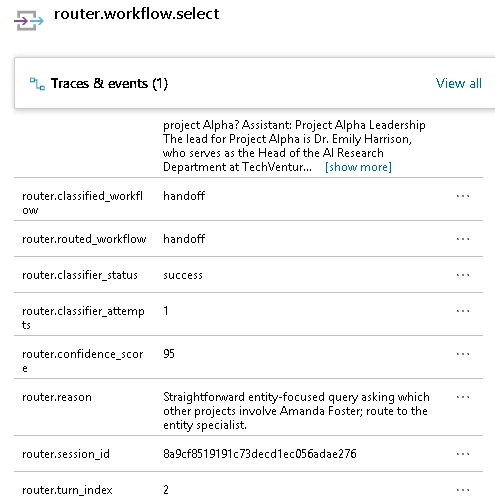
RouterWorkflow still enforces the 80-point confidence threshold and retries transient classifier errors before falling back to sequential. Telemetry now mirrors that contract by logging session context inside router.workflow.select spans:
with _TRACER.start_as_current_span("router.workflow.select") as span:
    self._span_set_if_present(span, "router.session_id", session_telemetry.get("session_id"))
    self._span_set_if_present(span, "router.turn_index", session_telemetry.get("turn_index"))
    self._span_set_if_present(span, "router.confidence_score", router_outcome.classification.confidence_score)
    self._span_set_if_present(span, "router.fallback_reason", router_outcome.fallback_reason)
This transparency supports the per-request optimization model described in Microsoft’s model router guidance, where a single endpoint chooses between Balanced, Cost, and Quality modes without sacrificing policy enforcement.
Session continuity mirrors Microsoft guidance on checkpoints
Microsoft Agent Framework recommends durable checkpoint storage for long-running workflows Microsoft Agent Framework Workflows – Checkpoints. Part 7 follows that guidance by surfacing ActiveWorkflowRun metadata through the session store:
@dataclass(slots=True)
class ActiveWorkflowRun:
    workflow_run_id: str
    checkpoint_id: str
    workflow_type: str
    status: str = "interrupted"
    last_step: str | None = None
When the Playground reconnects, get_or_create retrieves this structure, RouterWorkflow resumes from the stored checkpoint ID, and the span metadata records which checkpoint was used. The result is evidence-backed continuity without introducing a new proxy service.
Evaluation pipeline and workflow patterns stay intact
The multi-turn validation preserves the quality guardrails introduced earlier. The latest Foundry batch evaluation (10 rows) still reports TaskAdherence 0.8, IntentResolution 1.0, Relevance 1.0, Coherence 1.0, and ResponseCompleteness 1.0, while red-team runs continue to log non-zero evaluated attacks. Operators continue to confirm those numbers via uv run python -m evaluation.scripts.run_batch_evaluation --foundry and uv run python -m evaluation.scripts.run_redteam --flow cloud-model, giving the same evidence pipeline Part 5 established. Those results align with the specification that keeps sequential, concurrent, and handoff workflows as routed targets. In practice, that means the router can still delegate research-style questions to the sequential pipeline, parallel fact gathering to the concurrent path, and specialist escalations to the handoff workflow—now with the assurance that the session store can replay the correct checkpoint if a conversation resumes after a pause.
Join the conversation! Your thoughts help the community grow.