
Pre-requisite to understand this
Embeddings – Numerical vector representation of text/images generated by an embedding model.
LLM (Large Language Model) – Model like OpenAI GPT systems that generate human-like text.
Vector Similarity Search – Technique to find semantically similar vectors using cosine similarity or dot product.
API Gateway – Entry point that routes and secures client requests.
Chunking – Splitting large documents into smaller pieces before embedding.
Metadata – Structured attributes (author, date, tags) attached to stored vectors.
RAG (Retrieval-Augmented Generation) – Architecture combining retrieval system with LLM generation.
Introduction
Modern AI applications require more than just a Large Language Model. To provide accurate, contextual, and up-to-date responses, systems integrate Vector Databases, Metadata filtering, Backup Data strategies, RAG Services, and Dynamic Context Discovery (DCD) mechanisms. Together, these components form a scalable AI application that can retrieve domain-specific knowledge, apply contextual filters, dynamically adjust context, and generate reliable answers. Instead of relying solely on static training data, such systems allow AI to access live and enterprise knowledge securely and efficiently.
What problem we can solve with this?
Traditional LLMs hallucinate, lack domain-specific knowledge, and cannot access private enterprise data. By integrating a Vector Database and RAG service, AI applications can retrieve relevant information before generating responses. Metadata improves filtering precision (e.g., by department, date, role). Backup data ensures reliability and disaster recovery. Dynamic Context Discovery (DCD) optimizes which data chunks should be included in the prompt based on query intent. This architecture solves scalability, accuracy, governance, and contextual relevance challenges in AI applications.
Problems solved:
Reduce hallucinations by grounding answers in retrieved documents.
Enable domain-specific AI using enterprise knowledge.
Filter results using metadata constraints (date, department, tags).
Handle large document repositories efficiently.
Ensure system resilience via backup data.
Dynamically optimize context selection using DCD.
Maintain compliance and access control.
How to implement/use this?
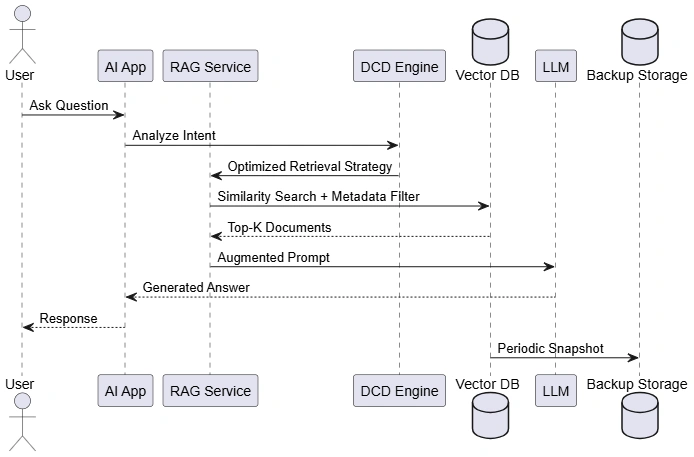
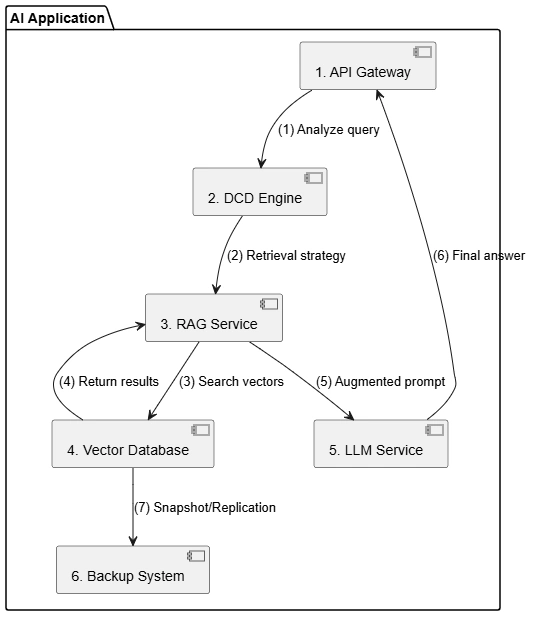
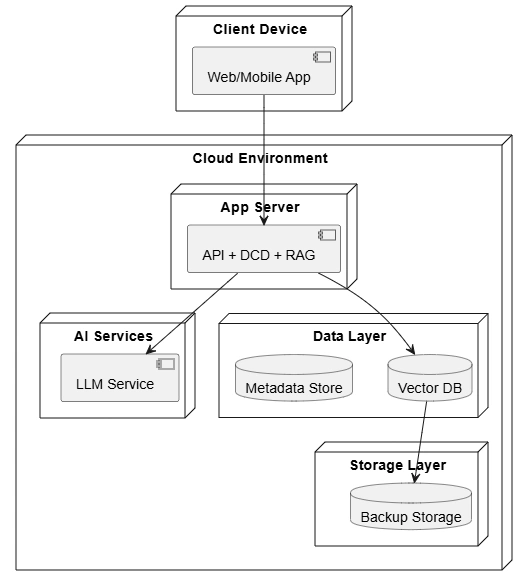
To implement this architecture in a single AI app, documents are first ingested, chunked, and converted into embeddings. These embeddings are stored in a Vector Database with metadata attributes. A RAG service retrieves top-k relevant chunks based on similarity search and metadata filters. Dynamic Context Discovery analyzes user intent and dynamically adjusts the retrieval strategy. The LLM then generates responses using retrieved context. Backup mechanisms periodically snapshot vector and metadata stores. The entire solution is deployed in a scalable cloud-native architecture.
Implementation steps:
Data Ingestion – Upload PDFs, docs, DB records into system.
Chunking & Embedding – Convert text into vector embeddings.
Vector Storage – Store embeddings in vector DB.
Metadata Tagging – Attach structured attributes for filtering.
RAG Retrieval – Fetch relevant vectors based on query.
DCD Layer – Dynamically refine context selection.
LLM Generation – Generate answer using retrieved context.
Backup Strategy – Periodic snapshot of DB and metadata.
Join the conversation! Your thoughts help the community grow.