

Table of Contents
Introduction
What Does “Making Array Elements Unique” Mean?
Why Uniqueness Matters in Healthcare PII Data
Common Techniques to Ensure Uniqueness
Real-World Scenario: De-duplicating Patient Identifiers
Time and Space Complexity Insights
Complete Implementation with Test Cases
Best Practices and Performance Tips
Conclusion
Introduction
In data processing—especially in sensitive domains like healthcare—ensuring that identifiers are unique is not just a best practice; it’s often a legal and ethical requirement. When handling arrays (or lists) of patient data, duplicate entries can lead to misdiagnosis, billing errors, or even violations of privacy regulations like HIPAA.
This article explores practical, efficient, and safe ways to make array elements unique in Python, using a realistic healthcare scenario involving Protected Health Information (PHI). You’ll learn not only how to deduplicate data but also why the method you choose matters for correctness, performance, and compliance.
What Does “Making Array Elements Unique” Mean?
Making array elements unique means transforming a list so that no two elements are the same. This process—often called deduplication—can preserve order, minimize data loss, or prioritize certain values (e.g., the first occurrence).
In Python, this is commonly achieved using sets, dictionaries, or custom logic—each with trade-offs in speed, memory, and behavior.
Why Uniqueness Matters in Healthcare PII Data
Imagine a hospital system ingesting patient records from multiple clinics. Each record includes a Medical Record Number (MRN)—a unique identifier assigned to a patient. Due to system errors or mergers, the same MRN might appear multiple times in a batch.
If duplicates aren’t removed:
Analytics may overcount patients
Alerts could be triggered multiple times
Audit trails become unreliable
Regulatory compliance is at risk
Thus, deduplication isn’t optional—it’s essential.
Common Techniques to Ensure Uniqueness
1. Using a Set (Fast, but Order Not Preserved)
unique_ids = list(set(mrn_list))Fast (O(n))
Loses original order
2. Using dict.fromkeys() (Preserves Order, Python 3.7+)
unique_ids = list(dict.fromkeys(mrn_list))Fast and order-preserving
Minimal code
3. Manual Loop with Seen Set (Full Control)
seen = set()
unique_ids = []
for mrn in mrn_list:
    if mrn not in seen:
        unique_ids.append(mrn)
        seen.add(mrn)
Explicit, readable, and flexible
Ideal for adding validation or logging
Avoid: Converting to set and back if order matters—especially in audit logs or chronological data.
Real-World Scenario: De-duplicating Patient Identifiers
Problem
A health data pipeline receives a list of MRNs from an EHR integration. Some MRNs are duplicated due to network retries. We must return a clean, ordered list of unique MRNs while preserving the first occurrence.
Solution
Use dict.fromkeys() for simplicity and performance.
def deduplicate_mrns(mrn_list: list) -> list:
    """Remove duplicates from MRN list while preserving order."""
    if not mrn_list:
        return []
    return list(dict.fromkeys(mrn_list))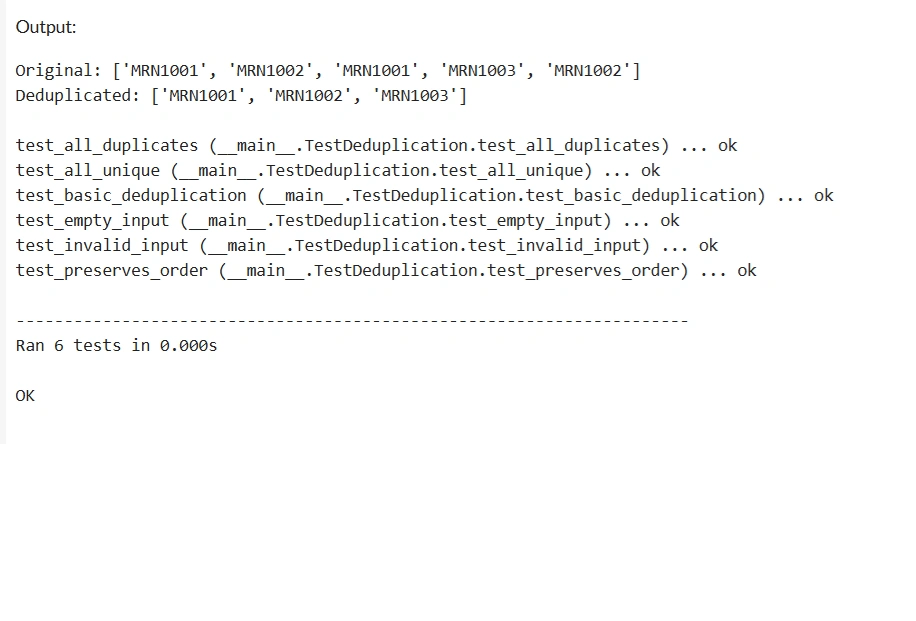
Join the conversation! Your thoughts help the community grow.