Even in today's modern era of technology and AI, we still often find ourselves needing to convert HTML to PDF format. This is a task that remains essential for enterprise applications, from compliance reports and automated invoices to on-demand PDFs from web content. Whether generating PDFs from entire web pages, HTML strings, or templates, the choice of PDF engine affects performance, security, and maintainability.
This guide evaluates more than 30 HTML to PDF solutions in the .NET ecosystem (November 2025), covering architectural patterns, NuGet packages, deprecated libraries, and production-ready options for .NET Framework, .NET Core, .NET 6–10, and cross-platform projects. It helps teams make informed decisions based on modern deployment requirements rather than legacy assumptions. The IronPDF sections, code examples and security guidance were revised in October 2026 against IronPDF v2026.10.3. The descriptions of the other libraries were checked against their vendors' sites and NuGet in October 2026, and claims that could no longer be supported were corrected or removed.
Architecture Patterns
HTML to PDF C# libraries typically follow four main architectural patterns, each with trade-offs in performance, security, and deployment:
- Native Rendering Engines Implement PDF generation entirely in .NET code. Ideal for simple PDF generation tasks and easy deployment, with control over page size, headers, embedded CSS, and images. Limited support for modern CSS or JavaScript rendering.
- Browser Engine Wrappers Use Chromium or WebKit to convert HTML files and HTML snippets with accurate rendering, supporting modern CSS and JavaScript. Examples: IronPDF, PuppeteerSharp. Trade-offs include higher memory usage and more complex deployment.
- External Process Integration Spawn command-line tools like wkhtmltopdf for HTML to PDF conversion. Easy to implement but introduces security, dependency, and performance concerns. Sandbox carefully for file permissions and input safety.
- Cloud Service APIs Offload PDF generation to SaaS providers via REST APIs. Simplifies deployment and maintenance, but adds latency, internet dependency, and potential privacy concerns.
These patterns help developers choose a PDF engine that balances performance, CSS support, JavaScript rendering, and security when you create PDF documents from HTML content.
Comprehensive Library Analysis
Production-Ready Commercial Solutions
IronPDF
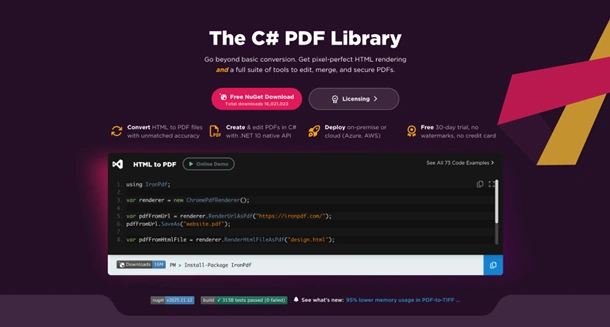
- Architecture: Chromium-based rendering engine
- NuGet: IronPdf package (current release v2026.10.3, October 2026)
- Standards Compliance: PDF Association member, with PDF/A archival output and PDF/UA-1 and PDF/UA-2 accessible output
- Key Strengths: Monthly updates, full .NET 10 support, reliable HTML to PDF conversion, CSS support, JavaScript execution, automatic PDF bookmarks from HTML headings, configurable tables of contents, in-memory compression and linearization, and AES-128/AES-256 encryption
- Use Case: Enterprise applications requiring reliable PDF generation from HTML files, HTML strings, or entire web pages
IronPDF is a powerful .NET library that consistently delivers predictable PDF output across modern web technologies, making it suitable for large-scale PDF generation and complex templates with embedded CSS or JavaScript. Developers can easily convert HTML code to PDF documents with just a few lines of code, minimizing time spent on HTML conversion troubleshooting.
The following .NET CLI command installs the version used in this guide.
dotnet add package IronPdf --version 2026.10.3
Pinning a version keeps builds reproducible. The IronPDF changelog lists the changes in each release, so teams can review them before upgrading.
GemBox.Document
- Architecture: Proprietary rendering engine
- Limitation: 20 paragraphs in free version
- Use Case: Document-centric applications needing PDF generation from HTML snippets or static HTML templates
GemBox.Document is a lightweight .NET library focused on document processing, including HTML to PDF conversion for simple documents and templates.
EO.Pdf
- Architecture: Embedded Chromium engine (Chromium 151 in the September 2026 release)
- Price Point: $799/license
- Limitation: Windows-only deployment
- Provides HTML to PDF conversion with support for embedded CSS, JavaScript execution, and custom headers.
EO.Pdf is a Windows-based .NET library offering HTML to PDF conversion with embedded CSS and JavaScript support.
HiQPdf HTML to PDF Converter
- Free Tier: Licensed for documents of up to 3 pages
- Strength: Supports HTML5/CSS3 rendering
- Limitation: Longer documents are still produced, and in tests with HiQPdf.Free.NetCore 15.0.8 most of them carried a Free Limited Version stamp on each page
- Suitable for generating small PDF documents from HTML content, HTML templates, or HTML pages.
HiQPdf is a .NET library that allows simple HTML to PDF conversions with support for HTML5 and CSS3.
SelectPdf
- Architecture: WebKit, Blink and Chromium engines
- Limitation: Classic packages are Windows-only, and the free SelectPdf.HtmlToPdf.Universal package runs on Linux, Docker and macOS
- Free Tier: 5 pages
- Works well for HTML to PDF conversion tasks where modern CSS and page breaks are needed.
SelectPdf is a .NET library that converts HTML to PDF with modern CSS support.
Spire.PDF
- HTML Engine: On .NET 6 and later, drives a separately installed Chrome browser (ChromeHtmlConverter), and the output text is searchable
- Deployment: Large footprint
- Requires Chrome on the server for HTML conversion.
Spire.PDF is a comprehensive PDF library for .NET that can create, read, and manipulate PDF files. Its HTML conversion depends on a Chrome installation outside the package.
ABCpdf
- Architecture: Multiple engines, with ABCChrome (Chrome 146) as the main engine alongside Gecko, WebKit and MSHTML
- Pricing: From $329 for a Standard single-computer license
- Note: A 30-day trial runs as the Professional Edition, and free licenses are granted on application
- Supports complex templates and HTML page conversion.
ABCpdf is a versatile .NET PDF library with several rendering engines, including Chrome, capable of handling complex templates and HTML pages.
ExpertPdf HTML to PDF Converter
- Strength: HTML5 support
- Price: $550–$1200
- Provides PDF generation from HTML snippets with CSS3 support.
ExpertPdf is a commercial library providing HTML to PDF conversion with HTML5 and CSS3 support.
Winnovative HTML to PDF
- Architecture: Classic engine, plus a Chromium-based engine in the Winnovative PDF Next packages
- Updates: Version 21.0.0 of both product lines released in October 2026
- The Chromium-based engine is intended for modern HTML, CSS and JavaScript.
Winnovative is a commercial .NET library with a classic rendering engine and a newer Chromium-based engine.
PDFmyURL .NET Component
- Type: API wrapper
- Dependency: Internet required
- Ideal for low-volume PDF conversion of entire web pages or HTML templates.
PDFmyURL is an API-based library that converts HTML pages to PDF over the internet, suitable for lightweight or occasional tasks.
GrabzIt
- Type: Screenshot/PDF API service
- Pricing: Plans with a monthly capture allowance
- Suitable for occasional HTML to PDF tasks.
GrabzIt is a cloud service for capturing web pages and generating PDFs or screenshots, optimized for on-demand tasks.
PDF Duo .Net
PDF Duo .Net is no longer available. Its vendor domain has expired, and its last release was version 2.4 in May 2016, so it is not an option for new projects.
Open-Source Solutions
PuppeteerSharp
- Architecture: .NET port of Puppeteer that controls Chrome through the DevTools Protocol and Firefox through WebDriver BiDi
- Issue: About 330 MB of browser downloads (Chrome plus chrome-headless-shell, compressed)
- Framework Support: Targets .NET 10, .NET 8 and .NET Standard 2.0 (version 25.15.0)
- Offers excellent HTML to PDF rendering, including CSS styling, JavaScript support, and entire web page conversion, but deployment is heavier.
PuppeteerSharp is a .NET port of Puppeteer, enabling high-fidelity HTML to PDF conversion with full CSS and JavaScript support.
wkhtmltopdf Ecosystem (CRITICAL WARNING)
All libraries here rely on wkhtmltopdf, whose repository was archived in January 2023:
- wkhtmltopdf: Base binary, archived
- TuesPechkin: Last update 2015
- Rotativa, DinkToPdf, Haukcode.DinkToPdf, NReco.PdfGenerator, OpenHtmlToPdf: All wrapping dead technology
- Security risks and lack of modern CSS support make these unsuitable for production PDF generation.
HtmlRenderer.PdfSharp
- Last Update: July 2026 (version 1.6.1)
- CSS Support: Level 2 only
- Limited to simple PDF files from HTML snippets.
HtmlRenderer.PdfSharp is a lightweight library for generating PDFs from HTML snippets, limited to CSS2 and simple document layouts.
PdfSharp
- No native HTML to PDF support
- Only for programmatic PDF document creation, not HTML conversion.
PdfSharp is a programmatic PDF creation library for .NET, but it does not natively support HTML to PDF conversion.
Browser Automation & Experimental Tools
Chrome Headless / Selenium
- Can render web pages to PDF but require full browser installs on the server.
WebView2 / Westwind.WebView.HtmlToPdf
- Windows-only, desktop runtime required. Westwind.WebView.HtmlToPdf is deprecated, and its HTML to PDF feature now ships in the Westwind.WebView package.
Gotenberg
- Docker-based API that uses headless Chromium for HTML. It runs as a separate service, which adds a network call and container orchestration.
HTMLDOC
- GPL tool first developed in the 1990s and still maintained (version 1.9.24, August 2026). It does not support CSS.
Modern Alternatives (2024–2025)
- Playwright: Browser automation with PDF capability in Chromium
- PeachPDF: Pure .NET, pre-1.0 (version 0.9.24, October 2026)
- Syncfusion PDF Library: Part of suite, Linux HTML converter package is about 150 MB
- Aspose.PDF: Comprehensive PDF manipulation, pricing from $1,199 for one developer
Top 10 NuGet Packages Analysis
This section reviews the most popular C# HTML to PDF NuGet packages based on download statistics and usage trends, excluding IronPDF. We examine their strengths, limitations, and suitability for various PDF generation tasks, including rendering entire web pages, HTML templates, and HTML strings. Download totals were taken from NuGet.org on October 26, 2026, and the list is ordered by them.
- iTextSharp (65.3M downloads)
- Advantages: Mature, widely documented, offers advanced tools for manipulating PDF documents beyond HTML conversion.
- Disadvantages: The AGPL license requires open-sourcing your code. HTML conversion needs the separate XMLWorker add-on, and the package is end-of-life with security fixes only.
- PuppeteerSharp (41.8M downloads)
- Advantages: Excellent Chrome rendering, full support for HTML5, CSS, and JavaScript. Ideal for generating PDF documents from dynamic web content.
- Disadvantages: Needs its own Chrome download. Chromium memory grows when pages are reused, so long-running services need to recycle pages or browsers.
- DinkToPdf (32.2M downloads)
- Advantages: Popular legacy solution for HTML to PDF conversion.
- Disadvantages: Built on the archived wkhtmltopdf, whose known vulnerabilities are unpatched. No NuGet release since April 2017.
- Syncfusion.Pdf.Net.Core (29.8M downloads)
- Advantages: Rich enterprise features, HTML to PDF conversion support for web content.
- Disadvantages: Commercial license per developer per year, with a free Community License for companies under $1M in revenue and 5 or fewer developers. HTML conversion needs a separate converter package of about 150 MB on Linux.
- SelectPdf (9.7M downloads for Select.HtmlToPdf.NetCore)
- Advantages: Simple API, supports CSS styling and a full JavaScript engine.
- Disadvantages: The free Community Edition stops at 5 pages.
- Spire.PDF (8.2M downloads)
- Advantages: Part of a larger Office suite, and integrates with Microsoft Excel and Word workflows.
- Disadvantages: HTML conversion requires a separately installed Chrome. Paid licenses start at $999 for one developer, and a minimal .NET 8 console produced about 70 MB of build output.
- HtmlRenderer.PdfSharp (7.3M downloads)
- Advantages: Depends only on PDFsharp, lightweight and easy for simple PDF generation tasks.
- Disadvantages: Supports HTML 4.01 and CSS level 2 only, so modern layouts and complex templates are out of scope.
- NReco.PdfGenerator (6.9M downloads)
- Advantages: Familiar API, straightforward for basic HTML conversion.
- Disadvantages: Wraps wkhtmltopdf, and its last release was in January 2023.
- Wkhtmltopdf.NetCore (4.9M downloads)
- Advantages: Native .NET Core support, easy to use for basic HTML conversion.
- Disadvantages: Another wrapper around wkhtmltopdf. Its own repository is archived, and its last build is a 2021 preview.
- Rotativa (4.1M downloads, plus 2.7M for Rotativa.AspNetCore)
- Advantages: Good MVC integration for web applications.
- Disadvantages: Relies on wkhtmltopdf and works only through MVC views.
Framework Compatibility Matrix
| Library |
.NET Framework 4.7.2 |
.NET Core 3.1 |
.NET 6–8 |
.NET 10 |
| IronPDF |
Full |
Full |
Full |
Full |
| PuppeteerSharp |
Full |
Full |
Full |
Full |
| SelectPdf |
Windows |
Windows |
Windows (cross-platform with Universal) |
Windows (cross-platform with Universal) |
| DinkToPdf |
None |
Issues |
Issues |
None |
| HtmlRenderer.PdfSharp |
Full |
Limited |
Limited |
Limited |
Takeaways:
- IronPDF and PuppeteerSharp support every framework in this matrix. PuppeteerSharp has targeted .NET 10 since version 21.1.0 (February 2026).
- DinkToPdf has had no NuGet release since April 2017.
Implementation Patterns
Generating PDF files from HTML content can be approached in a few common implementation patterns. These patterns help developers maintain clean, scalable, and testable code while supporting HTML to PDF conversion, CSS styling, and JavaScript execution.
using Microsoft.Extensions.Logging;
using IronPdf;
public interface IPdfGenerator
{
    Task<byte[]> GenerateFromHtmlAsync(string html);
    Task<byte[]> GenerateFromUrlAsync(string url);
}

public class ProductionPdfGenerator : IPdfGenerator
{
    private static readonly HashSet<string> AllowedHosts =
        new(StringComparer.OrdinalIgnoreCase) { "en.wikipedia.org" };

    private readonly ChromePdfRenderer _renderer;
    private readonly ILogger<ProductionPdfGenerator> _logger;

    public ProductionPdfGenerator(ILogger<ProductionPdfGenerator> logger)
    {
        _logger = logger;
        _renderer = new ChromePdfRenderer
        {
            RenderingOptions =
            {
                MarginTop = 25,
                MarginBottom = 25,
                EnableJavaScript = true,      // Supports dynamic HTML content
                Timeout = 60                  // Seconds before a stalled render is abandoned
            }
        };

        // Configure once here, because a singleton renderer is shared by concurrent requests
        _renderer.RenderingOptions.WaitFor.RenderDelay(2000); // Wait for 2 seconds to allow JS to execute
    }

    public async Task<byte[]> GenerateFromHtmlAsync(string html)
    {
        try
        {
            // Render PDF from an HTML string or template
            var pdf = await _renderer.RenderHtmlAsPdfAsync(html);
            _logger.LogInformation("PDF generated successfully");
            return pdf.BinaryData; // Return byte array for storage or download
        }
        catch (Exception ex)
        {
            _logger.LogError(ex, "PDF generation failed");
            throw;
        }
    }

    public async Task<byte[]> GenerateFromUrlAsync(string url)
    {
        // Accept only HTTPS URLs on an allow-list, so callers cannot point the browser at internal hosts
        if (!Uri.TryCreate(url, UriKind.Absolute, out var uri)
            || uri.Scheme != Uri.UriSchemeHttps
            || !AllowedHosts.Contains(uri.Host))
        {
            throw new ArgumentException("URL is not permitted.", nameof(url));
        }

        // Convert entire web pages or specific URLs to PDF documents
        var pdf = await _renderer.RenderUrlAsPdfAsync(uri.AbsoluteUri);
        return pdf.BinaryData;
    }
}
Notes:
- Use this pattern for enterprise applications, large-scale PDF generation, or when rendering complex HTML templates.
- Supports embedded CSS, JavaScript rendering, and custom headers.
- Logging ensures failures during HTML conversion or PDF generation are captured for diagnostics.
- All rendering options, including the JavaScript render delay, are set once in the constructor. When the class is registered as a singleton, every request shares the same renderer, so changing its options inside a request would also change them for requests that are rendering at the same time.
Timeout on RenderingOptions is measured in seconds. A render that exceeds it fails instead of holding the request open.GenerateFromUrlAsync accepts only HTTPS addresses on an allow-list. Without that check, a caller could submit an internal address and the browser engine would request it from inside the network, which is a server-side request forgery (SSRF) risk.
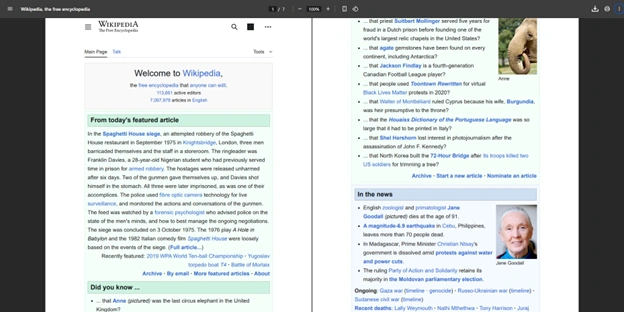
Using this code, for example, we were able to convert this URL (https://en.wikipedia.org/wiki/Main_Page) to PDF format while maintaining the original structure and styling:
Pattern 2: Dependency Injection Configuration
// Program.cs (.NET 6+)
builder.Services.AddSingleton<IPdfGenerator, ProductionPdfGenerator>();

// Usage in controller
[ApiController]
[Route("api/[controller]")]
public class PdfController : ControllerBase
{
    private readonly IPdfGenerator _pdfGenerator;

    public PdfController(IPdfGenerator pdfGenerator)
    {
        _pdfGenerator = pdfGenerator;
    }

    [HttpPost("generate")]
    public async Task<IActionResult> GeneratePdf([FromBody] string html)
    {
        // Generate PDF from HTML string or template
        var pdfData = await _pdfGenerator.GenerateFromHtmlAsync(html);

        // Return PDF file as response
        return File(pdfData, "application/pdf", "document.pdf");
    }
}
Notes:
- Integrates PDF generation into ASP.NET Core applications via dependency injection.
- Promotes clean, testable code and centralized rendering logic.
- Ideal for rendering entire web pages, HTML snippets, or complex templates from existing HTML content.
- Eight concurrent calls through one shared
ProductionPdfGenerator instance completed successfully with IronPDF v2026.10.3 on .NET 10.
Pattern 3 (Bookmarks and Table of Contents for Long Reports)
IronPDF can generate hierarchical PDF bookmarks directly from HTML headings, which makes lengthy reports, documentation and technical manuals easier to navigate. Automatic heading bookmarks were added in v2026.5.2. Table of contents generation existed before 2026, and v2026.10.1 added a configurable title (TableOfContentsTitle) and an optional title entry in the list (TableOfContentsIncludesTitleEntry) through ChromePdfRenderOptions.
using IronPdf;

var renderer = new ChromePdfRenderer();
renderer.RenderingOptions.AutoBookmarksFromHeadings = true;
renderer.RenderingOptions.AutoBookmarkMaxHeadingLevel = 3;
renderer.RenderingOptions.TableOfContents = TableOfContentsTypes.WithPageNumbers;
renderer.RenderingOptions.TableOfContentsTitle = "Contents";
renderer.RenderingOptions.CssPageRulePolicy = CssPageRulePolicy.RenderingOptionsWin;

// reportHtml contains <div id="ironpdf-toc"></div> where the table of contents should appear
var pdf = await renderer.RenderHtmlAsPdfAsync(reportHtml);
- The table of contents is inserted where the HTML contains an element with the ID
ironpdf-toc.
AutoBookmarkMaxHeadingLevel = 3 limits bookmarks to h1 through h3 and nests each level under the one above it. Every bookmark in an 11-page test report pointed to the page on which its heading was rendered.- By default, IronPDF locates headings by searching the rendered text. IronPDF's API documentation describes this mode as fragile when headings break across pages or repeat, and recommends setting
AutoBookmarkCssSelectors (for example, new[] { "h1", "h2", "h3" }) for production documents.
CssPageRulePolicy is explained in the next section.
Page Layout Control for HTML Templates
IronPDF has expanded its HTML rendering controls with configurable CSS @page behavior, header and footer overlap detection, custom hyphenation and fixes for responsive layouts. These changes make page layout more predictable when complex HTML templates are converted to PDF.
| Version |
Change |
| 2026.1.3 |
Custom hyphenation rules loaded from local paths or remote URLs through ChromePdfRenderOptions |
| 2026.3.1 |
Correct width and font scaling for HTML headers and footers when UseResponsiveCssRendering is enabled |
| 2026.5.2 |
Correct scaling of HTML headers and footers with UseFitToPageRendering() and UseScaledRendering() |
| 2026.7.2 |
ChromePdfRenderOptions.CssPageRulePolicy and header/footer overlap detection |
| 2026.8.1 |
Fix for empty areas at the page edge in landscape rendering with responsive CSS or fit-to-page scaling |
IronPDF renders HTML headers and footers in a separate pass and places them in the page margin. When a template declares its own @page { margin: ... } rule, the body margins and the header band can disagree. CssPageRulePolicy.RenderingOptionsWin replaces the template's @page margins with the margins set in RenderingOptions, and CssPageRulePolicy.CssPageWin copies the template's margins into the rendering options instead. The default value leaves @page rules unchanged.
For headers and footers added to an existing PDF, AddHtmlHeaders and AddHtmlFooters accept a ContentOverlapBehavior value (Ignore, Warn or Throw) that reports the pages where the new header or footer would cover existing text or images.
IronPDF bundles its own Chromium build, version 109, rather than using the browser installed on the server. Version 2026.10.3 applied :has(), container queries, @layer and aspect-ratio, but not CSS nesting or color-mix(). Templates that rely on CSS features introduced after Chrome 109 should be tested before deployment.
Performance Benchmarks
Performance is critical for HTML to PDF conversion, especially in high-volume or large-scale PDF generation scenarios. This section covers rendering reliability, output size and deployment complexity.
The original version of this guide included memory and timing figures for IronPDF, PuppeteerSharp, HtmlRenderer.PdfSharp and DinkToPdf. They were removed in this update because the test method was not published and the results could not be reproduced.
Rendering Reliability Updates in 2026
IronPDF's 2026 releases introduced improvements to browser-tab reuse, rendering efficiency, timeout handling and concurrent PDF processing. According to the changelog, these updates address unexpected browser-process crashes, queue deadlocks and rendering failures in high-volume HTML-to-PDF workloads and on servers with limited CPU.
- April 2026 (v2026.4.1) Fewer internal render calls and reuse of browser tabs to reduce startup overhead.
- May 2026 (v2026.5.2) Improved tab pool stability under concurrent rendering and a fix for intermittent crashes during process teardown.
- June 2026 (v2026.6.1) A fix for
IronPdfEngine queue deadlocks under concurrent load.
- July 2026 (v2026.7.2) Detection of stalled renders with clearer timeout errors, and fixes for orphaned browser processes and crashes under heavy load or constrained CPU.
- September and October 2026 (v2026.9.2, v2026.10.1) Fixes for intermittent crashes when PDF documents are accessed or disposed concurrently.
These items are fixes reported in the changelog, not measured performance gains. Teams that need throughput figures should benchmark their own templates and control the following conditions.
- Use the same HTML input, page count and assets for every library.
- Record the library version, .NET version, operating system and hardware.
- Report the first renders, which include browser start-up, separately from warm renders.
- Measure the peak memory of the whole process, including any browser child processes.
- Run at the concurrency level expected in production.
PDF Output Compression and Linearization
IronPDF also provides PDF output optimization through in-memory compression and linearization APIs, which are useful for document-heavy web applications and cloud workflows where writing temporary files is restricted.
| Version |
Capability |
| 2026.3.1 |
CompressPdfToBytes and CompressPdfToStream |
| 2026.5.2 |
LinearizePdfToBytes and LinearizePdfToStream |
| 2026.6.1 |
AdvancedCompressionOptions for image DPI downsampling and JPEG quality control |
| 2026.10.1 |
Optional 1-bit CCITT Group 4 compression for scanned documents through AdvancedCompressionOptions |
byte[] compressed = pdf.CompressPdfToBytes(null, false, CompressionMode.FastMemory);
byte[] linearized = pdf.LinearizePdfToBytes(LinearizationMode.InMemory);
CompressionMode.FastMemory performs no disk I/O but does not resample images. On a text-heavy 11-page test report, it reduced the file from 77,116 bytes to 64,339 bytes. Image downsampling and JPEG quality settings require AdvancedCompressionOptions, which is passed to CompressAndSaveAs and writes the result to a file. Linearized output allows a browser to display the first page before the whole file has downloaded. The second argument of CompressPdfToBytes removes the structure tree when set to true, which also removes the accessibility tags described under Recommendations.
Deployment Complexity
| Library |
Complexity Score (1–10) |
Notes |
| IronPDF |
2 |
NuGet install. On Linux, the package installs its system dependencies by default on first use. |
| HtmlRenderer.PdfSharp |
3 |
Easy to use but missing modern CSS and JavaScript support. |
| SelectPdf |
5 |
Classic packages are Windows-only. Linux and macOS need the separate Universal package. |
| PuppeteerSharp |
7 |
Downloads and manages its own Chrome binaries, about 330 MB compressed. |
| DinkToPdf |
8 |
Native binaries and platform differences make large-scale deployment tricky. |
| Gotenberg |
9 |
Runs as a Docker service, adding orchestration overhead and network latency. |
Takeaways:
- For production HTML to PDF conversion, libraries with low memory usage, fast generation times, and thread safety are preferred.
- Deployment simplicity is equally important: IronPDF scores best for quick integration in .NET Core, .NET 6+, and .NET 10 projects.
Docker, Linux and Cloud Deployment
The 2026 releases add AMD64 and ARM64 support for the IronPdfEngine Docker image, compatibility with current Linux distributions and fixes for Azure App Service.
| Version |
Improvement |
| 2026.3.1 |
LinuxAndDockerDependenciesAutoConfig installs the correct audio library (libasound2t64) on Ubuntu 24.04 for .NET 9 and .NET 10 |
| 2026.4.1 |
IronPdfEngine Docker image reduced by 60%, from 2.89 GB to 1.14 GB |
| 2026.5.2 |
qpdf rebuilt with statically linked libjpeg and zlib, which removes the libjpeg.so.62 dependency of IronPdf.Linux and adds compatibility with Debian 13 and Rocky Linux 9 and 10 |
| 2026.8.1 |
Startup fixes for read-only Azure App Service deployments and for minimal Linux containers |
| 2026.9.2 |
Multi-architecture IronPdfEngine Docker image for AMD64 and ARM64 |
The 60% reduction applies to the IronPdfEngine Docker image, not to the IronPdf NuGet package. The full IronPdf package bundles Chromium binaries for each supported platform, and a .NET 10 console application built on Windows with v2026.10.3 produced 603 MB of build output. Applications that need a smaller footprint can install IronPdf.Slim and send rendering to an IronPdfEngine container, as IronPDF's documentation recommends. The client package and the container must use the same version.
Security Considerations
Generating PDF documents from HTML carries potential security risks, especially when using abandoned libraries like wkhtmltopdf.
Key Vulnerabilities
- Local file disclosure (CVE-2020-21365, directory traversal) via crafted HTML.
- SSRF attacks (CVE-2022-35583) through injected iframes that point at internal addresses.
- XSS vectors from unsafe HTML or JavaScript.
- Unpatched flaws in discontinued libraries.
Best Practices
- Sanitize HTML input to remove unsafe scripts.
- Disable JavaScript unless necessary.
- Use sandboxed renderers with timeouts to prevent infinite loops.
- Avoid Process.Start() methods and abandoned libraries.
- Validate external resources for security compliance. HTML sanitization removes scripts, but it does not stop the renderer from requesting the image, stylesheet and font URLs that remain in the markup. Restrict those URLs to approved hosts, validate any URL passed to
RenderUrlAsPdf, and block outbound traffic from the PDF service to internal address ranges.
The following example uses the open-source HtmlSanitizer package (namespace Ganss.Xss), which is installed alongside IronPdf with dotnet add package HtmlSanitizer.
using Ganss.Xss;
using IronPdf;

public class SecurePdfGenerator
{
    private static readonly HashSet<string> AllowedResourceHosts =
        new(StringComparer.OrdinalIgnoreCase) { "cdn.example.com" };

    public async Task<byte[]> GenerateSecurePdf(string untrustedHtml)
    {
        var sanitizer = new HtmlSanitizer();

        // Drop any resource URL that is not HTTPS on an approved host (SSRF protection)
        sanitizer.FilterUrl += (sender, e) =>
        {
            if (!Uri.TryCreate(e.OriginalUrl, UriKind.Absolute, out var uri)
                || uri.Scheme != Uri.UriSchemeHttps
                || !AllowedResourceHosts.Contains(uri.Host))
            {
                e.SanitizedUrl = null;
            }
        };

        var sanitizedHtml = sanitizer.Sanitize(untrustedHtml);

        var renderer = new ChromePdfRenderer
        {
            RenderingOptions =
            {
                EnableJavaScript = false,
                Timeout = 30,
                PaperSize = IronPdf.Rendering.PdfPaperSize.A4
            }
        };

        var pdf = await renderer.RenderHtmlAsPdfAsync(sanitizedHtml);
        return pdf.BinaryData;
    }
}
HtmlSanitizer removes scripts, iframes, <link> elements, event handlers and javascript: links.- The
FilterUrl handler removes every resource URL that is not HTTPS on an approved host. It removed an image that pointed at a cloud metadata address (169.254.169.254) and a CSS background URL that pointed at a private IP address, and it kept an image from the approved CDN.
Timeout is measured in seconds, so 30 stops a render after 30 seconds.RenderHtmlAsPdfAsync returns a PdfDocument, so the method returns its BinaryData to match the byte[] signature.- Application-level filtering should be combined with network controls, because the DNS records of an approved host can change after the URL has been checked.
Keeping the PDF Library Patched
Version 2026.10.3 updates its SixLabors.ImageSharp dependency to resolve CVE-2026-106110 through CVE-2026-106118 on .NET 6 and later (ImageSharp 4.1.3 on .NET 8 and later, 3.2.0 on .NET 6 and 7). Earlier 2026 releases strengthened the IronPdfEngine Docker image, where v2026.4.1 removed unnecessary packages and resolved 4 high-severity CVEs and more than 1,400 other security scan findings. Version 2026.8.1 added configurable AES-128 and AES-256 PDF encryption through PdfSecuritySettings.EncryptionType.
Two further points apply to most projects.
- The ImageSharp fix arrives as a transitive dependency. Projects that target .NET 8 audit only direct dependencies by default, so transitive advisories do not appear in the build output. Adding
<NuGetAuditMode>all</NuGetAuditMode> to the project file, or running dotnet list package --vulnerable --include-transitive, reports them.
- The default encryption algorithm remains 128-bit RC4 for backward compatibility, and IronPDF's API documentation describes RC4 as cryptographically weak. AES should be set explicitly when a document is password-protected.
pdf.SecuritySettings.EncryptionType = IronPdf.Security.PdfEncryptionType.Aes_256;
pdf.SecuritySettings.UserPassword = "open-password";
pdf.SecuritySettings.OwnerPassword = "owner-password";
A document saved with these settings by v2026.10.3 used AES-256 encryption (security handler revision 6) and could not be opened without the user password.
Recommendations
Selecting the right HTML to PDF library in C# depends on your project's scope, scale, and security requirements. Below are tailored recommendations for different scenarios.
1. For Enterprise Applications
Primary Recommendation: IronPDF
- Fully cross-platform and supports .NET Framework, .NET Core, and .NET 10.
- Consistent monthly updates with security patches, most recently the ImageSharp vulnerability fixes in v2026.10.3.
- Supports PDF/A archival formats and the PDF/UA-1 and PDF/UA-2 accessibility standards, essential for archival, compliance and public-sector reports.
- Handles complex templates, CSS styling, and JavaScript execution.
- Provides professional support and extensive documentation, reducing developer overhead.
Accessible PDF output. PDF/UA-2 (ISO 14289-2) support was added in v2025.12.2. During 2026, releases improved the tagging of headings, paragraphs and form fields, added PdfDocument.SetImageAltText for setting alternative text on images in existing PDFs (v2026.9.2), and preserved accessibility metadata when PDFs are merged or pages are copied (v2026.9.2 and v2026.10.1). RenderHtmlAsPdfUA renders HTML directly to PDF/UA, and SaveAsPdfUA accepts a PdfUAVersions value to select PDF/UA-1 or PDF/UA-2.
Accessible output still depends on the source document. The HTML needs a logical heading order, alternative text for images, labelled form fields and a declared language, and the resulting PDF should be checked with a validator such as PAC or veraPDF before publication.
Use Case: Generating large-scale PDF files, entire web pages, or creating PDF files from HTML templates.
2. For Proof of Concepts or Testing
Recommended Library: PuppeteerSharp
- Excellent Chrome-based rendering, supporting modern HTML, CSS, and JavaScript.
- Good for dynamic web content or interactive HTML pages.
- Be mindful of memory usage and deployment complexity in serverless environments.
Use Case: Quick prototypes or experimental PDF generation.
3. For Simple Documents or Lightweight Tasks
Recommended Library: HtmlRenderer.PdfSharp
- Lightweight and easy to integrate.
- Supports basic HTML snippets and CSS2 styling.
- Not suitable for complex templates or large-scale PDF generation.
Use Case: Single-page HTML documents, simple reports, or internal tools with minimal CSS and JavaScript requirements.
4. Libraries to Avoid in Production
- All wkhtmltopdf-based libraries (DinkToPdf, Rotativa, NReco.PdfGenerator): Unpatched security vulnerabilities.
- Process.Start() approaches: Injection risks.
- Abandoned projects: No security updates, no modern web support.
5. Migration Strategy for Deprecated Libraries
// Legacy code using wkhtmltopdf-based library
public byte[] OldMethod(string html)
{
    var converter = new SomeWkHtmlToPdfWrapper();
    return converter.Convert(html);
}

// Migration to supported library
public async Task<byte[]> NewMethod(string html)
{
    var renderer = new ChromePdfRenderer();
    var pdf = await renderer.RenderHtmlAsPdfAsync(html);
    return pdf.BinaryData;
}
Conclusion
C# HTML to PDF conversion in 2026 requires careful library selection to balance performance, security, and maintainability. While many libraries exist, only a few meet modern .NET requirements for reliable PDF generation.
Key Takeaways
- Choose actively maintained libraries Monthly updates, security patches, and .NET 10 support are essential. IronPDF is the most reliable for production environments. Pin the package version and review the changelog before each upgrade.
- Avoid deprecated or abandoned solutions wkhtmltopdf-based libraries have security flaws and lack modern CSS/JS support. Process.Start() methods carry injection risks.
- Match the library to your use case Enterprise PDF generation: IronPDF. Prototypes / PoCs: PuppeteerSharp. Simple documents: HtmlRenderer.PdfSharp.
- Support complex HTML content Ensure libraries handle CSS3, JavaScript, page breaks, custom headers, and HTML templates. For long documents, also check bookmark and table of contents generation, and test any CSS feature that is newer than the library's bundled browser engine.
- Invest in maintainable workflows Dependency injection and well-maintained renderers simplify scalable PDF generation. Migrating from deprecated libraries reduces long-term security and maintenance risks.
- Plan for accessible output PDF/UA support, image alternative text and preserved tags matter for public-sector and regulated documents, but they still require well-structured HTML and validation.
Final Thought:
Choosing the right library is more than PDF quality, it ensures security, cross-platform support, and maintainability. For generating PDF documents from HTML pages or templates, a commercial, actively maintained solution like IronPDF is the most reliable approach. Try IronPDF's free trial to explore its powerful features for yourself, and check out its extensive documentation to learn more.

Join the conversation! Your thoughts help the community grow.