
1. The Problem Space
Modern Python microservices are rarely CPU-bound. They spend 80–95% of their time waiting: on databases, vector stores, LLM APIs, third-party REST endpoints, message queues, or object storage. In an enterprise multi-agent RAG system — where a single user query can fan out into 10+ concurrent I/O calls across retrieval, re-ranking, tool execution, and synthesis — naive implementations collapse under latency and connection exhaustion. This article walks through a complete, production-grade implementation of an Enterprise Customer Intelligence Platform built with LangGraph, combining async/await, connection pooling, and concurrent.futures to deliver sub-second latency at scale.
2. Three Pillars of I/O Optimization
2.1 async/awaitCooperative Concurrency
Python's asyncio event loop lets thousands of coroutines share a single thread. Every await is a yield point where the loop can switch to another task. Rule: if the operation is I/O, make it async. Never block the loop with requests, psycopg2, or time.sleep.
2.2 Connection Pooling Amortize Handshakes
TCP/TLS handshakes and DB authentication are expensive. A pool keeps warm, authenticated connections ready. Without pooling, a burst of 500 concurrent LLM calls can exhaust ephemeral ports or hit Postgres's max_connections.
2.3 concurrent.futures — Escape the GIL for CPU Work
When a coroutine must call a CPU-bound function (e.g., embedding computation, PDF parsing, re-ranking), run_in_executor offloads it to a worker thread/process without blocking the event loop.
The synergy: async handles the I/O fan-out, pools cap resource usage, and executors keep CPU work off the loop.
3. Real-World Use Case: Enterprise Customer Intelligence Platform
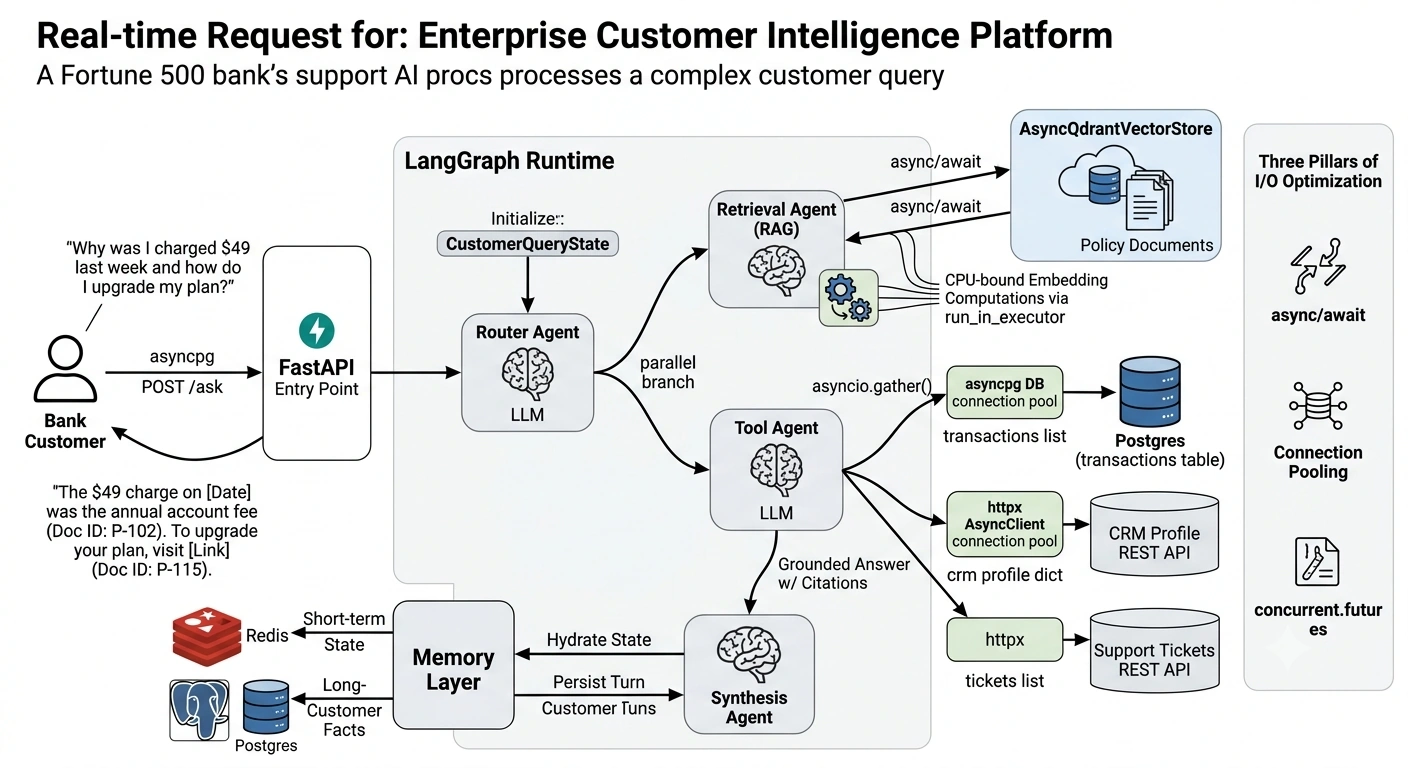
Scenario: A Fortune 500 bank's support AI. A customer asks: "Why was I charged $49 last week and how do I upgrade my plan?"
The system must:
Retrieve policy docs (vector DB)
Pull transaction history (Postgres)
Fetch CRM profile (REST API)
Check open support tickets (REST API)
Synthesize a grounded answer with citations
Five heterogeneous I/O sources, all called in parallel, all pooled, all async.
4. Architecture
5. Implementation
5.1 Dependencies
pip install langgraph langchain-openai langchain-qdrant \
            asyncpg httpx redis aioredis tenacity \
            pydantic python-dotenv
5.2 Shared Infrastructure — Pools & Clients
# infrastructure.py
import asyncio
from contextlib import asynccontextmanager
from typing import AsyncIterator

import asyncpg
import httpx
import redis.asyncio as aioredis

class ServicePool:
    """Holds all long-lived async resources. Created once at startup."""

    def __init__(self, config: dict):
        self.config = config
        self._db_pool: asyncpg.Pool | None = None
        self._http: httpx.AsyncClient | None = None
        self._redis: aioredis.Redis | None = None
        self._semaphore = asyncio.Semaphore(config.get("max_concurrent_llm", 20))

    async def start(self) -> None:
        # 1. DB connection pool — 20 min, 100 max connections
        self._db_pool = await asyncpg.create_pool(
            dsn=self.config["db_dsn"],
            min_size=10,
            max_size=100,
            command_timeout=10,
            server_settings={"application_name": "customer_intel"},
        )
        # 2. HTTP client with connection pooling + keep-alive
        limits = httpx.Limits(max_connections=200, max_keepalive_connections=50)
        self._http = httpx.AsyncClient(
            limits=limits,
            timeout=httpx.Timeout(15.0, connect=5.0),
            headers={"X-Service": "customer-intel"},
        )
        # 3. Redis for short-term memory & rate-limit counters
        self._redis = aioredis.from_url(
            self.config["redis_url"], decode_responses=True
        )

    async def stop(self) -> None:
        if self._db_pool: await self._db_pool.close()
        if self._http:    await self._http.aclose()
        if self._redis:   await self._redis.aclose()

    @property
    def db(self) -> asyncpg.Pool:
        assert self._db_pool is not None
        return self._db_pool

    @property
    def http(self) -> httpx.AsyncClient:
        assert self._http is not None
        return self._http

    @property
    def redis(self) -> aioredis.Redis:
        assert self._redis is not None
        return self._redis

    @asynccontextmanager
    async def llm_slot(self) -> AsyncIterator[None]:
        """Gate LLM calls to avoid provider rate limits."""
        async with self._semaphore:
            yield
5.3 State Schema (LangGraph TypedDict)
# state.py
from typing import Annotated, Any
from typing_extensions import TypedDict
from langgraph.graph.message import add_messages

class CustomerQueryState(TypedDict):
    session_id: str
    customer_id: str | None
    query: str
    messages: Annotated[list, add_messages]   # LangGraph message reducer
    retrieved_docs: list[dict]
    transactions: list[dict]
    crm_profile: dict | None
    open_tickets: list[dict]
    plan: str                                  # routing decision
    final_answer: str | None
    errors: list[str]
5.4 Agent Nodes — Parallel I/O with asyncio.gather
# agents.py
import asyncio
from concurrent.futures import ThreadPoolExecutor
from datetime import datetime

from langchain_openai import AsyncChatOpenAI
from langchain_qdrant import QdrantVectorStore, AsyncQdrantVectorStore
from tenacity import retry, stop_after_attempt, wait_exponential

from infrastructure import ServicePool
from state import CustomerQueryState

# CPU-bound work gets its own executor — never blocks the loop.
_embedding_executor = ThreadPoolExecutor(max_workers=4)

llm = AsyncChatOpenAI(model="gpt-4o-mini", temperature=0)
vector_store = AsyncQdrantVectorStore.from_existing_collection(
    embedding=None,  # we embed async below
    collection_name="policies",
    url="http://qdrant:6333",
)


# ---------- Router Agent ----------
async def router_node(state: CustomerQueryState, pools: ServicePool) -> dict:
    """Decide which downstream agents to invoke."""
    prompt = (
        "Classify the customer query into one of: "
        "billing, plan_upgrade, general, mixed. "
        f"Query: {state['query']}"
    )
    async with pools.llm_slot():
        resp = await llm.ainvoke(prompt)
    plan = resp.content.strip().lower()
    return {"plan": plan, "messages": [resp]}


# ---------- Retrieval Agent (RAG) ----------
@retry(stop=stop_after_attempt(3), wait=wait_exponential(min=1, max=8))
async def _embed_text(text: str) -> list[float]:
    """CPU-bound embedding offloaded to thread executor."""
    loop = asyncio.get_running_loop()
    # OpenAI client is sync; run_in_executor keeps the loop free.
    return await loop.run_in_executor(
        _embedding_executor,
        lambda: llm.client.embeddings.create(
            model="text-embedding-3-small", input=[text]
        ).data[0].embedding,
    )


async def retrieval_node(state: CustomerQueryState, pools: ServicePool) -> dict:
    query = state["query"]
    embedding = await _embed_text(query)
    docs = await vector_store.asimilarity_search_by_vector(embedding, k=5)
    return {
        "retrieved_docs": [{"content": d.page_content, "meta": d.metadata} for d in docs],
        "messages": [{"role": "tool", "content": f"Retrieved {len(docs)} docs"}],
    }


# ---------- Tool Agent: parallel DB + HTTP fan-out ----------
async def _fetch_transactions(pools: ServicePool, customer_id: str) -> list[dict]:
    rows = await pools.db.fetch(
        "SELECT id, amount, description, occurred_at "
        "FROM transactions WHERE customer_id = $1 "
        "AND occurred_at > now() - interval '30 days' "
        "ORDER BY occurred_at DESC LIMIT 20",
        customer_id,
    )
    return [dict(r) for r in rows]


async def _fetch_crm(pools: ServicePool, customer_id: str) -> dict:
    r = await pools.http.get(f"https://crm.internal/api/customers/{customer_id}")
    r.raise_for_status()
    return r.json()


async def _fetch_tickets(pools: ServicePool, customer_id: str) -> list[dict]:
    r = await pools.http.get(
        f"https://support.internal/api/tickets",
        params={"customer_id": customer_id, "status": "open"},
    )
    r.raise_for_status()
    return r.json().get("tickets", [])


async def tools_node(state: CustomerQueryState, pools: ServicePool) -> dict:
    customer_id = state.get("customer_id")
    if not customer_id:
        return {"errors": state.get("errors", []) + ["no customer_id"]}

    # ★ KEY OPTIMIZATION: fan out all I/O in parallel ★
    txns, crm, tickets = await asyncio.gather(
        _fetch_transactions(pools, customer_id),
        _fetch_crm(pools, customer_id),
        _fetch_tickets(pools, customer_id),
        return_exceptions=True,
    )

    errors = []
    if isinstance(txns, Exception): errors.append(f"txns: {txns}")
    if isinstance(crm, Exception):  errors.append(f"crm: {crm}")
    if isinstance(tickets, Exception): errors.append(f"tickets: {tickets}")

    return {
        "transactions": txns if not isinstance(txns, Exception) else [],
        "crm_profile":   crm  if not isinstance(crm, Exception)  else None,
        "open_tickets":  tickets if not isinstance(tickets, Exception) else [],
        "errors": state.get("errors", []) + errors,
    }


# ---------- Synthesis Agent ----------
async def synthesis_node(state: CustomerQueryState, pools: ServicePool) -> dict:
    context = (
        f"Docs:\n{state['retrieved_docs']}\n\n"
        f"Transactions:\n{state['transactions']}\n\n"
        f"CRM:\n{state['crm_profile']}\n\n"
        f"Open tickets:\n{state['open_tickets']}"
    )
    prompt = (
        "You are a senior support agent. Answer using ONLY the context. "
        "Cite document IDs. If unsure, say so.\n\n"
        f"Customer query: {state['query']}\n\n{context}"
    )
    async with pools.llm_slot():
        resp = await llm.ainvoke(prompt)
    return {"final_answer": resp.content, "messages": [resp]}
Join the conversation! Your thoughts help the community grow.