
A few weeks back, during a production rollout of a distributed Celery-based data processing platform , we started seeing random bursts of failed jobs. The logs showed this dreaded message:
FATAL: remaining connection slots are reserved for roles with
privileges of the "pg_use_reserved_connections" role
At first glance, it looked like a database outage — but it wasn’t. The real issue was PostgreSQL connection pool exhaustion. Multiple Celery workers, each running several concurrent processes, were quietly opening more connections than the database could handle. This post documents what we learned from that incident — and how to keep PostgreSQL, Celery, and SQLAlchemy working together reliably at scale.
Understanding what went wrong required digging into how PostgreSQL handles connections under the hood — and how Celery unintentionally multiplies them.
1. Why Connection Pools Matter
Every database operation needs a connection. Creating and tearing one down for each task is slow and expensive.
pools help — they reuse open connections and reduce latency. But in distributed systems, these pools can multiply across workers and nodes, quickly overwhelming PostgreSQL. Understanding how those pools interact with your worker topology is the key to avoiding connection exhaustion.
2. How Connections Multiply in Distributed Systems
2.1 Quick Mental Model
Each Celery worker process has its own pool. When you scale workers or increase concurrency, you’re multiplying the number of persistent connections.
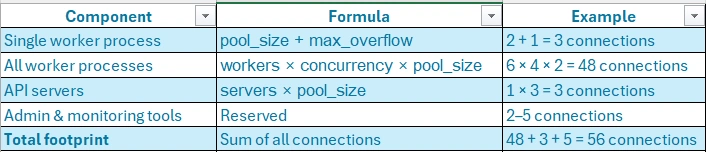
If max_connections in PostgreSQL is 50… exceeding the limit is just a matter of time.
2.2 Lifecycle of a Pooled Connection
The connection lifecycle looks like this:
App requests a connection from the pool.
If a free one exists, it’s reused. Otherwise, a new connection is opened.
When done, the app returns it to the pool.
The pool may close and refresh connections periodically (pool_recycle).
Once you understand how connections accumulate and persist through their lifecycle, the next step is learning how to control them. That’s where tuning strategies come in — right-sizing connection pools, managing idle connections, and adding resilience can prevent exhaustion before it starts.
3. Tuning Strategies That Actually Work
3.1 Right-Size Each Pool
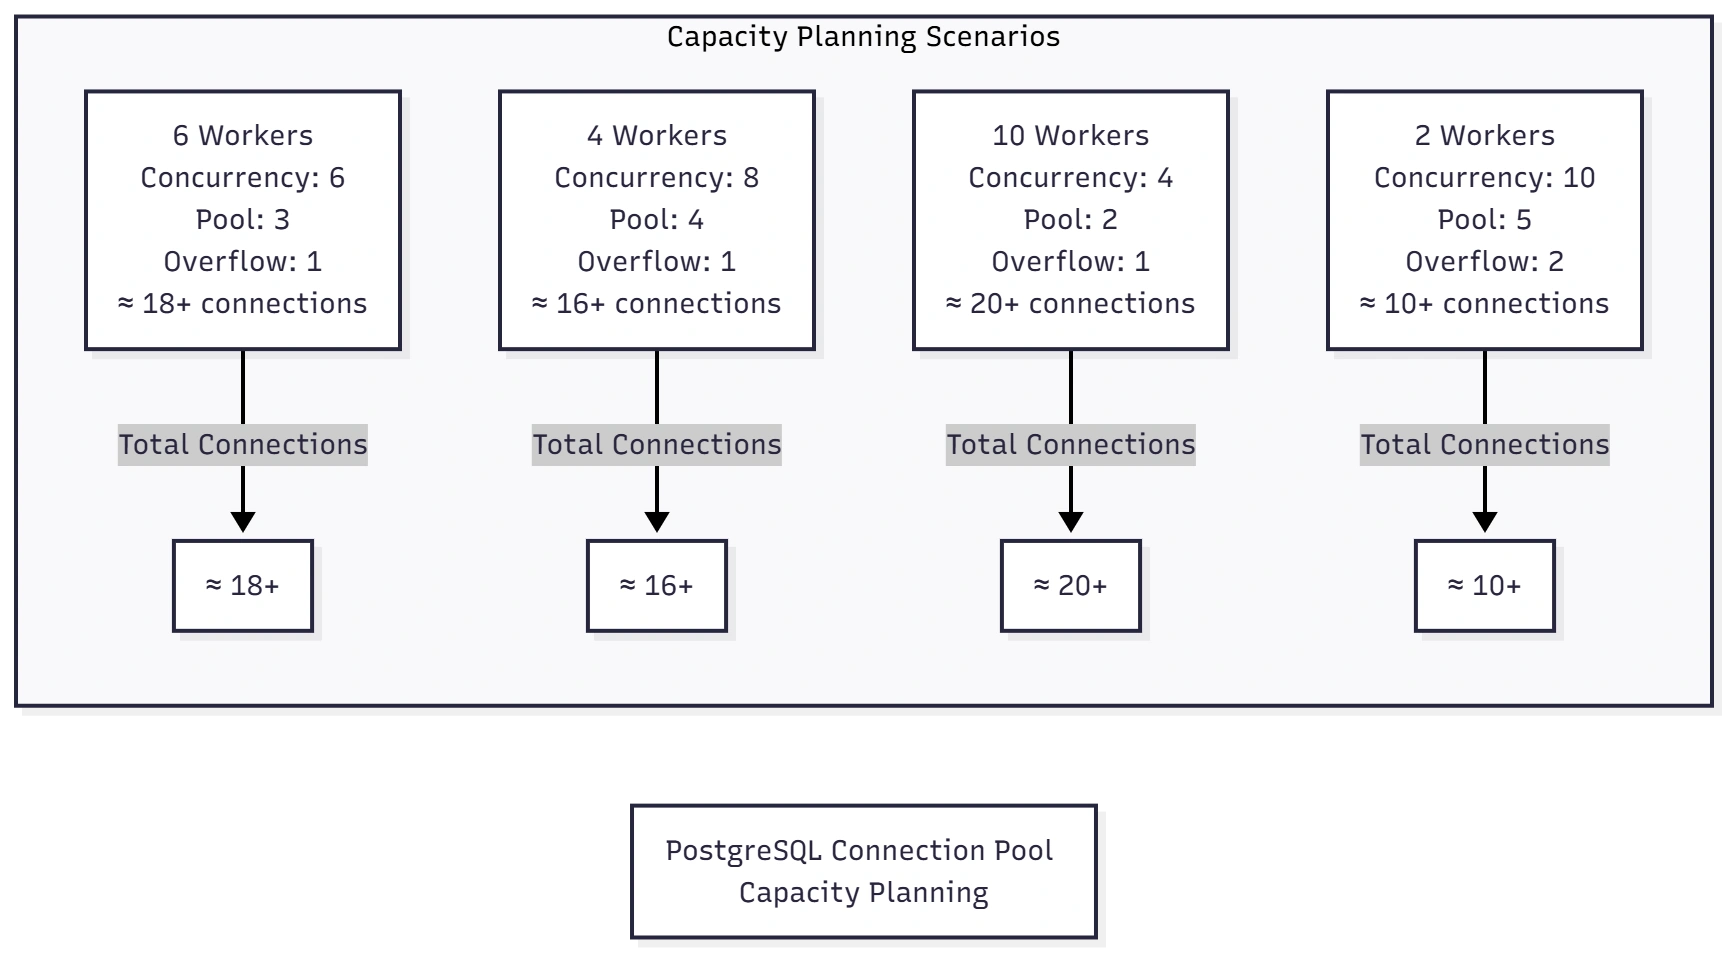
Set pool size to roughly half the worker concurrency and limit overflow to a quarter of the pool size.
engine = create_engine(
    DATABASE_URL,
    pool_size=POOL_SIZE,         # ≈ worker_concurrency / 2
    max_overflow=MAX_OVERFLOW,   # ≈ 25% of pool_size
    pool_recycle=3600,           # Refresh connections hourly
    pool_pre_ping=True,          # Validate before checkout
)
3.2 Keep Idle Connections Alive
Long-running jobs and network appliances can silently terminate idle connections. Enable TCP keepalives to avoid unexpected disconnects.
@event.listens_for(engine, "engine_connect")
def set_keepalive(dbapi_connection, connection_record):
    cursor = dbapi_connection.cursor()
    cursor.execute("SET tcp_keepalives_idle = 600")
    cursor.execute("SET tcp_keepalives_interval = 30")
    cursor.execute("SET tcp_keepalives_count = 3")
    cursor.close()
3.3 Add Resilient Session Management
Transient failures happen. Wrap database sessions with retry logic.
@contextmanager
def with_db_session():
    max_retries = 3
    retry_delay = 2
    for attempt in range(max_retries):
        session = SessionLocal()
        try:
            yield session
            session.commit()
            break
        except (DisconnectionError, OperationalError) as exc:
            session.rollback()
            session.close()
            if attempt < max_retries - 1:
                time.sleep(retry_delay)
            else:
                raise exc
        finally:
            session.close()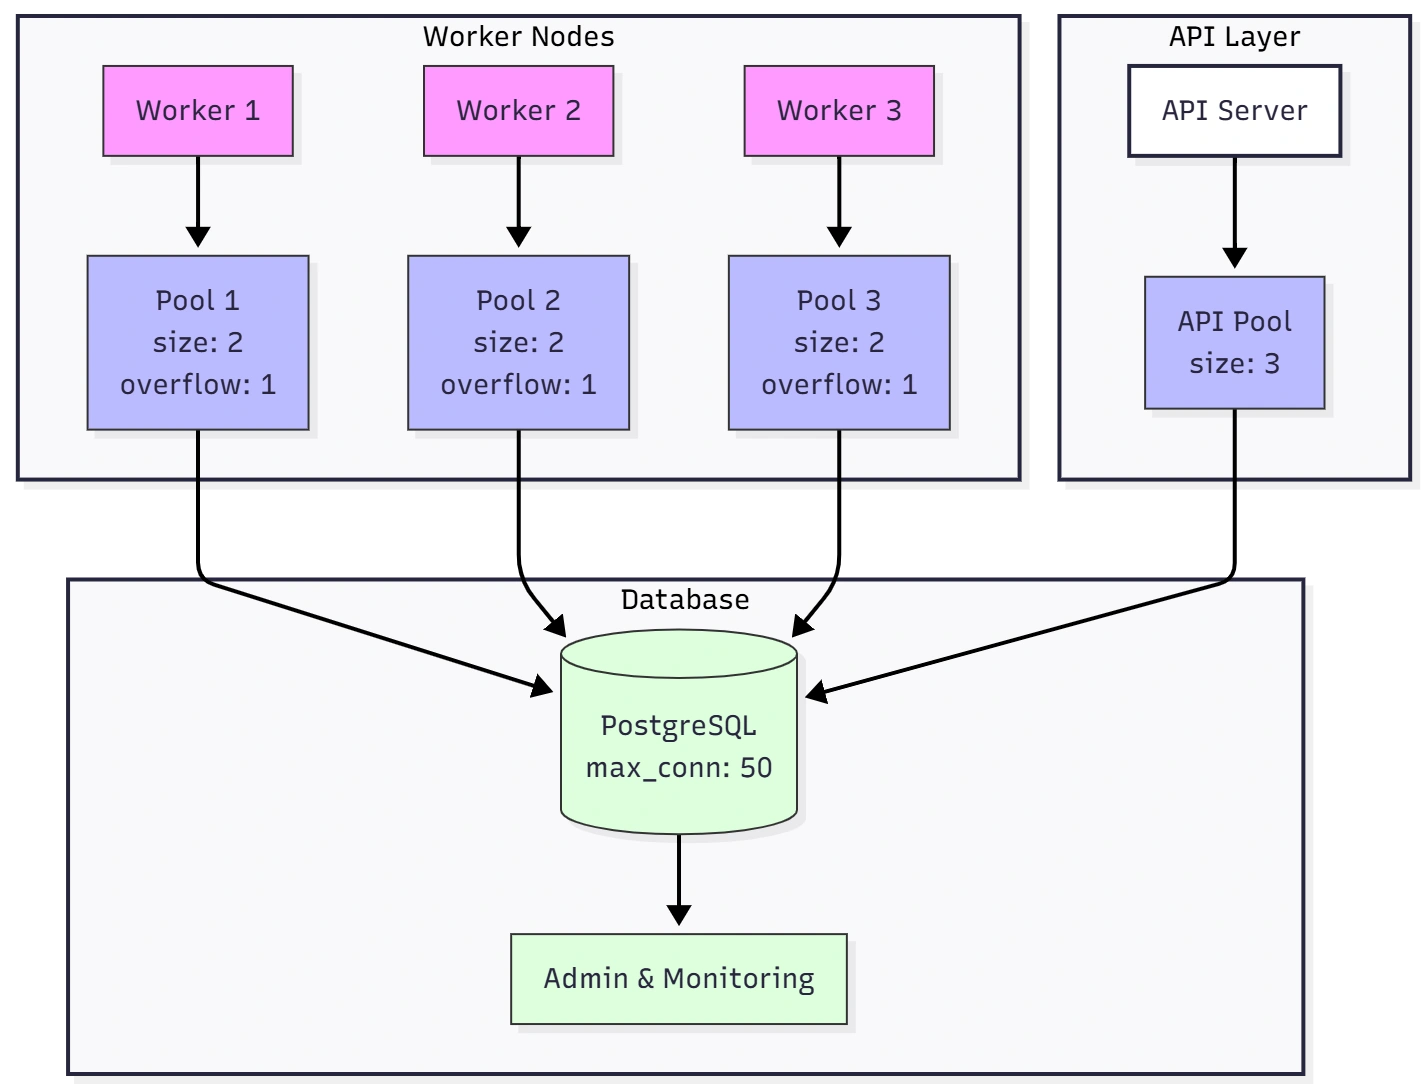
Join the conversation! Your thoughts help the community grow.