
In this article, you will learn what Hash Tables are, and why and where we use them. Hash Table is another kind of data structure to place data elements in a specific arrangement, which is easy to read and write.
To learn Hash Tables effectively, we need to discuss the following aspects of Hash Tables.
- What is Hashing?
- What are Hash Tables and why we use them?
- Collision handling while using Hash Tables?
- Where we Hash Tables?
- Difference between Hash Tables, binary search tree and approach to choose between the two?
What is hashing?
Hash Tables work on the concept of Hashing. Hashing is a process of converting the value from a string space to integer space or an index value or a string, that has a length of fixed size. Hashing is performed by hash functions. Two common hash methods are folding method and cyclic shift, which gives you index for a given key, to be used in Hash Tables. Another category of hash methods are cryptographic hash functions like MD5 and SHA, which gives you fixed size string for a given text, which are used for the security purposes. We are not going to discuss cryptographic hash methods here.
What are Hash Tables and why we use them?
Hash Table is a collection of items in terms of arrays, having special type of an index. An ordinary collection or a table, we can access data quickly, if we know the index of an item because indexes are already sorted by nature.
In the process of hashing a table or collection, we first decide which field or a column is going to be the key field, which will act as an index of Hash Tables. We put that key in some hash function, which gives us an index, which is called as hash value or hash index. Therefore, we place our data at that particular hash index in the table. Each data item in collection is directly mapped to some index ,because we have key and key is an index itself, when a key is processed by hash function. The same thing happens, when we read data from the table.
Therefore, hash is equally efficiently, while reading or writing data.
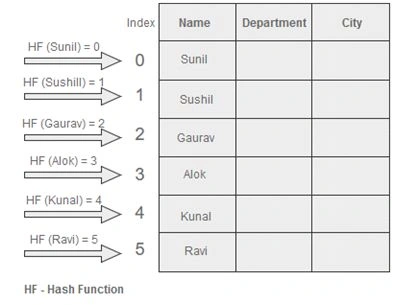
Hash function is a mapping from the input space to the integer space that defines the indices of the array.
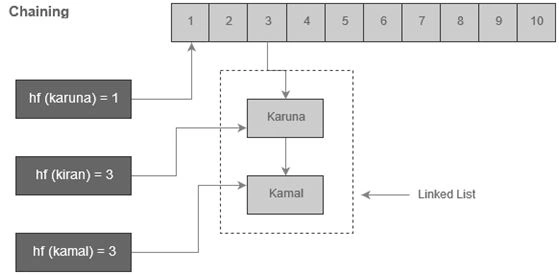
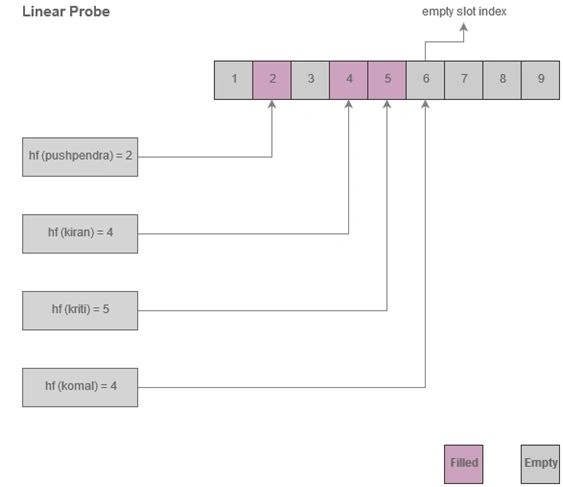
Problem: Now, it is possible that there is a same hash index in the process of assigning index slots for the several keys.
Example:
hf(k1) = 12
hf(k2) = 12
In other words, collision may happen. Then, how will you decide, where to store the data value for that particular key.
So, here comes the need of collision handling.
Collision handling
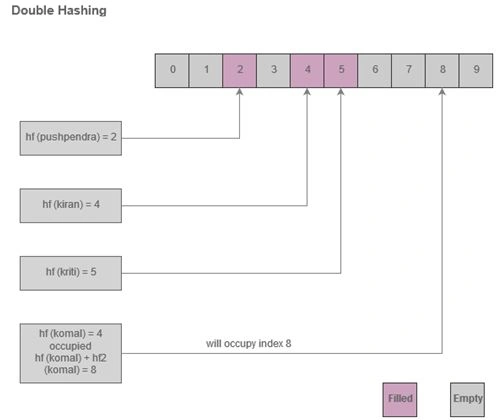
There are different strategies available which resolve this issue. Three main strategies are:
Santhakumar MunuswamyPosted Jun 9, 2016, 12:45 AM
Thank you for nice share
Nataraj Gandhi ArunachalamPosted Jun 6, 2016, 1:12 PM
good one!
Kuppurasu NagarajPosted Jun 6, 2016, 12:05 PM
Nice Sharing..
Sonu ChaudharyPosted Jun 6, 2016, 9:45 AM
good one...
Debasis SahaPosted Jun 6, 2016, 12:20 AM
Good One..
Atul KumarPosted Jun 3, 2016, 2:51 PM
@Afzaal: Thanks! I have already bookmarked your article. Will have look at it.
Afzaal Ahmad ZeeshanPosted Jun 3, 2016, 2:39 PM
Interesting concept, have a look at the similar article that I wrote about hashing the passwords in .NET Core, http://www.c-sharpcorner.com/article/hashing-passwords-in-net-core-with-tips/