
Schrödinger's AI is your invitation to look inside. Right now, AI feels like a mystery , wired like a brain, yet running on pure math.
Each article is a new layer of the box. We start with the first spark of an idea and move all the way to the models reshaping everything we thought we knew .
Part 5: Transformers in AI
And just to be clear, I'm not talking about Optimus Prime or any electronics. This is something completely different: a genius model architecture in AI.
By definition, a transformer is a type of model that's really good at understanding sequences like sentences, code, or music. It's like a better version of the autocomplete algorithm. Instead of looking at words one by one, it pays attention to all the words at once, figuring out which ones matter most for the meaning. There is factor called "attention" which we'll learn in a while.
If I had to give an analogy, I'd say it's like your mom tasting every ingredient in a big pot at the same time and instantly knowing if more salt or chili is needed to make the dish perfect. That's how transformers work: they suggest the next word, but in a mathematically. Let's see how.
Inside a Transformer
1. Self-Attention Mechanism
Instead of reading a sentence word by word, the model looks at all words at once to figure out relationships.
Sentence: "Harry told Ron that he had found the Horcrux."
The model learns that "he" = Harry not Ron, even though they're a few words apart. This helps it understand context properly.
2. Positional Encoding
Transformers read words in parallel, so they don't naturally know the order. Positional encodings tell the model the position of each word.
Sentence: "Voldemort cursed Harry" vs "Harry cursed Voldemort."
Without positional info, the meaning could get completely scrambled. Positional encoding ensures the model knows who did what to whom.
3. Encoder–Decoder Structure
Encoder: A smart reader. It reads and understands the input, figuring out all the details and context.
Decoder: A smart writer (like me). It takes what the encoder understood and generates the output in the target language or format.
Example
Input (English, encoder reads): "Harry needs the invisibility cloak" , The encoder figures out who, what, and the meaning of the sentence.
Output (French, decoder writes): "Harry a besoin de la cape d'invisibilité" , The decoder uses the encoder's understanding to produce correct output.
Use cases
BERT uses only encoder: Just reads and understands text. Perfect for questions like "Who is using the cloak?" or "What spell was cast?"
GPT uses only decoder: Just generates text. Can write new dialogue, spells, or stories, because it predicts the next words based on context.
4. Feedforward Layers and Residual Connections
These are like refinement steps that polish the model's understanding and prevent it from "forgetting" or going off-track.
Example
Imagine passing a blurry photo through multiple filters to sharpen it. Residual connections make sure the original info isn't lost while enhancing it.
How a Transformer Chooses What Happens Next?
Let's take an example,
Say you asked ChatGPT: "What did Harry do?" and then it start doing this in background.
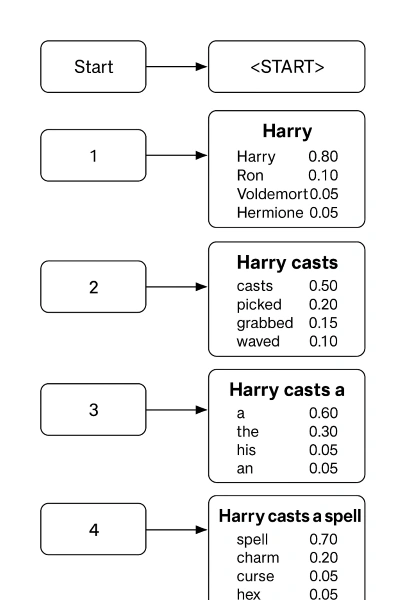
How are these words predicted?
Context understanding
The transformer reads the entire sentence, not just the last word. It knows the subject is "Harry" and that the sentence is asking about an action he performed.Self-attention
It looks at all the words in the sentence simultaneously to figure out relationships. For example, "Harry" + "do" is likely actions might be "cast a spell", "picked", "grabbed", etc.Feedforward & probability calculation
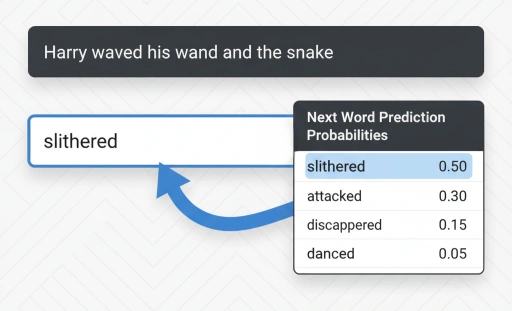
The model calculates a probability distribution over its entire vocabulary for the next word. That's where the numbers come from:
0.50 for "cast" 50% chance the model thinks this is the most likely next word.
0.20 for "picked" 20% chance.
0.15 for "grabbed" 15% chance.
And so on…
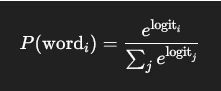
Join the conversation! Your thoughts help the community grow.