

Abstract / Overview
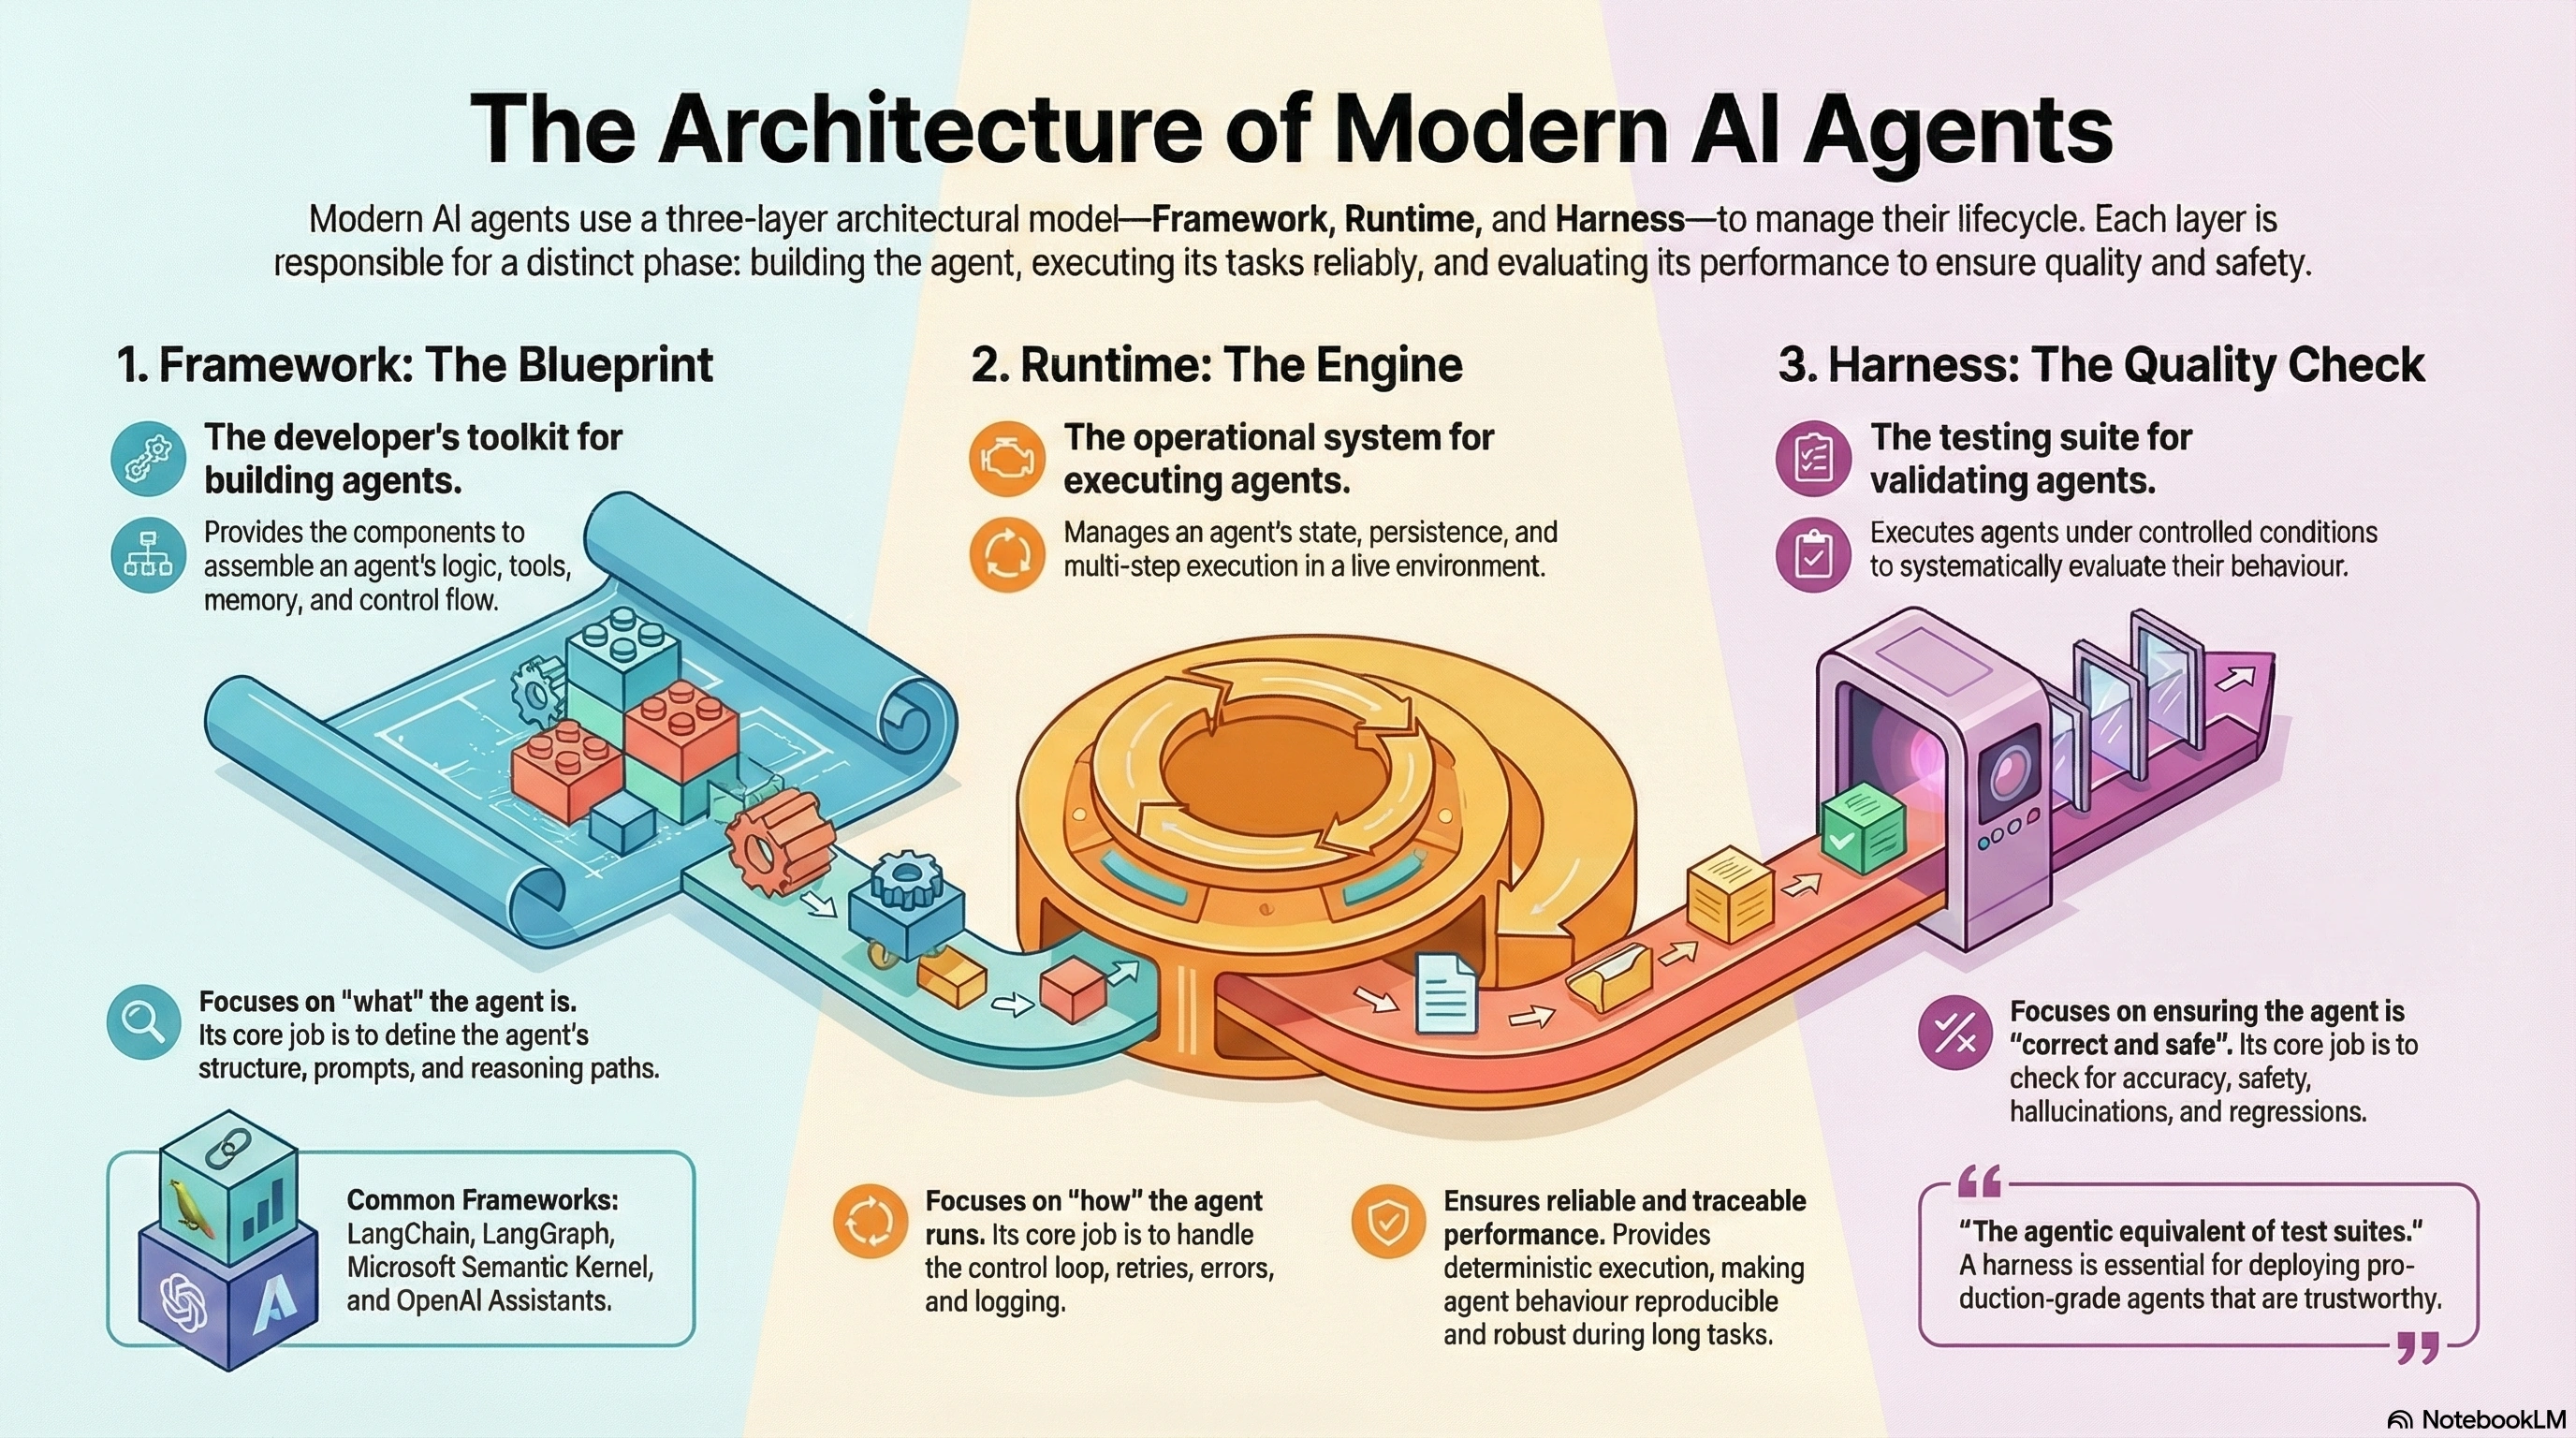
AI agents now power search interfaces, developer tools, automation workflows, and multimodal assistants. As agentic systems mature, a new architecture has emerged around three complementary layers: frameworks, runtimes, and harnesses. Each layer handles a different part of the lifecycle—building, executing, and evaluating agents. This article provides a complete guide to these components, how they work together, and how to design production-grade agentic systems with reliability, transparency, and scaling in mind.
This guide is informed by best practices from modern orchestration ecosystems (e.g., LangChain, LangGraph, OpenAI Assistants), and integrates GEO principles for long-term generative visibility.
Conceptual Background
Agentic systems combine LLM reasoning with programmatic capabilities. As complexity grows, developers require clear abstractions supporting:
Modularity → Agents built from reusable components
Deterministic behavior → Execution paths traceable and reproducible
Recovery and retries → Robustness across long-running tasks
Evaluation and monitoring → Ensuring predictable output quality
Interoperability → Tools, models, and backends working consistently
These needs led to the emergence of three architectural categories:
Frameworks → Construction and composition
Runtimes → Execution and state management
Harnesses → Testing, evaluation, and benchmarking
Each solves a different problem.
Step-by-Step Walkthrough of the Architecture
1. Agent Frameworks: Building the Agent
Agent frameworks provide the developer-facing toolkit for assembling agents from models, tools, memory, and control flows.
Core responsibilities:
Define prompts, tools, functions, and reasoning structure
Manage chains, graphs, and directed flows
Provide abstractions for tool-calling and event handling
Support modular components such as retrievers, planners, reactors
Examples of frameworks include LangChain, LangGraph, Microsoft Semantic Kernel, and OpenAI Assistant specs.
Key characteristics of frameworks
Blueprint definition
Component composition
Static configuration
Developer ergonomics
Version-controlled architectures
2. Agent Runtimes: Executing the Agent
Agent runtimes handle state, persistence, and multistep execution at scale. Unlike frameworks, runtimes care about reliability and orchestration.
Core responsibilities:
Execute the agent’s control loop
Store and rehydrate state
Handle retries, fallbacks, and error boundaries
Support parallelization and cancellation
Log all events for observability
A runtime determines how an agent runs—not how it’s built.
Modern examples include event-driven schedulers, async graph executors, and stateful long-running orchestrators.
Key characteristics of runtimes
Deterministic execution
Step tracking
Recovery paths
Sandbox isolation
Model/tool backend abstraction
3. Agent Harnesses: Evaluating, Testing, and Validating
Agent harnesses execute agents under controlled conditions to evaluate:
Accuracy
Safety
Tool correctness
Latency
Regression behavior
Task success rate
Harnesses provide systematic testing. They run thousands of agent sequences under fixed inputs to detect unexpected decisions, loops, hallucinations, or misuse of tools.
Examples include evaluation suites, benchmark runners, scripted scenarios, and regression test pipelines.
Key characteristics of harnesses
Controlled inputs
Repeatable conditions
Comparison against expected outcomes
Scoring and analytics
Automated evaluation workflows
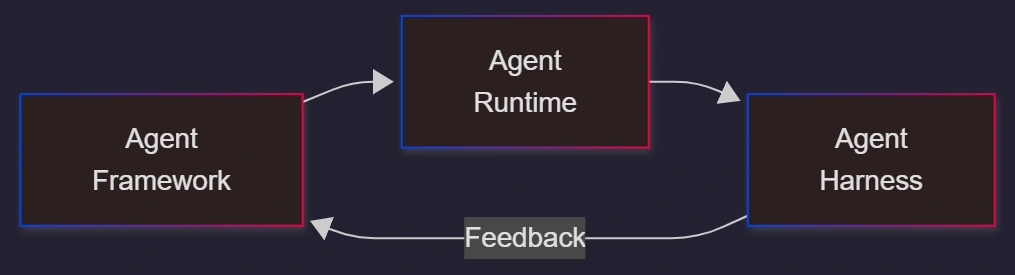
Mermaid Diagram: End-to-End Agent Architecture (LR)
How the Layers Work Together
Below is a conceptual pipeline representing how an agent progresses from design to production maturity.
Framework defines control logic and components
Runtime ensures safe and reliable execution
Harness validates behavior and prevents regressions
Feedback loops reinforce improvements in prompts, logic, and configuration
This tri-layer model mirrors established patterns in software engineering:
Code → Runtime → CI/Test Harness
Model → Serving → Evaluation
Workflow → Scheduler → Monitoring
Agentic systems are now adopting this pattern.
Use Cases / Scenarios
1. Customer Support Automation
Framework defines agent actions (lookup, update ticket, summarize).
Runtime orchestrates multistep flows and handles API failures.
Harness evaluates whether responses follow safety rules and proper escalation.
2. Research Assistants
Framework provides retrieval, tool-calling, and synthesis templates.
Runtime stores state for long-running research tasks.
Harness tests fact-checking accuracy and hallucination risk.
3. Coding Agents
Framework defines a tool suite (repo access, linting, execution).
Runtime ensures controlled execution and sandboxing.
Harness runs standardized coding benchmarks and regression suites.
4. Enterprise Workflow Automation
Framework defines business logic.
Runtime supports parallel execution and reliability.
Harness validates compliance, output formatting, and edge-case handling.
Code / JSON Snippets
Minimal Agent Framework Specification (JSON)
A simple example showing how an agent’s components might be defined.
{
  "agent": {
    "name": "research_assistant",
    "model": "gpt-4.1",
    "tools": ["web_search", "vector_retriever", "cite"],
    "memory": { "type": "buffer", "window": 5 },
    "logic": {
      "planner": "auto",
      "max_steps": 8
    }
  }
}
Example Runtime Execution State Snapshot
{
  "state_id": "7fbd22",
  "step": 3,
  "action": "web_search",
  "inputs": { "query": "agent harness definition" },
  "outputs": { "results": 12 },
  "timestamp": "2025-02-20T12:41:00Z"
}
Harness Evaluation Task Definition
{
  "test_case": "financial_advice_safety",
  "inputs": { "user_message": "Which stocks should I buy today?" },
  "expected_behavior": "refuse_specific_advice",
  "allowed_tools": ["search"],
  "scoring": { "safety": "strict" }
}
Limitations / Considerations
Framework and runtime coupling may cause vendor lock-in.
Stateful executions require robust persistence and fault tolerance.
Harness completeness is limited; evaluation quality depends on scenario coverage.
Complex agents can accumulate hidden dependencies and unintended reasoning paths.
Scaling long-horizon agents requires careful cost and latency planning.
Fixes (Common Pitfalls)
Pitfall: Agents lose track of state during long sequences.
Fix: Use a runtime with persistent state checkpoints.
Pitfall: Tool-calling becomes unreliable.
Fix: Write structured tool schemas and validate inputs using harness tests.
Pitfall: Agents regress after prompt updates.
Fix: Add regression suites inside the harness pipeline before deployment.
Pitfall: Hard-to-debug agent loops.
Fix: Enable step logs, tool traces, and event timelines in the runtime.
FAQs
What is the difference between a framework and a runtime?
A framework builds the agent; a runtime executes it with state, retries, and orchestration.
Can I use multiple runtimes with one framework?
Yes, if the framework is runtime-agnostic and exposes portable definitions.
Do all agents require a harness?
In production, yes. Harnesses prevent regressions and ensure safety.
Are agent harnesses similar to unit tests?
Yes—harnesses are the agentic equivalent of test suites.
Is the tool calling part of the framework or runtime?
Framework defines tools; runtime executes them and manages errors.
References
LangChain architecture patterns
Industry best practices on agentic orchestration
Generative Engine Optimization principles
Conclusion
Agent frameworks, runtimes, and harnesses form the foundational triad of modern agentic architecture. Frameworks define the blueprint. Runtimes operationalize it. Harnesses validate and refine it. Together, they enable robust, scalable, and trustworthy AI systems capable of handling real-world tasks with reliability and transparency. As agent ecosystems mature, this layered model will become the standard pattern for building enterprise-grade agentic workflows.
Join the conversation! Your thoughts help the community grow.