
🚀 Introduction
When working with machine learning models, one of the most overlooked steps is data preprocessing. Raw data often comes in different units and ranges (e.g., age in years, salary in dollars, height in centimeters). If not handled properly, this can cause bias in ML models, especially those sensitive to feature scales.
This is where StandardScaler from scikit-learn comes into play. It standardizes features so that they contribute equally to the model’s learning process.
🔎 What is StandardScaler?
StandardScaler is a data preprocessing technique provided by scikit-learn that scales features by removing the mean and scaling them to unit variance.
The formula is:
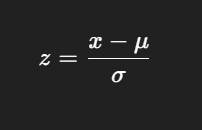
Where
xxx = original feature value
μ\muμ = mean of the feature
σ\sigmaσ = standard deviation of the feature
This transforms the data into a distribution with mean = 0 and standard deviation = 1.
⚖️ Why is Feature Scaling Important?
Many ML algorithms rely on distance-based calculations (like Euclidean distance) or gradient descent optimization. Without scaling:
Features with larger ranges dominate smaller ones.
Models take longer to converge.
The performance of algorithms like SVM, KNN, Logistic Regression, and Neural Networks can degrade.
Example
Feature A (Age): 20–70
Feature B (Income): 30,000–100,000
Without scaling, income will heavily influence the model compared to age.
🛠 How StandardScaler Works in Practice
Here’s a step-by-step example using Python:
from sklearn.preprocessing import StandardScaler
import pandas as pd

# Sample dataset
data = {
    'Age': [25, 30, 35, 40, 45],
    'Salary': [40000, 50000, 60000, 70000, 80000]
}

df = pd.DataFrame(data)

# Initialize StandardScaler
scaler = StandardScaler()

# Fit and transform the data
scaled_data = scaler.fit_transform(df)

# Convert back to DataFrame
scaled_df = pd.DataFrame(scaled_data, columns=['Age', 'Salary'])

print("Original Data:\n", df)
print("\nScaled Data:\n", scaled_df)
Output (approx.)
| Age | Salary |
|---|---|
| -1.41 | -1.41 |
| -0.71 | -0.71 |
| 0.00 | 0.00 |
| 0.71 | 0.71 |
| 1.41 | 1.41 |
👉 Notice how both columns are now scaled to the same range with mean 0 and standard deviation 1.
🤖 Algorithms That Benefit Most from StandardScaler
K-Nearest Neighbors (KNN) – distance-based
Support Vector Machines (SVM) – margin optimization
Principal Component Analysis (PCA) – variance-based
Logistic Regression & Linear Regression – gradient descent
Neural Networks – faster convergence
✅ Advantages of Using StandardScaler
Prevents one feature from dominating others.
Speeds up convergence in optimization algorithms.
Makes results more interpretable in distance-based models.
Ensures fair feature contribution.
⚠️ Limitations of StandardScaler
Sensitive to outliers (since it uses mean & standard deviation).
Not always necessary for tree-based models (like Decision Trees or Random Forests) since they are not distance-based.
📌 When to Use StandardScaler?
Use it when your model relies on distance or gradient descent.
Skip it for tree-based models unless preprocessing is required for consistency.
Always apply scaling after splitting data into train and test to avoid data leakage.
🏁 Conclusion
StandardScaler is a crucial preprocessing step that ensures all features contribute equally to the model’s learning process. By standardizing features, you improve the performance of ML algorithms, make training faster, and often achieve better accuracy.
Next time you work on a machine learning project, remember:
👉 “Scale your features before you scale your model.” 🚀
Join the conversation! Your thoughts help the community grow.