The first Gemma model, launched early last year, has sparked a massive wave of innovation, amassing over 160 million downloads and creating what’s now called the “Gemmaverse.” From safety-focused AI to medical models and community-driven variants like Japanese Gemma from the Institute of Science Tokyo, it’s been a journey of rapid evolution.
And now, Google is taking the next big step.
Say Hello to Gemma 3n
After teasing us with a preview last month, Google has officially launched Gemma 3n, a powerful mobile-first AI architecture. Designed for developers, this new model is fully optimized for on-device performance while supporting multimodal capabilities—text, image, video, and audio.
You can fine-tune and deploy it using tools you already love: Hugging Face Transformers, llama.cpp, Google AI Edge, Ollama, MLX, and more.
Let’s break down what’s new.
What Makes Gemma 3n Special?
Multimodal by Design: Gemma 3n can understand and generate from text, images, videos, and audio, all directly on your device.
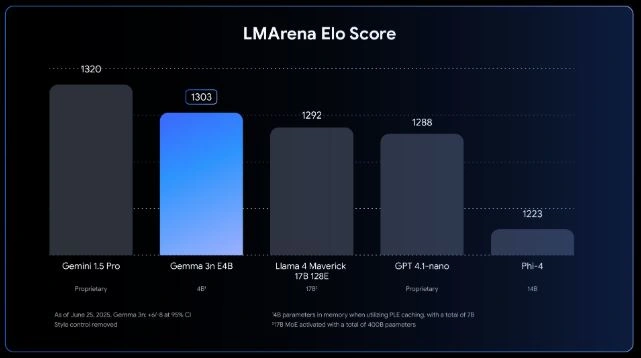
Two Sizes, Big Impact: Available in E2B (5B parameters) and E4B (8B parameters) sizes, the models are optimized to run on just 2GB or 3GB of memory, thanks to smart architectural tricks.
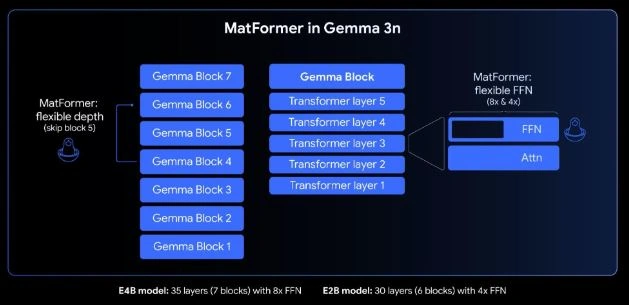
MatFormer Architecture: Like Nested Dolls: At the heart is MatFormer—a "Matryoshka Transformer" that contains smaller models inside a larger one. You can use the full E4B model or a faster E2B variant already extracted. Want something in between? Use Mix-n-Match to custom-size your model based on hardware needs.
Per-Layer Embeddings (PLE): These allow large models to run on smaller devices by offloading embeddings to the CPU, while keeping core transformer weights in GPU/TPU memory.
KV Cache Sharing: For long audio/video sequences, this new technique improves inference speed by 2x, cutting delay before you get a response.
Built-In Audio Understanding
Using a version of Google’s Universal Speech Model (USM), Gemma 3n enables.
Speech-to-text (ASR) directly on the device.
Speech translation (AST) for languages like English, Spanish, French, and Italian.
Support for audio clips up to 30 seconds today (longer clips coming soon).
Meet MobileNet-V5: A Vision Powerhouse
Gemma 3n features the brand-new MobileNet-V5-300M, delivering real-time image and video analysis. Key benefits.
Supports resolutions from 256x256 to 768x768
Handles 60 FPS on a Pixel device
13x faster than its predecessor with lower memory usage
Outperforms many cloud models in vision-language tasks
This is achieved through smart design: a deeper, wider pyramid model, distillation techniques, and a new fusion adapter for better token quality.
Developer-First, Community-Driven
From AMD to Hugging Face, Docker, RedHat, and many more—Gemma 3n is supported across your favorite open-source tools. It’s built with and for the developer community.
To celebrate this, Google is launching the Gemma 3n Impact Challenge. With $150,000 in prizes, it’s inviting devs to create on-device AI solutions that make a real-world difference.
Download the models: Available on Hugging Face and Kaggle
Explore the docs: Fine-tuning, inference, and deployment guides are available
Use your favorite tools: From Transformers to llama.cpp, Ollama, MLX, and more
Deploy anywhere: Cloud Run, Vertex AI, GenAI API, NVIDIA API Catalog, and more
Final Thoughts
Gemma 3n isn’t just another AI release—it’s a big leap in making advanced, multimodal AI truly portable. Whether you're building the next smart app, translating real-time audio, or designing edge vision systems, this model gives you the power to build—and deploy—intelligently, right from your device.
With the open challenge, Google is making it clear: AI’s future is not just cloud-first, it's device-ready.

Join the conversation! Your thoughts help the community grow.