
We’re excited to launch three new models in the API: GPT-4.1, GPT-4.1 mini, and GPT-4.1 nano.
These models are better than the previous GPT-4o and GPT-4o mini in every way, especially in coding and following instructions. They can also handle much longer text up to 1 million tokens and understand that long context better than before. Their knowledge is up to date until June 2024.
How GPT-4.1 Excel?
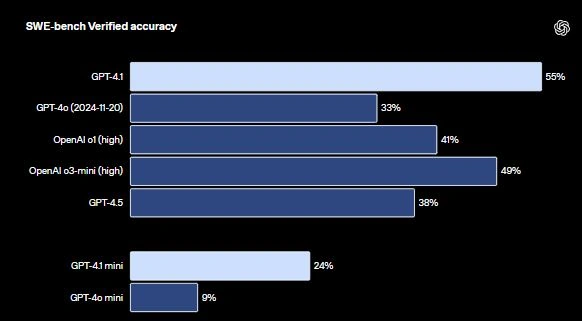
Coding: GPT-4.1 scores 54.6% on the SWE-bench Verified test, which is 21.4% higher than GPT-4o and 26.6% higher than GPT-4.5, making it one of the best models for coding tasks.
Following Instructions: On Scale’s MultiChallenge benchmark (which tests instruction following), GPT-4.1 scored 38.3%, improving by 10.5% over GPT-4o.
Long Context Understanding: On the Video-MME benchmark, GPT-4.1 scored 72% for understanding long videos without subtitles, a 6.7% improvement over GPT-4o.
These benchmarks show the model’s power, but the biggest goal was real-world usefulness. We worked closely with developers to optimize GPT-4.1 for the tasks that matter most.
Performance and Cost Benefits
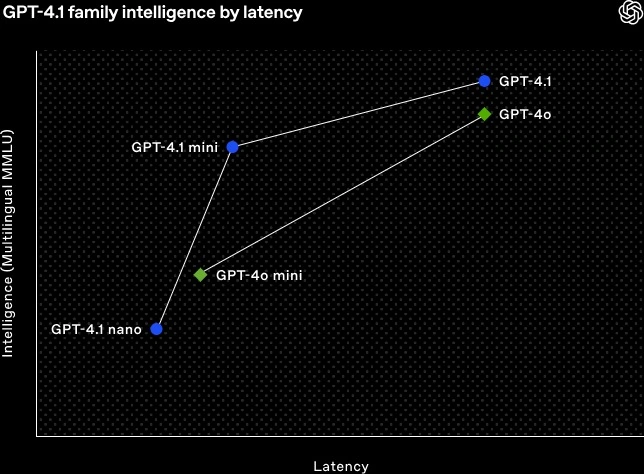
The GPT-4.1 family performs better but costs less.
- GPT-4.1 mini is a big step forward in small models it beats GPT-4o in many tests, runs nearly twice as fast, and costs 83% less.
- GPT-4.1 nano is the fastest and cheapest model, perfect for tasks needing quick responses like classification or autocompletion. It still delivers excellent performance, beating GPT-4o mini in several benchmarks.
Better Agents and Real-World Use
The improvements in instruction following and understanding long contexts also make GPT-4.1 great for building agent systems that work independently to complete tasks. Combined with tools like the Responses API, developers can create agents that handle complex software engineering, analyze large documents, and resolve customer issues with less supervision.
Availability and Transition
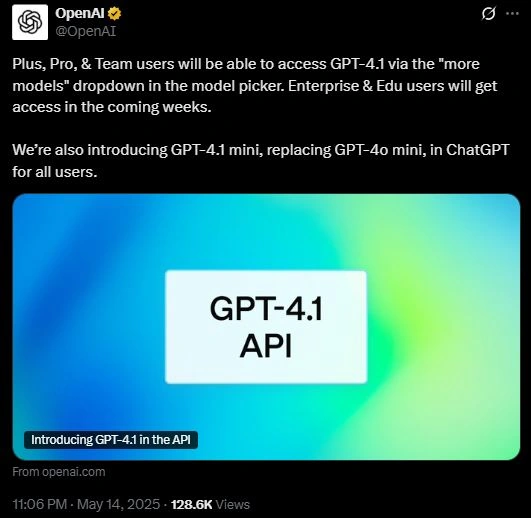
GPT-4.1 is available only via API. ChatGPT users will see many GPT-4.1 improvements gradually added to GPT-4o.
We will retire GPT-4.5 Preview on July 14, 2025, because GPT-4.1 matches or beats its performance at lower cost and latency. GPT-4.5 was a research model to test new ideas, and the lessons learned will continue to improve future models.
Detailed Highlights
- Coding: GPT-4.1 is much better at coding tasks like solving coding problems, frontend web coding, and making fewer unnecessary edits. For example, on SWE-bench Verified (a real-world coding test), GPT-4.1 solves 54.6% of tasks, compared to 33.2% for GPT-4o. It is also better at making code changes efficiently, doubling GPT-4o’s score on Aider’s polyglot diff benchmark.
- Frontend Web Apps: GPT-4.1 creates more functional and nicer-looking web apps than GPT-4o, and testers prefer its outputs 80% of the time.
GPT4.o
GPT4.1
Real-world feedback
- Windsurf reported 60% higher coding benchmark scores and a 30% boost in tool efficiency.
- Qodo found that GPT-4.1 gave better code review suggestions in 55% of cases, with improved precision and focus on important issues.
Instruction Following
GPT-4.1 follows instructions more reliably, including tricky cases like,
- Formatting responses in XML, YAML, or Markdown
- Avoiding behaviors developers don’t want
- Following multi-step ordered instructions
- Including specific content when required
- Saying “I don’t know” when unsure
It scored much higher on hard instruction prompts than GPT-4o and is better at keeping track of multi-turn conversations.
Real-world testers
- Blue J’s tax research improved by 53% accuracy with GPT-4.1, helping users handle complex regulations faster.
- Hex saw almost twice the accuracy on their toughest SQL tasks, with less manual debugging needed.
Long Context
All GPT-4.1 models handle up to 1 million tokens (more than 8 times the previous limits). This helps with very large codebases, documents, or long conversations. GPT-4.1 reliably finds important details anywhere in the long input.
We also introduced a new test (OpenAI-MRCR) to check if the model can disambiguate multiple similar requests spread across a long context. GPT-4.1 outperforms GPT-4o even at the largest context sizes, though it remains a hard challenge.
Conclusion
GPT-4.1, GPT-4.1 mini and GPT-4.1 nano represent a big step forward in AI performance, especially for coding, instruction following, and understanding long contexts. They provide better results, faster responses, and lower costs, making them ideal for developers building real-world applications. These models enable more powerful and reliable AI agents that can handle complex tasks with less human help. With the phase-out of GPT-4.5 Preview, GPT-4.1 becomes the new standard for API users.
Overall, GPT-4.1 brings the best balance of intelligence, speed, cost-efficiency, and reliability setting a new foundation for future AI-powered tools and applications.
Join the conversation! Your thoughts help the community grow.