
Previous Article
What is Apache Kafka?
Apache Kafka is an open-source distributed event streaming platform used for building real-time data pipelines and streaming applications. Originally developed by LinkedIn and later open-sourced as an Apache Software Foundation project, Kafka provides a scalable, fault-tolerant, and high-throughput platform for handling real-time data feeds.
Key features of Apache Kafka
- Publish-Subscribe Messaging System: Kafka follows the publish-subscribe messaging pattern. Producers publish messages to topics, and consumers subscribe to those topics to receive messages.
- Distributed: Kafka is designed to be distributed across multiple nodes or clusters for scalability and fault tolerance. It allows you to horizontally scale your system by adding more broker nodes.
- Partitioning: Topics in Kafka are divided into partitions, which allow data to be distributed and processed in parallel across multiple nodes. Each partition can be hosted on a different broker.
- Durability: Kafka is designed for durability, meaning that once data is written to a partition, it persists and can be retrieved even if a broker or node fails.
- Fault Tolerance: Kafka provides fault tolerance by replicating data across multiple brokers. If a broker fails, another broker can take over the responsibility of serving the data.
- High Throughput: Kafka is known for its high throughput and low-latency capabilities, making it suitable for use cases that require real-time data processing.
- Connectivity: Kafka has client libraries for various programming languages, making it easy to integrate with different applications and systems.
- Streaming APIs: Kafka includes streaming APIs that allow developers to build stream processing applications, enabling the transformation and analysis of data in real time.
- Ecosystem: Kafka has a rich ecosystem that includes connectors for integrating with various data sources and sinks, as well as tools like Kafka Streams for building stream processing applications.
What is Dapr?
Dapr, or Distributed Application Runtime, is an open-source runtime that simplifies the development of microservices and distributed applications. It provides a set of building blocks, libraries, and best practices for developers to build scalable, resilient, and portable applications. Dapr abstracts away the complexities of distributed systems, allowing developers to focus on building business logic rather than dealing with the intricacies of distributed architectures.
Key features and components of Dapr
- Service Invocation: Dapr enables microservices to invoke each other using a simple and consistent API, abstracting away the underlying communication mechanisms (HTTP, gRPC, etc.).
- State Management: Dapr provides a distributed state management API, allowing applications to store and retrieve state consistently across multiple microservices.
- Pub/Sub Messaging: Dapr supports the publish-subscribe pattern for messaging, allowing microservices to communicate asynchronously through events.
- Event-driven Programming Model: Dapr promotes an event-driven programming model, where microservices can publish and subscribe to events, enabling loosely coupled architectures.
- Secrets Management: Dapr provides a secrets management API for securely accessing sensitive information, such as API keys, connection strings, etc.
- Bindings: Dapr introduces the concept of bindings, which allows microservices to interact with external systems (like databases, message brokers, etc.) through a simple and consistent API.
- Middleware: Dapr supports middleware, allowing developers to add cross-cutting concerns (like authentication, logging, and tracing) to their applications.
- Actors: Dapr includes an actor model for building stateful microservices, providing a programming model similar to frameworks like Microsoft Orleans.
- Observability: Dapr integrates with popular observability tools, making it easier to monitor and trace microservices in production.
- Cross-language and Cross-framework: Dapr is designed to be language-agnostic and can be used with any programming language. It also integrates with various frameworks and platforms.
- Cloud Agnostic: Dapr is cloud-agnostic, allowing applications to be deployed across various cloud providers or on-premises environments.
- Open Source and Community-Driven: Dapr is an open-source project with an active community of contributors. It is part of the Cloud Native Computing Foundation (CNCF).
What is Dapr Bindings?
Dapr Bindings are a set of abstractions and building blocks that simplify the integration of Dapr applications with external services, systems, and events. Bindings provides a consistent and language-agnostic way for Dapr applications to interact with various external resources without having to worry about the underlying implementation details of each specific service.
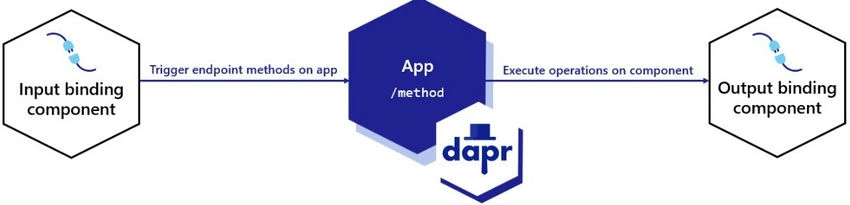
Key features and concepts of Dapr Bindings include
- Abstraction Layer: Bindings abstract away the complexity of working with external services by providing a standard programming model. Developers interact with the bindings using a consistent API regardless of the specific service being used.
- Supported Bindings: Dapr comes with built-in bindings for various external systems, including message brokers (like Kafka and RabbitMQ), databases (like Azure Cosmos DB and MongoDB), and other services (like Azure Blob Storage and Twilio). Additional bindings can be created and added by the community.
- Input and Output Bindings
- Input Bindings: Allow Dapr applications to consume events or data from external sources.
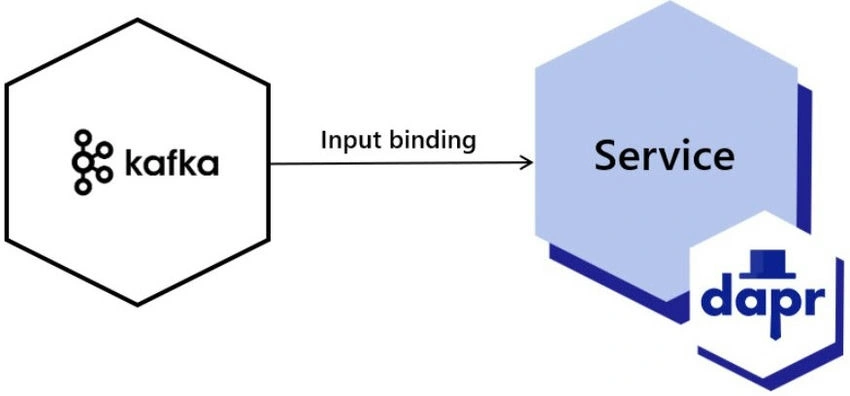
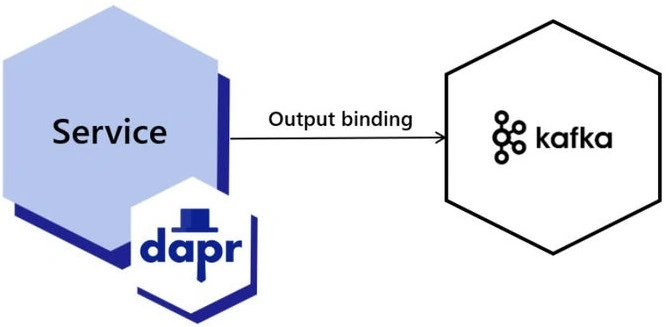
- Output Bindings: Enable Dapr applications to send events or data to external destinations.
- Input Bindings: Allow Dapr applications to consume events or data from external sources.
- Configuration: Bindings are configured through Dapr's configuration files (YAML or JSON). Configuration specifies details such as the type of binding, connection parameters, and other settings.
- Language-Agnostic: Dapr Bindings are designed to be language-agnostic. Whether you're writing your microservices in Java, .NET, Python, or any other supported language, you can interact with bindings using a consistent API.
- Event-Driven Model: Bindings are inherently event-driven. They allow Dapr applications to consume and produce events using the publish-subscribe pattern. This aligns well with Dapr's broader event-driven programming model.
- Extension Points: Developers can create custom bindings for their specific needs or integrate with services not covered by the built-in bindings. This flexibility allows Dapr to be extensible and adaptable to various scenarios.
Benefits of using Dapr Bindings for Kafka
- Consistent Abstraction: Dapr Bindings abstracts away the complexities of interacting with Kafka, providing a consistent programming model across different languages and platforms.
- Input and Output Bindings: Dapr supports both Input and Output Bindings for Kafka.
- Input Bindings: Allow Dapr applications to consume events from Kafka topics.
- Output Bindings: Enable Dapr applications to produce events to Kafka topics.
- Event-Driven Programming: Dapr promotes an event-driven programming model, and Kafka fits well into this paradigm. Applications can publish events to Kafka topics or subscribe to topics to consume events.
- Configuration with Dapr Components: Kafka bindings are configured through Dapr components using YAML or JSON files. Configuration includes details such as Kafka brokers, topics, and authentication settings.
- Language-Agnostic: Dapr Bindings are designed to be language-agnostic. Whether you're using Java, .NET, Python, or other supported languages, you can interact with Kafka bindings using a consistent API.
- Built-In Kafka Binding: Dapr comes with a built-in Kafka binding that simplifies the configuration and interaction with Kafka topics. Developers can use this binding out of the box or create custom bindings for specific use cases.
- Event Sourcing and Stateful Processing: Kafka can be used for event-sourcing architectures, where changes to the state of an application are captured as events. Dapr's state management and actors can complement Kafka in building stateful microservices.
- Flexibility and Extensibility: Dapr Bindings provide flexibility and extensibility. Developers can use the built-in Kafka binding or create custom bindings for unique scenarios, allowing Dapr to integrate with a wide range of services and systems.
- Fault Tolerance and Scalability: Kafka's built-in features for fault tolerance and scalability align well with Dapr's goals. Dapr applications can benefit from Kafka's distributed and resilient nature.
- Integration with Dapr Ecosystem: Kafka bindings seamlessly integrate with the broader Dapr ecosystem, including service invocation, state management, and other Dapr building blocks. This allows developers to build comprehensive and scalable distributed applications.
Let's start implementing Kafka with Dapr Bindings using .Net
Prerequisites: To get started with Dapr, the system has to be installed with Dapr CLI. Refer to the link 'Install-dapr' to install dapr.
Step 1. Setting up Kakfaand running at your system.
Follow steps 1 - 5 from my previous article, "Introduction to Apache Kafka with .Net" which has details of setting up the Kafka.
Step 2. Now, let's create a WebAPI project with .Net Minimal API.
Step 3. Install the below NuGet packages for the project.
- Dapr.AspNetCore
- modeling
Step 4. Create a folder called Components and place it below yaml files. These YAML files are used by Dapr for input and output bindings.
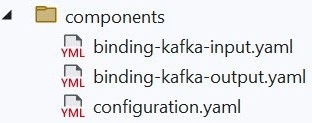
- binding-kafka-input.yaml
Use Dapr input bindings to trigger event-driven applications. With input bindings, you can trigger your application when an event from an external resource occurs. An external resource could be a queue, messaging pipeline, cloud service, filesystem, etc. An optional payload and metadata may be sent with the request. Input bindings are ideal for event-driven processing, data pipelines, or generally reacting to events and performing further processing. Dapr input bindings allow you to. - Receive events without including specific SDKs or libraries
- Replace bindings without changing your code
- Focus on business logic and not the event resource implementation
Within the metadata section, configure the following Kafka-related properties - The topic to which you’ll publish the message
- The broker
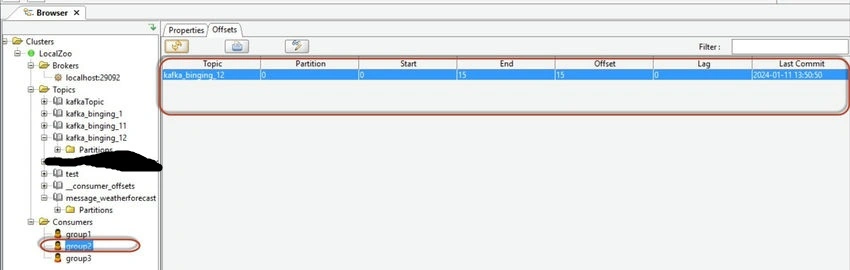
As mentioned above, below is the configuration for Dapr Input binding. This YAML file consists of info about Kafka Broker, Kafka Topic, Group, Direction, and authentication type.apiVersion: dapr.io/v1alpha1 kind: Component metadata: name: kafka-binding-input spec: type: bindings.kafka version: v1 metadata: # Kafka broker connection setting - name: brokers value: "localhost:29092" # consumer configuration: topic and consumer group - name: topics value: "kafka_binging_11,kafka_binging_12" - name: consumerGroup value: "group2" - name: authRequired value: "false" - name: authType value: "none" - name: initialOffset # Optional. Used for input bindings. value: "newest" - name: version # Optional. value: "2.0.0" - name: direction value: "input" - binding-kafka-output.yaml
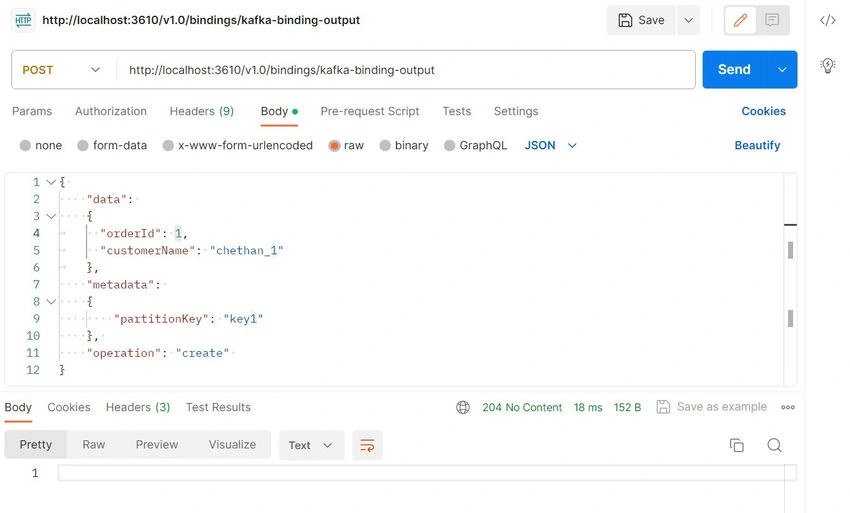
Invoke external systems with output bindings. With output bindings, you can invoke external resources. An optional payload and metadata can be sent with the invocation request. Within the metadata section, configure the following Kafka-related properties. - The topic to which you’ll publish the message
- The broker
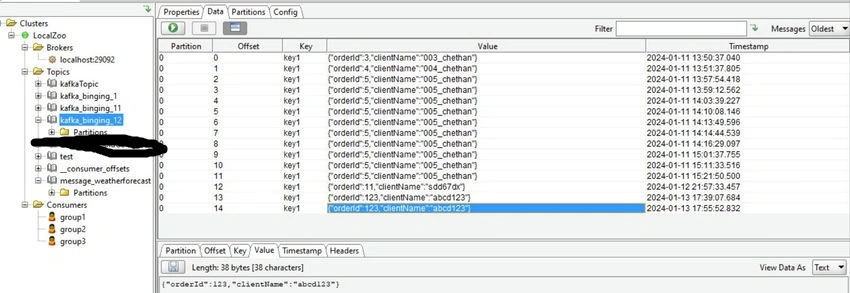
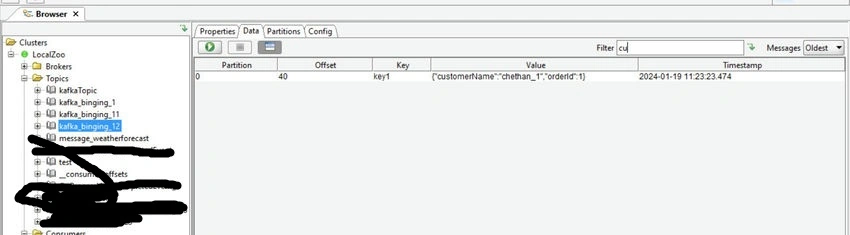
As mentioned above, below is the configuration for Dapr Output binding. This YAML file consists of info about Kafka Broker, Kafka Topic, Direction, and authentication type.apiVersion: dapr.io/v1alpha1 kind: Component metadata: name: kafka-binding-output spec: type: bindings.kafka version: v1 metadata: # Kafka broker connection setting - name: brokers value: "localhost:29092" # publisher configuration: topic - name: publishTopic value: "kafka_binging_12" - name: authRequired value: "false" - name: authType value: "none" - name: direction value: "output"

Join the conversation! Your thoughts help the community grow.