
When building Retrieval-Augmented Generation (RAG) systems, junior developers obsess over the LLM. Senior engineers obsess over the chunking strategy.
You can use the most advanced LLM in the world, but if your chunking strategy destroys the semantic and structural context of your documents, your RAG pipeline will fail. In large, complex domain knowledge bases, naive chunking (like blindly splitting text every 500 tokens) is a death sentence for accuracy.
Today, we will explore how to choose and implement an advanced chunking strategy for massive, highly structured domain knowledge, and how to orchestrate the retrieval of those chunks using LangGraph.
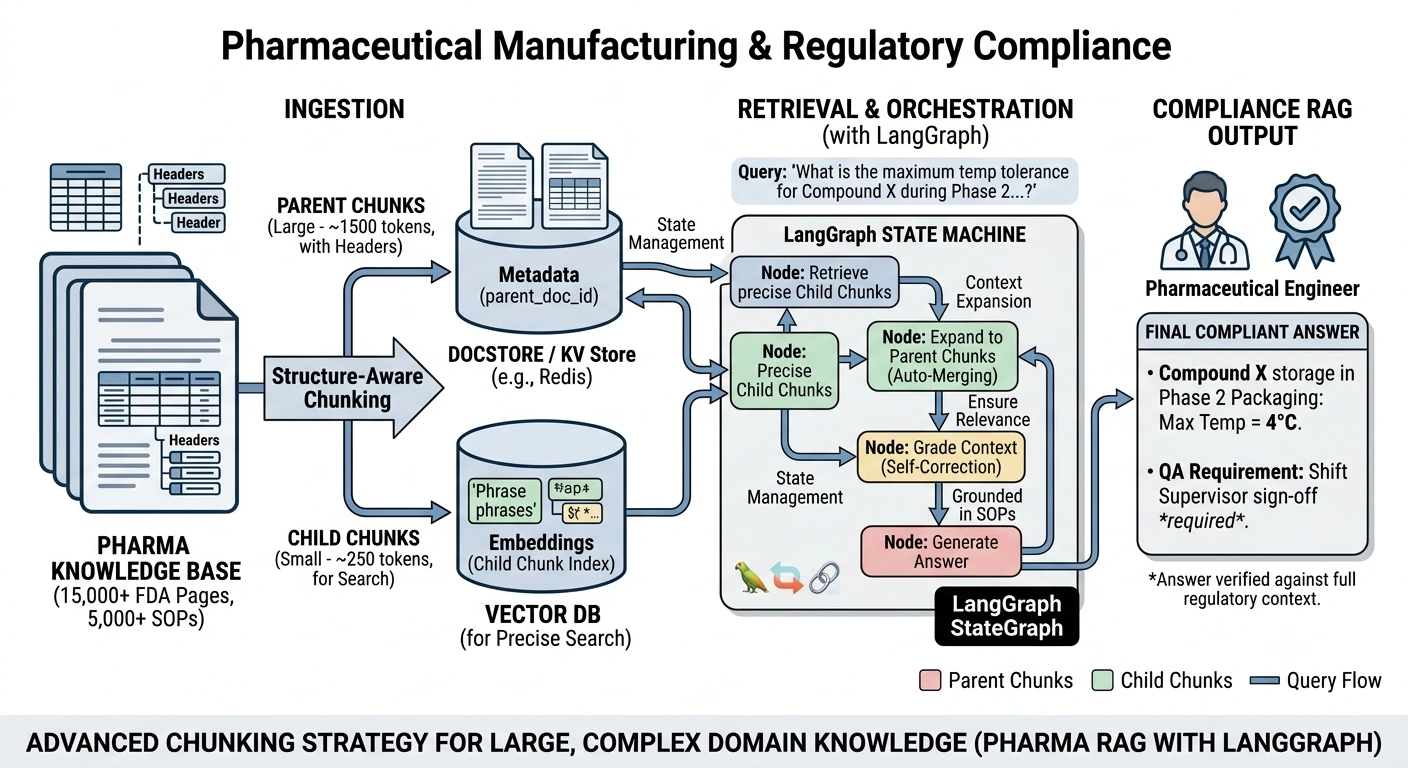
The Real-Time Use Case: Pharmaceutical Manufacturing & Regulatory Compliance
Imagine you are the Lead AI Architect for a global pharmaceutical company. You are building a Manufacturing Copilot for plant engineers and quality assurance (QA) teams.
The Knowledge Base:
15,000+ pages of FDA regulatory guidelines.
5,000+ Standard Operating Procedures (SOPs) for drug synthesis and packaging.
Highly structured data: Nested headings, complex parameter tables, and strict hierarchical workflows.
The Problem:
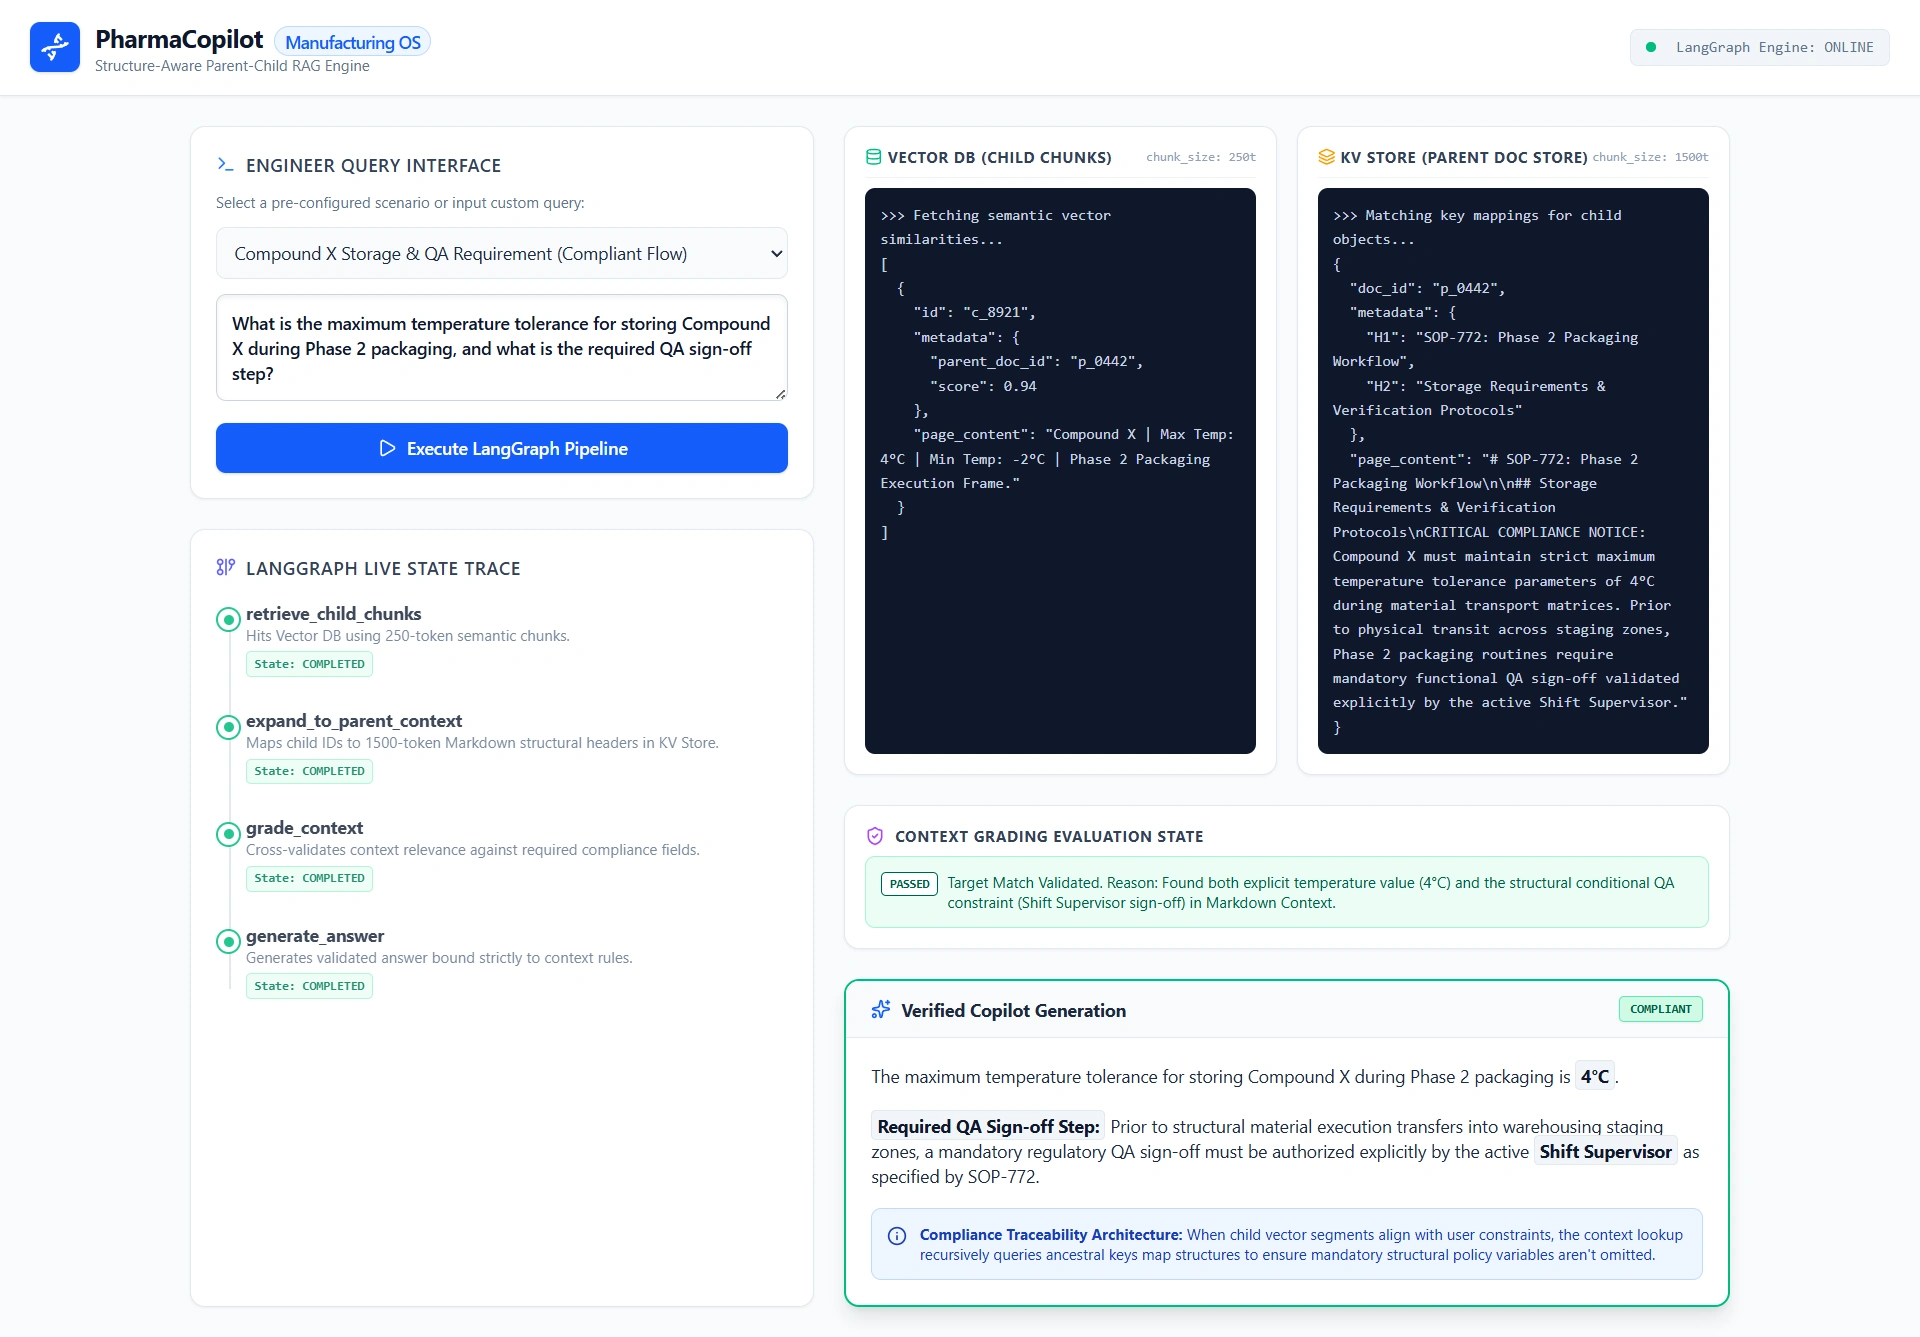
An engineer asks: "What is the maximum temperature tolerance for storing Compound X during Phase 2 packaging, and what is the required QA sign-off step?"
If you use a naive RecursiveCharacterTextSplitter, the text is chopped alphabetically. The "Storage Requirements" table gets separated from the "Phase 2 Packaging" heading. The LLM receives a fragmented table without context and hallucinates a temperature, or worse, misses the QA sign-off requirement entirely. In pharma, this isn't just a bad user experience; it's a compliance violation.
Choosing the Winning Chunking Strategy
For large, structured domain knowledge bases, we must abandon naive splitting. We need a hybrid approach: Structure-Aware Chunking combined with Parent-Child (Auto-Merging) Retrieval.
1. Structure-Aware Chunking (The Ingestion Phase)
Instead of splitting by character count, we split by document structure. We use Markdown headers to understand the hierarchy.
A chunk isn't just a block of text; it retains its metadata:
{"H1": "Phase 2 Packaging", "H2": "Storage Requirements"}.This ensures that a table about temperature is permanently bound to the context of "Phase 2 Packaging".
2. Parent-Child / Auto-Merging (The Retrieval Phase)
This is the secret weapon for enterprise RAG.
Child Chunks (Small - ~250 tokens): We embed these small, highly specific chunks into the Vector Database. This ensures high precision in semantic search.
Parent Chunks (Large - ~1500 tokens): We store the larger, context-rich chunks in a fast Key-Value store (like Redis).
The Magic: When a user queries the system, we search the Child chunks. But instead of passing the tiny child chunk to the LLM, we fetch its corresponding Parent chunk. The LLM gets the precise match plus the full surrounding context.
End-to-End Architecture with LangGraph
While ingestion is often a batch process, the retrieval and generation of Parent-Child chunks requires complex state management. This is where LangGraph shines.
We will build a LangGraph RAG pipeline that:
Retrieves the precise Child chunks.
Expands the context by fetching the Parent chunks.
Grades the expanded context for relevance.
Generates the final answer.
Step 1: Define the LangGraph State
from typing import TypedDict, List, Literal
from langchain_core.documents import Document

class PharmaRAGState(TypedDict):
    query: str
    child_documents: List[Document]      # Small, precise chunks from Vector DB
    parent_documents: List[Document]     # Large, context-rich chunks from KV Store
    final_context: List[Document]        # The context actually passed to the LLM
    answer: str
Step 2: The Ingestion Strategy (Conceptual Setup)
Before querying, we set up the Parent-Child index using LangChain's ParentDocumentRetriever.
from langchain.retrievers import ParentDocumentRetriever
from langchain.storage import InMemoryStore # Use Redis in production
from langchain_text_splitters import MarkdownHeaderTextSplitter, RecursiveCharacterTextSplitter

# 1. Structure-aware splitter (Headers)
header_splitter = MarkdownHeaderTextSplitter(headers_to_split_on=[("#", "H1"), ("##", "H2")])

# 2. Child splitter (Small chunks for precise vector search)
child_splitter = RecursiveCharacterTextSplitter(chunk_size=250, chunk_overlap=20)

# Initialize the Parent-Child Retriever
parent_child_retriever = ParentDocumentRetriever(
    vectorstore=vector_db,
    docstore=InMemoryStore(), # Maps child IDs to Parent chunks
    child_splitter=child_splitter,
    parent_splitter=header_splitter
)
# Add documents to the pipeline
parent_child_retriever.add_documents(raw_pharma_docs)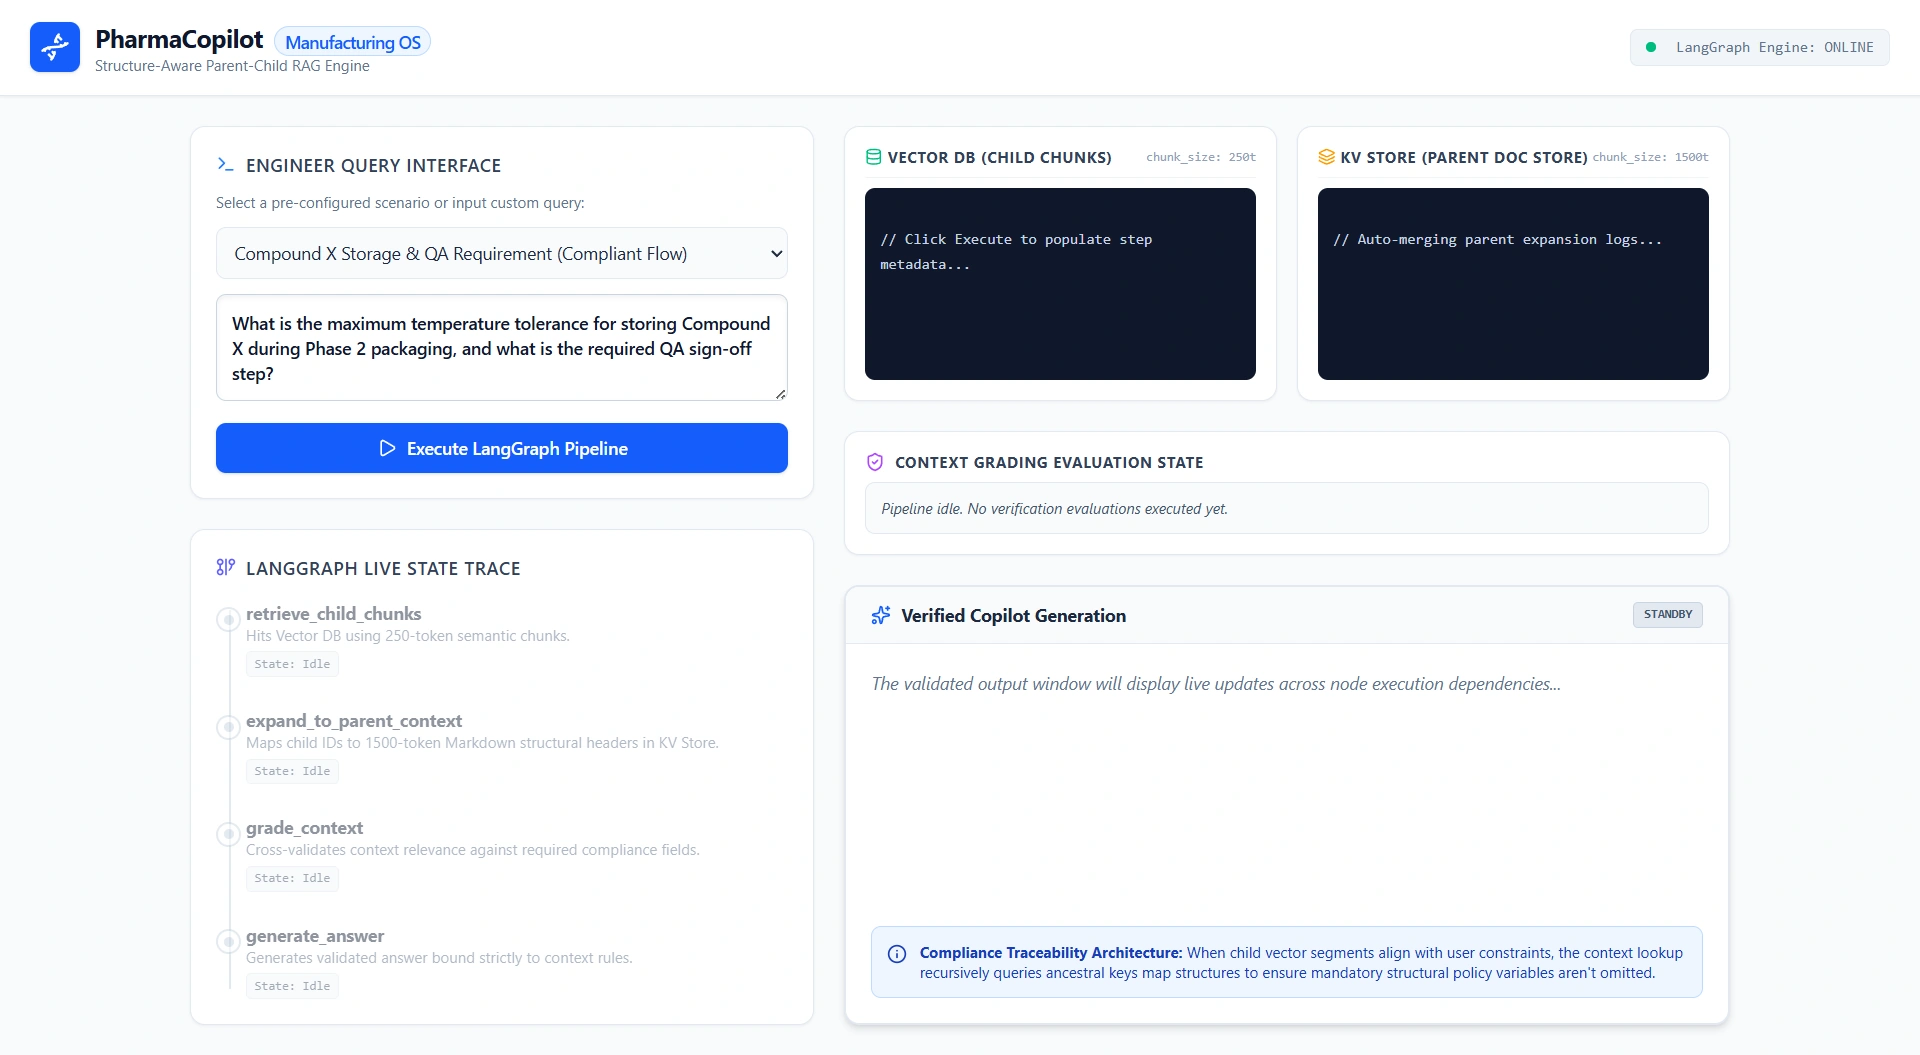
Join the conversation! Your thoughts help the community grow.