
In capital markets, collaborative filtering (CF) and behavioral models excel at pattern recognition: "Traders who executed NVDA blocks like this typically used Implementation Shortfall." But they fail catastrophically at causal reasoning: why that algo worked, whether current market microstructure supports it, and how clearing/settlement constraints modify the optimal choice. CF sees correlations; semantic retrieval understands mechanisms. This article demonstrates how to architect a hybrid recommender where semantic RAG provides the explanatory, constraint-aware reasoning layer that behavioral models lack—unified within a single LangGraph multi-agent system spanning both Order Execution and Clearing & Settlement modules.
The Real-Time Use Case: Cross-Module Execution-to-Settlement Advisor
Scenario: A trader needs to execute a €45M block of French equities while simultaneously ensuring T+2 settlement feasibility across Euroclear and domestic CSDs. Query: "Optimal execution strategy for BNP Paribas 600K shares considering current liquidity, upcoming ex-dividend date, and our failing trade exposure at Euroclear?"
Why Pure Behavioral Models Fail Here
CF recommends algos based on historical fills but ignores that tomorrow is ex-dividend (settlement risk changes fundamentally).
Behavioral models learn trader preferences but can't reason about CCP margin requirements or CSD cut-off times.
Neither module communicates: execution choices create settlement obligations that may breach collateral limits.
Why Pure Semantic RAG Fails Here
Retrieves relevant policies and market context but lacks personalized execution patterns from this specific trader/desk.
Can't leverage years of fill data to calibrate which strategies actually minimize implementation shortfall for this name.
Too slow and unstructured for real-time pre-trade decisions.
The Solution: A hybrid architecture where behavioral models generate candidate recommendations and semantic RAG validates, constrains, and explains them using real-time market state, regulatory corpus, and settlement infrastructure knowledge—all orchestrated by LangGraph with persistent cross-module state.
Part 1: The Hybrid Architecture Principle
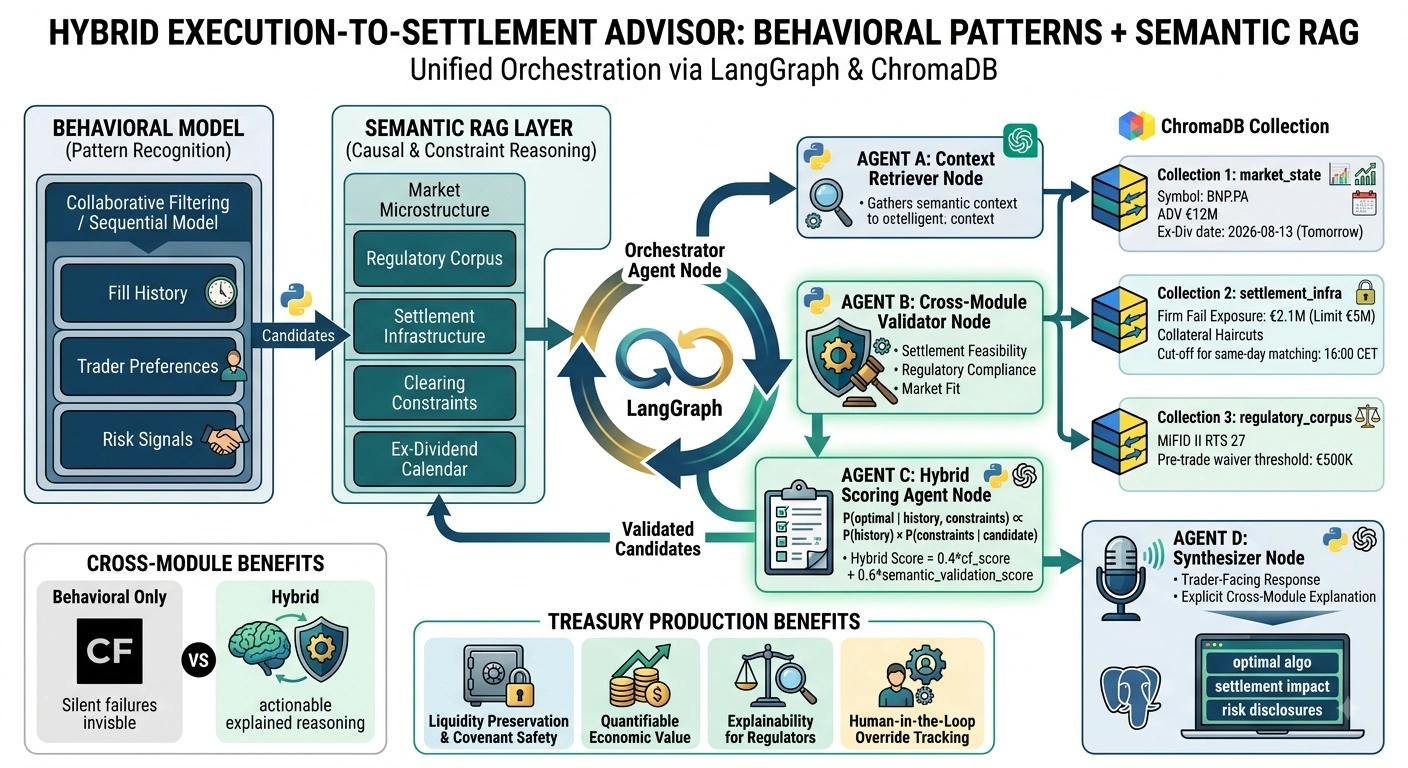
Key Insight: Behavioral models answer "what has worked?" Semantic RAG answers "what should work now, given current constraints, and why?" The intersection is actionable, compliant, explained recommendations.
Part 2: Multi-Collection ChromaDB Architecture
Collection 1: Market Microstructure & Liquidity State (market_state)
Real-time updated embeddings capturing current trading conditions.
market_document = {
    "id": "mkt_bnp_20260812_0930",
    "page_content": "BNP Paribas Euronext Paris: Spread 3.2bps, TOB depth €180K,
                     30d ADV €12M. Dark pool midpoint: €420K visible.
                     Implied vol term structure backwardated.
                     Ex-dividend date: 2026-08-13 (tomorrow).
                     Record date settlement requires T+1 delivery.",
    "metadata": {
        "type": "market_state",
        "symbol": "BNP.PA",
        "venue": "XPAR",
        "spread_bps": 3.2,
        "tob_depth_eur": 180000,
        "adv_30d_eur": 12000000,
        "dark_midpoint_liq_eur": 420000,
        "ex_dividend_date": "2026-08-13",
        "record_date_settlement": "T+1",
        "iv_term_structure": "backwardated",
        "timestamp": "2026-08-12T09:30:00Z"
    }
}
Collection 2: Clearing & Settlement Infrastructure (settlement_infra)
Static + slowly-changing knowledge about CSDs, CCPs, cut-offs, and collateral rules.
settlement_document = {
    "id": "csd_euroclear_france_equity_t2",
    "page_content": "Euroclear France equity settlement: T+2 standard cycle.
                     Cut-off for same-day matching: 16:00 CET.
                     Failing trade penalty: 0.5bps/day after grace period.
                     Collateral haircuts: French blue-chips 2%, mid-cap 5%.
                     Current firm failing exposure: €2.1M (within €5M limit).
                     Ex-dividend trades require cash collateral top-up by 14:00 CET D-1.",
    "metadata": {
        "type": "settlement_rule",
        "csd": "Euroclear_France",
        "asset_class": "equity",
        "settlement_cycle": "T+2",
        "matching_cutoff_cet": "16:00",
        "fail_penalty_bps_per_day": 0.5,
        "collateral_haircut_bluechip_pct": 2.0,
        "firm_fail_exposure_current_eur": 2100000,
        "firm_fail_limit_eur": 5000000,
        "ex_div_collateral_deadline_cet": "14:00",
        "effective_date": "2026-01-15"
    }
}
Collection 3: Regulatory & Best Execution Corpus (regulatory_corpus)
MiFID II RTS 27/28, SEC Rule 605, venue-specific obligations.
reg_document = {
    "id": "reg_mifid2_rts27_best_exec_large_cap",
    "page_content": "MiFID II RTS 27: For large-cap liquid equities, execution venues
                     must be assessed quarterly on price, costs, speed, likelihood of execution.
                     Pre-trade transparency waiver available for orders >€500K if reference price
                     derived from regulated market. Post-trade deferral: 4 weeks for large transactions.",
    "metadata": {
        "type": "regulation",
        "framework": "MiFID_II",
        "instrument": "RTS_27",
        "asset_class": "equity_large_cap",
        "pre_trade_waiver_threshold_eur": 500000,
        "post_trade_deferral_weeks": 4,
        "jurisdiction": "EU"
    }
}
Part 3: Unified State Schema Spanning Execution & Settlement
from typing import Annotated, List, Dict, Optional, Literalfrom typing_extensions import TypedDict
from langgraph.graph.message import add_messages
from langchain_core.documents import Document

class ExecSettleRecState(TypedDict):
    messages: Annotated[List, add_messages]
    order_id: str
    trader_id: str

    # === BEHAVIORAL MODEL OUTPUT ===
    cf_candidate_algos: List[Dict]           # From collaborative filtering
    cf_confidence: float
    behavioral_signals: Dict[str, float]     # Trader prefs, historical fill quality

    # === SEMANTIC RETRIEVAL OUTPUT ===
    market_context: List[Document]
    settlement_constraints: List[Document]
    regulatory_context: List[Document]

    # === CROSS-MODULE VALIDATION STATE ===
    settlement_feasible: bool
    collateral_impact_eur: Optional[float]
    ex_div_risk_flag: bool
    regulatory_compliant: bool
    hybrid_score: float                      # Combined behavioral + semantic score
    validation_reasoning: str

    # Output
    recommendation: Dict
    explanation: str                         # Human-readable rationale
    agent_trace: List[str]
Part 4: Multi-Agent Implementation
Agent A: Behavioral Candidate Generator
Runs first. Produces candidates from CF/sequential models. Fast, pattern-based, no reasoning.
def behavioral_candidate_node(state: ExecSettleRecState):
    """Collaborative filtering + trader preference model. Sub-10ms."""
    # In production: call your existing ML serving endpoint
    # This is a placeholder representing your behavioral model infrastructure
    candidates = behavioral_model.predict(
        symbol=extract_symbol(state["messages"][-1].content),
        order_size=extract_size(state["messages"][-1].content),
        trader_id=state["trader_id"],
        market_regime=get_current_regime()
    )

    return {
        "cf_candidate_algos": candidates["algos"],      # e.g., [{"algo": "IS_AGG", "score": 0.82}, ...]
        "cf_confidence": candidates["confidence"],
        "behavioral_signals": candidates["signals"],
        "agent_trace": [f"behavioral: {len(candidates['algos'])} candidates, conf={candidates['confidence']:.3f}"]
    }
Agent B: Semantic Context Retriever
Retrieves market state, settlement constraints, and regulations relevant to THIS order. Runs in parallel with or immediately after behavioral generation.
from langchain_chroma import Chroma
from langchain_openai import OpenAIEmbeddings

market_store = Chroma(collection_name="market_state", embedding_function=OpenAIEmbeddings())
settlement_store = Chroma(collection_name="settlement_infra", embedding_function=OpenAIEmbeddings())
reg_store = Chroma(collection_name="regulatory_corpus", embedding_function=OpenAIEmbeddings())

def semantic_retriever_node(state: ExecSettleRecState):
    query = state["messages"][-1].content
    symbol = extract_symbol(query)

    # Parallel retrieval across three collections
    market_docs = market_store.similarity_search(query, k=3, filter={"symbol": symbol})

    # Settlement retrieval keyed on symbol's primary listing venue + asset class
    settle_docs = settlement_store.similarity_search(
        query, k=5,
        filter={"asset_class": "equity"}
    )

    reg_docs = reg_store.similarity_search(query, k=3, filter={"asset_class": "equity_large_cap"})

    return {
        "market_context": market_docs,
        "settlement_constraints": settle_docs,
        "regulatory_context": reg_docs,
        "agent_trace": state["agent_trace"] + [
            f"semantic: market={len(market_docs)}, settlement={len(settle_docs)}, reg={len(reg_docs)}"
        ]
    }
Agent C: Cross-Module Validation & Hybrid Scoring Agent
This is the core innovation. It takes behavioral candidates and validates/constrains/explains them using semantic context. The LLM reasons across modules.
Join the conversation! Your thoughts help the community grow.