
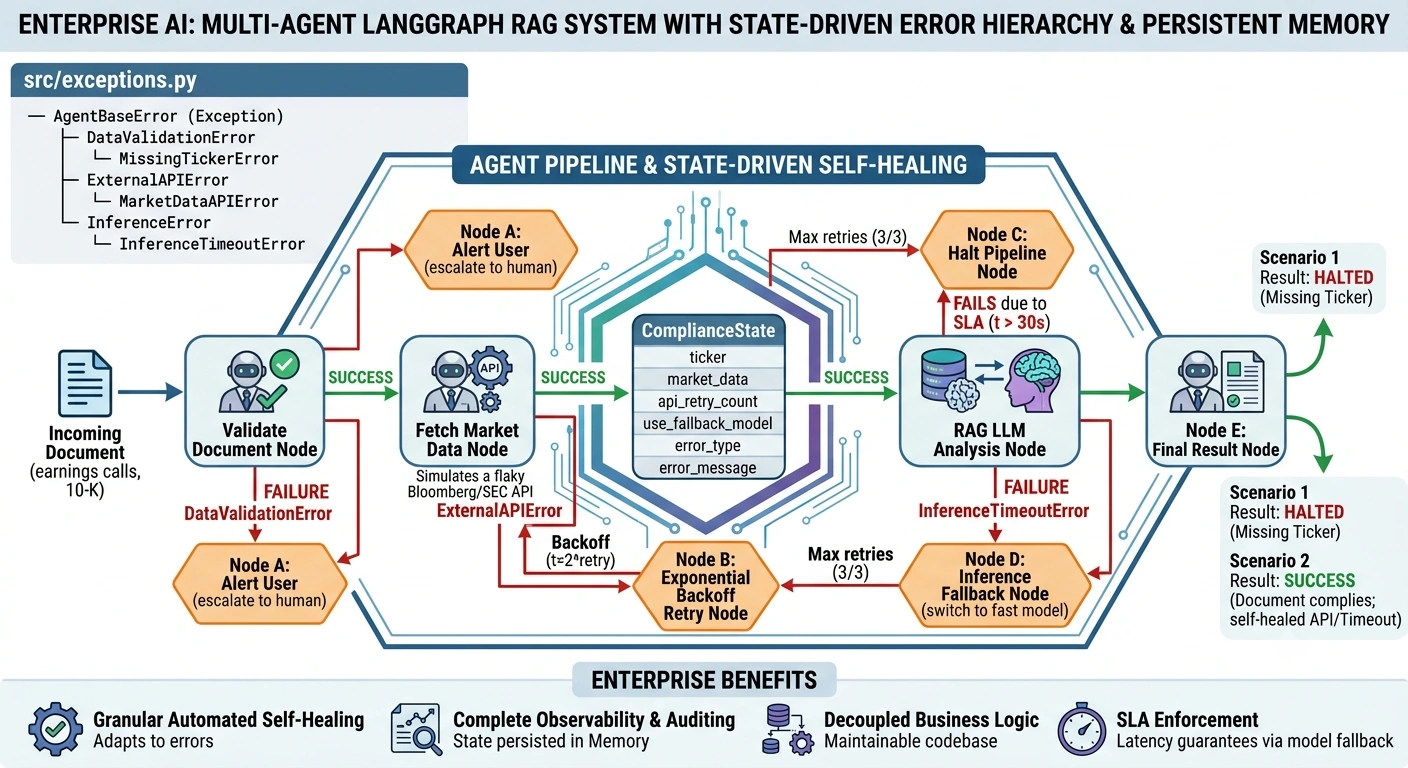
In enterprise AI deployments, a generic try...except Exception block is a death sentence for production reliability. When a Multi-Agent LangGraph system fails, the system doesn't just need to know that it failed; it needs to know why it failed to determine how to recover. A missing field in a PDF requires user intervention. A 500 error from a third-party API requires an exponential backoff retry. An LLM inference timeout requires a fallback to a smaller, faster model. Treating all these failures identically leads to infinite retry loops, wasted compute, and frustrated users. In this end-to-end guide, we will design a Custom Python Error Hierarchy and integrate it into an Enterprise Multi-Agent LangGraph RAG System with persistent memory. We will build a Real-Time Financial Compliance Agent that catches specific errors, updates the graph state, and autonomously routes to self-healing recovery nodes.
The Real-World Use Case: Real-Time Financial Compliance Monitoring
Imagine an enterprise system monitoring incoming financial documents (earnings calls, 10-K filings) in real-time to check for regulatory compliance and market anomalies.
The Pipeline:
Ingestion & Validation: Extract text and validate the presence of a valid Stock Ticker.
Market Data Fetching: Query a real-time external API (e.g., Bloomberg/SEC) for current market cap and peer data.
RAG & LLM Analysis: Retrieve compliance rules from a Vector DB and use an LLM to analyze the document against the rules.
The Failure Modes:
Data Validation Error: The uploaded document is an image-only PDF or lacks a ticker symbol. Action: Halt pipeline, notify user.
API Failure: The external market data API is rate-limited or down. Action: Retry with exponential backoff up to 3 times.
Inference Timeout: The document is 100 pages long, and the primary LLM (
gpt-4o) exceeds the 30-second SLA. Action: Fallback to a faster model (gpt-4o-mini) or chunk the document.
Designing the Custom Error Hierarchy
We create a structured exception tree. This allows us to catch broad categories of errors (e.g., AgentBaseError) or highly specific ones (e.g., InferenceTimeoutError).
# src/exceptions.py

class AgentBaseError(Exception):
    """Base exception for all enterprise agent errors."""
    def __init__(self, message: str, context: dict = None):
        super().__init__(message)
        self.message = message
        self.context = context or {}

# --- 1. Data Validation Errors ---
class DataValidationError(AgentBaseError):
    """Raised when input data is malformed or missing required fields."""
    pass

class MissingTickerError(DataValidationError):
    """Specific validation error for missing stock tickers."""
    pass

# --- 2. External API Errors ---
class ExternalAPIError(AgentBaseError):
    """Raised when an external service (DB, API, Vector Store) fails."""
    pass

class MarketDataAPIError(ExternalAPIError):
    """Specific error for the financial market data provider."""
    pass

# --- 3. Model Inference Errors ---
class InferenceError(AgentBaseError):
    """Raised when the LLM fails to generate a response."""
    pass

class InferenceTimeoutError(InferenceError):
    """Raised when the LLM exceeds the maximum allowed execution time."""
    pass
Architecture Overview: State-Driven Error Recovery
In standard Python, an unhandled exception crashes the thread. In LangGraph, we intercept these custom errors, write them to the Graph State, and use Conditional Edges to route the execution to specialized recovery nodes.
[ Incoming Document ]
          │
          ▼
┌───────────────────────┐
│ 1. Validate Document  │ ──(DataValidationError)──> [ Alert User Node ]
└───────────┬───────────┘
            │ (Success)
            ▼
┌───────────────────────┐
│ 2. Fetch Market Data  │ ──(ExternalAPIError)───> [ Retry Node ] ──┐
└───────────┬───────────┘                                               │
            │ (Success)                                                 │ (Retries < 3)
            ▼                                                           │
┌───────────────────────┐                                               │
│ 3. RAG LLM Analysis   │ ──(InferenceTimeoutError)──> [ Fallback Node ]
└───────────┬───────────┘
            │ (Success)
            ▼
      [ Final Report ]
End-to-End Python Implementation
Prerequisites
pip install langgraph langchain-openai langchain-coreStep 1: Define the LangGraph State and Memory
The state must include fields to track errors and retry attempts. We use MemorySaver to persist this state across conversational turns.
from typing import TypedDict, List, Dict, Any, Optional
from langgraph.checkpoint.memory import MemorySaver

class ComplianceState(TypedDict):
    document_text: str
    ticker: Optional[str]
    market_data: Optional[Dict[str, Any]]
    compliance_rules: str
    final_analysis: str

    # Error Tracking & Recovery State
    error_type: Optional[str]
    error_message: Optional[str]
    api_retry_count: int
    use_fallback_model: bool
Step 2: The Multi-Agent Nodes (with Custom Error Handling)
Each node performs its task. If it encounters a failure, it catches the specific custom exception, updates the state with the error details, and returns.
import asyncio
import random
from src.exceptions import (
    MissingTickerError, MarketDataAPIError, InferenceTimeoutError
)

# --- Node 1: Validation ---
def validate_document_node(state: ComplianceState) -> Dict[str, Any]:
    """Validates the document. Raises custom error if invalid."""
    text = state.get("document_text", "")

    # Simulate extracting a ticker
    if "TICKER:" in text:
        ticker = text.split("TICKER:")[1].strip().split()[0]
    else:
        # Catching our own custom error to update state instead of crashing the graph
        try:
            raise MissingTickerError("Document does not contain a valid TICKER identifier.")
        except MissingTickerError as e:
            return {
                "error_type": "validation",
                "error_message": e.message,
                "ticker": None
            }

    return {"ticker": ticker, "error_type": None, "error_message": None}

# --- Node 2: Market Data API ---
async def fetch_market_data_node(state: ComplianceState) -> Dict[str, Any]:
    """Fetches external data. Simulates API failures."""
    retry_count = state.get("api_retry_count", 0)

    # Simulate a flaky API (fails 50% of the time)
    if random.random() < 0.5:
        try:
            raise MarketDataAPIError("Upstream provider returned HTTP 503", context={"retry": retry_count})
        except MarketDataAPIError as e:
            return {
                "error_type": "api_failure",
                "error_message": e.message,
                "api_retry_count": retry_count + 1,
                "market_data": None
            }

    # Success scenario
    return {
        "market_data": {"market_cap": "50B", "sector": "Tech"},
        "error_type": None,
        "error_message": None
    }

# --- Node 3: RAG LLM Analysis ---
async def rag_analysis_node(state: ComplianceState) -> Dict[str, Any]:
    """Runs RAG and LLM inference. Simulates timeouts."""
    use_fallback = state.get("use_fallback_model", False)

    # Simulate a timeout if not using the fallback model
    if not use_fallback:
        try:
            # Simulate a 40-second LLM call
            await asyncio.sleep(40)
            raise InferenceTimeoutError("LLM inference exceeded 30s SLA.")
        except InferenceTimeoutError as e:
            return {
                "error_type": "inference_timeout",
                "error_message": e.message,
                "final_analysis": None
            }

    # Success scenario (Fallback model is fast)
    return {
        "final_analysis": "Document complies with SEC regulations. Market data aligns.",
        "error_type": None,
        "error_message": None
    }
Join the conversation! Your thoughts help the community grow.